Sensor fusion annotation pilot acceptance should rest on measurable evidence that both sides agree on before the first frame is labeled. The core measures are 3D geometric accuracy, camera-LiDAR projection consistency, track identity continuity, and first-pass quality, each scored per scenario slice against a blind gold set. Competing suppliers should work on identical data, guidelines, and scoring scripts, with the buyer owning adjudication. A passed pilot shows a supplier’s quality ceiling, so production readiness needs its own evidence.
Camera and LiDAR labels can each look correct in isolation and still disagree once they are projected into the same frame. That disagreement rarely shows up in a supplier demo, which is why teams evaluating multisensor fusion annotation vendors or robotics data services need a pilot designed to expose it. A well-built pilot turns the buyer’s question about consistency and calibration across camera and LiDAR labels into numbers two suppliers can be compared on.
Key Takeaways
- Agree on clear pass-or-fail rules before the pilot starts, so no one argues later about what “good” means.
- Check that camera and LiDAR labels match each other, because each can look right on its own and still disagree when combined.
- Test every supplier on the same data and instructions, with enough examples of rare situations, such as night driving, to judge them fairly.
- Score the work against hidden test samples the suppliers cannot spot, and let the buyer settle any disputed labels.
- Count work that passed the first time separately from work that needed fixing, since repeated fixes become an extra cost once volumes grow.
- Treat a passed pilot as a starting point, and ask each supplier for the same proof of quality, staffing, and capacity before you buy.
What Is a Sensor Fusion Annotation Pilot and What Does Acceptance Mean?
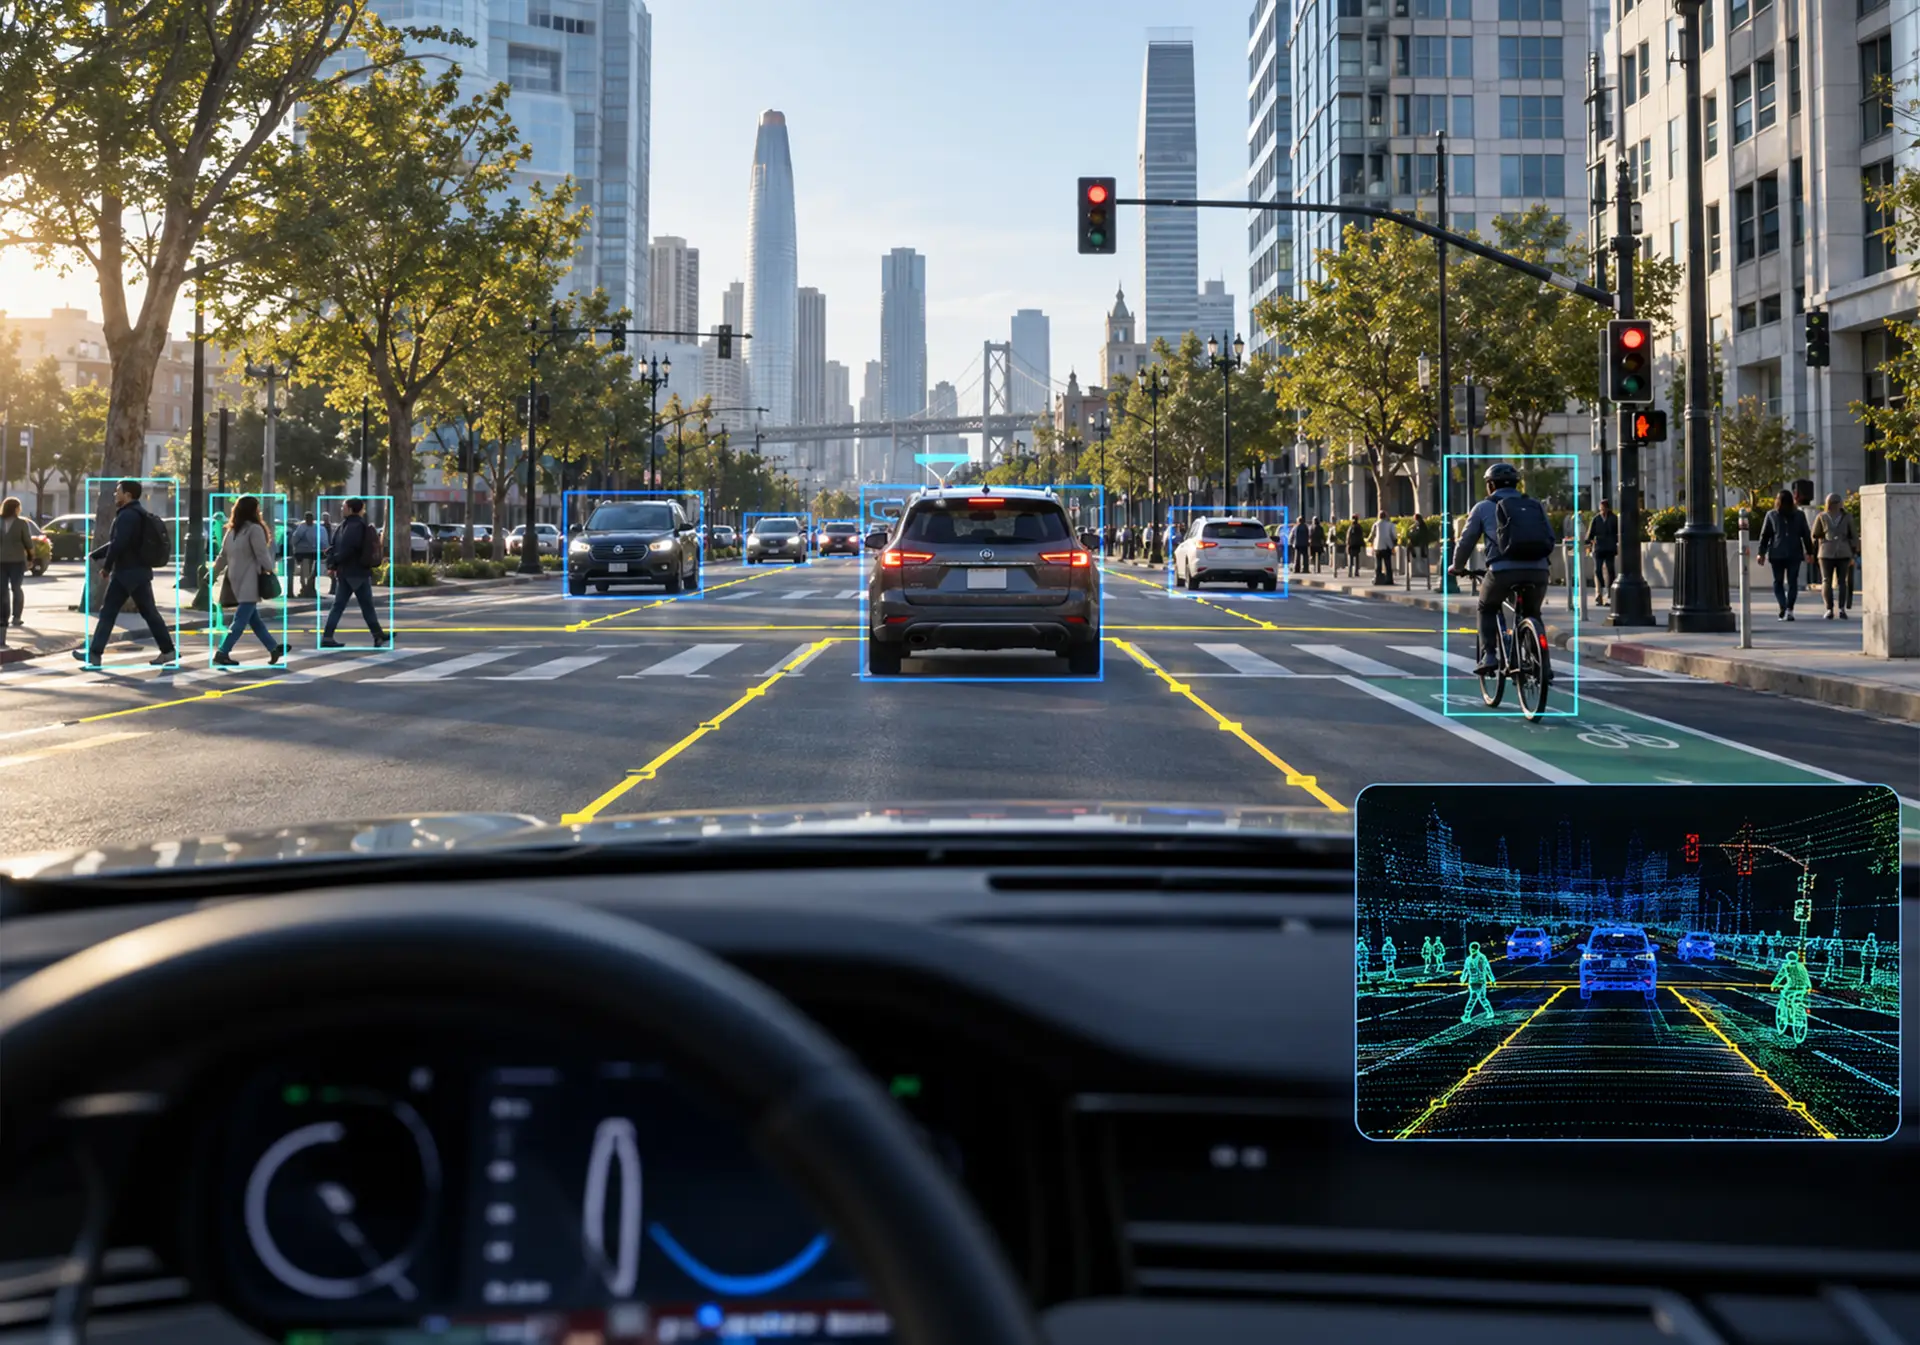
A sensor fusion annotation pilot is a time-boxed, paid trial in which a supplier labels a sample of the buyer’s own multi-sensor logs under production-like conditions. The output usually combines 2D boxes or segmentation on camera frames with 3D LiDAR point cloud annotation, linked by shared object IDs across sensors and time. Some programs add radar returns, which carry velocity cues for object association. Multi-sensor annotation, camera-LiDAR fusion labeling, and 2D-3D linked annotation all describe the same deliverable.
Acceptance is the pre-agreed rule that decides whether a delivered batch passes. It names the metric, the threshold, the sampling method, and the person who scores the result. Without that rule in writing before work starts, most pilots end in a negotiation over what “good” meant. ITU-T Recommendation F.749.23, approved in August 2026, now sets out content, method, data format, and acceptance criteria for bird’s-eye-view (BEV) fusion annotation in automated vehicles.
Fusion labels also depend on calibration data that usually comes from the buyer’s sensor rig. Intrinsic calibration describes each camera’s lens and focal properties. Extrinsic calibration describes where each sensor sits relative to the others, and time synchronization aligns their timestamps. The MultiCorrupt benchmark found that miscalibration and mismatched sampling rates create spatial and temporal misalignment between LiDAR and camera data, and that detector robustness varies with the fusion strategy. A pilot that never tests how a supplier detects and escalates calibration problems tells the buyer little about production logs.
Which Measures Belong in a Sensor Fusion Annotation Pilot?
The measures should mirror the failure modes that hurt fused perception models. Aggregate accuracy hides most of them. Report each measure per class and per scenario slice from the operational design domain (ODD), such as night, rain, dense traffic, and long range. Five groups of measures cover most programs.
| Measure group | What it checks | Typical metrics |
|---|---|---|
| 3D geometric accuracy | Cuboid position, size, and heading against the gold set | 3D IoU, BEV IoU, center error (m), yaw error (degrees) |
| Detection completeness | Missed and spurious objects, including small and distant ones | Recall and precision at an agreed match threshold |
| Cross-modal consistency | Whether 3D and 2D labels describe the same object in the same place | Projected-cuboid vs. 2D-box IoU, cross-sensor ID match rate |
| Temporal and identity consistency | Stable object identity and placement across frames | ID switches per 100 tracks, track fragmentation, motion-compensated placement error |
| Operational quality | How the supplier behaves while producing labels | First-pass acceptance, rework cycles, guideline query rate, throughput |
How is cross-modal consistency between camera and LiDAR labels measured?
Cross-modal consistency deserves the most attention because single-sensor QA cannot see it. A supplier can score well on cuboid IoU and on 2D boxes separately while the two disagree after projection. Checking each projected cuboid against its linked 2D label is the most direct test of how a supplier handles consistency and calibration across camera and LiDAR labels. The same check should confirm that one physical object carries one ID in every sensor view.
Why do temporal errors need their own measures?
Temporal errors are easier to miss than geometric ones. A WACV 2026 study of systematic errors in 3D box annotations found boxes in public driving datasets misplaced by up to 2.5 m, with highly dynamic objects most affected. The cause was timing: a rotating LiDAR observes different parts of a moving object at different moments within one sweep. A pilot should therefore include fast-moving objects and score their placement against motion-compensated gold labels.
What thresholds are realistic for 3D cuboids?
Thresholds should reflect what careful humans can achieve on the same data. In a human label study on the Waymo Open Dataset, experienced labelers matched verified ground truth at about 81% mean 3D IoU and 88% BEV IoU. Agreement fell from about 86% 3D IoU within 30 m to about 73% beyond 50 m. Range-banded thresholds, set from the buyer’s own internal agreement on the gold set, avoid failing good suppliers on normal variation.
How Can Two Suppliers Be Tested Fairly?
A fair comparison removes every difference except the suppliers themselves. Most unfair pilots break on small things, such as one supplier receiving a clarification by email that the other never saw. These controls keep the comparison clean:
- Same input: identical sequences, calibration files, and sensor metadata, stratified across the slices that matter.
- Same guideline version: one frozen document, with every clarification published to both suppliers through a shared query log.
- Same output schema: a common export format, so one scoring script evaluates both deliveries.
- Same time box and volume: equal deadlines, with delivery timestamps recorded.
- Blind gold set: buyer-adjudicated items mixed into the batch, so suppliers cannot tell which items are scored.
- Blind scoring: reviewers see deliveries under neutral supplier codes.
- Declared staffing: each supplier names the pilot team and confirms that team will start production.
The staffing declaration matters more than it looks. A common red flag is quality that drops after the first batch, which suggests a supplier placed its strongest annotators on the pilot. A second, smaller batch scored a few weeks later tests whether the first result holds.
Who Should Adjudicate Disputed Annotations?
The buyer should own adjudication, because the buyer owns the definition of ground truth. A small panel works well: a perception engineer who knows how the model consumes labels, the guideline owner, and a senior reviewer who did not label the item. Suppliers should be able to appeal a scored error with evidence, such as a camera frame showing an occluded object.
Every dispute should be logged with a root cause. Three causes cover most cases: annotator error, guideline ambiguity, and gold set error. Only annotator errors should count against a supplier. Guideline ambiguities trigger an update issued to both suppliers, and gold errors are corrected and rescored for everyone.
Differences within the range of normal human variation should not be scored as errors at all. Measuring that range on the buyer’s own data keeps adjudication focused on real mistakes. Well-designed inter-annotator agreement protocols make these boundaries explicit and provide a consistent framework for reviewing disagreements at scale.
Should Reworked Outputs Count in First-Pass Acceptance?
First-pass acceptance should count only items that passed on first submission. Reworked items belong in a separate final acceptance rate, reported with the number of rework cycles and the time each cycle took. Blending the two hides the cost that production will carry.
The gap between the two rates is often the most useful number in the pilot. A supplier with high final acceptance and low first-pass acceptance depends on the buyer’s reviewers to find its errors. At production volume, that review effort becomes a hidden cost that the per-label price does not show.
Both rates should carry into the contract. The pilot’s first-pass result becomes the baseline for the rework trigger, measured with the same gold set protocol. An AI training dataset SLA is where those rework terms, turnaround commitments, and cost responsibilities become enforceable.
How Much Pilot Data Is Enough?
Enough data is the amount that supports a confident decision on each slice that matters. Counting frames overstates the evidence, because consecutive frames in a sequence are highly correlated. Count independent sequences and labeled objects per slice instead.
A simple statistical rule helps with sizing. If a supplier makes zero errors on n independent objects, the 95% upper bound on its true error rate is roughly 3/n. Supporting an error rate below 1% on a slice therefore needs about 300 clean objects in that slice. Rare slices, such as pedestrians at night or motorcycles at long range, usually set the pilot size.
Most programs control cost by sampling rare slices more heavily than their natural frequency. The pilot also needs enough consecutive frames per sequence to measure ID switches and track fragmentation. A few long sequences reveal more about temporal consistency than many isolated frames.
Does Passing a Pilot Prove Production Readiness?
A pilot shows what a supplier can do under close attention on a small batch. Production readiness depends on whether that quality holds when volume, staff, and data conditions change. Those are separate questions, and they need separate evidence.
Useful readiness evidence includes a surge test at several times pilot throughput, annotator qualification records, and a ramp plan with named leads. It also includes proof that the supplier catches calibration drift when new vehicles or sensor rigs enter the data. Security posture matters for automotive work, where TISAX alignment is often expected.
The strongest signal is a second blind batch scored after ramp-up, using the same gold set protocol. If the result holds on that batch, the buyer has evidence about the operation as well as the labels. This is also where many AI pilots fail to scale because throughput, reviewer calibration, and feedback loops often weaken once production volume increases.
What Evidence Checklist Supports Sensor Fusion Annotation Pilot Acceptance?
Before procurement, each supplier should hand over the same set of artifacts. Comparing these side by side is more reliable than comparing headline accuracy claims. The checklist below works as an acceptance gate:
- A calibration validation report showing how intrinsic, extrinsic, and time-sync issues were detected and escalated.
- The frozen guideline version, with the full query log and every clarification issued.
- A per-slice metric report covering 3D geometry, detection completeness, and projection consistency.
- A track continuity report with ID switches and fragmentation per sequence.
- An error taxonomy with counts by class, slice, and root cause.
- The adjudication log, including disputes, outcomes, and gold set corrections.
- First-pass and final acceptance rates, with rework cycle counts and turnaround.
- Item-level lineage recording annotator, reviewer, QA pass, and timestamp.
- A staffing and ramp plan, with qualification records for the production team.
- Security and compliance evidence relevant to the data and region.
A supplier that cannot produce one of these artifacts during the pilot is unlikely to produce it at production volume. Missing evidence should count as a failed criterion, with the same weight as a missed metric threshold. Agreeing on that rule before the pilot avoids disputes after the results arrive.
How Digital Divide Data Can Help
Digital Divide Data runs sensor fusion pilots around the evidence described above. DDD’s multisensor fusion data services start with perception goals, sensor stack, and quality benchmarks agreed with the client. Work then moves through calibrated ingestion, cross-sensor annotation, and multi-layer QA for spatial, temporal, and semantic consistency. Edge cases and adverse conditions get a dedicated robustness review before delivery.
That sequence comes from production programs. In one engagement with an autonomous vehicle developer, DDD began with sensor synchronization and calibration validation. It then delivered linked 2D, 3D cuboid, and radar annotations with persistent object IDs across modalities. The multisensor fusion case study for robust autonomous perception describes how this reduced radar-camera association errors and improved 3D localization for occluded objects.
For pilots, DDD builds the evaluation set first, measures throughput on the team that will run production, and reports first-pass and final acceptance separately. Delivery runs under SOC 2 Type 2 and ISO 27001 controls, with TISAX alignment for automotive data. Clients get the per-slice reports, adjudication logs, and lineage records that procurement needs to compare suppliers.
Run a sensor fusion pilot that gives procurement evidence it can trust. Talk to an Expert.
Conclusion
A sensor fusion annotation pilot earns its cost when the acceptance rule, the gold set, and the adjudication process exist before the first label. Teams that set these up compare suppliers on evidence, catch cross-modal and temporal errors early, and sign contracts with baselines they can enforce. Teams that skip them compare demos, then find calibration and identity problems after the labels are already in the model.
The evidence checklist turns a supplier claim into a procurement decision. For related reading, multi-sensor data labeling covers the annotation techniques behind fused datasets. The guide on designing a pilot that proves the operation extends the production-readiness tests described here.
References
Beemelmanns, T., Zhang, Q., Geller, C., & Eckstein, L. (2024). MultiCorrupt: A multi-modal robustness dataset and benchmark of LiDAR-camera fusion for 3D object detection. https://arxiv.org/abs/2402.11677
International Telecommunication Union. (2026). Recommendation ITU-T F.749.23: Requirements for bird’s-eye view sensor fusion data labelling in connected and automated vehicles. ITU-T Study Group 21. https://www.itu.int/rec/T-REC-F.749.23-202608-P
Miro, A. J., af Klinteberg, L., Timus, B., Asefaw, A., Khoche, A., Gustafsson, T., Mansouri, S. S., & Daneshtalab, M. (2026). Correcting and quantifying systematic errors in 3D box annotations for autonomous driving.
Qi, C. R., Zhou, Y., Najibi, M., Sun, P., Vo, K., Deng, B., & Anguelov, D. (2021). Offboard 3D object detection from point cloud sequences. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR). https://arxiv.org/abs/2103.05073
Frequently Asked Questions
Which services address consistency and calibration across camera and LiDAR labels?
Look for multisensor fusion annotation services that validate calibration and time sync before labeling, link 2D and 3D labels with persistent object IDs, and check every projected cuboid against its 2D label. In a pilot, ask each supplier to prove this with a calibration validation report and a per-slice projection consistency report.
What IoU threshold should I use to accept 3D cuboid labels?
Set it from measured human agreement on your own data, and band it by range. In one Waymo Open Dataset study, experienced labelers reached about 81% 3D IoU and 88% BEV IoU against verified ground truth, with lower agreement at long range, so stricter thresholds tend to penalize normal variation.
Should the gold set be hidden from annotation suppliers?
A hidden gold set mixed into the regular batch means the supplier cannot give scored items extra attention, so the score reflects normal work. Scoring deliveries under neutral supplier codes keeps the comparison fair as well.
Why count sequences instead of frames when sizing a pilot?
Consecutive frames in one sequence are highly correlated, so many frames from the same drive add little independent evidence. Counting independent sequences and labeled objects per slice gives a truer picture, and long sequences are also needed to measure ID switches and track fragmentation.
Udit Khanna leads the delivery of scalable AI and data solutions at Digital Divide Data, with a deep specialization in Physical AI. With a background in presales, solutioning, and customer success, he brings a mix of technical depth and business fluency, helping global enterprises move their AI projects from prototype to real-world deployment without losing momentum.