
Celebrating 25 years of DDD's Excellence and Social Impact. ✖

Video Annotation

Autonomous Systems Mobility

Video Annotation Services for Physical AI

Physical AI refers to intelligent systems that perceive, reason, and act within real environments. It includes autonomous vehicles, collaborative robots, drones, defense systems, embodied assistants, and increasingly, machines that learn from human demonstration. Unlike traditional software that processes static inputs, physical AI must interpret continuous streams of sensory data and translate them into safe, precise actions.

Video sits at the center of this transformation. Cameras capture motion, intent, spatial relationships, and environmental change. Over time, organizations have shifted from collecting isolated frames to gathering multi-camera, long-duration recordings. Video data may be abundant, but clean, structured, temporally consistent annotations are far harder to scale.

The backbone of reliable physical AI is not simply more data. It is well-annotated video data, structured in a way that mirrors how machines must interpret the world. High-quality video annotation services are not a peripheral function; they are foundational infrastructure.

This blog is a dive into how high-precision video annotation services enable Physical AI systems, from robotics to autonomous vehicles, to perceive, reason, and act safely in the real world.

What Makes Physical AI Different from Traditional Computer Vision?

Static Image AI vs. Temporal Physical AI

Traditional computer vision often focuses on individual frames. A model identifies objects within a snapshot. Performance is measured per image. While useful, this frame-based paradigm falls short when actions unfold over time.

Consider a warehouse robot picking up a package. The act of grasping is not one frame. It is a sequence: approach, align, contact, grip, lift, stabilize. Each phase carries context. If the grip slips, the failure may occur halfway through the lift, rather than at the moment of contact. A static frame does not capture intent or trajectory.

Temporal understanding demands segmentation of actions across sequences. It requires annotators to define start and end boundaries precisely. Was the grasp complete when the fingers closed or when the object left the surface? Small differences in labeling logic can alter how models learn.

Long-horizon task understanding adds another dimension. A five-minute cleaning task performed by a domestic robot contains dozens of micro-actions. The system must recognize not just objects but goals. A cluttered desk becomes organized through a chain of decisions. Labeling such sequences calls for more than object detection. It requires a structured interpretation of behavior.

The Shift to Embodied and Multi-Modal Learning

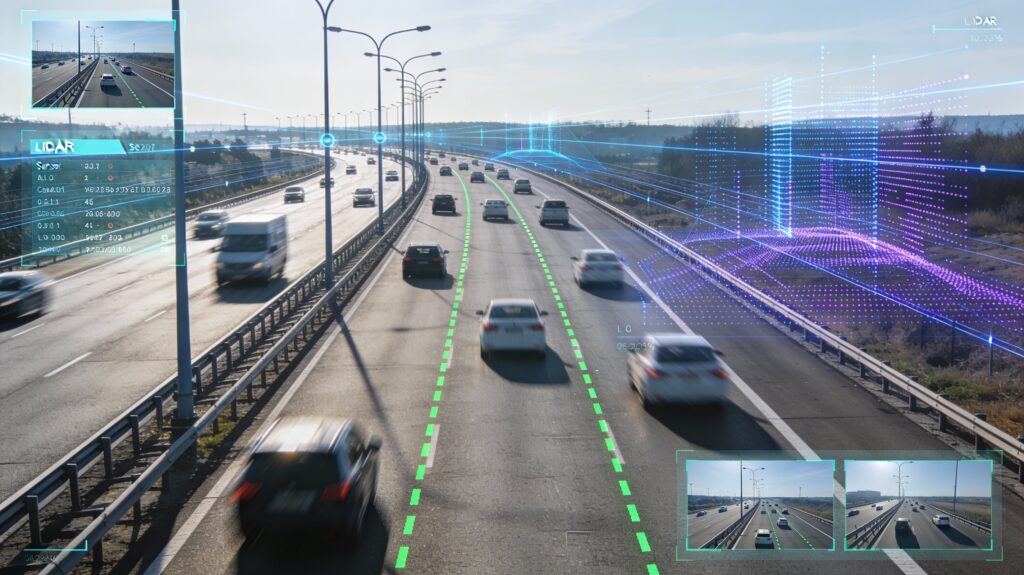
Vehicles combine camera feeds with LiDAR and radar. Robots integrate depth sensors and joint encoders. Wearable systems may include inertial measurement units.

This sensor fusion means annotations must align across modalities. A bounding box in RGB imagery might correspond to a three-dimensional cuboid in LiDAR space. Temporal synchronization becomes essential. A delay of even a few milliseconds could distort training signals.

Language integration complicates matters further. Many systems now learn from natural language instructions. A robot may be told, “Pick up the red mug next to the laptop and place it on the shelf.” For training, the video must be aligned with textual descriptions. The word “next to” implies spatial proximity. The action “place” requires temporal grounding.

Embodied learning also includes demonstration-based training. Human operators perform tasks while cameras record the process. The dataset is not just visual. It is a representation of skill. Capturing this skill accurately demands hierarchical labeling. A single demonstration may contain task-level intent, subtasks, and atomic actions.

Real-World Constraints

In lab conditions, the video appears clean. In real deployments, not so much. Motion blur during rapid turns, occlusions when objects overlap, glare from reflective surfaces, and shadows shifting throughout the day. Physical AI must operate despite these imperfections.

Safety-critical environments raise the stakes. An autonomous vehicle cannot misclassify a pedestrian partially hidden behind a parked van. A collaborative robot must detect a human hand entering its workspace instantly. Rare edge cases, which might appear only once in thousands of hours of footage, matter disproportionately.

These realities justify specialized annotation services. Labeling physical AI data is not simply about drawing shapes. It is about encoding time, intent, safety context, and multi-sensor coherence.

Why Video Annotation Is Critical for Physical AI

Action-Centric Labeling

Physical AI systems learn through patterns of action. Breaking down tasks into atomic components such as grasp, push, rotate, lift, and release allows models to generalize across scenarios. Temporal segmentation is central here. Annotators define the precise frame where an action begins and ends. If the “lift” phase is labeled inconsistently across demonstrations, models may struggle to predict stable motion.

Distinguishing aborted actions from completed ones helps systems learn to anticipate outcomes. Without consistent action-centric labeling, models may misinterpret motion sequences, leading to hesitation or overconfidence in deployment.

Object Tracking Across Frames

Tracking objects over time requires persistent identifiers. A pedestrian in frame one must remain the same entity in frame one hundred, even if partially occluded. Identity consistency is not trivial. In crowded scenes, similar objects overlap. Tracking errors can introduce identity switches that degrade training quality.

In warehouse robotics, tracking packages as they move along conveyors is essential for inventory accuracy. In autonomous driving, maintaining identity across intersections affects trajectory prediction. Annotation services must enforce rigorous tracking standards, often supported by validation workflows that detect drift.

Spatio-Temporal Segmentation

Pixel-level segmentation extended across time provides a granular understanding of dynamic environments. For manipulation robotics, segmenting the precise contour of an object informs grasp planning. For vehicles, segmenting drivable areas frame by frame supports safe navigation. Unlike single-frame segmentation, spatio-temporal segmentation must maintain shape continuity. Slight inconsistencies in object boundaries can propagate errors across sequences.

Multi-View and Egocentric Annotation

Many datasets now combine first-person and third-person perspectives. A wearable camera captures hand movements from the operator’s viewpoint while external cameras provide context. Synchronizing these views requires careful alignment. Annotators must ensure that action labels correspond across angles. A grasp visible in the egocentric view should align with object movement in the third-person view.

Human-robot interaction labeling introduces further complexity. Detecting gestures, proximity zones, and cooperative actions demands awareness of both participants.

Long-Horizon Demonstration Annotation

Physical tasks often extend beyond a few seconds. Cleaning a room, assembling a product, or navigating urban traffic can span minutes. Breaking down long sequences into hierarchical labels helps structure learning. At the top level, the task might be “assemble component.” Beneath it lie subtasks such as “align bracket” or “tighten screw.” At the lowest level are atomic actions.

Sequence-level metadata captures contextual factors such as environment type, lighting condition, or success outcome. This layered annotation enables models to reason across time rather than react to isolated frames.

Core Annotation Types Required for Physical AI Systems

Different applications demand distinct annotation strategies. Below are common types used in physical AI projects.

Bounding Boxes with Tracking IDs

Bounding boxes remain foundational, particularly for object detection and tracking. When paired with persistent tracking IDs, they enable models to follow entities across time. In autonomous vehicles, bounding boxes identify cars, pedestrians, cyclists, traffic signs, and more. In warehouse robotics, boxes track packages and pallets as they move between zones. Consistency in box placement and identity assignment is critical. Slight misalignment across frames may seem minor, but it can accumulate into trajectory prediction errors.

Polygon and Pixel-Level Segmentation

Segmentation provides fine-grained detail. Instead of enclosing an object in a rectangle, annotators outline its exact shape. Manipulation robots benefit from precise segmentation of tools and objects, especially when grasping irregular shapes. Safety-critical systems use segmentation to define boundaries of drivable surfaces or restricted zones. Extending segmentation across time ensures continuity and reduces flickering artifacts in training data.

Keypoint and Pose Estimation in 2D and 3D

Keypoint annotation identifies joints or landmarks on humans and objects. In human-robot collaboration, tracking hand, elbow, and shoulder positions helps predict motion intent. Three-dimensional pose estimation incorporates depth information. This becomes important when systems must assess reachability or collision risk. Pose labels must remain stable across frames. Small shifts in keypoint placement can introduce noise into motion models.

Action and Event Tagging in Time

Temporal tags mark when specific events occur. A vehicle stops at a crosswalk. A robot successfully inserts a component. A drone detects an anomaly.

Precise event boundaries matter. Early or late labeling skews training signals. For planning systems, recognizing event order is just as important as recognizing the events themselves.

Sensor Fusion Annotation

Physical AI increasingly relies on multi-sensor inputs. Annotators may synchronize camera footage with LiDAR point clouds, radar signals, or depth maps. Three-dimensional cuboids in LiDAR data complement two-dimensional boxes in video. Alignment across modalities ensures that spatial reasoning models learn accurate geometry.

Challenges in Video Annotation for Physical AI

Video annotation at this level is complex and often underestimated.

Temporal Consistency at Scale

Maintaining label continuity across thousands of frames is demanding. Drift can occur when object boundaries shift subtly. Correcting drift requires a systematic review. Automated checks can flag inconsistencies, but human oversight remains necessary. Even small temporal misalignments can affect long-horizon learning.

Long-Horizon Task Decomposition

Defining taxonomies for complex tasks requires domain expertise. Overly granular labels may overwhelm annotators. Labels that are too broad may obscure learning signals. Striking the right balance involves iteration. Teams often refine hierarchies as models evolve.

Edge Case Identification

Rare scenarios are often the most critical. A pedestrian darting into traffic. A tool slipped during assembly. Edge cases may represent a fraction of data but have outsized safety implications. Systematically identifying and annotating such cases requires targeted sampling strategies.

Multi-Camera and Multi-Sensor Alignment

Synchronizing multiple streams demands precise timestamp alignment. Small discrepancies can distort perception. Cross-modal validation helps ensure consistency between visual and spatial labels.

Annotation Cost Versus Quality Trade-Offs

Video annotation is resource-intensive. Frame sampling can reduce workload, but risks missing subtle transitions. Active learning loops, where models suggest uncertain frames for review, can improve efficiency. Still, cost and quality must be balanced thoughtfully.

Human in the Loop and AI-Assisted Annotation Pipelines

Purely manual annotation at scale is unsustainable. At the same time, fully automated labeling remains imperfect.

Foundation Model Assisted Pre-Labeling

Automated segmentation and tracking tools can generate initial labels. Annotators then correct and refine them. This approach accelerates throughput while preserving accuracy. It also allows teams to focus on complex cases rather than routine labeling.

Expert Review Layers

Tiered quality assurance systems add oversight. Initial annotators produce labels. Senior reviewers validate them. Domain specialists resolve ambiguous scenarios. In robotics projects, familiarity with task logic improves annotation reliability. Understanding how a robot moves or why a vehicle hesitates can inform labeling decisions.

Iterative Model Feedback Loops

Annotation is not a one-time process. Models trained on labeled data generate predictions. Errors are analyzed. Additional data is annotated to address weaknesses. This feedback loop gradually improves both the dataset and the model performance. It reflects an ongoing partnership between annotation teams and AI engineers.

How DDD Can Help

Digital Divide Data works closely with clients to define hierarchical action schemas that reflect real-world tasks. Instead of applying generic labels, teams align annotations with the intended deployment environment. For example, in a robotics assembly project, DDD may structure labels around specific subtask sequences relevant to that assembly line.

Multi-sensor support is integrated into workflows. Annotators are trained to align video frames with spatial data streams. Where AI-assisted tools are available, DDD incorporates them carefully, ensuring human review remains central. Quality assurance operates across multiple layers. Sampling strategies, inter-annotator agreement checks, and domain-focused reviews help maintain temporal consistency.

Conclusion

Physical AI systems do not learn from abstract ideas. They learn from labeled experience. Every grasp, every lane change, every coordinated movement between human and machine is encoded in annotated video. Model intelligence is bounded by annotation quality. Temporal reasoning, contextual awareness, and safety all depend on precise labels.

As organizations push toward more capable robots, smarter vehicles, and adaptable embodied agents, structured video annotation pipelines become strategic infrastructure. Those who invest thoughtfully in this foundation are likely to move faster and deploy more confidently.

The future of intelligent machines may feel futuristic. In practice, it rests on careful, detailed work done frame by frame.

Partner with Digital Divide Data to build high-precision video annotation pipelines that power reliable, real-world Physical AI systems.

References

Kawaharazuka, K., Oh, J., Yamada, J., Posner, I., & Zhu, Y. (2025). Vision-Language-Action Models for Robotics: A Review Towards Real-World Applications. IEEE Access, 13, 162467–162504. https://doi.org/10.1109/ACCESS.2025.3609980

Kou, L., Ni, F., Zheng, Y., Han, P., Liu, J., Cui, H., Liu, R., & Hao, J. (2025). RoboAnnotatorX: A comprehensive and universal annotation framework for accurate understanding of long-horizon robot demonstrations. In Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV) (pp. 10353–10363). https://openaccess.thecvf.com/content/ICCV2025/papers/Kou_RoboAnnotatorX_A_Comprehensive_and_Universal_Annotation_Framework_for_Accurate_Understanding_ICCV_2025_paper.pdf

VLA-Survey Contributors. (2025). Vision-Language-Action Models for Robotics: A Review Towards Real-World Applications [Project survey webpage]. https://vla-survey.github.io/

Frequently Asked Questions

How much video data is typically required to train a Physical AI system?
Requirements vary by application. A warehouse manipulation system might rely on thousands of demonstrations, while an autonomous driving stack may require millions of frames across diverse environments. Data diversity often matters more than sheer volume.

How long does it take to annotate one hour of complex robotic demonstration footage?
Depending on annotation depth, one hour of footage can take several hours or even days to label accurately. Temporal segmentation and hierarchical labeling significantly increase effort compared to simple bounding boxes.

Can synthetic data reduce video annotation needs?
Synthetic data can supplement real-world footage, especially for rare scenarios. However, models deployed in physical environments typically benefit from real-world annotated sequences to capture unpredictable variation.

What metrics indicate high-quality video annotation?
Inter-annotator agreement, temporal boundary accuracy, identity consistency in tracking, and cross-modal alignment checks are strong indicators of quality.

How often should annotation taxonomies be updated?
As models evolve and deployment conditions change, taxonomies may require refinement. Periodic review aligned with model performance metrics helps ensure continued relevance.

 

Video Annotation Services for Physical AI Read Post »
ObjecttrackingComputerVision

How Object Tracking Brings Context to Computer Vision

Computer vision has traditionally excelled at interpreting images as individual, static snapshots. A frame is analyzed, objects are detected, classified, and localized, and the system moves on to the next frame. This approach has driven major progress in visual AI, but it also exposes a fundamental limitation: a lack of temporal understanding. When every frame is treated in isolation, an algorithm can recognize what is present but not what is happening. The subtle story that unfolds over time, motion, interaction, and intent, remains invisible.

Without this temporal dimension, even advanced models can miss critical context. A car slowing near a pedestrian crossing, a person turning after a brief pause, or a drone adjusting its trajectory; each of these actions only makes sense when seen as part of a continuous sequence rather than a frozen moment. Static perception falls short in capturing these evolving relationships, leading to misinterpretations and missed insights.

This gap becomes particularly significant in dynamic environments where context significantly influences decision-making. In surveillance, tracking helps differentiate ordinary movement from suspicious behavior. In robotics, it enables machines to anticipate collisions or respond to human gestures. In autonomous vehicles, it supports trajectory forecasting and safety predictions.

In this blog, we will explore how object tracking provides the missing layer of temporal and relational context that transforms computer vision from static perception into continuous understanding.

Object Tracking in Computer Vision

Object tracking is the process of identifying and following specific objects as they move through a sequence of video frames. While object detection focuses on recognizing and localizing items in individual images, tracking extends this capability by maintaining an object’s identity over time. It connects detections across frames, building a coherent narrative of how each object moves, interacts, and changes within a scene.

At its core, object tracking answers questions that static detection cannot: Where did the object come from? Where is it going? Has it interacted with other objects? This continuity transforms raw visual data into a structured timeline of events. A tracker might observe a person entering a building, walking to a counter, and exiting moments later, all while maintaining the same identity across frames.

From Detection to Understanding

The evolution from object detection to object tracking marks a fundamental shift in how visual systems interpret the world. Object detection operates on individual frames, identifying and labeling items such as cars, people, or bicycles without any connection to previous or future observations. This works well for static images or short analyses but fails to capture the continuity of motion and interaction that defines real-world activity.

Object tracking bridges this gap by linking detections across time. Instead of treating each detection as an isolated event, a tracker maintains a consistent identity for every object throughout a video sequence. This allows the system to understand not only what is in the scene but also how it moves, where it came from, and what it might do next. Through motion trajectories, the model records direction, speed, and persistence. When combined with spatial awareness, it can even infer relationships between objects, such as vehicles yielding to pedestrians or groups moving together through a crowd.

Modern tracking algorithms take this further by incorporating temporal reasoning and predictive modeling. They can anticipate an object’s next position, recover it after occlusion, and recognize changes in behavior over time. This continuous interpretation transforms computer vision from a reactive tool into a predictive system, one capable of drawing insights from motion patterns and context.

Tracking provides the foundation for higher-order understanding, such as intent recognition, anomaly detection, and behavioral analytics. In traffic systems, it enables the prediction of potential collisions. In surveillance, it highlights unusual movement patterns. In industrial automation, it supports workflow optimization by analyzing how machines or people interact over time.

Why Context Matters in Computer Vision

In computer vision, context refers to the surrounding information that gives meaning to what a system sees. It includes three key dimensions: spatial, temporal, and semantic. Spatial context involves how objects relate to each other and to their environment. Temporal context captures how these relationships evolve. Semantic context interprets the purpose or intent behind movements and interactions. Without these layers, visual systems operate in isolation, able to detect objects but unable to understand their roles or relationships within a scene.

Object tracking introduces this missing context by preserving continuity and motion across frames. Through consistent identity assignment, it allows a model to follow how objects behave, anticipate how they might move next, and interpret intent behind those actions. For instance, a tracker can distinguish between a pedestrian walking along the sidewalk and one who steps onto the street. It can recognize that a car slowing near an intersection is preparing to turn or stop. These distinctions are impossible without temporal reasoning.

Context also transforms the capabilities of computer vision systems. With tracking, they move from reactive to predictive intelligence. Instead of simply identifying what exists in a frame, they learn to infer what is happening and what might happen next. This transition enables richer decision-making in real time. In safety-critical domains like autonomous driving or surveillance, predictive awareness can be the difference between passive observation and proactive response.

By embedding spatial, temporal, and semantic context, object tracking gives computer vision the depth it has long lacked. It connects perception to understanding and transforms visual AI into a system capable of reasoning about the dynamic nature of the world it observes.

Object Tracking Techniques in Computer Vision

Modern object tracking has evolved into a sophisticated field that combines geometry, motion modeling, and deep learning. Contemporary systems are not limited to following an object’s position but instead seek to model how objects behave, interact, and evolve within a scene. Several core techniques underpin this transformation, each contributing to more robust and context-aware performance.

Temporal Continuity

At the heart of tracking lies frame-to-frame association,  the process of linking an object’s detections across consecutive frames. Traditional methods relied on motion models such as the Kalman Filter or optical flow to estimate where an object would appear next. Modern deep learning trackers enhance this by learning temporal embeddings that encode both visual similarity and predicted motion patterns. Temporal continuity ensures that each tracked entity maintains a stable identity, even as it moves rapidly, changes appearance, or momentarily leaves the camera’s view.

Multi-Cue Integration

Accurate tracking depends on fusing multiple sources of information. Appearance features extracted from deep convolutional or transformer networks describe how an object looks, while motion cues capture its speed and direction. Geometry and depth provide structural context, and semantic cues embed object category or intent. Integrating these diverse signals allows trackers to remain reliable even when one cue, such as appearance under poor lighting, fails. The best modern systems treat tracking as a multi-sensory perception problem rather than a single-signal task.

Scene-Level Reasoning

Real-world environments rarely contain isolated objects. Scene-level reasoning helps trackers interpret interactions between multiple entities. By modeling how objects influence each other’s motion, such as vehicles avoiding collisions or groups of pedestrians moving together, trackers achieve a higher level of understanding. Some approaches use social behavior modeling or motion graphs to capture these dependencies, enabling the system to predict how the scene will evolve as a whole rather than simply following individual objects.

Unified Architectures

Recent advances have produced end-to-end architectures that jointly perform detection, association, and prediction. Transformer-based models and spatio-temporal graph neural networks represent the leading edge of this trend. These architectures process video as a sequence of interrelated frames, learning long-range dependencies and global motion coherence. By reasoning about objects collectively instead of in isolation, unified trackers achieve higher accuracy, fewer identity switches, and improved robustness in dynamic or crowded environments.

Key Applications of Object Tracking

Object tracking provides the temporal intelligence that turns perception into understanding. Its ability to maintain consistent identities and interpret motion across time has made it foundational to several industries that depend on dynamic visual data.

Autonomous Mobility

In autonomous vehicles, tracking enables the perception stack to move from detection to prediction. By following pedestrians, cyclists, and vehicles over time, the system can recognize intent and anticipate movement. A pedestrian slowing before a crosswalk or a vehicle drifting within a lane conveys important behavioral cues that help a self-driving system make safe, proactive decisions. Multi-object tracking also contributes to path planning, collision avoidance, and traffic flow analysis, creating a more complete situational picture of the driving environment.

Retail and Smart Environments

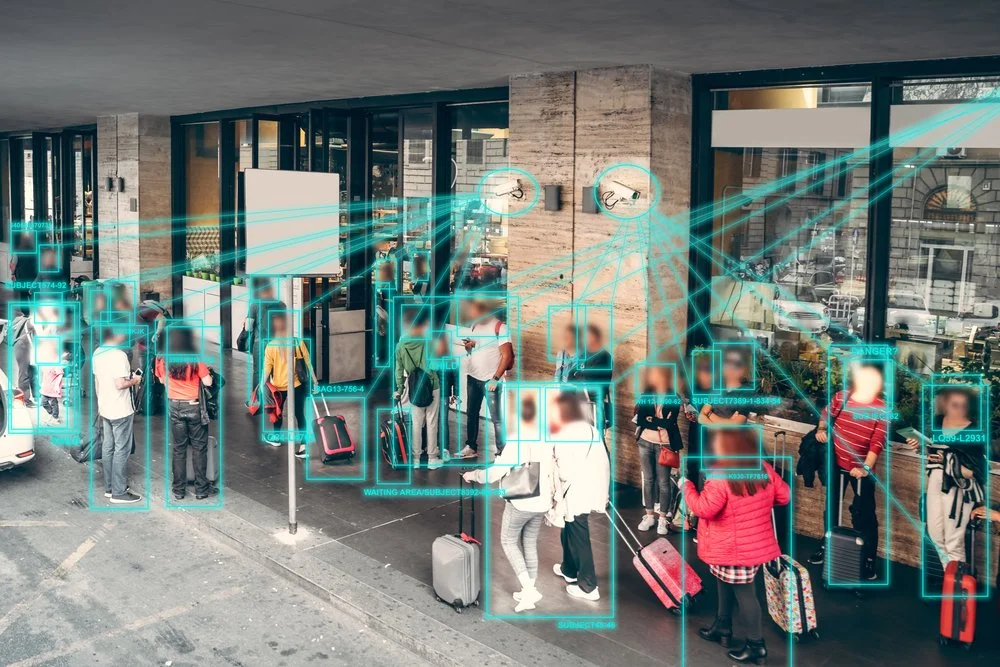
In retail analytics and smart spaces, object tracking helps transform passive video feeds into actionable insights. Tracking enables behavioral analysis, such as identifying dwell times, heatmap generation, and customer journey mapping. It supports queue management by measuring waiting times and crowd flow, and enhances store layout optimization by showing how people move through different sections. When combined with re-identification and privacy-preserving techniques, tracking provides business intelligence without compromising security or compliance.

Security and Defense

In security, defense, and public safety applications, tracking provides the continuity needed to monitor behavior and detect anomalies. Multi-camera systems rely on tracking to maintain identity across viewpoints, helping detect suspicious or coordinated movements that single-frame analysis would miss. In defense contexts, tracking supports target recognition, drone surveillance, and threat prediction by correlating object motion and patterns over extended periods.

Robotics and Augmented Reality

For robots and AR systems, object tracking delivers spatial awareness essential for real-world interaction. Robots depend on accurate motion tracking to manipulate objects, navigate cluttered environments, and avoid collisions. In augmented and mixed reality, tracking stabilizes virtual overlays and allows digital content to interact meaningfully with real-world motion. Both domains require low-latency, high-accuracy tracking to maintain contextual awareness in constantly changing environments.

Major Challenges in Object Tracking

Despite rapid progress, object tracking remains one of the most complex areas in computer vision. Real-world conditions introduce variability, uncertainty, and constraints that challenge even the most advanced algorithms.

Occlusion and Visual Variability

Occlusion, when one object blocks another, is a fundamental challenge. In crowded or cluttered environments, tracked objects may disappear for several frames and reappear later in different positions or poses. Changes in lighting, motion blur, or camera angles further distort appearance cues, making consistent identity maintenance difficult. Robust tracking systems must predict object trajectories and rely on temporal continuity or motion models to recover from such interruptions.

Maintaining Identity over Long Sequences

Long-term tracking requires maintaining consistent identities over extended time periods, sometimes across multiple cameras. Re-identification techniques attempt to match the same object after it re-enters the scene, but appearance changes and camera inconsistencies can cause identity switches. Building reliable re-identification embeddings that remain stable across contexts is a continuing research focus.

Balancing Speed and Accuracy

Many use cases, such as autonomous driving or robotics, require real-time performance. High-accuracy deep learning models are often computationally heavy, leading to latency and high energy costs. Conversely, lightweight models may struggle with precision under complex conditions. Achieving this balance involves model optimization, quantization, and efficient feature extraction to sustain accuracy without sacrificing speed.

Scalability in Dense Environments

Tracking hundreds of objects simultaneously, as in crowded intersections or retail spaces, introduces scalability issues. Systems must manage memory efficiently, handle overlapping trajectories, and minimize false associations. Multi-target tracking under such load demands architectures that can reason globally rather than process each object independently.

Data Diversity and Annotation

High-quality tracking datasets are labor-intensive to create, as they require frame-by-frame labeling of object identities and trajectories. The lack of annotated data for diverse environments and object types limits the generalizability of many models. Synthetic data generation and self-supervised learning are emerging as partial solutions, but large-scale, domain-specific annotation remains critical for advancing real-world performance.

Recommendations in Object Tracking

The following recommendations reflect best practices emerging from recent research and industry applications.

Fuse Multiple Cues for Robustness

No single signal, appearance, motion, geometry, or semantics is reliable across all conditions. Combining them improves resilience. Appearance features provide visual consistency, motion cues preserve temporal continuity, geometry constrains trajectories within realistic bounds, and semantic information adds behavioral context. Multi-cue fusion ensures that when one input degrades, others sustain reliable tracking.

Use Re-Identification and Memory Modules

In long-term or multi-camera settings, integrating re-identification (ReID) embeddings allows a system to recover object identities even after temporary loss or occlusion. Memory modules that store recent embeddings or motion states enable re-association, reducing ID switches and fragmentation. This capability is vital in surveillance, retail analytics, and traffic management, where continuity defines accuracy.

Integrate Scene Knowledge and Spatial Priors

Embedding scene-specific knowledge, such as maps, lanes, or walkable zones, constrains object trajectories to realistic paths. This not only improves accuracy but also reduces false positives. For instance, in autonomous driving, limiting motion predictions to road boundaries ensures physically plausible tracking and reduces computational load.

Balance Speed and Efficiency

Deployable tracking systems must meet real-time performance requirements. Use model optimization techniques such as pruning, quantization, and lightweight backbones to accelerate inference. For large-scale deployments, consider distributed processing pipelines that offload compute-intensive steps to edge or cloud servers.

Embrace Adaptive and Online Learning

Static models degrade over time as environmental conditions change. Online adaptation, updating model weights or parameters in response to new data, helps maintain accuracy. Techniques such as self-supervised fine-tuning, domain adaptation, and continual learning can extend model lifespan without full retraining.

Build and Curate Diverse Datasets

Tracking performance depends heavily on the diversity and representativeness of training data. Invest in datasets that capture a range of motion patterns, object types, and environmental conditions. Synthetic data, when paired with real-world footage, can help fill annotation gaps and improve generalization.

Read more: How Object Detection is Revolutionizing the AgTech Industry

How We Can Help

At Digital Divide Data (DDD), we understand that successful object tracking depends on more than algorithms; it depends on data quality, annotation precision, and scalable integration. Our teams combine domain expertise with deep technical capability to help organizations build end-to-end computer vision pipelines that are both context-aware and deployment-ready.

We design workflows that ensure consistent object identity labeling across frames, handle complex occlusions, and preserve spatial-temporal relationships. For projects involving multi-camera or long-duration sequences, DDD implements advanced re-identification annotation protocols to maintain accuracy and continuity.

Read more: Video Annotation for Generative AI: Challenges, Use Cases, and Recommendations

Conclusion

From autonomous vehicles to intelligent surveillance and robotics, the ability to maintain continuity and context has become essential. Modern object tracking architectures, powered by transformers, graph neural networks, and multi-cue fusion, are redefining what it means for machines to “see.” They enable systems to interpret not just what is in a scene, but how and why things move, interact, and evolve.

Yet, even as algorithms advance, success in object tracking continues to depend heavily on high-quality data, precise annotations, and scalable training workflows. The best technology cannot perform well without accurate temporal labeling and real-world variability captured in its data.

Partner with DDD to build object tracking solutions that see and understand the world in motion.


References

  • De Plaen, R., Zhu, H., & Van Gool, L. (2024). Contrastive Learning for Multi-Object Tracking with Transformers. In Proceedings of the IEEE/CVF Winter Conference on Applications of Computer Vision (WACV 2024).

  • Tokmakov, P., et al. (2024). CoTracker: Joint Point Tracking with Transformers. In Proceedings of the European Conference on Computer Vision (ECCV 2024).

  • NVIDIA Developer Blog. (2024, May). Mitigating Occlusions with Single-View 3D Tracking. Retrieved from https://developer.nvidia.com/blog


FAQs

What is the difference between online and offline tracking?
Online tracking processes each frame sequentially in real time, updating tracks as new frames arrive. Offline tracking, by contrast, uses the entire video sequence at once, enabling global optimization of trajectories but making it unsuitable for live applications such as robotics or surveillance.

How do object trackers handle partial or full occlusion?
Most modern object trackers use motion prediction combined with re-identification embeddings to infer where an object is likely to reappear. Some deep models also learn occlusion patterns, allowing them to maintain identity even when visual evidence is temporarily missing.

What is multi-object tracking, and how is it different from single-object tracking?
Single-object tracking focuses on one target at a time, often using initialization in the first frame. Multi-object tracking (MOT) simultaneously detects and associates multiple instances across frames, requiring robust ID management, data association, and re-identification mechanisms.

Can synthetic data improve tracking performance?
Yes. Synthetic datasets can fill gaps in rare scenarios, like extreme weather, night-time scenes, or unusual motion, by generating annotated sequences at scale. When properly mixed with real footage, synthetic data enhances model robustness and generalization.

How Object Tracking Brings Context to Computer Vision Read Post »

Scroll to Top
