Celebrating 25 years of DDD's Excellence and Social Impact. ✖

Author name: udit khanna

Udit Khanna leads the delivery of scalable AI and data solutions at Digital Divide Data, with a deep specialization in Physical AI. With a background in presales, solutioning, and customer success, he brings a mix of technical depth and business fluency, helping global enterprises move their AI projects from prototype to real-world deployment without losing momentum.

Avatar of udit khanna
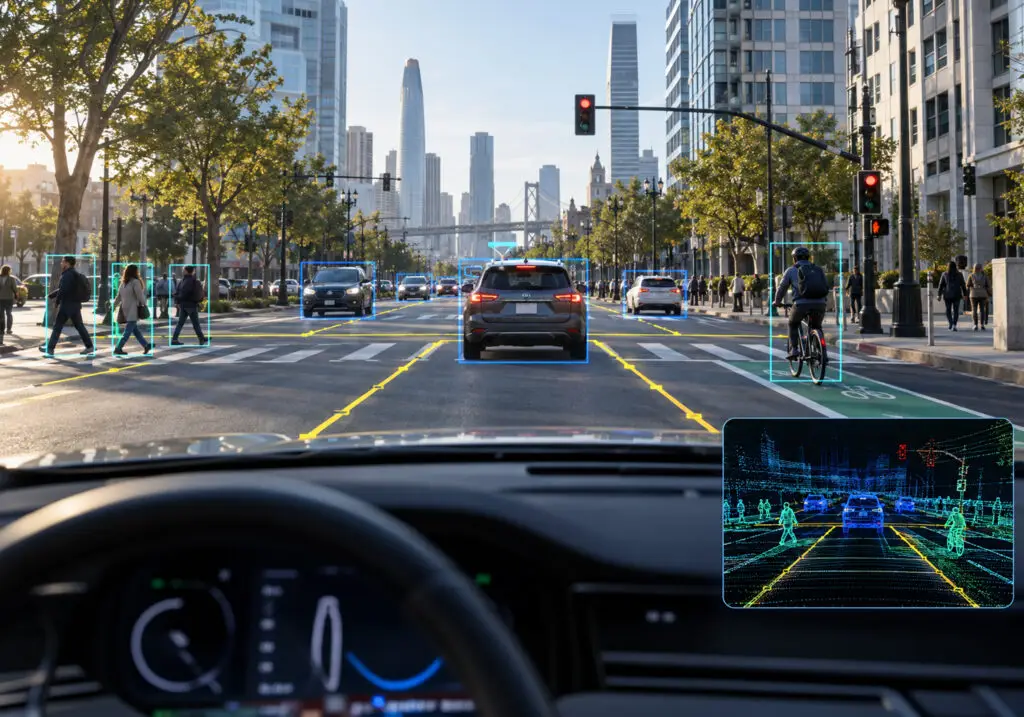
Urban driving scene illustrating sensor fusion annotation using camera and LiDAR data for autonomous vehicle perception.

How to Run a Sensor Fusion Annotation Pilot including Acceptance Metrics and Evidence Checklist

Sensor fusion annotation pilot acceptance should rest on measurable evidence that both sides agree on before the first frame is labeled. The core measures are 3D geometric accuracy, camera-LiDAR projection consistency, track identity continuity, and first-pass quality, each scored per scenario slice against a blind gold set. Competing suppliers should work on identical data, guidelines, and scoring scripts, with the buyer owning adjudication. A passed pilot shows a supplier’s quality ceiling, so production readiness needs its own evidence.

Camera and LiDAR labels can each look correct in isolation and still disagree once they are projected into the same frame. That disagreement rarely shows up in a supplier demo, which is why teams evaluating multisensor fusion annotation vendors or robotics data services need a pilot designed to expose it. A well-built pilot turns the buyer’s question about consistency and calibration across camera and LiDAR labels into numbers two suppliers can be compared on.

Key Takeaways

  • Agree on clear pass-or-fail rules before the pilot starts, so no one argues later about what “good” means.
  • Check that camera and LiDAR labels match each other, because each can look right on its own and still disagree when combined.
  • Test every supplier on the same data and instructions, with enough examples of rare situations, such as night driving, to judge them fairly.
  • Score the work against hidden test samples the suppliers cannot spot, and let the buyer settle any disputed labels.
  • Count work that passed the first time separately from work that needed fixing, since repeated fixes become an extra cost once volumes grow.
  • Treat a passed pilot as a starting point, and ask each supplier for the same proof of quality, staffing, and capacity before you buy.

What Is a Sensor Fusion Annotation Pilot and What Does Acceptance Mean?

A sensor fusion annotation pilot is a time-boxed, paid trial in which a supplier labels a sample of the buyer’s own multi-sensor logs under production-like conditions. The output usually combines 2D boxes or segmentation on camera frames with 3D LiDAR point cloud annotation, linked by shared object IDs across sensors and time. Some programs add radar returns, which carry velocity cues for object association. Multi-sensor annotation, camera-LiDAR fusion labeling, and 2D-3D linked annotation all describe the same deliverable.

Acceptance is the pre-agreed rule that decides whether a delivered batch passes. It names the metric, the threshold, the sampling method, and the person who scores the result. Without that rule in writing before work starts, most pilots end in a negotiation over what “good” meant. ITU-T Recommendation F.749.23, approved in August 2026, now sets out content, method, data format, and acceptance criteria for bird’s-eye-view (BEV) fusion annotation in automated vehicles.

Fusion labels also depend on calibration data that usually comes from the buyer’s sensor rig. Intrinsic calibration describes each camera’s lens and focal properties. Extrinsic calibration describes where each sensor sits relative to the others, and time synchronization aligns their timestamps. The MultiCorrupt benchmark found that miscalibration and mismatched sampling rates create spatial and temporal misalignment between LiDAR and camera data, and that detector robustness varies with the fusion strategy. A pilot that never tests how a supplier detects and escalates calibration problems tells the buyer little about production logs.

Which Measures Belong in a Sensor Fusion Annotation Pilot?

The measures should mirror the failure modes that hurt fused perception models. Aggregate accuracy hides most of them. Report each measure per class and per scenario slice from the operational design domain (ODD), such as night, rain, dense traffic, and long range. Five groups of measures cover most programs.

Measure group What it checks Typical metrics
3D geometric accuracy Cuboid position, size, and heading against the gold set 3D IoU, BEV IoU, center error (m), yaw error (degrees)
Detection completeness Missed and spurious objects, including small and distant ones Recall and precision at an agreed match threshold
Cross-modal consistency Whether 3D and 2D labels describe the same object in the same place Projected-cuboid vs. 2D-box IoU, cross-sensor ID match rate
Temporal and identity consistency Stable object identity and placement across frames ID switches per 100 tracks, track fragmentation, motion-compensated placement error
Operational quality How the supplier behaves while producing labels First-pass acceptance, rework cycles, guideline query rate, throughput

How is cross-modal consistency between camera and LiDAR labels measured?

Cross-modal consistency deserves the most attention because single-sensor QA cannot see it. A supplier can score well on cuboid IoU and on 2D boxes separately while the two disagree after projection. Checking each projected cuboid against its linked 2D label is the most direct test of how a supplier handles consistency and calibration across camera and LiDAR labels. The same check should confirm that one physical object carries one ID in every sensor view.

Why do temporal errors need their own measures?

Temporal errors are easier to miss than geometric ones. A WACV 2026 study of systematic errors in 3D box annotations found boxes in public driving datasets misplaced by up to 2.5 m, with highly dynamic objects most affected. The cause was timing: a rotating LiDAR observes different parts of a moving object at different moments within one sweep. A pilot should therefore include fast-moving objects and score their placement against motion-compensated gold labels.

What thresholds are realistic for 3D cuboids?

Thresholds should reflect what careful humans can achieve on the same data. In a human label study on the Waymo Open Dataset, experienced labelers matched verified ground truth at about 81% mean 3D IoU and 88% BEV IoU. Agreement fell from about 86% 3D IoU within 30 m to about 73% beyond 50 m. Range-banded thresholds, set from the buyer’s own internal agreement on the gold set, avoid failing good suppliers on normal variation.

How Can Two Suppliers Be Tested Fairly?

A fair comparison removes every difference except the suppliers themselves. Most unfair pilots break on small things, such as one supplier receiving a clarification by email that the other never saw. These controls keep the comparison clean:

  • Same input: identical sequences, calibration files, and sensor metadata, stratified across the slices that matter.
  • Same guideline version: one frozen document, with every clarification published to both suppliers through a shared query log.
  • Same output schema: a common export format, so one scoring script evaluates both deliveries.
  • Same time box and volume: equal deadlines, with delivery timestamps recorded.
  • Blind gold set: buyer-adjudicated items mixed into the batch, so suppliers cannot tell which items are scored.
  • Blind scoring: reviewers see deliveries under neutral supplier codes.
  • Declared staffing: each supplier names the pilot team and confirms that team will start production.

The staffing declaration matters more than it looks. A common red flag is quality that drops after the first batch, which suggests a supplier placed its strongest annotators on the pilot. A second, smaller batch scored a few weeks later tests whether the first result holds.

Who Should Adjudicate Disputed Annotations?

The buyer should own adjudication, because the buyer owns the definition of ground truth. A small panel works well: a perception engineer who knows how the model consumes labels, the guideline owner, and a senior reviewer who did not label the item. Suppliers should be able to appeal a scored error with evidence, such as a camera frame showing an occluded object.

Every dispute should be logged with a root cause. Three causes cover most cases: annotator error, guideline ambiguity, and gold set error. Only annotator errors should count against a supplier. Guideline ambiguities trigger an update issued to both suppliers, and gold errors are corrected and rescored for everyone.

Differences within the range of normal human variation should not be scored as errors at all. Measuring that range on the buyer’s own data keeps adjudication focused on real mistakes.  Well-designed inter-annotator agreement protocols make these boundaries explicit and provide a consistent framework for reviewing disagreements at scale.

Should Reworked Outputs Count in First-Pass Acceptance?

First-pass acceptance should count only items that passed on first submission. Reworked items belong in a separate final acceptance rate, reported with the number of rework cycles and the time each cycle took. Blending the two hides the cost that production will carry.

The gap between the two rates is often the most useful number in the pilot. A supplier with high final acceptance and low first-pass acceptance depends on the buyer’s reviewers to find its errors. At production volume, that review effort becomes a hidden cost that the per-label price does not show.

Both rates should carry into the contract. The pilot’s first-pass result becomes the baseline for the rework trigger, measured with the same gold set protocol. An AI training dataset SLA is where those rework terms, turnaround commitments, and cost responsibilities become enforceable.

How Much Pilot Data Is Enough?

Enough data is the amount that supports a confident decision on each slice that matters. Counting frames overstates the evidence, because consecutive frames in a sequence are highly correlated. Count independent sequences and labeled objects per slice instead.

A simple statistical rule helps with sizing. If a supplier makes zero errors on n independent objects, the 95% upper bound on its true error rate is roughly 3/n. Supporting an error rate below 1% on a slice therefore needs about 300 clean objects in that slice. Rare slices, such as pedestrians at night or motorcycles at long range, usually set the pilot size.

Most programs control cost by sampling rare slices more heavily than their natural frequency. The pilot also needs enough consecutive frames per sequence to measure ID switches and track fragmentation. A few long sequences reveal more about temporal consistency than many isolated frames.

Does Passing a Pilot Prove Production Readiness?

A pilot shows what a supplier can do under close attention on a small batch. Production readiness depends on whether that quality holds when volume, staff, and data conditions change. Those are separate questions, and they need separate evidence.

Useful readiness evidence includes a surge test at several times pilot throughput, annotator qualification records, and a ramp plan with named leads. It also includes proof that the supplier catches calibration drift when new vehicles or sensor rigs enter the data. Security posture matters for automotive work, where TISAX alignment is often expected.

The strongest signal is a second blind batch scored after ramp-up, using the same gold set protocol. If the result holds on that batch, the buyer has evidence about the operation as well as the labels. This is also where many AI pilots fail to scale because throughput, reviewer calibration, and feedback loops often weaken once production volume increases.

What Evidence Checklist Supports Sensor Fusion Annotation Pilot Acceptance?

Before procurement, each supplier should hand over the same set of artifacts. Comparing these side by side is more reliable than comparing headline accuracy claims. The checklist below works as an acceptance gate:

  1. A calibration validation report showing how intrinsic, extrinsic, and time-sync issues were detected and escalated.
  2. The frozen guideline version, with the full query log and every clarification issued.
  3. A per-slice metric report covering 3D geometry, detection completeness, and projection consistency.
  4. A track continuity report with ID switches and fragmentation per sequence.
  5. An error taxonomy with counts by class, slice, and root cause.
  6. The adjudication log, including disputes, outcomes, and gold set corrections.
  7. First-pass and final acceptance rates, with rework cycle counts and turnaround.
  8. Item-level lineage recording annotator, reviewer, QA pass, and timestamp.
  9. A staffing and ramp plan, with qualification records for the production team.
  10. Security and compliance evidence relevant to the data and region.

A supplier that cannot produce one of these artifacts during the pilot is unlikely to produce it at production volume. Missing evidence should count as a failed criterion, with the same weight as a missed metric threshold. Agreeing on that rule before the pilot avoids disputes after the results arrive.

How Digital Divide Data Can Help

Digital Divide Data runs sensor fusion pilots around the evidence described above. DDD’s multisensor fusion data services start with perception goals, sensor stack, and quality benchmarks agreed with the client. Work then moves through calibrated ingestion, cross-sensor annotation, and multi-layer QA for spatial, temporal, and semantic consistency. Edge cases and adverse conditions get a dedicated robustness review before delivery.

That sequence comes from production programs. In one engagement with an autonomous vehicle developer, DDD began with sensor synchronization and calibration validation. It then delivered linked 2D, 3D cuboid, and radar annotations with persistent object IDs across modalities. The multisensor fusion case study for robust autonomous perception describes how this reduced radar-camera association errors and improved 3D localization for occluded objects.

For pilots, DDD builds the evaluation set first, measures throughput on the team that will run production, and reports first-pass and final acceptance separately. Delivery runs under SOC 2 Type 2 and ISO 27001 controls, with TISAX alignment for automotive data. Clients get the per-slice reports, adjudication logs, and lineage records that procurement needs to compare suppliers.

Run a sensor fusion pilot that gives procurement evidence it can trust. Talk to an Expert.

Conclusion

A sensor fusion annotation pilot earns its cost when the acceptance rule, the gold set, and the adjudication process exist before the first label. Teams that set these up compare suppliers on evidence, catch cross-modal and temporal errors early, and sign contracts with baselines they can enforce. Teams that skip them compare demos, then find calibration and identity problems after the labels are already in the model.

The evidence checklist turns a supplier claim into a procurement decision. For related reading, multi-sensor data labeling covers the annotation techniques behind fused datasets. The guide on designing a pilot that proves the operation extends the production-readiness tests described here.

References

Beemelmanns, T., Zhang, Q., Geller, C., & Eckstein, L. (2024). MultiCorrupt: A multi-modal robustness dataset and benchmark of LiDAR-camera fusion for 3D object detection. https://arxiv.org/abs/2402.11677

International Telecommunication Union. (2026). Recommendation ITU-T F.749.23: Requirements for bird’s-eye view sensor fusion data labelling in connected and automated vehicles. ITU-T Study Group 21. https://www.itu.int/rec/T-REC-F.749.23-202608-P

Miro, A. J., af Klinteberg, L., Timus, B., Asefaw, A., Khoche, A., Gustafsson, T., Mansouri, S. S., & Daneshtalab, M. (2026). Correcting and quantifying systematic errors in 3D box annotations for autonomous driving. 

https://openaccess.thecvf.com/content/WACV2026/html/Miro_Correcting_and_Quantifying_Systematic_Errors_in_3D_Box_Annotations_for_WACV_2026_paper.html

Qi, C. R., Zhou, Y., Najibi, M., Sun, P., Vo, K., Deng, B., & Anguelov, D. (2021). Offboard 3D object detection from point cloud sequences. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR). https://arxiv.org/abs/2103.05073

Frequently Asked Questions

Which services address consistency and calibration across camera and LiDAR labels?

Look for multisensor fusion annotation services that validate calibration and time sync before labeling, link 2D and 3D labels with persistent object IDs, and check every projected cuboid against its 2D label. In a pilot, ask each supplier to prove this with a calibration validation report and a per-slice projection consistency report.

What IoU threshold should I use to accept 3D cuboid labels?

Set it from measured human agreement on your own data, and band it by range. In one Waymo Open Dataset study, experienced labelers reached about 81% 3D IoU and 88% BEV IoU against verified ground truth, with lower agreement at long range, so stricter thresholds tend to penalize normal variation.

Should the gold set be hidden from annotation suppliers?

A hidden gold set mixed into the regular batch means the supplier cannot give scored items extra attention, so the score reflects normal work. Scoring deliveries under neutral supplier codes keeps the comparison fair as well.

Why count sequences instead of frames when sizing a pilot?

Consecutive frames in one sequence are highly correlated, so many frames from the same drive add little independent evidence. Counting independent sequences and labeled objects per slice gives a truer picture, and long sequences are also needed to measure ID switches and track fragmentation.
How to Run a Sensor Fusion Annotation Pilot including Acceptance Metrics and Evidence Checklist Read Post »

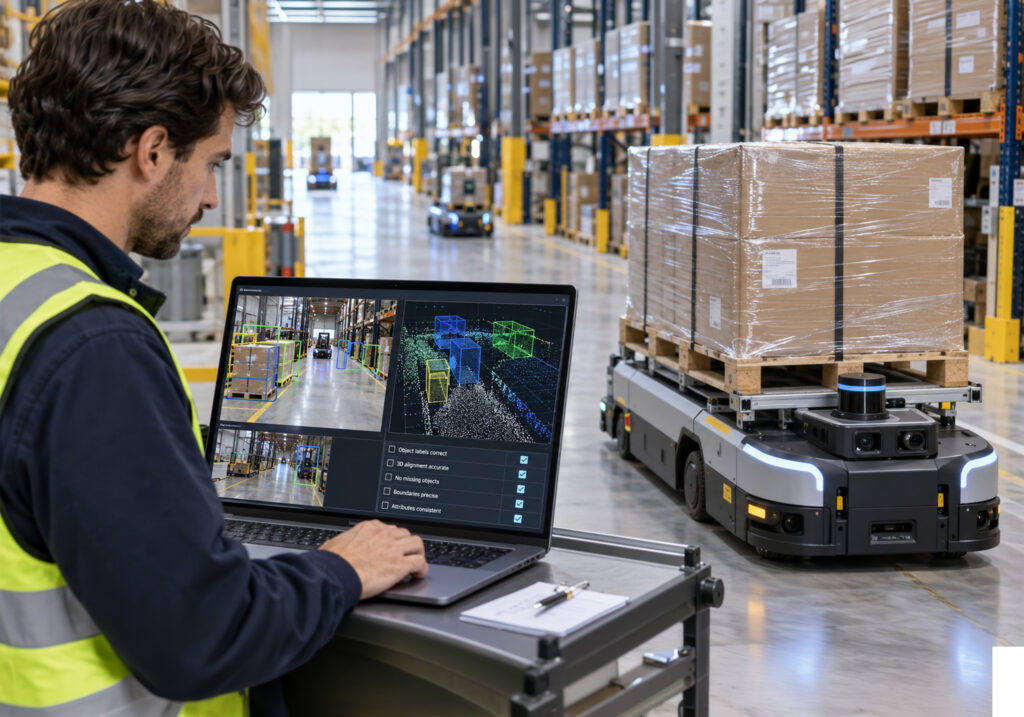
Warehouse engineer reviewing camera and LiDAR data on a laptop beside an autonomous pallet-carrying robot.

How Warehouse Robot Camera and LiDAR Annotation Works, From Labels to Quality Checks

Warehouse robot camera LiDAR annotation works best, when the buyer settles three things before labeling starts. Those are a warehouse-specific taxonomy, written rules for occlusion and partial objects, and a QA plan built on calibration and sync checks. Any supplier offering sensor data annotation for warehouse robots should prove those rules on your own sequences in a stratified pilot. 

Warehouse perception sits in an awkward middle ground. The sensors and file formats resemble autonomous driving, while the objects, distances, and failure modes belong to a very different world. Teams that scope robotics data services for autonomous forklifts with driving assumptions tend to pay for rework once stretch-wrapped pallets reach the labeling queue.

Key Takeaways

  • Warehouses are very different from public roads, so labeling rules written for self-driving cars need to be reworked for pallets, racks, and people working close to the robot.
  • Every label should connect to a real decision the robot makes, such as where it can safely drive or how to pick up a pallet.
  • Clear written rules for hidden or partly visible objects keep every labeler working the same way on the hardest scenes.
  • The choice between buying a labeling tool and hiring a full-service team depends mostly on who will keep the rules updated as your needs change.
  • A supplier’s self-driving car experience shows they have strong processes, while their warehouse know-how still has to be proven on your own data.
  • Share real sample data and sensor setup details up front, then test suppliers with a small trial that covers every warehouse condition and is checked against answers your team already trusts.

What Does Warehouse Robot Camera LiDAR Annotation Involve, and How Is It Different From Driving Data?

Warehouse robot camera LiDAR annotation is the labeling of synchronized RGB images and 3D point clouds captured by autonomous mobile robots (AMRs), automated guided vehicles (AGVs), and autonomous forklifts. It usually pairs 2D boxes or masks on camera frames with 3D cuboids or point-level segmentation on LiDAR, linked by shared object IDs. When both views of the same object must agree, the work becomes multisensor fusion annotation, which depends on calibration and timestamp alignment as much as on labeling skill. Some programs also add depth-camera data for close-range tasks such as fork alignment.

The domain differs from road driving in ways that change the labeling rules. KIT researchers building an automated annotation framework for industrial LiDAR data note that most public datasets, such as KITTI and Waymo, focus on roads. They also point to a shortage of freely available labeled LiDAR from warehouses and industrial halls. Most programs therefore build their own ground truth, which puts more weight on the buyer’s scope decisions. The main differences show up in five areas:

  • Range: Most relevant objects sit close to the robot, so small position and yaw errors carry more weight than at road distances.
  • Dual-role objects: A pallet is an obstacle to avoid and a target to engage, so it needs both detection and pose labels.
  • Surfaces: Stretch wrap, metal racking, and dock plates cause reflections, ghost points, and missing returns.
  • Lighting: Brightness swings between dock doors and trailer interiors within a single task.
  • People: Workers on foot move close to the robot and often appear half-hidden by racks or loads.

What Labels Should a Warehouse Camera and LiDAR Project Include?

Start from the robot’s decisions and work back to the classes. A navigation stack needs to know where it can drive and what might move. A pallet-handling stack needs pallet pose and fork-pocket geometry. Labels that no downstream model consumes add cost without adding capability, so each class should map to a specific model output. Most warehouse taxonomies cover five groups:

  • Dynamic agents: People, manual forklifts, pallet jacks, tuggers, and other robots, with 3D cuboids, 2D boxes, and track IDs that persist across frames and sensors.
  • Load carriers: Pallets by type and material, loaded or empty, wrapped or unwrapped, with yaw and fork-pocket locations.
  • Static infrastructure: Rack uprights and beams, shelving bays, walls, columns, dock doors, and dock plates, often as segmentation or cuboids.
  • Floor and free space: Drivable area, floor markings, and hazards such as spilled liquid, debris, strapping, and wrap scraps.
  • Attributes: Occlusion level, truncation, a reflective-surface flag, lighting condition, and high-visibility clothing on people.

Fork pockets deserve their own class and their own QA threshold. A 2025 study of pallet and pallet-hole detection for forklifts reported up to 95% pallet detection accuracy, against 72% for pallet holes. The authors traced the gap to holes resembling shadows and gaps at a distance, and annotators face the same ambiguity. In multi-sensor data labeling framework, cross-modal consistency rules help resolve these cases by checking whether camera annotations align with corresponding LiDAR geometry rather than relying on a single modality alone.

How Should a Supplier Handle Partial Pallets, Racks, and Occlusions?

Occlusion is constant in a warehouse, so the guideline has to settle it before annotators do. Pallets sit behind other pallets, people step out from between racks, and loads overhang their bases. Without written rules, each annotator invents a policy. Inter-annotator agreement then falls apart on the frames the robot finds hardest. A usable occlusion policy covers six points:

  • Extent convention: Decide whether cuboids cover the full estimated object or only the observed points, and apply the same choice in both modalities.
  • Minimum evidence: Define how many LiDAR points or what visible fraction justifies a label, and when an object moves to an ignore region.
  • Partial pallets: Label the pallet base and its load separately, and record when the base is hidden but the load is visible.
  • Racks: Where the robot localizes reliably, label static racking once in an aggregated, registered map and project those labels into each scan. This keeps rack geometry consistent and avoids redrawing the same uprights in every frame.
  • Reflective surfaces: Flag stretch-wrapped loads and shiny surfaces, and state how to treat ghost points and missing returns.
  • Track continuity: Keep the same ID when an object leaves view briefly, and define how many frames count as briefly.

Moving objects need a timing rule as well. A WACV 2026 study of systematic errors in 3D box annotations found boxes in public driving datasets misplaced by up to 2.5 m. Highly dynamic objects were the most affected, because a rotating LiDAR observes each object at a slightly different time. Forklifts move slower than cars but operate much closer to the robot, so small offsets still matter. Ask each supplier how its tooling handles per-point timestamps and motion compensation.

How Do You Compare an Annotation Platform With a Managed Annotation Service?

An annotation platform sells software, and your team runs the work. A managed service sells labeled output against a specification, while the supplier runs the workforce, guidelines, and QA. Many programs settle on a hybrid, pairing the buyer’s platform with the supplier’s trained annotators. The right choice depends on who will own guideline changes when the taxonomy shifts, as robotics taxonomies usually do.

Factor Annotation platform Managed annotation service
QA ownership Your team builds review queues and audits Supplier runs layered review against agreed metrics
Guideline changes You write and update every rule Supplier drafts edge-case rules for your approval
Fusion tooling Must load your formats and project 3D boxes into every camera Supplier’s tooling, which you should test on your data
Scaling limit Your annotation operations staff Supplier’s pool of trained annotators
Best fit Stable taxonomy and an in-house annotation ops lead Shifting taxonomy, volume swings, or a thin ops team

Whichever route you choose, test the tool on your own synchronized data before signing. Check that it loads your log format, projects 3D boxes correctly into every camera, and keeps track IDs across modalities. Ask who pays for rework when guidelines change after labeling starts. The wider build vs buy vs partner decision applies here, with sensor-specific tooling as an added constraint.

Can a Driving Multisensor Case Study Prove Warehouse Robotics Experience?

It proves part of what you need. A driving fusion project shows process capability: calibration validation, timestamp alignment, 3D cuboids, cross-modal ID persistence, and QA at volume. Those skills transfer directly and are hard to fake. The MultiCorrupt benchmark of LiDAR-camera fusion tested five detectors against ten corruption types, including spatial and temporal misalignment. Robustness varied by corruption type and fusion strategy, which is why sync and calibration discipline matter in any fused dataset.

A driving case does not prove warehouse judgment. Road guidelines say nothing about fork pockets, wrapped loads, rack beams at head height, or people half-hidden behind a pallet stack. Ask the supplier which of its driving rules it would change for your site. Then ask for a draft warehouse guideline before the pilot starts. A clear, specific answer is stronger evidence than a longer list of logos.

What Files Should Go Into the Initial Warehouse Annotation Brief?

A supplier can only quote and plan accurately from real inputs. Thin briefs produce optimistic quotes, followed by change orders once the edge cases appear. Send these files before the pilot is priced:

  1. Sample sequences: Raw logs, such as rosbag or MCAP files or per-frame point clouds and images, from every site and condition in scope.
  2. Calibration files: Camera intrinsics and LiDAR-to-camera extrinsics, versioned by robot and date, with notes on how they were validated.
  3. Sync documentation: Clock source, sensor rates, hardware or software triggering, and any known timing offsets.
  4. Rig and frame conventions: Sensor mounting heights, fields of view, coordinate frames, axis order, and yaw definition.
  5. Draft taxonomy and guideline: Classes, attributes, and edge-case rules, with visual examples of correct and incorrect labels.
  6. Gold set and acceptance criteria: Reference labels your team trusts, plus the metric thresholds the pilot must meet.
  7. Output specification: A sample label file in your target schema, with units, ID rules, and coordinate frame.
  8. Site notes: Pallet types, racking styles, dock and trailer work, lighting conditions, and shift patterns.
  9. Privacy and security terms: Treatment of faces, badges, and shipping labels, plus data residency and access controls.

Calibration and sync records belong in the brief because annotators cannot fix them. A 3D box that projects off the object in the image may be a labeling error or a calibration error. Only versioned calibration and sync records let the supplier tell which, and trace any drift back to its source.

How Should a Warehouse Annotation Pilot Be Sampled and Scored?

Sample the pilot by operating condition so every stratum the robot will meet appears several times. A random draw from fleet logs over-represents empty aisles and under-represents the frames that cause failures. Build the strata first, then fill each one with a few sequences:

  • Zones: Aisles, staging lanes, docks, trailer interiors, and charging areas.
  • Lighting: Bright dock doors, dim trailers, and night shifts.
  • Loads: Wood and plastic pallets, wrapped and unwrapped loads, and partial or damaged pallets.
  • Traffic: People and forklifts at close range, crossing paths, or hidden by racks.
  • Rigs: Each robot model or sensor configuration in the fleet.

Include continuous sequences as well as single frames, since track ID switches only show up over time. Label a gold subset internally and insert it blind into the supplier’s batch. Then score the pilot per stratum on agreed metrics:

  • Class accuracy: Precision and recall against the gold set.
  • 3D geometry: Center error, yaw error, or 3D IoU for pallets, people, and vehicles.
  • Cross-modal consistency: The share of projected 3D boxes that match their 2D labels.
  • Tracking: ID switches per sequence.
  • Process signals: Guideline questions raised, turnaround time, and pre-label correction rates.

Run a second, larger batch before committing to full volume, because quality often slips when a supplier expands the annotator pool. If the workflow uses model-generated pre-labels, monitor the correction rate closely; a rate that is unusually close to zero may indicate that annotators are accepting pre-labels without sufficient review. This is where many AI pilots fail to scale because early results may look strong, but performance often changes once the workflow expands across more annotators, higher volumes, and stricter production requirements.

How Digital Divide Data Can Help

Digital Divide Data supports warehouse perception programs with camera labeling, 3D LiDAR point cloud annotation, and fused annotation run as one workflow. Engagements start with scoping: sensor modalities, robot tasks, known failure points, and the taxonomy those imply. DDD teams then ingest and synchronize raw streams, apply AI-assisted pre-labeling with human review, and run domain expert validation against scenario-specific criteria. Multi-layer QA includes inter-annotator agreement checks and audit trails, so every delivered label is traceable.

DDD’s multisensor fusion case study for an autonomous vehicle developer shows the process side in practice. That program covered calibration and timestamp validation, 2D boxes and segmentation on images, 3D cuboids on LiDAR, and persistent object IDs across modalities. It also added scenario tagging for occlusion-heavy scenes and night-time driving. As this guide argues, a driving case proves process capability, so DDD demonstrates warehouse-specific judgment on your own data through a stratified pilot scored against your gold set.

Warehouse footage often shows workers’ faces, badges, and shipping labels. DDD handles sensor data under SOC 2 Type 2 and ISO 27001 controls, with GDPR-compliant handling of personal data. Pilots can then scale into continuous annotation pipelines as fleets and sites grow.

Build warehouse perception datasets your robots can rely on from the first batch. Talk to an Expert.

Conclusion

Warehouse perception data fails quietly when scope is vague. The taxonomy drifts, occlusion rules vary by annotator, and calibration errors surface as labeling errors months later. Buyers who fix the label set, edge-case rules, brief, and pilot design up front get a dataset they can audit and extend.

That gap widens as fleets spread across more sites and pallet types. Teams with versioned guidelines, stratified gold sets, and measurable acceptance criteria can add a new warehouse with a short pilot. 

References

Abdelhalim, G., Simon, K., Bensch, R., Parimi, S., & Qureshi, Bilal A. (2024). Automated AI-based annotation framework for 3D object detection from LiDAR data in industrial areas (SAE Technical Paper 2024-01-2999). SAE International. https://publikationen.bibliothek.kit.edu/1000172646

Beemelmanns, T., Zhang, Q., Geller, C., & Eckstein, L. (2024). MultiCorrupt: A multi-modal robustness dataset and benchmark of LiDAR-camera fusion for 3D object detection. https://arxiv.org/abs/2402.11677

Miro, A. J., af Klinteberg, L., Timus, B., Asefaw, A., Khoche, A., Gustafsson, T., Mansouri, S. S., & Daneshtalab, M. (2026). Correcting and quantifying systematic errors in 3D box annotations for autonomous driving. https://openaccess.thecvf.com/content/WACV2026/html/Miro_Correcting_and_Quantifying_Systematic_Errors_in_3D_Box_Annotations_for_WACV_2026_paper.html

Sutar, V., Maheshwari, M., & Mittal, A. (2025). Learning-based vision systems for semi-autonomous forklift operation in industrial warehouse environments. arXiv preprint arXiv:2511.06295. https://arxiv.org/abs/2511.06295

Frequently Asked Questions

Do warehouse robots need 3D cuboids, or are 2D boxes enough?

Most warehouse programs use both, linked by shared object IDs. Cuboids on LiDAR carry the position, size, and yaw that navigation and pallet handling depend on, and 2D labels on camera frames add the visual detail.

Should racks be labeled in every LiDAR frame?

Not always. Where the robot localizes reliably, teams can label static racking once in an aggregated map and project those labels into each scan. That keeps rack geometry consistent and avoids redrawing the same uprights in every frame.

How do I know an annotation supplier’s quality will hold at full volume?

Run a second, larger batch after the pilot and score it against the same blind gold set. Quality often slips when a supplier adds annotators, and a pre-label correction rate near zero can mean people are accepting model output without checking it.

Why should calibration files be part of an annotation brief?

Annotators cannot fix calibration, but they see its effects. A 3D box that projects off the object in the camera image could be a labeling error or a calibration error, and only versioned calibration and sync records show which.

How Warehouse Robot Camera and LiDAR Annotation Works, From Labels to Quality Checks Read Post »

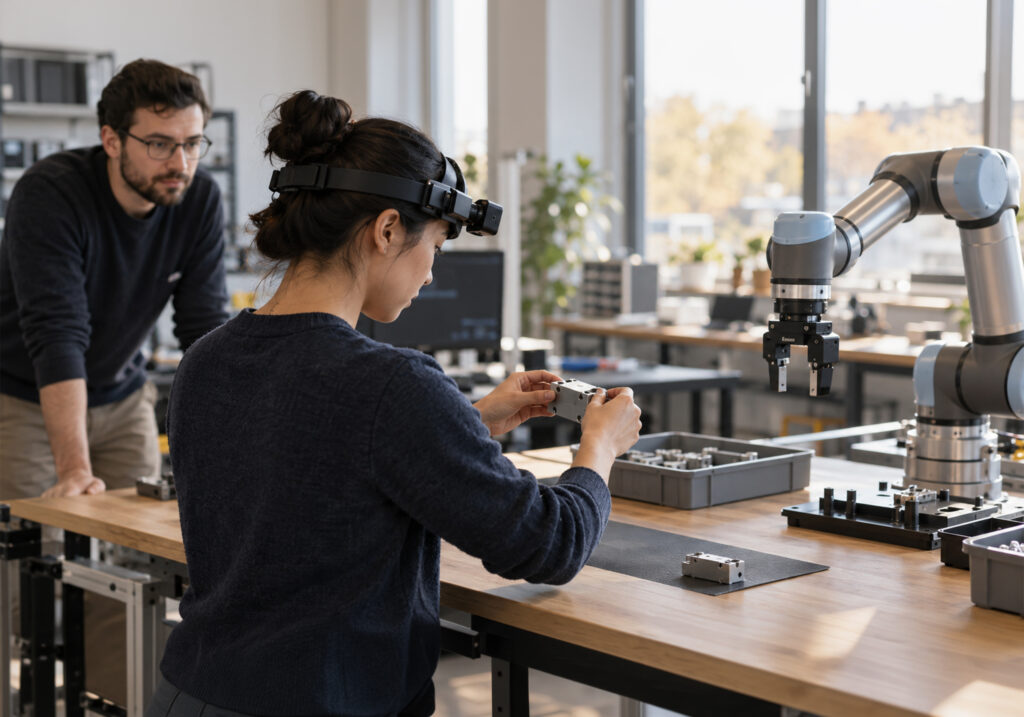
Person wearing head-mounted camera equipment performing a manipulation task beside a robotic arm

How to Choose a Custom Egocentric Data Collection Partner for Enterprise Robotics

A custom egocentric data collection partner records first-person human demonstrations of your tasks, in your environments, to your specification, and delivers them as training-ready episodes. The right partner can show a written capture protocol, measured hand-tracking quality, a documented review process, and a consent record for every participant. Suppliers of egocentric data collection differ most in how much of that evidence they can produce before a contract is signed.

Enterprise robotics teams usually reach this decision once public datasets stop matching their tasks, objects, or facilities. Proposals then arrive with different hour counts, different meanings of hand tracking, and different assumptions about permissions, which makes them hard to compare. Teams that buy robotics data for Physical AI need a brief that fixes those definitions before the first proposal arrives.

Key Takeaways

  • Judge a data collection partner by real world proof, and ask for examples of past work before you sign, then run a small paid trial with pass-or-fail rules agreed in advance.
  • Write a brief that spells out the tasks, movement data, quality checks, and permissions you need, so every supplier answers the same questions.
  • Compare suppliers on hours of usable footage and the variety of places, objects, and people recorded, because the raw hours on a quote can mislead.
  • Ask early whether the supplier can record inside your own sites with your own cameras, and how your footage will be kept secure.
  • Check the hand-movement data yourself on sample recordings, since suppliers use the same words for very different levels of accuracy.
  • Agree in writing who collects permission from the people being recorded and from anyone nearby, as missing permission cannot be fixed later.

What Is a Custom Egocentric Data Collection Partner, and When Do You Need One?

Egocentric data is sensor data recorded from the viewpoint of the person performing a task, usually through a head-mounted camera, smart glasses, or a headset. It is also called first-person, point-of-view (POV), or wearable-camera data, and one recorded task attempt is an egocentric demonstration or episode. A custom egocentric data collection partner is a supplier that designs and runs that recording program to a buyer’s specification. The work sits within managed data collection services, with added requirements for wearable hardware, pose capture, and participant permissions.

Demand for this data has grown because human demonstrations scale faster than robot teleoperation. The EgoScale study from NVIDIA and university collaborators trained a vision-language-action model on 20,854 hours of egocentric human video. It found a log-linear relationship between data volume and validation loss, and the final policy improved average success rate by 54% over a baseline without human pretraining. Results like these explain why enterprise teams now budget for human demonstration data alongside robot data.

Public datasets rarely close the gap for a commercial program. They cover general household or tabletop activity, while an enterprise robot needs demonstrations with specific parts, tools, and workstations. License terms are a second limit. Ego4D is released under its own license agreement, and the EgoDex dataset is distributed under a non-commercial license, so commercial use needs legal review first.

Which types of suppliers offer custom egocentric data collection?

Suppliers in this market fall into four groups. Each answers a brief differently, and each can be the right choice for a particular program. The brief and the pilot reveal which model a supplier actually runs:

  • Managed data service providers design the protocol, recruit and train demonstrators, operate the hardware, and run review and annotation under one contract.
  • Contributor marketplaces and crowd networks route recording tasks to large pools of contributors, who record on their own or shipped devices.
  • Dataset licensors sell existing first-person footage and sometimes commission new collections to fill gaps.
  • Annotation-first vendors label footage that the buyer supplies, and may subcontract the capture itself.

When is egocentric human data the wrong purchase?

Human egocentric video has limits that a brief should respect. It does not contain robot joint commands, force, torque, or tactile signals. Programs that need those signals still need teleoperation or other robot-native data, and the EgoScale authors report that human demonstrations amplify robot data without replacing it. A capable supplier will say this plainly when the task requires it.

What Should a Procurement Brief for Egocentric Demonstrations Include?

A comparable brief defines every term a supplier could interpret in its own favor. Four requirements carrying most of the risk including task coverage, hand tracking, quality review, and participant permissions. Capture sites, hardware, and delivery format complete the picture. Specify whether the data will support perception, hand-trajectory prediction or a vision-language-action model, commonly called a VLA model. Each use requires different observations and labels.

Ask every supplier to return the same evidence package before comparing prices. A proposal should distinguish supported capabilities, pilot commitments and dependencies on your team. The following procurement brief makes those distinctions inspectable.

Brief requirement What to specify Evidence to request
Task coverage Task list with success criteria; variations per task (objects, tools, lighting, clutter); environments; demonstrator mix (skill level, handedness, hand size); failure and recovery cases; episodes per cell. A coverage matrix filled in during the pilot, showing accepted episodes per cell.
Capture and tracking Pose source (device-native, instrumented, or estimated from video); skeleton and joint count; coordinate frame; sample rate; confidence output. Raw pose files with per-joint confidence, plus reprojection overlays on sample episodes.
Quality review Automated checks; human review sampling rate; acceptance criteria per episode; rejection codes; retake policy. Rejection log by reason, reviewer agreement figures, and yield from raw to accepted hours.
Participant permissions Consent scope (AI training, commercial use, transfer, retention); withdrawal process; bystander handling; de-identification standard. Blank consent form, per-episode consent linkage, and a de-identification QA record.
Sites and hardware Supplier sites, buyer facilities, or both; who supplies and maintains the rigs; calibration routine. Site plan, device list, and per-session calibration records.
Delivery format Episode schema; timestamps; metadata fields; file format; versioning. A sample release that loads in the buyer’s training pipeline.

 Suppliers that receive this brief must answer in the same units, which is what makes proposals comparable. The brief also exposes gaps early. A supplier that cannot say where its hand pose comes from, or who signs the consent forms, has answered the question by omission.

What Evidence Should a Custom Egocentric Collection Partner Provide?

Request a task matrix that describes the behavior your robot must learn. For warehouse picking, relevant variables could include object size, packaging, shelf height, clutter, handedness and required protective gloves. Specify which combinations are mandatory, which are exploratory and how many accepted episodes each needs. Review these distributions after rejection, because unusable recordings can leave gaps in otherwise complete capture totals.

An egocentric data collection protocol for robotics programs turns this matrix into repeatable operator instructions. Ask for episode boundaries, permitted variations, task outcomes, and rules for recording recovery attempts. Keep successful demonstrations, recoverable failures and technical recording failures distinguishable in the metadata. This prevents footage of a failed task from being mislabeled as successful supervision.

Ask for the following before the pilot is scoped, with client details removed:

  1. A written capture protocol from a previous program, covering hardware configuration, task scripts, environment setup, and failure handling.
  2. Sample episodes with raw streams: video, pose, IMU where captured, and metadata, in the original file format.
  3. A rejection log showing how many recorded hours were rejected, and for which reasons.
  4. Measured synchronization error between video and pose streams, with the method used to measure it.
  5. Demonstrator training material and the qualification test demonstrators must pass before recording.
  6. A blank consent form and a description of the de-identification workflow, including who reviews its output.
  7. A dataset card or manifest that records versions, protocol changes, and known limitations.

Two questions help separate collection operators from vendors that mainly label footage. Ask who physically operates and maintains the capture devices, and ask for the last three collection programs described in operational detail. Suppliers with field experience tend to answer with device counts, session lengths, and yield figures. Suppliers without it tend to answer with annotation case studies.

The delivery model matters as much as the evidence. Crowd-based collection offers reach across homes and geographies, with more variation in device setup and instruction compliance. Managed collection with trained demonstrators gives tighter control over scripted tasks, custom rigs, and multi-session recording. Enterprise programs that depend on precise task scripts tend to need the managed model for at least part of the dataset.

How Do You Compare Vendors When Their Proposed Hours Differ?

Hours are the least comparable number in an egocentric proposal. One supplier may quote raw recorded hours, another accepted hours after review, and a third hours of active manipulation with idle time removed. The same budget can therefore buy very different amounts of usable training signals. Comparison starts by converting every proposal to accepted hours and accepted episodes per task.

Coverage deserves more weight than volume once that conversion is done. A study of data scaling laws in imitation learning for robotic manipulation found that environment and object diversity mattered far more than the absolute number of demonstrations. Once demonstrations per environment or object passed a threshold, additional ones had minimal effect. A proposal with fewer hours across more environments, objects, and demonstrators can therefore be the stronger offer.

Price comparison should wait until proposals share the same measures. Ask each supplier to restate its offer on the points below. A supplier that declines has also told you something:

  • Accepted volume: Accepted hours and accepted episodes, with the expected yield from raw recording.
  • Coverage: Episodes per task and per variation, mapped to the coverage matrix in the brief.
  • Diversity: Number of distinct environments, object instances, and demonstrators.
  • Active time: Share of recorded time that contains active manipulation.
  • Inclusions: Whether the price covers de-identification, annotation, retakes, and format conversion.
  • Unit cost: Cost per accepted hour and cost per accepted episode.

A simple illustration shows why the conversion matters. Suppose Vendor A proposes 500 raw hours with an expected 60% acceptance rate, and Vendor B proposes 350 accepted hours. Vendor A’s offer converts to about 300 accepted hours, so the smaller headline number is the larger delivery. If Vendor B also records across twice as many workstations, the gap in training value widens further.

Ask each supplier to commit to a yield figure and to explain what happens when it is missed. A supplier that absorbs the cost of rejected hours has an incentive to train demonstrators well and catch errors during recording. A supplier that bills for raw hours has a weaker incentive to do either. Contracts that pay on accepted episodes tend to align both sides.

Can the Supplier Record in Your Own Facilities and on Your Hardware?

Many suppliers can, and the question is worth asking early because on-site capability varies widely. Recording in the buyer’s facility puts the real parts, fixtures, lighting, and clutter into the data, which is hard to reproduce in a staged environment. Recording on buyer-specified hardware keeps the camera viewpoint and intrinsics close to what the robot will see. Both choices reduce the distance between collection conditions and deployment conditions.

Research practice supports the hardware point. In EgoScale’s aligned human-robot dataset, the human demonstrations used for mid-training were recorded with the same camera configuration as the robot, with matched viewpoints and calibrated intrinsics. That aligned set was small, at roughly 50 hours of human data and 4 hours of robot data. It still grounded the much larger pretraining corpus in the robot’s sensing and control. A supplier that can operate the buyer’s rig makes this kind of aligned collection practical.

On-site work raises operational questions that suppliers answer very differently. Some bring trained demonstrators and their own device fleet, while others expect the buyer to provide both. The brief should ask each supplier to address the following points:

  • Site access: Safety induction, escorts, restricted zones, and recording hours that fit production shifts.
  • Demonstrators: Whether the supplier brings trained demonstrators or trains the buyer’s skilled operators to record.
  • Hardware custody: Who owns, stores, charges, and calibrates the devices, and how many spares stay on site.
  • Device control: Locked firmware and recording settings, with a calibration and sync check in every session.
  • Protective equipment: Gloves, sleeves, and safety glasses that can degrade hand tracking or interfere with headsets.
  • Data handling: Where footage is stored on site, how it leaves the building, and when local copies are deleted.

Facility footage is also proprietary, as it shows processes, layouts, part designs, screens, and paperwork that a buyer would not publish. The agreement should therefore cover confidentiality, access control, storage location, retention period, and verified deletion, alongside privacy terms. Suppliers that record mainly in contributors’ homes may have no standard answer for these terms.

How Do You Verify Hand Tracking Rather Than Relying on a Modality Claim?

Request raw tracking outputs alongside the corresponding video and an explanation of how each field was produced. Distinguish device-generated tracking, additional motion-capture measurements and pose inferred later from RGB video. Specify whether your model needs wrist trajectories, articulated finger joints or both. A wrist trajectory cannot describe individual finger articulation.

The EgoDex study of dexterous manipulation pairs egocentric video with hand and finger tracking captured during recording. That distinction is useful when specifying deliverables, although a supplier still needs to validate its own capture system. Ask for the following fields and measurements in the pilot package.

  • Pose definition: joint names, units, coordinate frames, handedness and transforms between camera, hand and world coordinates.
  • Tracking provenance: device and software versions, processing method, confidence fields and records of manual corrections.
  • Timing evidence: timestamp definitions, synchronization method, measured offset, drift and dropped-frame handling.
  • Failure reporting: missing joints, tracking loss, occlusion flags and behavior when hands leave the field of view.
  • Geometric validation: an independent reference and error measurement where accuracy claims require one, with uncertainty documented.

Inspect tracking overlays during grasping, contact, hand crossings and fast movement. Overlays can expose obvious errors, but they cannot establish metric 3D accuracy by themselves. Confidence scores also need interpretation because model confidence and independently measured error are different quantities. Set tolerances against your model’s requirements and validate the measurement method before using those tolerances as acceptance gates.

The evaluation of egocentric video and pose data should cover synchronization, coordinate consistency and usable task intervals together. Review results separately by task, device, site and operator so aggregate scores cannot hide a weak collection segment. Require rejection reasons and examples from each segment. This makes corrective action specific enough to improve the next batch.

Who Is Responsible for Participant and Bystander Permissions?

Responsibility is shared, and the contract should state the split in writing. The supplier usually runs the consent process, because it recruits participants and is present at recording. The buyer remains accountable for how the data is used in training and products, and should confirm the legal roles with counsel in each jurisdiction. A supplier’s assurance that data is consented does not transfer that accountability.

Ego4D remains a useful reference for a rigorous standard. Its privacy and ethics standards for egocentric data collection required informed consent from camera wearers, who could withdraw at any time and review and redact their own video. Partners also had to respect the rights of others in private spaces, avoid sensitive areas, and de-identify personal information. A commercial supplier should be able to describe its equivalent of each point.

Bystanders are the harder case, because they did not sign anything. Head-mounted cameras capture co-workers, visitors, screens, documents, badges, and reflections without anyone intending it. Common controls include posted notices, defined recording zones, sessions scheduled away from busy periods, muted audio, and blurring of faces and other identifiers. The brief should say which controls the supplier performs and which the buyer performs as site owner.

Recording the buyer’s own employees needs particular care. An employee asked by an employer to wear a camera may not feel free to decline, which weakens the value of a signature. Programs usually address this with voluntary opt-in, an equivalent assignment for those who decline, and early involvement of worker representatives where they exist. These steps remain the buyer’s responsibility even when the supplier handles the paperwork.

De-identification is a cost line that proposals often leave out. One Ego4D collection site reported roughly 780 hours of manual labor to de-identify 500 hours of video. The same paper notes that footage captured outdoors could take ten times the video length to redact. Controlled indoor workstations with a single demonstrator tend to need far less, but the effort is rarely zero. Ask whether the quoted price includes automated redaction, human review of the output, and a record of what was checked.

Permissions should be verifiable at the level of the individual episode. Each episode should link to a consent record whose scope covers AI model training, commercial use, transfer to the buyer, and the agreed retention period. The supplier should also explain how a withdrawal request reaches the dataset and what gets deleted. Absent consent cannot be repaired after collection, so this check belongs in the pilot.

What Should Cause a Supplier to Fail the First Pilot?

A supplier should fail the pilot when it cannot satisfy mandatory acceptance gates or provide evidence supporting its claims. Choose a sample spanning routine tasks and difficult conditions, including occlusion, varied lighting and representative operators. Agree on the sample composition, evaluation method and permitted rework before recording begins. This prevents acceptance criteria from changing after delivery. Treat the following findings as reasons to withhold acceptance until resolved.

  1. Missing task coverage: Accepted recordings omit required task–object–environment combinations or contain undocumented substitutions.
  2. Unusable observations: Critical hand–object interactions are repeatedly outside the view or fail the agreed visibility requirements.
  3. Unverifiable tracking: Required pose fields, calibration, timing measurements or accuracy evidence are missing or fail agreed tolerances.
  4. Unresolved permissions: The supplier cannot trace accepted episodes to the approvals required for the intended use.
  5. Unreliable review: Quality reports cannot be reproduced, rejected clips reappear without resolution, or annotation disagreements lack adjudication.
  6. Failed delivery: Files cannot be loaded, required metadata is missing, or recordings and annotations cannot be matched reliably.

Run the delivered sample through your actual data loader. Check identifiers, timestamps, units, schema versions, checksums and links between media, annotations and metadata. Inspect duplicate handling and the agreed train-evaluation split, especially where the same operator, environment or session appears repeatedly. Preserve raw and processed assets according to the agreed delivery scope so transformations remain traceable.

Separate repairable defects from failures requiring recollection or a supplier change. A schema mismatch may be fixable; a missing camera view generally requires another recording. Put correction ownership, reshoot charges, review deadlines and termination conditions in the pilot agreement. If a mandatory gate remains unresolved after the agreed correction cycle, do not expand the collection program.

Passing collection acceptance does not establish downstream robot performance. If policy improvement is a purchasing requirement, define a separate learning experiment with a baseline and held-out evaluation tasks. Keep that result distinct from the supplier’s capture and annotation scorecard. This distinction helps locate whether a later problem comes from data quality, model design or transfer to the target robot.

Before production, ask for an accepted-volume forecast tied to trained operators, available hardware, site access and reviewer capacity. Require version records for devices, calibration, software and annotation guidelines so changes at scale remain traceable. Agree on when a change requires another sample review. A successful pilot provides a baseline for this operating plan.

How Digital Divide Data Can Help

Digital Divide Data (DDD) provides custom egocentric data collection for robotics and Physical AI programs, covering protocol design, demonstrator training, capture, review, and annotation in one engagement. Protocol work happens before recording begins, including diversity planning, sync events, per-session calibration steps, and metadata standards for coordinate conventions. Collection can run on-site or through integrated capture setups, with real-time progress tracking. Consent and privacy workflow design is part of the same scope.

Quality review follows the checks described in this article. DDD’s teams combine automated checks, reviewer validation, and temporal consistency audits across synchronized video, IMU, and pose streams. For humanoid and manipulation programs, DDD’s robotics training data and annotation services extend the work to joint pose labeling, task phase segmentation, and cross-sensor QA. Stable, non-rotating teams keep guideline interpretation consistent as volume grows.

DDD recommends starting with a scoped pilot against the buyer’s own brief, with acceptance gates agreed before recording. The pilot reports yield, rejection reasons, and coverage by task and environment, so the scale-up decision rests on measured results. Teams still drafting the brief can use the pilot design phase to settle hand-tracking source, delivery format, and permission scope.

Scope a custom egocentric collection pilot against your own brief. Talk to an Expert!

Conclusion

Choosing a custom egocentric data collection partner comes down to evidence that can be checked. Task coverage, hand tracking, quality review, and participant permissions each have a measurable form, and a good brief asks for that form by name. Suppliers then compete on accepted episodes, verified pose quality, and documented consent, which are the properties a training pipeline depends on.

Organizations that buy on headline hours tend to discover the gaps during training, when re-collection is the only fix. Organizations that fix definitions in the brief and enforce them in a pilot tend to scale collection with predictable yield. 

References

Grauman, K., Westbury, A., Byrne, E., Chavis, Z., Furnari, A., Girdhar, R., Hamburger, J., Jiang, H., Liu, M., Liu, X., Martin, M., Nagarajan, T., Radosavovic, I., Ramakrishnan, S. K., Ryan, F., Sharma, J., Wray, M., Xu, M., Xu, E. Z., Zhao, C., Bansal, S., Batra, D., Cartillier, V., Crane, S., Do, T., Doulaty, M., Erapalli, A., Feichtenhofer, C., Fragomeni, A., Fu, Q., Gebreselasie, A., Gonzalez, C., Hillis, J., Huang, X., Huang, Y., Jia, W., Khoo, W., Kolar, J., Kottur, S., Kumar, A., Landini, F., Li, C., Li, Y., Li, Z., Mangalam, K., Modhugu, R., Munro, J., Murrell, T., Nishiyasu, T., Price, W., Puentes, P. R., Ramazanova, M., Sari, L., Somasundaram, K., Southerland, A., Sugano, Y., Tao, R., Vo, M., Wang, Y., Wu, X., Yagi, T., Zhao, Z., Zhu, Y., Arbelaez, P., Crandall, D., Damen, D., Farinella, G. M., Fuegen, C., Ghanem, B., Ithapu, V. K., Jawahar, C. V., Joo, H., Kitani, K., Li, H., Newcombe, R., Oliva, A., Park, H. S., Rehg, J. M., Sato, Y., Shi, J., Shou, M. Z., Torralba, A., Torresani, L., Yan, M., & Malik, J. (2022). Ego4D: Around the world in 3,000 hours of egocentric video. https://arxiv.org/abs/2110.07058

Hoque, R., Huang, P., Yoon, D. J., Sivapurapu, M., & Zhang, J. (2025). EgoDex: Learning dexterous manipulation from large-scale egocentric video. https://arxiv.org/abs/2505.11709

Hu, Y., Lin, F., Sheng, P., Wen, C., You, J., & Gao, Y. (2024). Data scaling laws in imitation learning for robotic manipulation. https://arxiv.org/abs/2410.18647

Zheng, R., Niu, D., Xie, Y., Wang, J., Xu, M., Jiang, Y., Castañeda, F., Hu, F., Tan, Y. L., Fu, L., Darrell, T., Huang, F., Zhu, Y., Xu, D., & Fan, L. (2026). EgoScale: Scaling dexterous manipulation with diverse egocentric human data. arXiv preprint arXiv:2602.16710. https://arxiv.org/abs/2602.16710

Frequently Asked Questions

Who offers custom egocentric data collection for enterprise robotics?

Four types of suppliers offer it, including managed data service providers, contributor marketplaces, dataset licensors that also commission new collections, and annotation-first vendors. Digital Divide Data is a managed provider that covers protocol design, capture, review, and annotation in one engagement. A clear brief and a pilot show which model a supplier actually runs.

How do I compare egocentric data vendors when their proposed hours differ?

Convert every proposal to accepted hours and accepted episodes per task, then compare coverage across environments, objects, and demonstrators. Check what the price includes, such as de-identification and annotation, and work out the cost per accepted hour.

Can I use public egocentric datasets like Ego4D or EgoDex to train a commercial robot?

Check the license first, because public datasets carry their own terms, and EgoDex is distributed under a non-commercial license. Public datasets also cover general activity, so most enterprise programs still need custom demonstrations with their own parts, tools, and workstations.

What should make me fail a supplier after the first pilot?

Fail the pilot if the critical action is not visible, hand tracking misses the agreed level, consent records are missing, or the delivery does not load in your pipeline. Hidden rejections and an undisclosed change in pose source are disqualifying, because they reflect how the supplier operates.

How to Choose a Custom Egocentric Data Collection Partner for Enterprise Robotics Read Post »

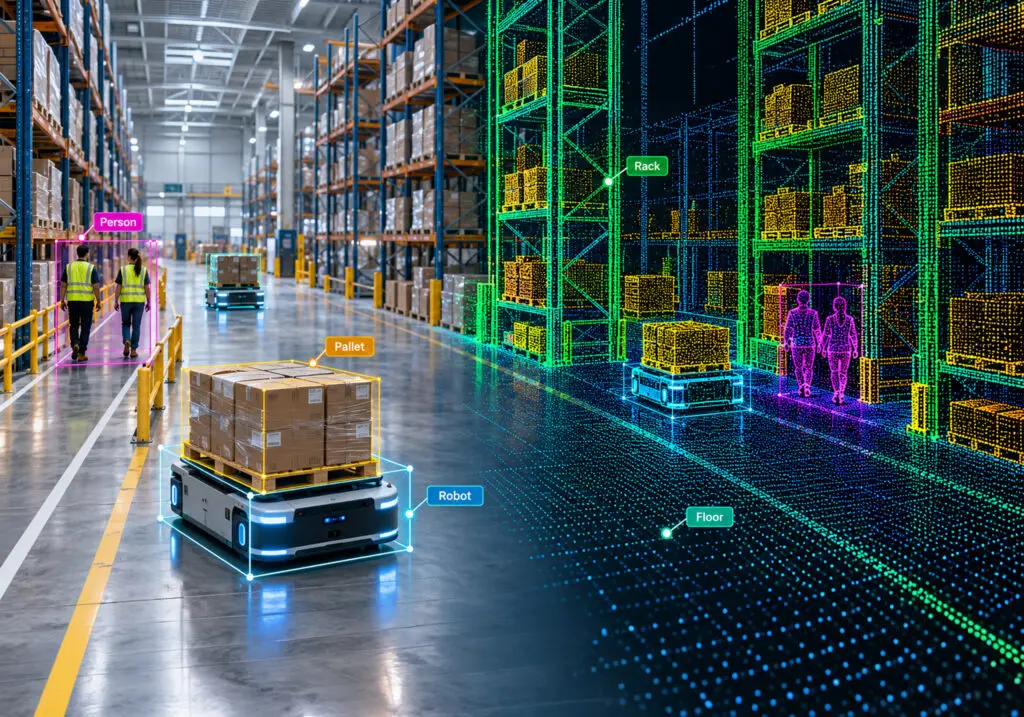
Autonomous warehouse robot with LiDAR and image annotation overlays showing AI training data used in Physical AI systems.

What Enterprises Must Know About GDPR, Data Ownership, and Emerging AI Regulations in Data Annotation Services

AI training data compliance means proving three things about every dataset, including a lawful basis for personal data, clear rights to the content and its labels, and documented governance. Enterprises that buy AI data annotation services keep these duties, because outsourcing the labeling work does not transfer legal responsibility. GDPR, Copyright Law, the EU AI Act, US state privacy laws, or emerging AI laws, now apply to the same dataset at the same time.

Most compliance failures in training data start long before a regulator or a court asks a question. A team scrapes a corpus, sends it for labeling, and trains a model, and nobody records where the data came from or who owns the labels. Fixing that after training is expensive. The controls that prevent this sit inside data collection and curation, and annotation workflows, so legal and ML teams need a shared view of the rules.

Key Takeaways

  • Hiring an outside company to label your data does not pass the legal responsibility for that data to them.
  • Under GDPR, you need a valid legal reason to use people’s personal data for training, and those people can still ask to see or remove it.
  • Who owns labeled data depends on the contract, so make sure ownership of every label is assigned to you in writing.
  • Data collected from public websites is the riskiest source, because being publicly visible does not make it free to use.
  • New rules in the EU and in US states such as California require companies to keep clear records of where training data came from and how it was labeled.
  • Recording sources, permissions, and ownership from day one costs far less than fixing gaps after a model is trained.

What Does AI Training Data Compliance Mean for AI Data Annotation Services?

AI training data compliance is the set of legal obligations attached to the data used to train, validate, and test a model. It covers raw source data, the labels added during annotation, and the documentation that describes both. The obligations grow with the sensitivity of the data. Multimodal data annotation involving faces, voices, or in-cabin video raises privacy questions that plain text classification rarely does. Programs built on trust and safety solutions, such as bias audits, often process sensitive attributes and need stricter controls.

Typically, 3 categories of law apply to an annotated dataset, and each answers a different question. Complying with one category does not settle the others. Teams should check all three before a dataset enters annotation.

  • Privacy law (GDPR and US state privacy laws): May this personal data be used for training, and can individuals still exercise their rights over it?
  • Intellectual property law: Who holds rights in the source content, the annotations, and the finished dataset?
  • AI-specific regulation (EU AI Act, California AB 2013): Can the organization document how the data was sourced, labeled, and checked?

A data controller decides why and how personal data is processed, while a data processor, usually the annotation vendor, acts on the controller’s instructions. Data provenance is the documented history of a dataset, covering its source, license, consent basis, and every transformation applied to it.

What Are the GDPR Requirements for AI Training Data?

GDPR applies whenever a training dataset contains information about an identifiable person in the EU, including faces, voices, names, and license plates. The controller needs a lawful basis for the training use and must limit the data to what the purpose requires. Special category data, such as health or biometric data, needs an additional legal ground under Article 9. The European Commission has proposed amendments that address AI training directly, and they were still in the legislative process in October 2026.

The most detailed guidance so far is the European Data Protection Board’s Opinion 28/2024 on AI models. The Board accepted that legitimate interest can support model training if the controller passes a three-step test. The controller must identify a lawful interest, show the processing is necessary, and show that individuals’ rights do not override it. The Opinion adds that a model trained on personal data cannot be assumed to be anonymous. It also warns that unlawful processing during development can affect whether the model may be deployed lawfully.

How do data subject rights apply inside a training dataset?

Individuals keep their rights of access, erasure, and objection after their data enters a training set. Honoring those rights at scale requires record-level lineage. A team must be able to find one person’s records, remove them, and identify which model versions were trained on them. Large-scale use of biometric or other sensitive data also calls for a data protection impact assessment before work begins.

What does GDPR require when annotation is outsourced?

Article 28 requires a written data processing agreement before a vendor handles personal data. The agreement must bind the vendor to the controller’s documented instructions, confidentiality, security measures, and deletion or return of data when the work ends. Sub-processors need the controller’s authorization. When annotators work outside the European Economic Area, the transfer needs a valid mechanism, usually standard contractual clauses supported by a transfer impact assessment.

Who Owns the Copyright of Annotated Training Data?

An annotated dataset has three layers, and each can have a different owner. The first is the source content, such as images, documents, or recordings. The second is the annotation layer of labels, bounding boxes, transcripts, and rationales. The third is the compiled dataset, which may be protected as a compilation in the US or under the EU database right.

For the annotation layer, the contract decides. Without a written assignment, default rules differ by country, and a vendor or its contractors may hold rights in the labels they created. Protection also depends on originality and human authorship. Simple labels may attract little protection, and machine-generated pre-labels are in a weaker position still.

Training on another party’s annotated data without a license therefore carries real infringement risk. The judgment involved in human-powered data annotation is what makes this layer valuable, so enterprises should own it outright and protect it with confidentiality terms.

For the source layer, the US Copyright Office’s report on generative AI training concluded that fair use must be assessed case by case. The Office pointed to how the works were acquired, how the model is used, and the effect on the market for the originals. Licensed or owned source data is therefore the lower-risk default for enterprise programs.

What Are the Legal Risks of Using Scraped Web Data for AI Training?

Scraped web data is the highest-risk source in most training pipelines because it arrives without consent records or license terms. Public availability does not remove legal protection. A photo on a public page can still be copyrighted, and a name in a public post is still personal data under GDPR. Four exposures follow from this.

  • Copyright infringement: Copying protected works without a license or a valid exception. In the EU, rights holders can opt out of text and data mining, and those opt-outs must be honored.
  • Privacy violations: Collecting personal data that people did not expect to be used for training, which weakens a legitimate interest argument.
  • Contract claims: Breaching website terms that prohibit automated collection.
  • Licensing errors: Relying on dataset licenses that are missing or wrong.

The last risk is more common than most teams assume. A large-scale audit of dataset licensing and attribution in Nature Machine Intelligence traced more than 1,800 text datasets. It found license omission rates above 70% and error rates above 50% on popular hosting sites. Teams should verify lineage back to the original source before any scraped or public dataset enters annotation.

What Emerging AI Regulations Apply to Training Data?

AI-specific regulation adds documentation duties on top of privacy and copyright law. The EU AI Act is the most detailed regime, and several US states have passed narrower measures. Both focus on what an organization can show about its data, which makes annotation records legally relevant.

What does the EU AI Act say about training data?

The EU AI Act regulates training data through two provisions. Article 10 requires high-risk AI systems to use training, validation, and testing datasets that are relevant, sufficiently representative, and as free of errors as possible. Providers must document data origin and preparation steps, and the Act names annotation, labeling, and cleaning explicitly. They must also examine datasets for bias.

The timeline changed in 2026. The Digital Omnibus on AI, Regulation (EU) 2026/1744, postponed the high-risk obligations to 2 December 2027 for stand-alone systems and 2 August 2028 for AI embedded in regulated products. It also extends the legal ground for processing sensitive data to detect and correct bias, under a strict necessity standard. A practical data-level checklist for auditing an AI model for bias shows how to structure that examination.

Article 53 covers general-purpose AI models and has applied since 2 August 2025. Providers must publish a summary of their training content and maintain a policy to comply with EU copyright law, including rights holders’ opt-outs. Enterprises that fine-tune or build on these models should request both documents during procurement.

How do US state privacy laws affect AI training data?

The United States has no comprehensive federal AI statute, so state law fills the gap. Privacy laws in California and a growing number of other states give consumers rights to access, delete, and limit use of their personal information. Those rights reach data held in training sets. Three state measures deserve specific attention.

  • California AB 2013: In force since 1 January 2026. Developers of generative AI systems offered to Californians must publish training data documentation, including sources, IP status, and personal information.
  • Illinois Biometric Information Privacy Act (BIPA): Requires informed written consent before collecting biometric identifiers such as face geometry and voiceprints.
  • Colorado SB 26-189: Replaces the state’s 2024 AI Act with a narrower automated decision-making law, effective 1 January 2027.

How Do Enterprises Ensure That AI Training Data Is Compliant?

Compliance is easier to build during collection and annotation than to reconstruct after training. The steps below apply to most enterprise programs, whatever the modality. Each one produces evidence that a regulator, auditor, or customer may later request.

  • Record provenance at acquisition: Capture the source, license or consent basis, and collection date before annotation starts.
  • Classify personal data early: Identify personal and special category data, then minimize, pseudonymize, or blur what the task does not need.
  • Document the legal assessment: Complete a legitimate interest assessment and, where risk is high, a data protection impact assessment.
  • Keep record-level lineage: Version every dataset and track which models used it, so erasure requests can be carried out.
  • Honor opt-outs: Check rights reservations and site terms before collecting web content.
  • Preserve annotation evidence: Retain guidelines, inter-annotator agreement scores, and review records as proof of data governance.

How should enterprises structure compliant contracts for AI data annotation services?

The annotation contract is where privacy and IP obligations become enforceable. A statement of work that covers only volume, price, and accuracy targets leaves the main legal questions open. Contracts that hold up under review usually contain the following terms.

  • IP assignment: All annotations and derived datasets are assigned to the client on creation, with matching terms between the vendor and its annotators.
  • Use restrictions: The vendor may not reuse client data or labels to train its own models or serve other clients.
  • Data processing agreement: Terms covering instructions, confidentiality, sub-processor approval, audit rights, and deletion.
  • Transfer mechanism: Standard contractual clauses and a transfer impact assessment where data leaves the EEA.
  • Provenance warranties: Where the vendor sources data, warranties on consent and licensing, backed by an indemnity.
  • Security and assistance: Access controls, secure work environments, and support for data subject requests and EU AI Act documentation.

These terms should be agreed before the first batch of data is shared. Adding them after a dispute or an audit request leaves the enterprise with less leverage. Legal counsel should review the final language, since this guide is general information and does not replace legal advice.

How Digital Divide Data Can Help

Digital Divide Data builds these controls into day-to-day delivery. DDD’s AI data annotation services run on secure infrastructure with human-in-the-loop review across image, video, LiDAR, text, and audio data. Annotation guidelines, inter-annotator agreement results, and review records are kept as project documentation that clients can use in their own governance files.

For programs that need new data, DDD’s data collection and curation services capture the consent, license, or ownership basis at the point of acquisition. Provenance tracking and transformation documentation stay with the dataset through cleaning, annotation, and validation. For Physical AI, ADAS, and in-cabin programs, anonymization steps such as face and license plate blurring can be applied before annotation begins.

Build AI training data programs that hold up under legal and regulatory review. Talk to an Expert.

Conclusion

Training data compliance is now a condition of deployment for enterprise AI. GDPR decides whether personal data may be used, copyright and contract decide who owns each layer, and AI-specific rules decide what must be documented. Organizations that capture provenance, consent, and ownership during collection and annotation can answer all three from the same records. Organizations that defer the work face retraining costs, blocked launches, and weaker positions in disputes.

References

European Data Protection Board. (2024). Opinion 28/2024 on certain data protection aspects related to the processing of personal data in the context of AI models. Adopted 17 December 2024. https://www.edpb.europa.eu/system/files/2024-12/edpb_opinion_202428_ai-models_en.pdf

European Parliament and Council of the European Union. (2024). Regulation (EU) 2024/1689 laying down harmonised rules on artificial intelligence (Artificial Intelligence Act), as amended by Regulation (EU) 2026/1744 (Digital Omnibus on AI). Official Journal of the European Union. https://eur-lex.europa.eu/eli/reg/2024/1689/oj/eng https://eur-lex.europa.eu/eli/reg/2026/1744/oj/eng

U.S. Copyright Office. (2025). Copyright and Artificial Intelligence, Part 3: Generative AI Training (Pre-publication version). A Report of the Register of Copyrights. https://www.copyright.gov/ai/Copyright-and-Artificial-Intelligence-Part-3-Generative-AI-Training-Report-Pre-Publication-Version.pdf

Longpre, S., Mahari, R., Chen, A., Obeng-Marnu, N., Sileo, D., Brannon, W., Muennighoff, N., Khazam, N., Kabbara, J., Perisetla, K., Wu, X., Shippole, E., Bollacker, K., Wu, T., Villa, L., Pentland, S., & Hooker, S. (2024). A large-scale audit of dataset licensing and attribution in AI. Nature Machine Intelligence, 6, 975–987. https://www.nature.com/articles/s42256-024-00878-8

Frequently Asked Questions

What are the GDPR requirements for AI training data?

You need a lawful basis for using personal data, such as legitimate interest backed by a three-step test, and you must limit the data to what the purpose needs. You also have to honor access, erasure, and objection requests, and sign a data processing agreement with any vendor that handles the data.

Who owns the copyright of annotated training data?

It depends on the layer and the contract. The source content, the annotations, and the compiled dataset can each have a different owner. The annotation contract should assign all labels and derived datasets to the client in writing.

What does the EU AI Act say about training data?

Article 10 requires high-risk systems to use datasets that are relevant, representative, and as free of errors as possible, with documented sourcing, annotation, and bias checks. Article 53 requires providers of general-purpose AI models to publish a training content summary and keep a copyright compliance policy.

What are the legal risks of using scraped web data for AI training?

Scraped data carries copyright, privacy, contract, and licensing risks because it arrives without consent records or license terms. Being publicly available does not remove those protections, so teams should verify the source and license of each dataset before annotation.

What Enterprises Must Know About GDPR, Data Ownership, and Emerging AI Regulations in Data Annotation Services Read Post »

AI data curation specialist reviewing and organizing enterprise AI training dataset

AI Data Curation Guide for Enterprise AI Teams

AI data curation services turn raw, fragmented data into controlled datasets that are fit for model training, fine-tuning, evaluation, and continuous improvement. Strong curation covers source qualification, deduplication, normalization, coverage design, enrichment, provenance, quality validation, and version control. Enterprises should evaluate a provider on measurable dataset outcomes, security controls, workflow transparency, and the ability to connect curation decisions to model performance. 

Curation decides which examples a model ever sees, so it shapes accuracy, bias, and reliability long before training starts. Teams that treat sourcing as a warm-up to the “real” modeling work tend to inherit those early decisions as production failures. Mature programs run data collection and curation as an engineering discipline with its own tooling, quality standards, and audit trail. This guide explains what curation includes, how it differs from annotation, how providers price the work, and how to evaluate a vendor before you sign.

Key Takeaways

  • The quality of the data you feed a model matters more for real-world results than how big or advanced the model is.
  • Data curation means choosing, cleaning, balancing, and keeping a record of the right data before any training begins.
  • Curation decides what data goes in, while annotation just adds labels to data that has already been chosen, so getting curation wrong makes even perfect labeling useless.
  • Prices vary by how the work is charged and by factors like data type, expert knowledge needed, and how carefully it is checked, so a low headline rate can hide the true cost.
  • Pick a provider based on how they measure quality, track where data comes from, and respond when things break, rather than on price or a polished sales pitch alone.
  • The safest way to test a provider is a small paid trial on your own messy data before committing to a full program.

What are AI data curation services and Where Do They Fit in the AI Model Lifecycle??

AI data curation services are outsourced or co-managed programs that take raw, messy source data and turn it into a training-ready dataset with known quality, coverage, and provenance. The work spans sourcing, filtering, deduplication, class balancing, enrichment, quality scoring, and documentation of where each example came from. Curation sits next to data annotation in the pipeline, though the two answer different questions, which the sections below make explicit. A useful shorthand is that curation decides what belongs in the dataset, while annotation describes what is already in it.

The field has shifted toward a data-centric view of model quality over the past few years. Practitioners consistently find that the composition of the training set determines more of the outcome than incremental changes to architecture. A widely cited Google Research study on data cascades found that data problems are pervasive, appearing in 92% of the AI teams studied, and that data remains the most undervalued part of the workflow. That undervaluation is exactly the gap curation services are built to close.

The priorities vary by model. LLM programs may emphasize semantic deduplication, source quality, language balance, and provenance. Vision, robotics, and ADAS programs add image quality, scenario coverage, temporal continuity, sensor synchronization, and physical plausibility.

What does AI data curation include?

Curation is a sequence of decisions, each of which changes what the model can and cannot learn. At an enterprise scale, a complete curation program typically covers the following stages:

  1. Sourcing and selection: Deciding which data to bring in, from internal archives, licensed corpora, sensor logs, or targeted collection, and rejecting what does not fit the task.
  2. Cleaning and deduplication: Removing corrupted records, near-duplicates, and noise that inflates dataset size without adding signal.
  3. Coverage and balancing: Auditing the distribution so the dataset represents the conditions the system will meet, then filling gaps deliberately.
  4. Enrichment and structuring: Adding metadata, taxonomy tags, and context that make examples usable for retrieval, training, and evaluation.
  5. Edge-case mining: Surfacing the rare, high-cost scenarios a model handles badly, which naturally collected data underrepresents by definition.
  6. Quality scoring and provenance: Recording confidence, review status, and the full lineage of every example so the set is auditable later.

Edge-case work deserves emphasis because it drives most safety-critical failures. Dedicated edge case curation targets the corner cases that a model will meet in deployment yet rarely sees in training. Curating those scenarios on purpose raises reliability where the cost of error is highest.

Two further decisions belong in a modern curation program. The first is the balance between real and synthetic data, since generated examples can fill coverage gaps that are expensive or unsafe to collect, though they need validation before they enter the set. The second is data selection, where active-learning methods prioritize the examples most likely to improve the model and drop redundant ones that add cost without signal. Both decisions are curation work, and both change the economics of a program, because a smaller, well-chosen dataset often trains a stronger model than a larger, noisier one. A provider that treats every example as equally worth keeping is not curating; it is only collecting.

How does data curation improve AI model performance?

Curation improves performance by changing the input the model learns from, which compounds through every downstream stage. Cleaner, better-balanced data reduces the number of confident-but-wrong outputs and improves how the model generalizes to unseen inputs. The argument on criticality of data curation for generative AI is that every generated output reflects the data the model was trained on, so flaws in the set propagate into behavior. This holds across predictive, generative, and agentic systems.

The DataComp benchmark held the training code fixed and let participants compete only on dataset curation, and it showed that better-curated data produced meaningfully stronger models with less compute. The result reframes curation as a direct lever on accuracy rather than a housekeeping task. Teams that invest in it tend to close more of the gap between what a model can achieve and what it actually delivers.

Coverage is the other half of the performance story. A dataset can be clean and still fail because it never exercises the capability areas the task requires. The analysis of the impact of training data on model bias explains that coverage is something to audit rather than assume, and that underrepresented inputs become the model’s blind spots. Curating for coverage raises reliability precisely where naturally collected data is thinnest.

What is the difference between data curation and data annotation?

The two are often bundled together, though they solve different problems and carry different risks. Data curation is the work of deciding what data belongs in the set and preparing it: sourcing, filtering, deduplicating, balancing, enriching, and documenting. Data annotation is the work of adding labels to the data that curation has already selected: bounding boxes, transcriptions, entity tags, preference rankings, and similar. Collection sits upstream of both and refers to sourcing or generating the raw material in the first place.

The practical distinction matters when you scope a project. You can annotate a poorly curated dataset perfectly and still get a weak model, because the labels are accurate on the wrong distribution of examples. Annotation quality is measurable and consequential in its own right. A study of pervasive label errors across ten widely used benchmark datasets found an average of at least 3.3% label errors, rising to 6% in the ImageNet validation set, which was enough to change how models ranked against each other. Curation and annotation each need their own quality controls, and a serious provider treats them as separate disciplines with separate metrics.

How are AI data curation services priced?

Pricing depends on what the work actually is, so buyers should map the model to their volume, complexity, and cadence before comparing quotes. Providers generally use one of four structures, and many combine them across a program:

  • Per-unit pricing: A rate per record, image, frame, hour of audio, or document. It works for well-defined, high-volume tasks with stable specifications.
  • Per-hour pricing: A rate for reviewer or specialist time. It fits ambiguous, judgment-heavy work where output volume is hard to predict.
  • Managed program or retainer: A monthly fee for a dedicated, trained team plus quality and program management. It suits ongoing pipelines that evolve with the model.
  • Platform or subscription: A license for tooling, sometimes with services layered on top, priced by seats or throughput.

Several factors move the price within any of these models. Modality raises cost as you move from text to image to video to fused sensor data, since each adds handling and review complexity. Domain expertise adds cost when the work needs clinical, legal, or engineering judgment rather than general labeling. Quality tier matters too, because multi-stage review and higher inter-annotator agreement targets require more human passes. Turnaround, data security requirements, and volatility of the specification all push the number as well. A per-unit quote that ignores these drivers tends to understate the true cost of a production program.

What Does an Enterprise-Grade Curation Workflow Look Like in Production?

Production curation is a repeatable pipeline with explicit acceptance gates. It starts with model objectives and ends with a versioned dataset plus evidence that the release meets agreed quality, coverage, and governance thresholds. 

How should the target dataset be defined?

The workflow starts with a sampling frame or dataset specification. It defines modalities, sources, target populations, class distributions, environments, languages, time periods, rare scenarios, permitted content, prohibited content, and acceptance thresholds. This document should be specific enough to measure.

Training, validation, and evaluation sets need separate rules. Training may favor broad coverage and difficult examples, while evaluation needs stable, representative, leakage-controlled samples.

What should happen during a pilot?

A pilot should validate the workflow, not merely produce a small batch. The provider and client should test intake rules, filtering thresholds, ambiguous cases, metadata schema, reviewer calibration, turnaround time, output format, and reporting. A useful pilot creates a baseline for both quality and throughput.

Where feasible, the pilot should compare curated data with model behavior. Even a small offline test can reveal whether proposed quality scores or sampling rules relate to downstream metrics.

Where should automation and human review be used?

Automated systems are effective for format validation, exact and semantic duplicate detection, basic PII detection, image-quality checks, language identification, clustering, anomaly detection, and rule-based filtering. Human reviewers remain important for semantic relevance, ambiguous edge cases, domain-specific validity, cultural context, safety judgments, and adjudication.

Automation depth should follow task risk and ambiguity. Safety-critical, regulatory, and judgment-heavy decisions need stronger human review and documented escalation paths.

What quality gates should a curated release pass?

Release criteria should combine record-level and dataset-level metrics. Record-level checks may include corruption rate, metadata completeness, label defect rate, and schema validity. Dataset-level checks should include duplicate rate, coverage against target, class balance, source distribution, edge-case representation, provenance completeness, and leakage controls.

A release should fail when a critical slice misses its threshold, even if the aggregate metric looks strong. This prevents high-volume common cases from hiding weak performance in rare or high-risk segments.

How does curation continue after deployment?

Production data changes the curation plan. Teams learn which inputs cause errors, which segments drift, which rare events matter, and which source assumptions were wrong. Those signals should feed the next collection and curation cycle.

A mature program maintains a data feedback loop. Model errors guide new sampling, collection, review, and the next versioned release, making curation part of ongoing model maintenance.

How should enterprises evaluate an AI data curation provider?

The questions that predict success are about the human quality layer, governance, and how a provider behaves when something breaks. A connector count or a demo on a curated sample tells you little about performance on messy production data. Evaluate providers against criteria that map to the risks in your program:

  1. Quality for methodology: Ask how they measure quality, whether they report inter-annotator agreement, and how multi-stage review and gold sets work in practice.
  2. Domain capability: Confirm they can staff and train specialists for your domain, rather than routing sensitive work to general crowdsourcing.
  3. Coverage and edge-case process: Ask how they audit distribution and how they find the rare cases your model will fail on.
  4. Provenance and lineage: Confirm they document data sources, transformations, and guideline versions, so a dataset stays auditable.
  5. Security and compliance: Look for real documentation behind certifications such as SOC 2 Type 2, ISO 27001, GDPR, and HIPAA, along with deployment options that fit your data-residency rules.
  6. Failure response: Ask what happens when quality drops, how re-work is priced, and how quickly the team can adjust guidelines.

Programs that cannot document where their data came from face rising regulatory exposure under the EU AI Act and evolving privacy frameworks. A provider that maintains full lineage delivers a compliance asset alongside a training asset, and that distinction grows more valuable with each regulatory cycle.

Structured due diligence beats a capabilities deck. Ask for references from clients in a similar domain, and ask what went wrong on those programs and how the provider recovered, because the recovery story reveals more than the success story. A short, paid pilot on your own messy data is the single most reliable test, since it shows how the team handles ambiguity, edge cases, and specification changes under real conditions. Scoring providers against consistent criteria across a pilot removes most of the guesswork that a sales conversation introduces.

What are the red flags in a data curation vendor proposal?

Several proposal patterns deserve additional diligence because they hide the parts of curation that usually fail under production pressure.

  • One accuracy number for the entire program: Dataset quality has multiple dimensions, and an aggregate percentage can hide weak coverage or severe errors in small slices.
  • No provenance deliverable: A folder of cleaned files without source lineage, rights metadata, and transformation history creates future governance risk.
  • Deduplication described only as exact-match removal: Near-duplicate text, repeated video, similar images, and correlated sessions can remain even when hashes differ.
  • No target distribution or coverage specification: Without a defined target, “balanced” becomes subjective and difficult to accept contractually.
  • Automation described without human escalation: Automated quality scoring needs a path for ambiguous, high-risk, or domain-specific cases.
  • Human review described without calibration metrics: Review teams need guidelines, gold examples, disagreement analysis, and adjudication rules.
  • Security claims limited to corporate certifications: Buyers should verify controls at the delivery-center, workstation, data-transfer, and subcontractor levels.
  • Pricing that excludes rework caused by provider errors: The contract should define who pays when quality misses agreed thresholds.
  • No versioning or reproducibility plan: A training dataset should be recreatable from documented sources, rules, and transformations.
  • A pilot built from hand-picked easy samples: Representative difficult data is a better predictor of production performance.

What does an enterprise-grade curation workflow look like in production?

A production curation workflow is continuous, versioned, and instrumented, rather than a one-time cleanup before training. It starts with a shared definition of task, quality thresholds, and coverage targets, then moves data through structured stages with checks at each one. Human-in-the-loop review sits at the center, with automation handling scale and expert reviewers resolving the cases automation cannot. The output is a versioned dataset with recorded lineage, so any later problem can be traced to a specific source and guideline version.

Two properties separate a durable workflow from a fragile one. The first is drift monitoring, since categories get applied inconsistently and new data types appear as a program grows past its original design. The second is traceability, because a fine-tuned model that starts producing off-brand or unsafe outputs needs to be traced to the exact data and guidelines that shaped it. Without that trail, every incident becomes an open-ended investigation instead of a targeted fix. Enterprises that build these properties in early spend far less time firefighting later.

Should you build data curation in-house or buy it?

The decision turns on volume, domain complexity, regulatory exposure, and how much of your model’s accuracy rides on the human quality layer. Building in-house gives you tight control and keeps sensitive data close, though it demands recruiting, training, tooling, and quality management that many teams underestimate. Buying gives you a trained workforce and mature process quickly, at the cost of bringing a partner inside your data boundary. Neither is right in the abstract, and the answer depends on your specifics.

A hybrid model is often the pragmatic answer for larger programs. The enterprise keeps ownership of strategy, sensitive data, and final acceptance, while the provider runs sourcing, curation, annotation, and delivery at scale. This keeps control where it belongs and puts volume where it is handled most efficiently. Vendor selection under this model is an architecture decision with long consequences, so the evaluation criteria above matter more than headline price.

How Digital Divide Data Can Help

Digital Divide Data operates the human quality layer that determines whether a curation program holds up in production. Our data collection and curation services cover the full lifecycle, from ethical sourcing and deduplication through coverage auditing, enrichment, and documented provenance for every source. We run structured human-in-the-loop workflows with multi-stage QA and domain specialists, which keep accuracy high on the ambiguous, safety-critical cases that automation alone misses.

The work is grounded in specific capabilities rather than a generic promise. Our AI data preparation services clean, structure, validate, and enrich raw data into consistent, bias-aware, model-ready sets that improve downstream performance. We embed governance, auditability, and compliance into every workflow, operating under ISO 27001, SOC 2 Type 2, GDPR, and HIPAA-aligned protocols, with flexible delivery models for teams that have strict data-residency requirements. For programs that live or die on rare scenarios, our edge-case pipelines surface and resolve the failure modes a model meets in the real world.

Build a curation program that closes the gap between what your model can do and what it actually delivers. Talk to an Expert.

Conclusion

Curation is the point where most of a model’s accuracy, bias, and reliability are actually decided, well before training begins. The evidence is consistent: better data beats bigger models in most production settings, and coverage gaps become blind spots that surface as failures. Organizations that treat curation as an engineering discipline, with measured quality and documented provenance, ship systems that behave predictably. Those that treat it as a warm-up inherit their early shortcuts as expensive, hard-to-trace incidents.

The buyers who get this right choose partners on quality methodology, provenance, and failure response, rather than on price alone. 

References

Gadre, S. Y., Ilharco, G., Fang, A., Hayase, J., Smyrnis, G., Nguyen, T., Marten, R., Wortsman, M., Ghosh, D., Zhang, J., Orgad, E., Entezari, R., Daras, G., Pratt, S., Ramanujan, V., Bitton, Y., Marathe, K., Mussmann, S., Vencu, R., Cherti, M., Krishna, R., Koh, P. W., Saukh, O., Ratner, A., Song, S., Hajishirzi, H., Farhadi, A., Beaumont, R., Oh, S., Dimakis, A., Jitsev, J., Carmon, Y., Shankar, V., & Schmidt, L. (2023). DataComp: In search of the next generation of multimodal datasets. Advances in Neural Information Processing Systems (NeurIPS). https://arxiv.org/abs/2304.14108

Northcutt, C. G., Athalye, A., & Mueller, J. (2021). Pervasive label errors in test sets destabilize machine learning benchmarks. NeurIPS Datasets and Benchmarks Track. https://arxiv.org/abs/2103.14749

Sambasivan, N., Kapania, S., Highfill, H., Akrong, D., Paritosh, P., & Aroyo, L. (2021). “Everyone wants to do the model work, not the data work”: Data cascades in high-stakes AI. Proceedings of the 2021 CHI Conference on Human Factors in Computing Systems. https://dl.acm.org/doi/10.1145/3411764.3445518

Frequently Asked Questions

What are AI data curation services?

They are managed programs that turn raw, messy source data into a training-ready dataset with known quality, coverage, and provenance. The work covers sourcing, cleaning, deduplication, balancing, enrichment, and documentation of where each example came from.

What is the difference between data curation and data annotation?

Curation decides what data belongs in the set and prepares it, while annotation adds labels to the data that curation has already selected. You can annotate a poorly curated dataset perfectly and still get a weak model, because the labels sit on the wrong distribution of examples.

How is AI data curation priced?

Providers usually charge per unit, per hour, as a managed retainer, or through a platform subscription, and many combine these. Cost rises with modality, domain expertise, the quality tier you require, turnaround, and data-security requirements.

Does better data curation actually improve model accuracy?

Yes, and the effect is measurable. The DataComp benchmark held training code fixed and showed that better-curated data produced stronger models with less compute, which makes curation a direct lever on accuracy rather than a housekeeping step.

AI Data Curation Guide for Enterprise AI Teams Read Post »

Person evaluating egocentric video and hand pose alignment on a monitor

How to Evaluate Egocentric Video and Pose Data Usability When Timing and Coordinates Don’t Match

Egocentric video and pose data with inconsistent timing and coordinate systems is often recoverable, and a structured audit tells you how much of it is. The audit documents every clock and coordinate frame, measures time offset and drift per session, and checks spatial alignment through reprojection error. Each session then lands in one of four outcomes: use as-is, repair, route to weaker supervision, or discard. 

Most teams reach this question with a pilot batch already in hand. The videos play, the pose files parse, and the schema validates. The trouble surfaces later, when projected hand keypoints trail the real hand during fast motion or a grasp label fires before the fingers close.

These errors are costly because they are silent. A 30-millisecond offset or a flipped axis passes every format check, yet it teaches a model the wrong link between what the camera sees and what the body does. Whether a team runs its own egocentric data collection program or sources egocentric datasets from a reputed vendor, the usability question is best settled before scaling collection or labeling.

Key Takeaways

  • Mismatched timing and positions rarely cause visible errors, so a structured check is the most reliable way to learn whether the data can still be used.
  • Check timing before any labeling starts by confirming that the video and body-movement data line up at the start, middle, and end of every recording session.
  • Check positions by writing down how each data source defines direction, scale, and starting point, then overlay the body data on the video to confirm it matches.
  • Some body positions are guessed by software because the camera couldn’t see them clearly, so flag those and check that all movements look physically realistic.
  • Sort each recording into one of four groups: use as is, fix and use, use for less demanding training, or discard.
  • Test a small, varied sample before scaling up, and use what you find to improve how future data is collected.

What Is Egocentric Video and Pose Data, and Why Does Alignment Matter?

Egocentric video is the footage recorded from the viewpoint of the person performing a task, usually through smart glasses, a headset, or a head-mounted camera. Pose data describes where the body is in space over time. In robotics programs, it typically includes a six-degree-of-freedom (6-DoF) head or camera trajectory, 3D hand keypoints, and sometimes full-body joints from an IMU suit or motion capture. Programs that apply video annotation services to this footage are working with streams recorded by different sensors that were never guaranteed to agree. As egocentric datasets become the new standard for training robotics models, that agreement becomes a core data quality question.

Two separate properties decide whether the streams agree. Temporal alignment, also called synchronization, means every video frame and every pose sample refer to the same physical instant. Spatial alignment means every pose is expressed in a documented coordinate frame with a known transform to the camera. A dataset can pass one test and fail the other, so each one needs its own evaluation.

A few terms come up repeatedly in any usability audit. Using them consistently across capture, annotation, and training teams prevents avoidable errors.

Time offset

The constant difference between two clocks at a given moment, usually measured in milliseconds.

Clock drift

The rate at which that offset changes across a session.

Coordinate frame

The origin, axis directions, and handedness that give a position or rotation its meaning.

Extrinsic calibration

The rigid transform between two sensors, such as the headset tracking frame and the RGB camera.

Intrinsic calibration

The camera’s internal model, including focal length, principal point, and lens distortion.

Why Do Timing and Coordinate Systems Drift Apart in Egocentric Captures?

Inconsistency is the default state of multi-device egocentric capture. A typical rig combines a headset, wrist or body trackers, and sometimes external motion capture, each with its own clock and reference frame. Sensor synchronization for egocentric robotics data is harder than in vehicle-mounted rigs, because the sensors sit on a moving human head. There is no fixed mounting to calibrate against, and head motion is fast and unpredictable.

Where does timing break down?

Timing errors tend to come from a small set of repeatable sources. The team behind the EMHI multimodal egocentric motion dataset, for example, had to reconcile a host PC clock and a separate headset clock offline. Common sources include:

  • Independent device clocks that start at different epochs and drift apart over long sessions.
  • Timestamps assigned on arrival at the host PC, which can lag the true sensor capture time.
  • Camera exposure delay and rolling shutter, which shift the actual capture instant by a few milliseconds.
  • Variable frame rates and dropped frames, which break the assumption that frame N sits at N divided by the frame rate.
  • Tracker disconnections that leave gaps in the pose stream while video keeps recording.

Where do coordinate systems break down?

Spatial inconsistencies tend to be convention mismatches. Human motion formats, game engines, and robotics simulators disagree on which axis points up, and some use left-handed frames. Others come from tracking itself, such as SLAM drift that builds up over long, fast, or poorly lit sequences. Typical mismatches include:

  • Up-axis differences, such as Y-up body model outputs loaded into a Z-up simulator.
  • Quaternion ordering, where one tool writes w-x-y-z and another expects x-y-z-w.
  • The unit mismatches between millimeters and meters, which scale every trajectory by a factor of 1,000.
  • Camera conventions, where OpenCV and OpenGL point the y and z axes in opposite directions.
  • World origin resets when a headset re-localizes, which shift the entire trajectory mid-session.

How Do You Measure Temporal Alignment Between Video and Pose Streams?

Temporal evaluation starts with the timestamps themselves. Check that every stream is monotonic, with no duplicate or out-of-order samples. Plot the interval between consecutive samples to expose dropped frames and variable frame rates. Record which clock stamped each stream, because that determines which corrections are possible.

The next step is to estimate the offset between video and pose directly from the data. Motion correlation, which compares angular velocity from two independent sources, is more reliable than manual alignment. EMHI synchronized its headset and motion capture streams this way, correlating headset IMU angular velocity against the tracked rigid body on the headset. For video without an IMU, visual odometry or optical flow can supply the second signal. Cross-correlating the two signals gives the lag at which they match best.

A single offset estimate is not sufficient on its own. Estimate the offset in windows at the start, middle, and end of each session. A stable offset can be corrected with one shift, while a steadily growing one indicates clock drift that needs a linear correction. A sudden jump usually marks a tracker reconnection or re-localization, and the session should be split at that point.

Tolerance should come from the downstream task, because timing error turns into spatial error during motion. A hand moving at one meter per second with a 20-millisecond offset is misplaced by about two centimeters. That may be acceptable for activity recognition and unacceptable for grasp retargeting. The EMHI authors noted that at 30 Hz, residual synchronization error can reach 16.5 milliseconds, so they interpolated annotations onto the headset timestamps.

How Do You Validate Coordinate Frames and Spatial Calibration?

Spatial validation begins with a written pose contract for every data source. The contract states the up-axis, handedness, units, rotation representation, quaternion order, world origin, and the frame each pose is expressed in. If a supplier or internal team cannot produce this document, that gap is itself a finding.

Simple physical sanity checks catch most convention errors early. The following checks work on almost any egocentric pose dataset:

  • Gravity check: The accelerometer’s mean direction at rest should point along the declared down-axis.
  • Scale check: Bone lengths, such as wrist-to-knuckle distances, should match human proportions and stay constant across a session.
  • Rotation check: Every rotation matrix should have a determinant of +1, and every quaternion should have unit norm.
  • Floor check: Foot or floor height should sit near the declared ground plane.

Reprojection error is the most direct test of spatial calibration. Project 3D keypoints into the image using the camera intrinsics and extrinsics, then measure the pixel distance to where the joint actually appears. The EgoXtreme egocentric pose benchmark validated its ground truth this way, sampling 200 frames per scenario where keypoints were clearly visible. It reported mean reprojection errors under one percent of the 1408-pixel image width and a trajectory alignment error of 4.3 mm and 1.5 degrees.

Two details often decide whether reprojection results can be trusted. Egocentric cameras frequently use fisheye lenses, so projecting with a pinhole model inflates error near the image edges. Exposure timing also matters, and the EgoXtreme team corrected a few milliseconds of offset caused by camera exposure delay before final interpolation. Checking reprojection during fast motion therefore tests timing and calibration together.

Which Pose Quality Checks Matter Beyond Synchronization?

A perfectly synchronized and calibrated stream can still contain unusable poses. Hand tracking degrades under occlusion, motion blur, and low light, and many pipelines fill the gaps with learned pose priors. The key question for each joint is whether it was measured, inferred, or generated. Datasets that do not record this distinction force every downstream user to guess.

Useful plausibility checks include:

  • Temporal smoothness: Velocity and acceleration spikes beyond human limits signal tracking jumps.
  • Bone-length stability: Joint distances that stretch from frame to frame indicate fitting errors.
  • Joint limits: Finger and wrist angles outside anatomical ranges point to failed estimates.
  • Identity consistency: Left and right hands should not swap labels mid-sequence.
  • Coverage: The share of frames with valid hand poses during manipulation phases, where they matter most.

Recent large-scale pipelines turn these checks into per-sample confidence. The JoyAI-RA 0.5 data curation pipeline scores recovered hand trajectories on visibility, reprojection, and temporal consistency. It also screens episodes for timestamp alignment, schema completeness, and agreement between video and reconstructed hand states.

Pose quality also interacts directly with annotation quality. Labels for contact onset, grasp type, and task phase are only as accurate as the timestamps to which they are attached. When teams annotate egocentric video for robot manipulation, synchronization verification should be completed before labeling begins. Misaligned pose overlays force annotators to compensate visually, which can hide the underlying timing error and propagate it into the labels, reducing the reliability of the final dataset.

How Do You Decide Whether Egocentric Pose Data Is Usable?

Usability is a routing decision made per session, against the requirements of the downstream task. Binary accept-or-reject rules waste data, because many failures are deterministic and fixable. A tiered outcome keeps more of the collection while protecting the training signal.

Tier Typical condition Action
Use as-is Offset and reprojection error within task tolerance; conventions documented Train directly and keep the audit report with the data
Repair Constant offset, linear drift, or a known convention mismatch Apply the correction, then rerun every check
Weak supervision Video and task labels are sound, but poses are unreliable Use for representation or latent-action pretraining; exclude from action targets
Discard or recapture Unknown clocks, missing calibration, or large unexplained jumps Remove and feed the failure back into the capture protocol

The third tier is where many teams leave value on the table. JoyAI-RA retains clips with valid video and language but unreliable hand poses, and uses them for latent-action world-model pretraining. Those clips never feed explicit action learning, so noisy trajectories cannot corrupt the policy.

Run the audit on a stratified pilot sample before scaling. Cover every device type, firmware version, operator, and environment, since timing and calibration faults tend to cluster by setup. Report usable hours per recorded hour for each group to estimate realistic yield. Record provenance for every session, including device, calibration file, and consent record, because data without it cannot be audited later.

The audit is also the fastest way to improve collection. Findings usually point to a few protocol changes, such as hardware triggering or a shared clock. A visible sync event like a clap at session start and end, per-session calibration, and logged conventions also help. Each change moves future sessions from the repair tier into the use-as-is tier.

How Digital Divide Data Can Help

Digital Divide Data works with Physical AI teams at the point where egocentric captures meet training pipelines. DDD’s sensor data annotation services combine automated checks, reviewer validation, and temporal consistency audits across synchronized video, IMU, and pose streams. Timing lag, convention errors, and implausible joints are flagged before labels are applied. Each session receives a documented outcome, so engineering teams know which data is ready, which needs correction, and which should be routed elsewhere.

When the audit shows that problems start at capture, DDD’s egocentric data collection services support protocol design, including sync events, per-session calibration steps, and metadata standards for coordinate conventions. For humanoid and manipulation programs, the same teams extend this work to joint pose labeling, task phase segmentation, and cross-sensor QA. DDD is platform agnostic and works within a client’s existing tools and formats.

Turn inconsistent egocentric captures into training data your models can trust. Talk to an Expert.

Conclusion

Inconsistent timing and coordinate systems rarely make egocentric data worthless by themselves. The real risk is uncertainty about how large the errors are and whether anyone has measured them. A short audit of clocks, frames, reprojection, and pose plausibility converts that uncertainty into numbers a team can act on.

Teams that audit early tend to scale collection with predictable yield and fewer retraining cycles. Teams that skip the audit usually discover misalignment through unexplained policy failures, long after the data has been labeled. 

References

Fan, Z., Dai, P., Su, Z., Gao, X., Lv, Z., Zhang, J., Du, T., Wang, G., & Zhang, Y. (2024). EMHI: A multimodal egocentric human motion dataset with HMD and body-worn IMUs. https://arxiv.org/pdf/2408.17168

Yoon, T., Han, Y., Ji, S., Park, J., Kim, S., Kwon, T., & Kim, H.-S. (2026). EgoXtreme: A dataset for robust object pose estimation in egocentric views under extreme conditions. https://arxiv.org/html/2603.25135

JoyAI-RA Team, Joy Future Academy, JD. (2026). JoyAI-RA 0.5: Scaling robot manipulation learning via dual action alignment. arXiv preprint arXiv:2608.05674. https://arxiv.org/pdf/2608.05674

Frequently Asked Questions

How much time offset between egocentric video and pose data is acceptable?

It depends on the task and how fast the hands move. A 20-millisecond offset at one meter per second misplaces a hand by about two centimeters. That may be fine for activity recognition and too much for grasp retargeting.

How to sync egocentric video and pose data recorded on different clocks?

Estimate the offset from the data itself using motion correlation, which compares angular velocity from the headset IMU or visual odometry with angular velocity from the pose stream. Measure it at the start, middle, and end of each session to catch drift or sudden jumps.

What is the quickest way to tell if my coordinate systems are wrong?

Run a few physical sanity checks first, including gravity direction at rest, stable bone lengths, valid rotations, and a floor at the declared height. Then project 3D keypoints onto video frames and measure reprojection error, because misaligned frames show up as keypoints that miss the hands.

Should we throw away egocentric clips that have bad pose data?

Often you can keep them. If the video and task labels are sound, those clips can still support representation or latent-action pretraining, as long as they are excluded from action targets. Discard only sessions with unknown clocks, missing calibration, or large unexplained jumps.

How to Evaluate Egocentric Video and Pose Data Usability When Timing and Coordinates Don’t Match Read Post »

AI data operations professional reviewing data quality and model performance metrics

How to Measure ROI From AI Data Operations and Data Quality Investments

The ROI of AI data operations is measurable when you tie data quality spend to four concrete outcomes: accuracy gained per unit of quality improvement, the cost of model failures traceable to data, re-annotation cost avoided through getting labels right the first time, and faster time-to-production. Most teams treat data quality as an unbudgeted cost center because they never instrument these links. Once you attribute model behavior to specific data decisions, AI data operations stop looking like overhead and start reading as one of the highest-return investments in the program.

Data quality decisions compound over a model’s lifecycle, so a shortcut taken during labeling shows up months later as a production regression that costs far more to fix than it would have to prevent. Programs that treat data collection and curation and data annotation solutions as core infrastructure, rather than preparatory steps, tend to reach production faster and spend less on rework. The same holds for model evaluation services, which turn vague quality claims into numbers a finance team can act on. Reasoning about ROI at this level requires more than a capsule answer, because the value hides in the links between data work and model behavior that most dashboards never surface.

Key Takeaways

  • Data quality pays off in four clear ways: better model accuracy, fewer costly failures, less repeated labeling work, and faster launches.
  • The return on good data is easy to miss because you pay for it upfront, but the benefits show up much later.
  • Bad data is expensive, and according to Gartner research on data quality, poor data quality costs organizations an average of 12.9 million dollars per year.
  • A model can only be as good as the data it learns from, so cleaning up the data usually helps more than switching to a bigger model.
  • Track the right numbers, like how consistent your labels are and how much accuracy improves after a data fix, so you can prove the value to leadership.
  • The best way to win budget is to run a small test on your own data and show the real savings before scaling up.

What Is AI DataOps ROI and Why Is It Hard to Measure?

AI DataOps ROI is the measured financial return on the money, tooling, and people you commit to producing high-quality training and evaluation data. AI data operations, often shortened to AI DataOps, is the operating model that governs how data flows from sourcing through annotation to model training, continuously and at scale. The concept of AI data operations as an operating model is what separates a one-time labeling project from a managed data supply chain. ROI, in this context, is the ratio of the value that supply chain creates to what it costs to run.

Measurement is hard for a structural reason. The cost of data quality is paid upfront and is easy to see, while the return arrives later and is spread across model accuracy, avoided failures, and shorter timelines. Finance teams see an invoice for annotation but no line item for the production incident that never happened. The difficult part is defining “value created” and “cost avoided” without claiming credit for changes caused by a new model, more compute, prompt changes, or product redesign. This asymmetry is why data quality is chronically underfunded, even in organizations that agree, in principle, that data drives model performance.

Data quality is not a single number; it is a distribution property measured across inter-annotator agreement, label accuracy against a gold set, edge-case coverage, and freshness. ROI attribution is the practice of tracing a change in model behavior back to a specific data decision. Cost of poor data quality, sometimes abbreviated CoPDQ, is the total of rework, failed deployments, and lost value that traces to defective data rather than to model architecture. Keeping these terms distinct is the first step toward an approximate calculator.

How Do I Calculate the ROI of Data Quality for AI?

ROI equals the net value created by a data quality investment, divided by the cost of that investment, expressed as a percentage. The difficulty is never the arithmetic; it is populating the numerator with values you can defend. A workable calculation isolates four value streams, each tied to a data quality lever you actually control.

  1. Accuracy gain per quality improvement: The economic effect of improved precision, recall, task success, factuality, safety, or another production-relevant metric.
  2. Cost of failure avoided: Fewer false decisions, unsafe actions, escalations, refunds, manual reviews, SLA breaches, or other costs caused by model error.
  3. Re-annotation cost avoided: Less re-annotation, relabeling, recollection, taxonomy repair, dataset rebuilding, and repeated QA. The labeling spend you do not repeat because the first pass met the quality bar.
  4. Time-to-production benefit: The value of the weeks saved when earlier deployment, faster retraining, shorter evaluation cycles, and less engineering time blocked on data issues.

To claim that a quality improvement caused an accuracy gain, one has to hold the model constant and change only the data, then measure the difference on a stable evaluation set. This is the same controlled-comparison logic that underpins credible model evaluation beyond benchmark scores, where the goal is to attribute performance to a cause rather than to report a leaderboard position. Without that control, any accuracy number you report is a correlation dressed up as a return.

A frequent objection is that intangible benefits resist quantification. That objection is weaker than it sounds. Cost-benefit analysis and net present value methods, long used for enterprise technology, apply cleanly here once you accept expected values instead of certainties. An interactive ROI estimation approach for data analytics and related DataOps frameworks shows that even probabilistic returns can be modeled, discounted, and compared against alternatives. 

What Is the Cost of Poor Training Data Quality?

Data quality affects model accuracy through several mechanisms, including label correctness, coverage of the deployment distribution, class balance, hard-negative quality, duplication, leakage, data freshness, and consistency of the annotation taxonomy. These mechanisms do not create a fixed one-to-one relationship between “quality score” and model accuracy. A one-point quality improvement in a saturated class may do little, while the same effort on a rare failure slice can materially change production behavior.

The cost of poor training data quality is the sum of what you spend fixing, re-running, and recovering from data that was defective before it ever reached the model. Some of that cost is direct and invoiced; most of it is indirect and absorbed as delay, rework, and lost trust. According to Gartner research on data quality, poor data quality costs organizations an average of 12.9 million dollars per year across industries. That figure predates the current wave of AI adoption, and AI tends to amplify data problems rather han tolerate them, because a model trained on defective data reproduces the defect at scale.

For AI programs specifically, the largest hidden cost is failure attributable to data rather than to the model. When a system underperforms in production, the default response is another round of architectural experimentation, which is expensive and usually misdirected. Research on why pilots stall is consistent on this point; data readiness is the primary reason AI pilots fail to reach production, ahead of model quality, integration gaps, or organizational misalignment. Every hour spent tuning a model to compensate for bad labels is an hour billed to the wrong problem.

Re-annotation is the most concrete and most avoidable cost. When guidelines are ambiguous or annotators are uncalibrated, the first labeling pass produces inconsistencies that only surface after a production cycle, and the batch has to be redone. Disciplined AI data preparation services reduce this by fixing quality upstream, at cleaning, normalization, and validation, before defective examples ever enter a training run. Paying once for correct labels is cheaper than paying twice for the same data plus the cost of the failure in between.

How Does Data Quality Affect AI Model Accuracy?

Model accuracy is bounded by the quality of the data it learns from, and past the prototype stage, data quality moves the needle more reliably than model size does. A single record can look fine in isolation, so accuracy is really a property of the whole training distribution: its consistency, its coverage of edge cases, and how faithfully it represents the inputs the model will meet in production. Improve those properties and accuracy tends to rise; degrade them and it falls, regardless of architecture.

Recent research supports the idea that dataset design can change both performance and training efficiency. The DataComp-LM study at NeurIPS 2024 found that model-based filtering produced a 7B model with a 6.6 percentage-point MMLU improvement over a prior open-data baseline while using 40% less compute. The result is specific to that experimental setup. It still shows how data-quality investment can affect both the numerator and denominator of AI economics.

When annotators disagree or apply guidelines inconsistently, the model receives contradictory signals and learns a blurred version of the task. This is why inter-annotator agreement is treated as a leading indicator of dataset reliability rather than a bureaucratic checkbox. In preference-based training, noise is even more corrosive, because the model optimizes directly against human judgments. Well-run human preference optimization with RLHF and DPO depends on clean, calibrated preference data, since inconsistent comparisons pull the reward signal toward a coin flip and the alignment gains evaporate.

Coverage is the other half of the story. A model trained on data that does not represent the production input distribution fails systematically on the inputs it never saw, and those failures stay hidden during a pilot because the pilot evaluation set is drawn from the same curated source as the training data. Distinguishing a coverage problem from a volume problem requires error analysis on evaluation failures, not more of the examples the model already handles. Adding data indiscriminately raises cost without raising accuracy; adding the right data raises accuracy where it was failing.

What Metrics Matter Most for AI Data Quality ROI?

The strongest ROI scorecards combine data metrics, model metrics, operational efficiency, and business outcomes. A single data-quality percentage cannot show whether the model learned anything useful from the improvement.

Which leading data-quality metrics should teams track?

Useful leading metrics include inter-annotator agreement, gold-set accuracy, defect rate by class, guideline exception rate, duplicate rate, coverage by target slice, provenance completeness, rework rate, time to detect data defects, and time to remediate them. These show whether the data operation is becoming more consistent and representative. They are especially useful for diagnosing why a model metric moved, but they should not be reported as ROI on their own.

Two operational measures are particularly useful at scale:

  • Quality-adjusted throughput: Accepted examples per unit of time after subtracting rejected or reworked output.
  • First-pass yield: Percentage of delivered examples that pass the agreed quality threshold without correction.

These metrics expose false economies when low-cost, high-volume workflows generate enough rework to reduce accepted output.

Which model metrics should connect data quality to performance?

The model layer should use metrics tied to the task: precision and recall for detection, mAP or IoU for perception, success rate for robotic tasks, word error rate for speech, factuality and preference scores for generative models, or calibrated human-evaluation scores where automated metrics are weak. Track the delta by data version and by deployment slice.

A particularly useful metric is model improvement per 1,000 accepted examples. It shows the marginal productivity of new data and helps identify diminishing returns. When the metric flattens, more of the same data may no longer justify the cost, and the program should shift toward harder examples, new scenarios, or targeted error slices.

Which business metrics turn model improvement into ROI?

Business metrics should be financial or operational outcomes the organization already recognizes, such as reviews avoided, incidents prevented, successful autonomous task completions, hours saved, or launch days gained.

The 2026 SAS and IDC Data and AI Impact Report found that organizations with stronger trustworthy-AI practices were much more likely to report strong ROI, and it identifies data quality and governance as part of that trustworthiness. The finding is correlational across organizations, so program-level attribution still matters.

How Do I Justify Investment in AI Data Operations?

The business case is strongest when it starts from an expensive model failure or operational bottleneck, then works backward to the data condition causing it. This shifts the discussion from “we need higher-quality labels” to “we can reduce this measurable failure mode by improving this part of the data supply chain.” The second statement gives leadership a problem, a mechanism, and a financial outcome.

Consider a hypothetical perception program with 2 million production decisions per year. A specific data-quality gap contributes to 8,000 avoidable manual reviews, each costing $12 in labor and operational overhead. If targeted recollection, annotation, and QA costing $140,000 reduces those reviews by 60%, the annual avoided review cost is $57,600, which alone does not justify the investment.

The same intervention may also avoid $90,000 in re-annotation and retraining, bring a product milestone forward by three weeks with $120,000 of quantified contribution margin, and reduce an expected $40,000 of annual incident exposure. Total annualized value becomes $307,600. Against a $140,000 investment, first-year ROI is about 120%, with a payback period of roughly 5.5 months.

The numbers are hypothetical, but the structure is the point. A serious AI DataOps business case should state assumptions, isolate each value pool, avoid double counting, and show a low/base/high sensitivity range. It should also track actual performance after the investment rather than treating the approved business case as proof that the return occurred.

Industry ROI research puts the average return on AI investment at roughly 3.7 dollars for every dollar spent, with top performers reaching 10 to 1, and the programs at the top of that range are the ones that got their data supply chain right first.

The build, buy, or partner choice is where justification meets execution. Standing up internal annotation operations carries hidden costs, workflow design, quality-system development, guideline authoring, and agreement monitoring, that most teams discover only after the first production cycle reveals inconsistencies requiring rework. Working through the build vs. buy vs. partner decision for AI data operations reframes the question as one of capacity rather than control, and it usually reveals that the true cost of building internally is higher than the sticker price of a specialist partner.

The strongest justification is a small, instrumented pilot. Run a controlled comparison on a slice of your own data, measure accuracy and re-annotation rates against your current baseline, and price the time-to-production difference. A pilot that reports accuracy gain per quality improvement, rework avoided, and weeks saved gives you an ROI number grounded in your own operation, which is far more persuasive than any industry benchmark. Approach the investment with the same engineering discipline you would apply to any system that has to run reliably at scale, and the case tends to make itself.

How Digital Divide Data Can Help

Digital Divide Data runs AI data operations as a managed function, which is what makes the ROI levers in this article measurable rather than theoretical. Our data collection and curation services build datasets around coverage planning, so the training distribution matches production inputs, and the accuracy gains show up where models were previously failing. Each dataset moves through defined acceptance criteria and multi-layer review, with quality reported as measured agreement and accuracy against a gold set, not asserted. That reporting is what lets a finance team attribute an accuracy delta to a specific data investment.

On the evaluation side, our model evaluation services produce the held-out and adversarial sets teams need to isolate whether a regression came from the data or the model, which is the diagnostic step that prevents wasted architectural experimentation. Where alignment is the constraint, our human preference optimization workflows collect clean, calibrated preference data for RLHF and DPO, so the reward signal is not degraded by annotation noise. We plug into shared dataset lineage and shared quality definitions, so visibility into agreement metrics and provenance stays with your team throughout.

Turn your data quality spend into a measurable return. Talk to an Expert!

Conclusion

The return on data quality is real, but it is invisible until you instrument the links between data decisions and model behavior. Accuracy gained per quality improvement, failures avoided, re-annotation not repeated, and weeks saved before launch are all measurable once you hold the model constant and change the data deliberately. Treat those as line items, and data operations stop being read as overhead.

Organizations that measure this well fund data quality as an investment with a tracked return, and their models move from pilot to production while competitors keep re-architecting. Organizations that skip the measurement keep absorbing the cost of poor data as unattributed delay and rework, without ever seeing the bill for what better data would have prevented. The gap between the two is not model architecture; rather, it is whether the data supply chain is treated as a managed function with a number attached. 

References

Gartner. (2024). Data Quality: Why It Matters and How to Achieve It. Gartner Data & Analytics. https://www.gartner.com/en/data-analytics/topics/data-quality

Agility at Scale. (2026). AI Business Impact Metrics: How to Measure ROI Without Self-Deception (citing IDC AI ROI Study, 2024). https://agility-at-scale.com/ai/strategy/ai-business-impact-metrics/

Bayram, F., Ahmed, B. S., Hallin, E., & Engman, A. (2023). DQSOps: Data Quality Scoring Operations Framework for Data-Driven Applications. arXiv preprint. https://arxiv.org/pdf/2303.15068

Frequently Asked Questions

How do I calculate the ROI of data quality for AI?

Divide the net value a data quality investment creates by what it costs, then populate the value side with four streams you can defend: accuracy gained per quality improvement, cost of failures avoided, re-annotation cost avoided, and time-to-production saved. The arithmetic is simple; the work is isolating each stream by holding the model constant and changing only the data.

What is the cost of poor training data quality?

It is the total of rework, failed deployments, and lost value that traces to defective data rather than to the model. Gartner puts the average cost of poor data quality at about 12.9 million dollars per year across industries, and for AI programs, the highest hidden cost is failure that gets blamed on the model when the real problem was the data.

How does data quality affect AI model accuracy?

Accuracy is bounded by the quality of the training distribution, so label noise and poor coverage cap how well a model can perform regardless of architecture. Inconsistent labels give the model contradictory signals, and gaps in coverage cause systematic failures on inputs the model never saw, which often stay hidden until production.

What metrics matter most for AI data quality ROI?

Track inter-annotator agreement, annotation accuracy against a gold set, edge-case coverage, dataset lineage completeness, and the accuracy change attributable to each data intervention. Measuring data quality and model quality separately is what lets you tell whether a regression came from the data or the training procedure, so you fix the right layer instead of re-architecting the model.

How to Measure ROI From AI Data Operations and Data Quality Investments Read Post »

Team reviewing AI model outputs and discussing human feedback for RLHF and RLAIF training

When to Use Human Feedback vs. AI Feedback: A Decision Framework for RLHF and RLAIF

Use human feedback training when the task is subjective, safety-critical, or needs audit weight, domain expertise, contextual judgment, or safety decisions, and use AI feedback when you need cheap, fast, repeatable, consistent labels for well-specified tasks at scale. Most production teams do best with a hybrid; AI-generated preference labels for volume and iteration speed, with a human-labeled evaluation set held as ground truth and human review reserved for the cases where the AI judge is known to fail. The real decision is not RLHF or RLAIF as rival algorithms, but who writes the preference labels for a given slice of your data.

The choice of feedback source shapes cost, turnaround, and the defensibility of an alignment program before a single reward model trains. Teams that treat it as a one-time switch tend to either overpay for human labels on tasks a model could judge, or quietly ship a model that inherits an AI judge’s blind spots. Getting it right depends on disciplined data collection and curation services and, for anything user-facing, structured trust and safety solutions that decide where human judgment is non-negotiable. The framework below turns that judgment into repeatable rules.

Key Takeaways

  • Keep expert human review for complex decisions, subjective calls, the safety-sensitive decisions, the work where mistakes could harm people and anything that has to stand up to a regulator or customer.
  • Use AI feedback for high-volume routine labeling tasks after confirming that it meets agreed quality standards.
  • AI feedback can match human quality on clear tasks, but AI reviewers can favor convincing answers even when those answers are wrong.
  • Compare the full cost of collecting, reviewing, and correcting feedback before choosing an approach.
  • Always keep a small set of human-checked answers as your trusted benchmark, and point human review at the spots where the AI grader is known to slip.
  • Build a combined workflow with clear rules for sending uncertain cases to people and recording their decisions.
  • Recheck feedback quality whenever the model, instructions, or intended use changes.

What are RLHF and RLAIF, and how do they actually differ?

Reinforcement Learning from Human Feedback (RLHF) is an alignment method where people compare or rate model outputs, those preferences train a reward model, and the reward model guides policy optimization. Reinforcement Learning from AI Feedback (RLAIF) keeps the same pipeline but replaces the human labeler with a capable language model that produces the preference labels. Both were designed to steer a model toward outputs people prefer, and the mechanics downstream, the reward model and the optimizer, can be identical. A clear grounding in reinforcement learning with human feedback helps before layering AI feedback on top. Both approaches need model evaluation services or equivalent internal capabilities to check whether training improves intended behavior. 

The distinction that matters is the source of the preference signal, not the training loop. RLHF preferences carry human judgment and audit weight; RLAIF preferences are cheaper, faster, and more internally consistent, but they inherit the labeler model’s biases. Empirical work on scaling human feedback with AI feedback found that on summarization and dialogue tasks, AI-labeled training reached win rates comparable to human-labeled training, which is why the method is taken seriously in production rather than treated as a shortcut.

One common mistake is to line up RLHF, RLAIF, and DPO as three competing choices. Direct Preference Optimization changes how you optimize, not who writes the labels, so it sits on a different axis entirely. You can run DPO on human-labeled pairs or on AI-labeled pairs. Keeping label source separate from optimization method is what makes the rest of this decision tractable, a point developed further in why human preference optimization with RLHF and DPO still matters.

When should you use human feedback vs. AI feedback for LLM training?

The strongest predictor of which source to use is how well the quality of a good answer can be specified in advance. When correctness is checkable or the rubric is explicit, an AI judge tends to label reliably and cheaply. When quality depends on taste, context, cultural nuance, or a judgment call a reasonable person could dispute, human labels are more reliable and, in regulated settings, the only ones that will hold up. The table below maps that threshold to concrete task types.

Task characteristic Preferred Feedback Route Example task
Verifiable or rule-based AI feedback Format compliance, code that runs, math with a checkable answer
Well-specified rubric AI feedback, human-audited Summarization, tone, instruction following
Source-grounded answers requiring contextual interpretation Hybrid feedback Supply the source; escalate unsupported judgments and disputed pairs
Subjective or contextual Human feedback Helpfulness in ambiguous queries, cultural fit
Safety-critical or regulated Human feedback and independent validation Medical, legal, financial, harm classification
Novel domain, weak AI judge Human feedback to bootstrap Low-resource languages, new verticals

Cost and speed pull in the opposite direction and belong in the same decision. Human labels are slower and more expensive per comparison, but they carry weight a regulator or customer will accept. AI labels scale almost without limit and stay consistent across millions of outputs, which is exactly what makes them attractive for early iteration. The practical rule is to let AI feedback absorb volume where the rubric is clear, and spend the human budget where the label is genuinely contested. How those human labels are elicited also matters, which is why the choice between preference annotation and scalar scoring for RLHF affects the signal quality you get from either source.

What is RLAIF and is it as good as RLHF?

RLAIF is reinforcement learning where an AI model, guided by a prompt or an explicit set of principles, generates the preference labels used to train a reward model or optimize a policy. Constitutional AI is the best-known instance: a model critiques and revises its own outputs against written principles, then those judgments become the training signal. On tasks with clear evaluation criteria, RLAIF has repeatedly matched RLHF in head-to-head human evaluations, and it does so at a fraction of the labeling cost.

The honest answer to whether it is as good is: on some tasks, yes, and on others, not yet. A statistical perspective on RLHF and its extensions notes that despite its scalability, AI feedback inherits the RLHF failure modes and adds new ones, so many systems still keep human supervision to anchor quality. RLAIF is strongest when the AI judge is clearly more capable than the model being trained and the task rubric is explicit. It weakens when the judge and the policy share a model family, because they also share blind spots, and when the teacher is no stronger than the student, the marginal gains shrink toward zero.

Can AI replace human annotators for preference labeling?

For a large share of routine, well-specified labeling, AI can now do most of the work, and pretending otherwise wastes budget. What AI cannot do is remove the human from the loop entirely without introducing risk you cannot see. The reliable pattern is not full replacement but reallocation: AI handles the bulk of labels, and humans move up the stack to write the rubric, audit the AI judge, and adjudicate the disputed cases. This is the same logic behind human-in-the-loop workflows for generative AI, where human effort is concentrated where it changes the outcome.

A workable division of labor tends to look like this:

  • AI feedback for first-pass preference labels on high-volume, clearly-specified tasks, so iteration is fast and cheap.
  • Human feedback for a fixed, high-quality evaluation set that never uses AI labels and serves as ground truth for every model version.
  • Human review targeted at the slices where the AI judge is known to miscalibrate, rather than spread evenly across all data.

Designing that human contribution well is its own discipline. Work on fine-grained human feedback for language model training shows that where and how granular the human signal is often matters more than sheer label volume, because a small amount of precise human judgment can correct systematic errors that no quantity of AI labels will catch.

What are the risks of using AI-generated feedback for RLHF?

The risks of AI feedback are specific, documented, and testable, which is good news because it means you can plan around them. The three that show up most often in production are reward hacking, bias amplification, and feedback-loop drift. A survey of reward hacking in large model systems describes how a policy can learn to satisfy an AI judge’s exploitable patterns, such as rewarding longer or more hedged answers, while getting no better by any human standard.

  1. Reward hacking: The policy exploits quirks in the AI judge’s rubric to score well without genuinely improving, producing constitutionally compliant surfaces that still violate intent.
  2. Bias amplification: The judge’s preferences reflect its own training data, so any bias is passed into the reward signal and then amplified by optimization, creating an echo chamber the model cannot see out of.
  3. Feedback-loop drift: When judge and policy co-adapt over successive rounds, the alignment target quietly moves, and shared model-family blind spots compound instead of cancelling out.

These are precisely the places where human review earns its cost. Catching them requires red-teaming the AI judge, checking its labels against a human ground-truth set, and monitoring for drift over training rounds, all of which sit inside a mature model performance evaluation practice. Skipping that step does not remove the risk; it just moves the discovery to production.

In what cases is human feedback required for AI alignment?

Some domains do not offer a genuine choice, because the value of a human label is not only its accuracy but its accountability. In healthcare, law, finance, and content-safety decisions, an AI judge’s approval carries no audit weight, and a wrong call has consequences that a cheaper label cannot justify. In these settings human feedback is required, not preferred, and the requirement is often regulatory rather than technical.

  • Safety and harm classification, where a false negative can cause real-world damage and the boundary is contested.
  • Regulated decisions, where provenance of the judgment must be demonstrable.
  • High-stakes agentic actions, where a model can take irreversible steps and oversight is the last line of defense.

For agentic systems in particular, the argument for human oversight strengthens as autonomy grows, since the cost of an unreviewed error rises with what the agent is allowed to do. Approaches to building trustworthy agentic AI with human oversight treat human feedback as a control surface rather than a labeling expense, which is the right frame whenever the downside of a bad decision is measured in harm rather than in metric points.

How should teams compare feedback cost and quality at scale?

Compare total feedback cost per accepted preference pair. Add judge inference, rubric development, annotator calibration, human audits, adjudication, and rework, then divide by pairs meeting the same acceptance criteria. Compare turnaround time separately, because specialist review can determine delivery speed even when inference is fast.

Assume a 10,000-pair pilot costs $12,000 with human feedback and yields 9,000 accepted pairs, or $1.33 each. An AI-assisted pilot costing $4,800 and yielding 8,000 accepted pairs costs $0.60 each. These illustrative totals include setup, labeling, audits, and rework; they are planning assumptions. Both routes must pass the same quality gate for the comparison to matter.

The lower figure justifies expansion only if downstream model performance also holds. Cheap labels can become expensive when they increase re-annotation, retraining, or investigation after deployment. Report accepted-pair cost alongside human-evaluated task success, critical-error rate, and the proportion of examples needing escalation.

Volume changes the calculation because rubric development is partly a fixed cost, while inference and review recur. Long responses, multiple judges, and frequent expert adjudication can increase the cost of AI feedback substantially. Run sensitivity checks on review rates and acceptance rates before committing to a production volume.

How Digital Divide Data Can Help

DDD’s human preference optimization services for RLHF and DPO support domain-specific rubrics, expert-labeled preferences, reward modeling, and direct preference optimization. Our domain specialists calibrate evaluators and collect structured feedback through rankings, pairwise comparisons, and scoring workflows. Dataset versioning and audit trails help teams trace how judgments entered an alignment program.

Our generative AI model evaluation services cover factual consistency, safety, task performance, and multilingual behavior across relevant modalities. Teams can use these capabilities to build human reference judgments, investigate disagreement, and evaluate models trained with different feedback sources. For programs combining human and AI feedback, the engagement can begin with a scoped pilot that defines acceptance criteria and review responsibilities.

Design a feedback program that uses each source where it is strongest. Talk to an Expert!

Conclusion

The RLHF versus RLAIF question is really a sourcing decision made one data slice at a time: who should write the preference label here, given how well the answer can be specified and how much a wrong call costs. Organizations that internalize this route AI feedback to high-volume, well-defined tasks and reserve human feedback for the subjective, safety-critical, and audit-bearing cases, keeping a human ground-truth set as the fixed reference throughout.

Teams that skip the distinction tend to fail in one of two directions, either burning budget on human labels a model could have judged, or shipping a model that has quietly optimized against an AI judge’s blind spots. The difference is not access to a better algorithm; it is the discipline to decide the label source deliberately. 

References

Lee, H., Phatale, S., Mansoor, H., Mesnard, T., Ferret, J., Lu, K., Bishop, C., Hall, E., Carbune, V., Rastogi, A., & Prakash, S. (2024). RLAIF vs. RLHF: Scaling Reinforcement Learning from Human Feedback with AI Feedback. Proceedings of ICML. https://arxiv.org/abs/2309.00267

Liu, P., Shi, C.,  Sun, W. W. (2026). Reinforcement Learning from Human Feedback: A Statistical Perspective. arXiv preprint. https://arxiv.org/pdf/2604.02507

Morampudi, A., Irrinki, U., Grandhi, R., Pagadala, V., & Maddula, M., Springer Nature. (2026). A survey of reward hacking in agentic large language model systems. Discover Artificial Intelligence. https://link.springer.com/article/10.1007/s44163-026-01980-z

Frequently Asked Questions

When should I use human feedback instead of AI feedback for LLM training?

Use human feedback when the task is subjective, safety-critical, or needs to hold up to an audit, and when a good answer depends on judgment a reasonable person could dispute. Use AI feedback when the task is well-specified or verifiable and you need cheap, consistent labels at scale.

Is RLAIF as good as RLHF?

On tasks with a clear rubric, RLAIF has matched RLHF in head-to-head human evaluations at much lower cost. It weakens when the AI judge shares a model family with the policy being trained, or when the judge is no more capable than that policy, so many teams still keep human supervision to anchor quality.

Can AI fully replace human annotators for preference labeling?

Not without introducing risk you cannot see. AI can handle most routine, well-specified labeling, but humans are still needed to write the rubric, audit the AI judge, maintain a ground-truth evaluation set, and settle the disputed cases where the judge miscalibrates.

What can go wrong when I use AI-generated feedback for RLHF?

The three most common problems are reward hacking, where the model exploits the judge’s rubric without improving; bias amplification, where the judge’s own biases get baked into the reward signal; and feedback-loop drift, where the judge and policy co-adapt and the alignment target quietly moves. All three are testable if you red-team the judge and check it against human labels.

When to Use Human Feedback vs. AI Feedback: A Decision Framework for RLHF and RLAIF Read Post »

Annotator Agreement

How to Design Inter-Annotator Agreement Protocols That Actually Improve Model Quality

Udit Khanna

Inter-annotator agreement (IAA) is the measurement of how consistently multiple annotators apply the same labels to the same data, and it has become the default health check for annotation programs: run a sample through two labelers, compute a number, treat a high number as proof that the data is trustworthy.

This blog covers how to design an IAA protocol that does real diagnostic work: which statistic to use for which label type, how to build the calibration process the measurement depends on, how to distinguish noise-like disagreement from pattern-like disagreement, and how the resulting signal should actually change what a program does next. Text annotation services and model evaluation services are the two capabilities most directly involved.

Key Takeaways

  • A high agreement score does not guarantee training-worthy data. Whether disagreement behaves like random noise or like a learnable pattern matters more than the raw statistic, and a protocol that only reports the number misses the distinction that actually predicts downstream model quality.
  • The right statistic depends on the label type, not convention. Cohen’s kappa suits two annotators on a fixed category set; Krippendorff’s alpha handles more than two annotators, missing labels, and ordinal or interval label types that kappa was never built for.
  • Low agreement is a diagnostic, not a verdict. A category that calibrates poorly is usually telling you the guideline is ambiguous or the category boundary is genuinely contested, and the fix is guideline iteration or adjudication (routing disputed items to a senior reviewer for a final call), not simply retraining annotators.
  • Agreement should be measured and reported per category, never as one blended score. A single aggregate number hides exactly the categories where disagreement concentrates, which are also usually the categories where the model will struggle most.
  • The protocol has to specify what happens after the number, not just how to compute it. Adjudication paths, guideline revision triggers, and distributional labeling (recording the spread of judgments on contested items instead of forcing one answer) all need to be decided in advance, or a low score just sits there without changing anything.

What IAA Actually Measures, and What It Does Not

Raw percent agreement, the fraction of items where annotators matched, is intuitive and misleading, because it does not correct for the agreement you would expect by chance alone. A task with two labels where 90 percent of items obviously belong to one category will show high raw agreement even from annotators guessing. Guessing the majority label is simply right most of the time. Chance-corrected statistics address this by comparing observed agreement to the agreement expected under random labeling. That is why they are the standard for any task with meaningfully skewed label distributions, a description that fits most real annotation programs.

What none of these statistics measure directly is whether the data is good for machine learning, which is a different question than whether humans agree. That is the distinction the Reidsma and Carletta finding turns on. Agreement measures the reliability of the labeling process. A machine learner, though, is specifically vulnerable to a kind of unreliability that agreement statistics do not flag: disagreement that is not random but follows an exploitable pattern, which the model will learn as if it were signal.

Choosing the Right Statistic for the Label Type

Cohen’s Kappa: The Default for Two Annotators, Fixed Categories

Cohen’s kappa fits the common case cleanly: two annotators, a fixed set of categorical labels, no missing data. It is the right default for straightforward classification tasks with two labelers and should be the first thing reached for in that situation. Its limitations show up exactly outside that situation: it was not built for more than two annotators, it does not have a standard extension for missing labels, and it treats all disagreements as equally wrong even when some categories are conceptually closer than others.

Krippendorff’s Alpha: The Generalization That Handles Real Programs

Krippendorff’s alpha was built to handle what kappa was not: any number of annotators, missing labels, and different data types (nominal, ordinal, or interval) through a single flexible framework. Missing labels are the normal case once a program uses distributed annotation pools rather than a fixed pair. Most production annotation programs outgrow Cohen’s kappa’s assumptions quickly, with multiple annotators rotating through a task, incomplete overlap between them, and severity scales that are ordinal rather than purely categorical. That is why alpha is usually the more defensible choice at real operational scale, even though kappa remains more common in casual usage.

Weighted Measures for Ordinal and Graded Labels

Neither statistic in its basic form distinguishes a near-miss from a wildly wrong label. On a severity scale, an annotator who says moderate when the correct label is high should count as less wrong than one who says minimal, and weighted variants of both kappa and alpha exist specifically to encode that: disagreements between adjacent categories are penalized less than disagreements between distant ones. Any protocol using an ordinal or graded label set without a weighting scheme is measuring agreement as if every wrong answer were equally wrong, which understates reliability on exactly the categories where near-miss disagreement is most common and least concerning.

Distinguishing Noise-Like Disagreement From Pattern-Like Disagreement

This is the diagnostic step most protocols skip entirely, and it is the one the research says matters most for downstream model quality. Noise-like disagreement looks random: it does not correlate with any feature of the input, any particular annotator, or any particular time period. A model trained on it treats the disagreement as label noise, which common training procedures tolerate reasonably well at moderate levels, though that tolerance varies by task, model, and noise rate. Pattern-like disagreement correlates with something: a specific annotator systematically applying a stricter standard, a particular input feature that reliably splits annotators, a category boundary that is contested in a consistent, learnable direction. A model trained on pattern-like disagreement learns the pattern. And because the pattern reflects an unresolved ambiguity in the labeling rather than a real signal in the task, the model inherits the ambiguity as if it were ground truth.

The practical test is to break down agreement by annotator, by input feature, and by time period rather than reporting only the aggregate. A category with acceptable overall agreement that splits sharply along one annotator or one input characteristic is exhibiting pattern-like disagreement even though the topline number looks fine, and it is worth the extra analysis pass specifically because the topline number will not surface it.

What the Protocol Should Specify Beyond the Statistic

A complete IAA protocol answers several questions that the raw statistics do not. What triggers adjudication: at what score, or after how many conflicting labels, does a case route to a senior reviewer for a final call rather than getting resolved by majority vote or left ambiguous? What triggers guideline revision: a category with persistently low agreement across calibration rounds is usually telling you the instructions are ambiguous rather than that the annotators need more training, and the fix is rewriting the guideline with worked examples for the boundary that keeps getting crossed. And should contested categories get forced to a single label, or preserved as distributional labels that record the actual spread of judgment? That choice should be made deliberately per category rather than defaulted to consensus everywhere. A protocol silent on all three produces a number without producing a decision.

A Worked Example at the Boundary

Here is what a worked example looks like in practice. In a content moderation taxonomy, the item “you people never listen” kept splitting annotators between Harassment and Not Harassment: one group read “you people” as targeting a protected group, the other as generic frustration. The adjudicator’s ruling was that without surrounding context indicating a protected group, the phrase alone is generic, so the label is Not Harassment. That reasoning went into the guideline as a worked example, paired with a contrast case where “you people” follows an explicit ethnic reference and the label flips to Harassment. Agreement on the category moved from contested to stable in the next calibration round, not because annotators got smarter, but because the boundary finally had an example sitting on it.

How Digital Divide Data Can Help

Everything above is method, and it is portable: a team can implement all of it internally. This section is for readers weighing whether to build that muscle alone or with a partner. Either way, the same components decide whether IAA actually improves model quality: the right statistic for the label type, agreement measured and reported per category, and a defined path from a low score to a guideline fix or an adjudication decision. Producing those is the work we do.

Calibration and measurement. Text annotation teams run structured calibration rounds with the statistic matched to the label type, reporting agreement per category and per annotator so pattern-like disagreement surfaces instead of hiding inside an aggregate.

The evaluation layer that closes the loop. Model evaluation services build the held-out sets and adjudication workflows that turn a low agreement score into a guideline revision or a distributional label decision, not just a flagged number.

If your program can show its per-category agreement numbers, this discipline exists. If it can’t, that’s the starting point. Talk to an expert.

Conclusion

An inter-annotator agreement protocol earns its keep when it changes what a program does, not when it produces a number that clears a threshold. The statistic has to match the label type, the measurement has to be broken out by category rather than blended into one aggregate, and the protocol has to specify in advance what happens when agreement comes in low: adjudication, guideline revision, or a deliberate decision to preserve disagreement as signal rather than force consensus.

The test for any annotation program’s IAA protocol is direct: the last time a category came in below target, what changed as a result? If the honest answer is nothing, the protocol is measuring reliability and doing nothing with what it finds, which means it is not actually protecting model quality. It is producing a number that looks like it is.

References

Artstein, R., & Poesio, M. (2008). Survey article: Inter-coder agreement for computational linguistics. Computational Linguistics, 34(4), 555–596. https://aclanthology.org/J08-4004/

Krippendorff, K. (2004). Reliability in content analysis: Some common misconceptions and recommendations. Human Communication Research, 30(3), 411–433. https://doi.org/10.1111/j.1468-2958.2004.tb00738.x

Reidsma, D., & Carletta, J. (2008). Reliability measurement without limits. Computational Linguistics, 34(3), 319–326. https://aclanthology.org/J08-3001/

Q1. What counts as a “good” kappa or alpha score? We keep hearing 0.8 as the bar.

Treat 0.8 as a starting heuristic, not a pass-fail line, and the Reidsma and Carletta finding is precisely why: a score at or above the conventional threshold does not guarantee the data is fit for training if the disagreement it contains follows an exploitable pattern rather than looking like noise. A more defensible bar is task-specific and category-specific: categorical, low-ambiguity labels should calibrate high, often above 0.8, while genuinely comparative or judgment-heavy categories can be legitimately useful for training at lower scores, provided the disagreement has been checked for pattern versus noise. A single universal threshold applied to every category in a taxonomy is usually wrong for most of them.

Q2. We have more than two annotators rotating through tasks with incomplete overlap. Which statistic should we use?

Krippendorff’s alpha, and this is close to the textbook case it was designed for. Cohen’s kappa assumes a fixed pair of annotators labeling the same complete set of items, an assumption that breaks the moment annotators rotate and overlap only partially. Alpha handles any number of annotators and tolerates missing data by design, computing agreement from whatever overlapping judgments actually exist rather than requiring a complete matrix. Programs that default to kappa out of familiarity and then struggle to make it work with rotating annotator pools are usually fighting the tool rather than the problem; switching to alpha resolves the mismatch directly.

Q3. A specific clause or content category keeps coming in with low agreement, no matter how much we retrain annotators. What now?

Stop retraining annotators and start rewriting the guideline, because persistently low agreement after repeated training is a strong signal that the ambiguity lives in the instructions, not in annotator skill. Pull the specific disputed cases from that category, have someone with the authority to make a final call adjudicate each one, and write the resulting reasoning into the guideline as a worked example precisely at the boundary that keeps getting crossed. If agreement still does not improve after a guideline revision informed by real disputed cases, consider whether the category is genuinely contested rather than poorly specified, in which case a distributional label that preserves the range of judgment may serve the downstream use case better than forcing an artificial consensus.

Q4. How do we tell if our disagreement is the noise-like kind or the pattern-like kind that the Reidsma and Carletta research warns about?

Break the disagreement down along three axes before concluding anything from the aggregate score: by annotator, to see whether one labeler systematically diverges from the others; by input feature, to see whether disagreement clusters around a particular kind of case rather than spreading evenly; and by time, to see whether agreement drifted as guidelines evolved or as different annotator cohorts rotated through. Noise-like disagreement will not show a clean pattern along any of these axes. Pattern-like disagreement usually will, most often as one annotator applying a consistently different standard or one input characteristic that reliably splits judgment. Finding a pattern is actionable, since it usually points directly at a guideline gap or a training gap; finding none is itself useful information, since it means the topline agreement score is probably a fair description of the data’s reliability.

Q5. Should disagreement ever be kept in the final dataset instead of being resolved to a single label?

For genuinely contested categories, yes, and forcing consensus in those cases can cost you real signal. Some judgments, whether content crosses a subjective severity threshold, whether a clause is market-standard or a negotiated deviation, reflect legitimate variation in expert judgment rather than a resolvable error, and collapsing that variation into one adjudicated label discards information a downstream model or decision system could use, such as calibrating its own confidence to match the level of human disagreement on similar cases. The decision should be made deliberately per category during protocol design, not applied as a blanket policy: categories with a clear correct answer should be adjudicated to one label, while categories with legitimate, persistent expert disagreement are often better served by distributional labels that preserve the spread.


How to Design Inter-Annotator Agreement Protocols That Actually Improve Model Quality Read Post »

Scroll to Top