Celebrating 25 years of DDD's Excellence and Social Impact. ✖

Robotics

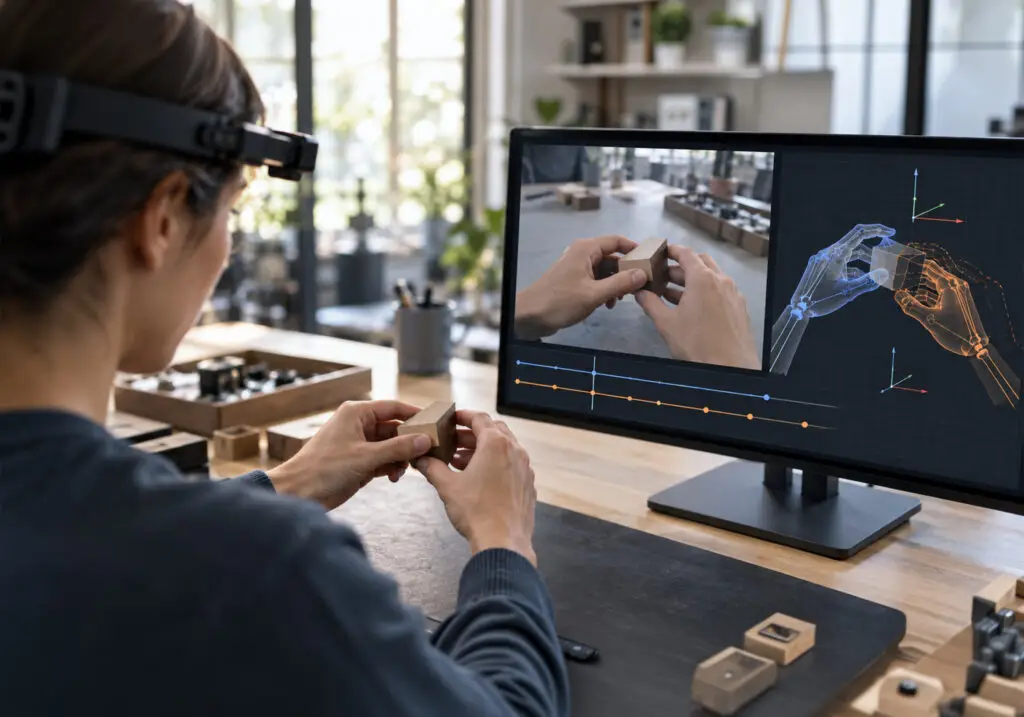
Person evaluating egocentric video and hand pose alignment on a monitor

How to Evaluate Egocentric Video and Pose Data Usability When Timing and Coordinates Don’t Match

Egocentric video and pose data with inconsistent timing and coordinate systems is often recoverable, and a structured audit tells you how much of it is. The audit documents every clock and coordinate frame, measures time offset and drift per session, and checks spatial alignment through reprojection error. Each session then lands in one of four outcomes: use as-is, repair, route to weaker supervision, or discard. 

Most teams reach this question with a pilot batch already in hand. The videos play, the pose files parse, and the schema validates. The trouble surfaces later, when projected hand keypoints trail the real hand during fast motion or a grasp label fires before the fingers close.

These errors are costly because they are silent. A 30-millisecond offset or a flipped axis passes every format check, yet it teaches a model the wrong link between what the camera sees and what the body does. Whether a team runs its own egocentric data collection program or sources egocentric datasets from a reputed vendor, the usability question is best settled before scaling collection or labeling.

Key Takeaways

  • Mismatched timing and positions rarely cause visible errors, so a structured check is the most reliable way to learn whether the data can still be used.
  • Check timing before any labeling starts by confirming that the video and body-movement data line up at the start, middle, and end of every recording session.
  • Check positions by writing down how each data source defines direction, scale, and starting point, then overlay the body data on the video to confirm it matches.
  • Some body positions are guessed by software because the camera couldn’t see them clearly, so flag those and check that all movements look physically realistic.
  • Sort each recording into one of four groups: use as is, fix and use, use for less demanding training, or discard.
  • Test a small, varied sample before scaling up, and use what you find to improve how future data is collected.

What Is Egocentric Video and Pose Data, and Why Does Alignment Matter?

Egocentric video is the footage recorded from the viewpoint of the person performing a task, usually through smart glasses, a headset, or a head-mounted camera. Pose data describes where the body is in space over time. In robotics programs, it typically includes a six-degree-of-freedom (6-DoF) head or camera trajectory, 3D hand keypoints, and sometimes full-body joints from an IMU suit or motion capture. Programs that apply video annotation services to this footage are working with streams recorded by different sensors that were never guaranteed to agree. As egocentric datasets become the new standard for training robotics models, that agreement becomes a core data quality question.

Two separate properties decide whether the streams agree. Temporal alignment, also called synchronization, means every video frame and every pose sample refer to the same physical instant. Spatial alignment means every pose is expressed in a documented coordinate frame with a known transform to the camera. A dataset can pass one test and fail the other, so each one needs its own evaluation.

A few terms come up repeatedly in any usability audit. Using them consistently across capture, annotation, and training teams prevents avoidable errors.

Time offset

The constant difference between two clocks at a given moment, usually measured in milliseconds.

Clock drift

The rate at which that offset changes across a session.

Coordinate frame

The origin, axis directions, and handedness that give a position or rotation its meaning.

Extrinsic calibration

The rigid transform between two sensors, such as the headset tracking frame and the RGB camera.

Intrinsic calibration

The camera’s internal model, including focal length, principal point, and lens distortion.

Why Do Timing and Coordinate Systems Drift Apart in Egocentric Captures?

Inconsistency is the default state of multi-device egocentric capture. A typical rig combines a headset, wrist or body trackers, and sometimes external motion capture, each with its own clock and reference frame. Sensor synchronization for egocentric robotics data is harder than in vehicle-mounted rigs, because the sensors sit on a moving human head. There is no fixed mounting to calibrate against, and head motion is fast and unpredictable.

Where does timing break down?

Timing errors tend to come from a small set of repeatable sources. The team behind the EMHI multimodal egocentric motion dataset, for example, had to reconcile a host PC clock and a separate headset clock offline. Common sources include:

  • Independent device clocks that start at different epochs and drift apart over long sessions.
  • Timestamps assigned on arrival at the host PC, which can lag the true sensor capture time.
  • Camera exposure delay and rolling shutter, which shift the actual capture instant by a few milliseconds.
  • Variable frame rates and dropped frames, which break the assumption that frame N sits at N divided by the frame rate.
  • Tracker disconnections that leave gaps in the pose stream while video keeps recording.

Where do coordinate systems break down?

Spatial inconsistencies tend to be convention mismatches. Human motion formats, game engines, and robotics simulators disagree on which axis points up, and some use left-handed frames. Others come from tracking itself, such as SLAM drift that builds up over long, fast, or poorly lit sequences. Typical mismatches include:

  • Up-axis differences, such as Y-up body model outputs loaded into a Z-up simulator.
  • Quaternion ordering, where one tool writes w-x-y-z and another expects x-y-z-w.
  • The unit mismatches between millimeters and meters, which scale every trajectory by a factor of 1,000.
  • Camera conventions, where OpenCV and OpenGL point the y and z axes in opposite directions.
  • World origin resets when a headset re-localizes, which shift the entire trajectory mid-session.

How Do You Measure Temporal Alignment Between Video and Pose Streams?

Temporal evaluation starts with the timestamps themselves. Check that every stream is monotonic, with no duplicate or out-of-order samples. Plot the interval between consecutive samples to expose dropped frames and variable frame rates. Record which clock stamped each stream, because that determines which corrections are possible.

The next step is to estimate the offset between video and pose directly from the data. Motion correlation, which compares angular velocity from two independent sources, is more reliable than manual alignment. EMHI synchronized its headset and motion capture streams this way, correlating headset IMU angular velocity against the tracked rigid body on the headset. For video without an IMU, visual odometry or optical flow can supply the second signal. Cross-correlating the two signals gives the lag at which they match best.

A single offset estimate is not sufficient on its own. Estimate the offset in windows at the start, middle, and end of each session. A stable offset can be corrected with one shift, while a steadily growing one indicates clock drift that needs a linear correction. A sudden jump usually marks a tracker reconnection or re-localization, and the session should be split at that point.

Tolerance should come from the downstream task, because timing error turns into spatial error during motion. A hand moving at one meter per second with a 20-millisecond offset is misplaced by about two centimeters. That may be acceptable for activity recognition and unacceptable for grasp retargeting. The EMHI authors noted that at 30 Hz, residual synchronization error can reach 16.5 milliseconds, so they interpolated annotations onto the headset timestamps.

How Do You Validate Coordinate Frames and Spatial Calibration?

Spatial validation begins with a written pose contract for every data source. The contract states the up-axis, handedness, units, rotation representation, quaternion order, world origin, and the frame each pose is expressed in. If a supplier or internal team cannot produce this document, that gap is itself a finding.

Simple physical sanity checks catch most convention errors early. The following checks work on almost any egocentric pose dataset:

  • Gravity check: The accelerometer’s mean direction at rest should point along the declared down-axis.
  • Scale check: Bone lengths, such as wrist-to-knuckle distances, should match human proportions and stay constant across a session.
  • Rotation check: Every rotation matrix should have a determinant of +1, and every quaternion should have unit norm.
  • Floor check: Foot or floor height should sit near the declared ground plane.

Reprojection error is the most direct test of spatial calibration. Project 3D keypoints into the image using the camera intrinsics and extrinsics, then measure the pixel distance to where the joint actually appears. The EgoXtreme egocentric pose benchmark validated its ground truth this way, sampling 200 frames per scenario where keypoints were clearly visible. It reported mean reprojection errors under one percent of the 1408-pixel image width and a trajectory alignment error of 4.3 mm and 1.5 degrees.

Two details often decide whether reprojection results can be trusted. Egocentric cameras frequently use fisheye lenses, so projecting with a pinhole model inflates error near the image edges. Exposure timing also matters, and the EgoXtreme team corrected a few milliseconds of offset caused by camera exposure delay before final interpolation. Checking reprojection during fast motion therefore tests timing and calibration together.

Which Pose Quality Checks Matter Beyond Synchronization?

A perfectly synchronized and calibrated stream can still contain unusable poses. Hand tracking degrades under occlusion, motion blur, and low light, and many pipelines fill the gaps with learned pose priors. The key question for each joint is whether it was measured, inferred, or generated. Datasets that do not record this distinction force every downstream user to guess.

Useful plausibility checks include:

  • Temporal smoothness: Velocity and acceleration spikes beyond human limits signal tracking jumps.
  • Bone-length stability: Joint distances that stretch from frame to frame indicate fitting errors.
  • Joint limits: Finger and wrist angles outside anatomical ranges point to failed estimates.
  • Identity consistency: Left and right hands should not swap labels mid-sequence.
  • Coverage: The share of frames with valid hand poses during manipulation phases, where they matter most.

Recent large-scale pipelines turn these checks into per-sample confidence. The JoyAI-RA 0.5 data curation pipeline scores recovered hand trajectories on visibility, reprojection, and temporal consistency. It also screens episodes for timestamp alignment, schema completeness, and agreement between video and reconstructed hand states.

Pose quality also interacts directly with annotation quality. Labels for contact onset, grasp type, and task phase are only as accurate as the timestamps to which they are attached. When teams annotate egocentric video for robot manipulation, synchronization verification should be completed before labeling begins. Misaligned pose overlays force annotators to compensate visually, which can hide the underlying timing error and propagate it into the labels, reducing the reliability of the final dataset.

How Do You Decide Whether Egocentric Pose Data Is Usable?

Usability is a routing decision made per session, against the requirements of the downstream task. Binary accept-or-reject rules waste data, because many failures are deterministic and fixable. A tiered outcome keeps more of the collection while protecting the training signal.

Tier Typical condition Action
Use as-is Offset and reprojection error within task tolerance; conventions documented Train directly and keep the audit report with the data
Repair Constant offset, linear drift, or a known convention mismatch Apply the correction, then rerun every check
Weak supervision Video and task labels are sound, but poses are unreliable Use for representation or latent-action pretraining; exclude from action targets
Discard or recapture Unknown clocks, missing calibration, or large unexplained jumps Remove and feed the failure back into the capture protocol

The third tier is where many teams leave value on the table. JoyAI-RA retains clips with valid video and language but unreliable hand poses, and uses them for latent-action world-model pretraining. Those clips never feed explicit action learning, so noisy trajectories cannot corrupt the policy.

Run the audit on a stratified pilot sample before scaling. Cover every device type, firmware version, operator, and environment, since timing and calibration faults tend to cluster by setup. Report usable hours per recorded hour for each group to estimate realistic yield. Record provenance for every session, including device, calibration file, and consent record, because data without it cannot be audited later.

The audit is also the fastest way to improve collection. Findings usually point to a few protocol changes, such as hardware triggering or a shared clock. A visible sync event like a clap at session start and end, per-session calibration, and logged conventions also help. Each change moves future sessions from the repair tier into the use-as-is tier.

How Digital Divide Data Can Help

Digital Divide Data works with Physical AI teams at the point where egocentric captures meet training pipelines. DDD’s sensor data annotation services combine automated checks, reviewer validation, and temporal consistency audits across synchronized video, IMU, and pose streams. Timing lag, convention errors, and implausible joints are flagged before labels are applied. Each session receives a documented outcome, so engineering teams know which data is ready, which needs correction, and which should be routed elsewhere.

When the audit shows that problems start at capture, DDD’s egocentric data collection services support protocol design, including sync events, per-session calibration steps, and metadata standards for coordinate conventions. For humanoid and manipulation programs, the same teams extend this work to joint pose labeling, task phase segmentation, and cross-sensor QA. DDD is platform agnostic and works within a client’s existing tools and formats.

Turn inconsistent egocentric captures into training data your models can trust. Talk to an Expert.

Conclusion

Inconsistent timing and coordinate systems rarely make egocentric data worthless by themselves. The real risk is uncertainty about how large the errors are and whether anyone has measured them. A short audit of clocks, frames, reprojection, and pose plausibility converts that uncertainty into numbers a team can act on.

Teams that audit early tend to scale collection with predictable yield and fewer retraining cycles. Teams that skip the audit usually discover misalignment through unexplained policy failures, long after the data has been labeled. 

References

Fan, Z., Dai, P., Su, Z., Gao, X., Lv, Z., Zhang, J., Du, T., Wang, G., & Zhang, Y. (2024). EMHI: A multimodal egocentric human motion dataset with HMD and body-worn IMUs. https://arxiv.org/pdf/2408.17168

Yoon, T., Han, Y., Ji, S., Park, J., Kim, S., Kwon, T., & Kim, H.-S. (2026). EgoXtreme: A dataset for robust object pose estimation in egocentric views under extreme conditions. https://arxiv.org/html/2603.25135

JoyAI-RA Team, Joy Future Academy, JD. (2026). JoyAI-RA 0.5: Scaling robot manipulation learning via dual action alignment. arXiv preprint arXiv:2608.05674. https://arxiv.org/pdf/2608.05674

Frequently Asked Questions

How much time offset between egocentric video and pose data is acceptable?

It depends on the task and how fast the hands move. A 20-millisecond offset at one meter per second misplaces a hand by about two centimeters. That may be fine for activity recognition and too much for grasp retargeting.

How to sync egocentric video and pose data recorded on different clocks?

Estimate the offset from the data itself using motion correlation, which compares angular velocity from the headset IMU or visual odometry with angular velocity from the pose stream. Measure it at the start, middle, and end of each session to catch drift or sudden jumps.

What is the quickest way to tell if my coordinate systems are wrong?

Run a few physical sanity checks first, including gravity direction at rest, stable bone lengths, valid rotations, and a floor at the declared height. Then project 3D keypoints onto video frames and measure reprojection error, because misaligned frames show up as keypoints that miss the hands.

Should we throw away egocentric clips that have bad pose data?

Often you can keep them. If the video and task labels are sound, those clips can still support representation or latent-action pretraining, as long as they are excluded from action targets. Discard only sessions with unknown clocks, missing calibration, or large unexplained jumps.
How to Evaluate Egocentric Video and Pose Data Usability When Timing and Coordinates Don’t Match Read Post »

Egocentric Data Collection

How to Design an Egocentric Data Collection Protocol for Robotics Programs

Udit Khanna

Egocentric data collection has a property that most robotics teams discover too late: protocol errors are permanent. An annotation mistake can be corrected in a second pass. A model architecture decision can be revisited at the next training run. But footage collected without synchronization signals cannot be synchronized afterward; scenes that were never sampled cannot be recovered from those that were; and consent that was not obtained at capture time cannot be applied retroactively without discarding the data. The collection protocol is the one component of an egocentric data program where the cost of getting it wrong is re-collection, not revision.

This blog covers the design of an egocentric collection protocol for robotics programs: hardware selection and its downstream consequences, diversity planning, task decomposition, demonstrator training, metadata that must be captured at collection time, privacy architecture, and the pilot collection run that validates the protocol before it scales.

Key Takeaways

  • Protocol errors are permanent in a way that annotation and modeling errors are not. Missing synchronization signals, unsampled scene types, and absent consent cannot be fixed after collection. The protocol deserves the same design rigor as the model architecture.
  • Hardware selection is a dataset design decision, not a procurement decision. The capture device determines which annotation types are possible downstream: gaze labels require eye tracking, finger-level manipulation labels require joint tracking, and scalable multi-site collection requires hardware that demonstrators can operate without specialist supervision.
  • Diversity must be planned as quotas before collection, not assessed as statistics after it. EgoVerse’s consortium study found that effective scaling depends on alignment between human data and robot learning objectives, and that domain-aligned diversity, not raw volume, drives transfer.
  • Metadata captured at collection time is the cheapest data in the program. Scene identifiers, hardware calibration records, demonstrator identifiers, task labels, and synchronization markers cost seconds to capture during recording and are expensive or impossible to reconstruct afterward.
  • A pilot collection run of a small fraction of the target volume, taken all the way through annotation and a probe training run, is the single highest-return step in protocol design. It surfaces protocol defects while they are still cheap to fix.

Why Protocol Design Determines Dataset Value

A useful way to evaluate an egocentric collection protocol is to ask what fraction of the collected hours will survive to become training data. In a well-designed protocol, that fraction is high: episodes are complete, streams are synchronized, metadata is attached, consent is documented, and the scene and task distribution matches what the training pipeline needs. In a weakly designed protocol, the collected volume looks impressive and the surviving fraction is low: episodes are discarded for missing calibration records, entire sessions are unusable because a firmware update changed the timestamp format mid-collection, and the scene distribution is discovered, after the fact, to be concentrated in whichever environments were most convenient to access.

In our experience reviewing collection programs, the difference between these two outcomes is rarely the collection team’s diligence. It is whether the protocol specified, in advance and in writing, what a valid episode consists of: which streams, at which rates, with which metadata, under which scene and task conditions, verified by which checks before the demonstrator moves to the next episode. A protocol that leaves these questions to session-time judgment produces a dataset whose quality varies with who was in the room.

Hardware Selection: The Decision That Constrains Everything Downstream

What Each Hardware Class Provides

Smart glasses with eye tracking, such as the Meta Project Aria glasses used in EgoMimic, provide RGB video (standard color camera footage), inertial measurement unit (IMU) motion data, and calibrated eye gaze, which makes gaze target annotation possible downstream. Headset-class devices such as Apple Vision Pro, used in EgoDex, add on-device hand tracking: SE(3) poses (positions and orientations in full 3D space) for 25 joints of both hands at 30 Hz, captured via the device’s own simultaneous localization and mapping (SLAM) system. This is what makes finger-level dexterous manipulation annotation feasible at scale without a motion capture studio. Custom head-mounted camera rigs, the approach behind Build AI’s Egocentric-1M, trade sensor richness for cost and durability, which is what made it possible to equip factory workers at the scale required to reach one million hours. Wrist-mounted cameras provide the closest view of hand-object contact but lose head-level gaze and wide scene context.

Selecting Against the Annotation Plan, Not the Spec Sheet

The correct selection procedure runs backward from the annotation schema. If the training pipeline requires gaze target labels, the hardware must capture calibrated eye tracking, and no post-processing can substitute for it. If the pipeline requires finger-joint ground truth, the hardware must track joints at capture time, because manual joint annotation of ordinary video is prohibitively expensive at production volume and markedly less accurate. If the program requires thousands of demonstrators across many sites, the hardware must be operable by a trained demonstrator without an engineer present, which rules out rigs that require per-session calibration by a specialist.

A practical consequence, visible in the EgoVerse design, is that large diverse programs often standardize on more than one hardware class: a rich-sensor device for the subset of tasks that need gaze and joint tracking, and a simpler, cheaper device for the volume and diversity of collection. The protocol must then specify how episodes from each hardware class are marked, because the downstream pipeline will treat them differently.

Diversity Planning: Quotas Before Volume

What the Evidence Says About Diversity Versus Scale

The EgoVerse consortium study, replicated across multiple labs, tasks, and robot embodiments, found that policy performance generally improves with more human data, but that effective scaling depends on alignment between the human data and the robot learning objectives. Volume collected in the wrong distribution does not convert to policy performance. The precedent for planned diversity goes back to Ego4D, which deliberately collected its more than 3,000 hours across 74 locations in 9 countries precisely because earlier egocentric datasets had been narrow in geography and demography, and that narrowness limited what models trained on them could generalize to.

Building the Coverage Matrix

Diversity planning operationalizes as a coverage matrix defined before collection: scene types crossed with task types crossed with object variations, with a target episode count in each cell. The matrix should be derived from the deployment target, not from convenience of collection. A program training household manipulation policies needs kitchens, bathrooms, and living spaces in realistic states of clutter, across multiple lighting conditions, with object instances that vary in size, material, and wear. A program training industrial policies needs the equivalent coverage of workstations, fixtures, and part variations.

An illustrative slice of such a matrix, for a household manipulation program, shows how deployment targets become collection quotas:

Scene type Grasp and place Open and close Pour and transfer
Kitchen, cluttered counter 30 episodes × 5 object variants 20 episodes × 4 container types 25 episodes × 4 vessel pairs
Kitchen, clear counter 20 episodes × 5 object variants 15 episodes × 4 container types 15 episodes × 4 vessel pairs
Bathroom shelf 20 episodes × 4 object variants 20 episodes × 3 cabinet types 10 episodes × 2 vessel pairs
Living space, low light 15 episodes × 4 object variants 10 episodes × 3 furniture types 10 episodes × 2 vessel pairs

Each cell is further split across demonstrators under the per-demonstrator caps described below, and the real matrix extends across every scene, lighting, and task condition in the deployment target.

Demonstrator diversity belongs in the matrix as well. Different demonstrators perform the same task with different hand sizes, motion styles, speeds, and strategies, and a policy trained on a single demonstrator’s style inherits that style’s idiosyncrasies as if they were task requirements. In our experience, programs that assign per-demonstrator episode caps per task, forcing the same task to be captured by many hands, produce measurably more robust policies than programs that let their fastest demonstrators dominate the collection.

Task Decomposition and Language at Capture Time

The task list is not a logistics artifact. It defines the supervision the dataset can provide. Tasks should be decomposed to the granularity the training pipeline will use: if policies will be trained on atomic skills such as grasp, place, open, and pour, the collection should capture clean episodes at that granularity, with defined start and end states, rather than long unsegmented activity streams that annotation must later cut apart. If the program targets long-horizon policies, the protocol should capture both the composed sequences and their atomic components, because both supervision levels will be needed.

Natural language task descriptions should be recorded at capture time, by the demonstrator or the session operator, in the phrasing that end users would actually use. Language-conditioned policies ground instructions in these descriptions, and descriptions written months later by annotators who did not perform the task are systematically flatter and less varied than descriptions captured in the moment. This is among the cheapest high-value data in the protocol: a spoken sentence per episode, recorded while the context is live.

Demonstrator Recruitment and Training

Demonstrators require training, and the training has a specific and somewhat counterintuitive goal: natural motion, not performative motion. Untrained demonstrators tend to perform for the camera, slowing down, exaggerating grasps, holding objects in view longer than natural task execution would. Policies trained on performative demonstrations learn performative behavior, which then looks hesitant and inefficient on the robot. Demonstrator training should therefore emphasize executing the task as if no camera were present, with the protocol’s quality checks catching the drift back toward performance.

The onboarding session should cover three things: device handling and calibration verification; the definition of a valid episode, including start state, end state, and what to do when a task attempt fails; and a supervised set of practice episodes reviewed against the protocol before the demonstrator’s data enters the production dataset.

Failed attempts deserve explicit protocol treatment: they should be captured and marked as failures rather than deleted, because failure episodes are among the most valuable and scarce training data in manipulation learning.

Metadata and Synchronization: Capture-Time or Never

Certain data can only be captured at collection time, and the protocol must enumerate it explicitly. Synchronization markers are what make multi-stream temporal alignment verifiable downstream: a clap, a flash, or a device-generated sync event at every episode start. Without them, alignment becomes an estimation problem with no ground truth. 

Calibration records determine whether spatial annotation downstream is trustworthy: camera intrinsics and extrinsics, device firmware versions, and eye tracking calibration results. Scene and session metadata rounds out the record: location identifier, lighting condition, object inventory, demonstrator identifier, and task label. Capturing these is seconds of effort during recording. Reconstructing them afterward is a project.

The protocol should treat metadata capture as a gating requirement: an episode without its metadata record is an invalid episode, checked at session end rather than discovered at annotation time. In our experience, the single most common source of discarded egocentric footage is not sensor failure. It is metadata that was deferred to later and never created.

Privacy and Consent Architecture

Egocentric capture records everything the demonstrator looks at, which includes bystanders, screens, documents, and identifying details of private spaces. Consent must be obtained from demonstrators and, where applicable, from the owners of collection environments, before recording, with the scope of use, including model training and potential dataset publication, stated explicitly.

Bystander handling must be designed into the protocol. Collection windows and locations should be chosen to minimize incidental capture, and a redaction stage (face and screen blurring at minimum) should sit in the pipeline before footage becomes broadly accessible to annotation teams.

Programs that defer privacy handling to a post-collection review consistently lose data to it, because footage with unconsented identifiable individuals in critical frames often cannot be salvaged by redaction without destroying the annotation value of those frames. Privacy architecture designed before collection is a yield decision as much as a compliance one.

The Pilot Collection Run: Validate Before You Scale

Before scaling to production volume, the protocol should be validated end to end with a pilot collection: a small fraction of the target volume, in our experience typically one to three percent, taken through the entire pipeline. That means collecting under the written protocol, running the full annotation schema on the pilot data, and training a probe model to confirm that the collected data actually supports the intended supervision. Each stage surfaces a different class of protocol defect: collection surfaces hardware and session-flow problems, annotation surfaces missing metadata and ambiguous episode boundaries, and the probe training run surfaces distribution and label-quality problems that neither of the first two stages can see.

The pilot ends with a protocol revision, and the revision should be treated as the expected outcome rather than a failure. Every large program’s published methodology reflects lessons that were cheap at pilot scale and would have been expensive at production scale. The discipline is refusing to scale until the pilot data has survived the full pipeline.

How Digital Divide Data Can Help

The principles above are straightforward to state and demanding to execute, which is where a specialist partner earns its place.

Digital Divide Data designs and operates egocentric collection programs where the protocol work is done before the first minute of footage is recorded, so that the collected hours survive to become training data instead of becoming an expensive archive.

That work runs upstream to downstream, from hardware and collection design through execution at scale. Physical AI data services cover this protocol and collection design layer, and data collection and curation operate the collection itself at production scale.

If a previous collection produced less usable data than its volume suggested, the audit almost always traces to one of the protocol elements above, and the fix belongs in the protocol, not in heroic post-processing. Talk to an expert.

Conclusion

Protocol errors are permanent in a way that annotation and modeling errors are not, which is why the five practices above earn the same design rigor as the model architecture itself.

The published datasets that robotics teams now benchmark against, EgoVerse, EgoDex, EgoMimic, and their successors, are protocol documents as much as they are data releases: every one of those practices is visible in how they were built. The question for a program planning its own collection is whether its protocol would survive the same scrutiny. For every hour it plans to collect, does the protocol specify what makes that hour usable?

References

Punamiya, R., Kareer, S., Liu, Z., Citron, J., Qiu, R.-Z., Cai, X., Gavryushin, A., Chen, J., Liconti, D., Zhu, L. Y., et al. (2026). EgoVerse: An egocentric human dataset for robot learning from around the world. arXiv. https://arxiv.org/abs/2604.07607

Hoque, R., Huang, P., Yoon, D. J., Sivapurapu, M., & Zhang, J. (2025). EgoDex: Learning dexterous manipulation from large-scale egocentric video. arXiv. https://arxiv.org/abs/2505.11709

Kareer, S., Patel, D., Punamiya, R., Mathur, P., Cheng, S., Wang, C., Hoffman, J., & Xu, D. (2024). EgoMimic: Scaling imitation learning via egocentric video. In Conference on Robot Learning (CoRL). https://arxiv.org/abs/2410.24221

Grauman, K., Westbury, A., Byrne, E., Chavis, Z., Furnari, A., Girdhar, R., Hamburger, J., Jiang, H., Liu, M., Liu, X., et al. (2022). Ego4D: Around the world in 3,000 hours of egocentric video. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR). https://arxiv.org/abs/2110.07058

Frequently Asked Questions

Q1. We have a limited budget and cannot afford Vision Pro or Aria units at scale. Does that rule out a serious egocentric program?

No, but it changes the design. The Egocentric-1M program reached one million hours on custom low-cost head-mounted cameras precisely because sensor richness was traded for scale and durability. The decision procedure is the same regardless of budget: run backward from the annotation schema. If the training pipeline does not require gaze targets or finger-joint ground truth, low-cost RGB head rigs with disciplined synchronization markers and metadata capture support a fully credible program. If a subset of tasks does require rich sensing, the mixed-fleet approach used by EgoVerse, a small number of rich-sensor devices for those tasks and inexpensive hardware for volume and diversity, delivers most of the capability at a fraction of the fleet cost.

Q2. How many hours should we plan to collect?

The honest answer is that the coverage matrix, not an hours target, is the right planning unit. The published evidence, including the EgoVerse consortium finding that scaling gains depend on alignment between the human data and the robot learning objectives, indicates that hours in the wrong distribution convert poorly to policy performance. The practical sequence is to define the coverage matrix from the deployment target, estimate episodes per cell from the task complexity, and let the hours total fall out of that calculation. Then validate with the pilot run: if the probe model trained on pilot data shows the expected learning signal, the matrix and the derived volume are credible; if it does not, more hours of the same distribution will not fix it.

Q3. Should we run collection in-house with our own team or distribute it across many demonstrators and sites?

The tradeoff is control versus diversity, and the deployment target should decide it. A small in-house team gives tight protocol control, fast iteration, and easy hardware management, at the cost of demonstrator and environment diversity, which the evidence consistently identifies as a driver of policy robustness. Distributed collection across many demonstrators and sites delivers the diversity but demands a protocol strong enough to survive operation by non-specialists: hardware that self-calibrates or verifies calibration automatically, session checklists that gate episode validity, and remote quality review with fast feedback to collectors. Most production programs converge on a hybrid: in-house collection to develop and stabilize the protocol, then distributed collection to scale diversity once the protocol has survived the pilot.

Q4. What synchronization approach should the protocol specify when devices cannot share a hardware clock?

The protocol should layer three mechanisms. First, a physical sync event at every episode start, a clap or a light flash visible or audible across streams, which creates a ground-truth alignment point that survives any clock behavior. Second, periodic timestamp logging against a common reference such as a network time source, which bounds drift within long sessions. Third, cross-correlation verification during the pilot run, confirming that streams which should show correlated signals at the same physical event actually do after alignment. The critical protocol rule is that the sync event is a gating requirement: an episode recorded without it is invalid at session end, not a problem deferred to the annotation team.

Q5. How do we know the protocol is ready to scale beyond the pilot?

Three checks, in order. First, yield: the fraction of pilot episodes that passed metadata, synchronization, and completeness gates should be high and the failure causes should be understood and fixed in the revised protocol, not explained away. Second, annotation viability: the full annotation schema should have run on the pilot data without discovering missing information that the protocol failed to capture, because any such gap will replicate across the entire production collection. Third, learning signal: a probe model trained on the annotated pilot data should show the expected supervision behavior on its target skills. When all three hold on the revised protocol, scaling is justified. When any one fails, scaling multiplies the defect by the size of the production run, which is the most expensive way to discover it.

How to Design an Egocentric Data Collection Protocol for Robotics Programs Read Post »

Sensor Synchronization for Egocentric Robotics Data: IMU, RGB, Depth, and Gaze Alignment

Sensor Synchronization for Egocentric Robotics Data: IMU, RGB, Depth, and Gaze Alignment

Udit Khanna

Every modern egocentric capture device is a federation of sensors running on their own schedules. Meta’s Project Aria research glasses combine RGB cameras (standard color video), monochrome scene cameras, inertial measurement units (IMUs, which measure acceleration and rotation), eye tracking cameras, microphones, and positioning sensors in a single wearable, each stream sampling at its own rate. Apple Vision Pro, the capture platform behind EgoDex, adds hand joint tracking at 30 Hz derived from its on-device simultaneous localization and mapping (SLAM) system. A typical egocentric robotics rig therefore produces four to eight concurrent time series whose scientific value depends entirely on a property none of them can guarantee alone: that a timestamp in one stream refers to the same physical instant as the identical timestamp in every other stream.

When that property fails, it fails silently. A dataset with a 40 millisecond offset between the gaze stream and the video stream contains no corrupted files, no missing frames, and no error messages. Every individual stream looks perfect. What it contains is a systematic lie about which object the demonstrator was looking at during every fast head movement in the collection, and the policy trained on it learns attention patterns that are consistently, confidently wrong. Synchronization errors are the only data quality failure that gets worse the better the rest of the pipeline is, because clean annotation applied to misaligned streams produces precise labels for events that did not co-occur.

This blog covers the mechanics: where desynchronization comes from, the hardware and software methods for preventing it, the verification techniques that prove alignment rather than assume it, and the capture-time logging that makes all of it auditable. It goes a level deeper than protocol design, into the specific failure modes and checks that apply per stream pair. Sensor data annotation and physical AI data services are the two capabilities most directly involved in operating this discipline at production scale.

Key Takeaways

  • Desynchronization is silent and systematic. Misaligned streams produce no errors and no corrupted files, only labels that are precisely wrong about which events co-occurred. It is the one data quality failure that clean annotation makes worse rather than better.
  • The error budget is stream-pair specific. Gaze-to-video alignment during fast head motion demands tighter tolerance than depth-to-video alignment in a slow scene. Setting one global tolerance either over-engineers cheap pairs or under-protects critical ones.
  • Clock architecture is a design decision, not a default. Shared hardware clocks, hardware trigger lines, network time protocols, and physical sync events form a hierarchy of guarantees, and the right choice depends on which streams share silicon and which cross device boundaries.
  • Verification means measurement, not inspection. Cross-correlation of physically coupled signals produces an empirical offset estimate with confidence bounds. Watching playback does not.
  • Drift makes synchronization a per-session property, not a per-device one. Independent clocks diverge over minutes to hours, so long recording sessions require drift measurement across the session, not a single alignment check at the start.

Where Desynchronization Actually Comes From

Clock Domains and Drift

Every sensor with its own oscillator keeps its own time, and consumer-grade oscillators drift relative to each other at rates that are trivial per second and material per session. Two independent clocks diverging at 20 parts per million accumulate 72 milliseconds of relative offset per hour, which at a 1000 Hz force sensor is 72 samples and at 30 Hz video is more than two frames. Devices that share a clock domain, sensors on the same board reading one oscillator, do not drift relative to each other; streams that cross a device boundary, an external tactile glove alongside head-mounted glasses, always do. Mapping which streams share clock domains is the first task of synchronization design, because it separates the pairs that are aligned by construction from the pairs that must be aligned by method.

Pipeline Latency and Timestamp Semantics

The second source is subtler: even with perfect clocks, a timestamp means different things in different streams. Some drivers stamp at exposure start, some at exposure end, some at readout, and some at software arrival after buffering, and the differences span tens of milliseconds. Gaze estimates carry processing latency between the eye image and the computed gaze vector. Compressed video streams buffer before writing. A synchronization design that treats all timestamps as equivalent inherits these semantic offsets as fixed biases, which is why documented timestamp semantics per stream (what event, in whose clock, stamped where in the pipeline) belong in every capture specification.

The useful property of pipeline latency is that it is a known bias. Once the per-stream latency is characterized and documented, it is subtracted analytically as a fixed correction before any verification runs, so that measurement only has to recover what remains. That yields a clean two-axis model for the whole problem: latency is the known bias you correct by arithmetic, and drift is the unknown, time-varying bias you must measure. A pipeline that conflates the two spends its measurement budget rediscovering constants it already logged.

Sampling Rate Mismatch

Streams at 30, 60, 100, and 1000 Hz never sample the same instant except by coincidence. This is not an error, but it forces an explicit decision that many pipelines make implicitly and inconsistently: how a label defined on one stream maps to the nearest samples of another, by nearest-neighbor assignment, by interpolation, or by windowed association. In our experience, the most common downstream defect in multi-rate egocentric datasets is not clock error at all, but inconsistent resampling conventions applied by different annotation tools on the same corpus.

The Synchronization Method Hierarchy

Level 1: Shared Hardware Clock

The strongest guarantee is sensors reading one clock. Integrated devices provide this within their own sensor suite, which is a genuine and underappreciated argument for integrated capture hardware over assembled rigs: the hardest synchronization problems are solved in silicon before collection begins. The limit is the device boundary; the moment a program adds an external sensor, it leaves Level 1 for that pair.

Level 2: Hardware Trigger and Timestamping

Where streams cross devices but the hardware supports it, a shared electrical trigger line or a common timestamping unit provides near-hardware alignment: a pulse that either drives simultaneous capture or is recorded by both devices as a common reference. This is standard practice in robot-mounted rigs where cameras and force-torque sensors expose trigger inputs, and it converts an unbounded drift problem into a bounded interpolation problem between trigger events.

Level 3: Network Time Protocols

Devices that share only a network can discipline their clocks to a common reference: Network Time Protocol (NTP) at millisecond-scale accuracy, or Precision Time Protocol (PTP) at sub-millisecond scale on supported hardware. Two numbers characterize what a protocol actually delivers, and they should not be conflated. Accuracy is the mean offset: how far the disciplined clock sits from the reference on average. Jitter is the variance of that offset from timestamp to timestamp. For label alignment, jitter is frequently the binding constraint, because a stable bias is a constant that one correction removes, while jitter scatters individual timestamps unpredictably and no per-session correction can undo it. 

This is also the honest form of the argument for hardware triggering over network discipline: triggers win less on mean accuracy than on jitter, because an electrical pulse does not wobble with network conditions. Protocol discipline bounds drift continuously, but both its accuracy and its jitter depend on network conditions and must be measured rather than assumed, which returns to the verification requirement below.

Level 4: Physical Sync Events

The universal fallback, and the mandatory floor for any protocol: a physical event visible or audible across streams at every episode start. The standard forms are a clap (which appears in audio, in video, and as an IMU spike) or a light flash visible to every camera. A physical sync event provides ground truth alignment that survives any clock behavior, firmware update, or driver quirk, and it costs two seconds per episode. Its absence is unrecoverable, which is why episode validity gates on its presence. The event also anchors post-hoc verification: it is the known co-occurrence against which computed alignments are checked.

Verification: Proving Alignment Instead of Assuming It

Cross-Correlation of Physically Coupled Signals

Streams that observe the same physics provide free verification signal. Head rotation appears simultaneously in the IMU gyroscope and as global optical flow in the video; a hand strike appears in audio, video, IMU, and any force sensor at the same physical instant; gaze saccades correlate with the head movements that accompany them. Computing the cross-correlation between such signal pairs across a recording yields the empirical time offset at which they align best. After the documented per-stream latency corrections have been applied, this measurement only has to recover the residual, which keeps the search window small and the estimate stable. Run per session and per stream pair, this converts synchronization from an assumption into a measurement, and its output (offset and confidence per pair per session) is the artifact a dataset can actually audit.

Three implementation details make the measurement operational rather than gestural. First, commensurability: an IMU gyroscope trace and video optical flow live in different units and rates, so the practical pairing correlates angular-rate magnitude against global flow magnitude, after resampling both to a common rate and band-pass filtering each to the shared band of natural head motion, which suppresses sensor noise below the band and rolling-shutter and compression artifacts above it. 

Second, sub-sample estimation: the true offset rarely lands on a sample boundary, so the standard cheap refinement is a parabolic fit through the correlation peak and its two neighbors, which recovers the offset at a fraction of a sample interval. Third, quantitative confidence: peak sharpness should be reported as a number, either the peak-to-sidelobe ratio or the correlation coefficient at the peak, with a minimum threshold below which the session’s alignment is treated as unverified rather than approximately fine.

Drift Measurement Across the Session

A single offset estimate at session start says nothing about session end. Repeating the correlation estimate in windows across the recording, or comparing physical sync events at episode boundaries, measures drift directly: a stable offset indicates a fixed bias that one correction removes, while a growing offset quantifies drift that requires time-varying correction. In our experience, a practical session gate is that residual misalignment after correction stays below half of the tightest sampling interval among the critical stream pairs, a threshold that keeps nearest-sample label assignment unambiguous; programs should calibrate the exact figure to their own error budget rather than adopt it as a standard.

The Per-Pair Error Budget

Not all misalignment is equally expensive, and the tolerance should follow the physics of the labels. Gaze-to-video alignment is the most demanding pair in most egocentric programs, because saccades complete in tens of milliseconds and a modest offset relocates the gaze target across object boundaries during exactly the head movements that matter. Contact labels shared between video and force or tactile streams are next, since contact transitions complete within a few high-rate samples. Depth-to-video and IMU-to-video tolerances can often be looser in slow-motion segments. Writing the budget down per pair, with the label types each pair supports, is what turns synchronization requirements from folklore into specification.

What to Log at Capture Time

Verification and correction are only as good as the records they run on. The capture specification should mandate, per session: device and firmware versions for every sensor, since firmware updates change timestamp behavior; both device timestamps and host arrival timestamps for every stream, preserving the raw material for offset analysis; the timestamp semantics declaration per stream; the measured per-stream pipeline latencies that will be applied as fixed corrections; the physical sync events with their per-stream detections; and the clock discipline configuration in effect. None of this is reconstructible afterward, and all of it is seconds of engineering per session. Sessions missing these records should fail intake before annotation, for the same reason unsynchronized episodes should: annotation effort spent on unverifiable alignment is annotation effort at risk.

If your annotation pipeline has ever adjudicated a disagreement about what the demonstrator was looking at, and the answer turned out to depend on which tool loaded the streams, the underlying issue is almost certainly synchronization, and it is measurable this week. Talk to an expert.

How Digital Divide Data Can Help

Digital Divide Data operates synchronization as a gate, not a hope: alignment is measured, corrected, and documented before a single label is applied.

For multi-modal egocentric programs, sensor data annotation begins with cross-correlation verification per stream pair per session, producing the offset and drift record that makes every downstream label auditable, and applies consistent resampling conventions so multi-rate labels mean the same thing across the entire corpus.

Upstream of that, physical AI data services build the synchronization architecture into the collection protocol itself: clock domain mapping, sync event design, timestamp semantics specification, and the capture-time logging that verification depends on.

And where the aligned streams feed video labels, video annotation teams work against the verified timeline, so gaze targets, contact events, and phase boundaries land on the frames where the physics actually happened.

If your program can state its per-pair error budget and produce last week’s drift measurements, this discipline is already in place. If it cannot, that is the gap. Talk to an expert.

Conclusion

Synchronization is the least visible layer of an egocentric data program and the one every other layer silently depends on. The discipline is not conceptually difficult: map the clock domains, choose the strongest feasible alignment method per stream pair, mandate physical sync events as the universal floor, correct the documented latencies analytically, verify the residual by measurement rather than inspection, track drift across sessions, and log the capture-time records that make all of it auditable. Each element is cheap at collection time and unrecoverable afterward.

The test of the discipline is not whether the streams look aligned in playback. It is whether the program can produce, for any session in the corpus, the measured offset, the residual after correction, and the drift profile, per stream pair. A dataset that can answer that question has synchronized data. A dataset that cannot has synchronized-looking data, and the difference is invisible until a policy trained on it meets the physical world.

References

Engel, J., Somasundaram, K., Goesele, M., Sun, A., Gamino, A., Turner, A., et al. (2023). Project Aria: A new tool for egocentric multi-modal AI research. arXiv. https://arxiv.org/abs/2308.13561

Hoque, R., Huang, P., Yoon, D. J., Sivapurapu, M., & Zhang, J. (2025). EgoDex: Learning dexterous manipulation from large-scale egocentric video. arXiv. https://arxiv.org/abs/2505.11709

Kareer, S., Patel, D., Punamiya, R., Mathur, P., Cheng, S., Wang, C., Hoffman, J., & Xu, D. (2024). EgoMimic: Scaling imitation learning via egocentric video. In Conference on Robot Learning (CoRL). https://arxiv.org/abs/2410.24221

Grauman, K., Westbury, A., Byrne, E., Chavis, Z., Furnari, A., Girdhar, R., Hamburger, J., Jiang, H., Liu, M., Liu, X., et al. (2022). Ego4D: Around the world in 3,000 hours of egocentric video. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR). https://arxiv.org/abs/2110.07058

Frequently Asked Questions

Q1. Our capture device is an integrated headset. Doesn’t the manufacturer handle synchronization for us?

Within the device, largely yes: sensors sharing the device’s clock domain are aligned by construction, which is a real advantage of integrated hardware. The guarantee ends at the device boundary. The moment a program records anything alongside the headset (a robot’s joint states, an external force sensor, a second camera, a tactile glove), that pair crosses clock domains and requires explicit alignment. Programs should also verify rather than assume the intra-device guarantee across firmware updates, since timestamp behavior is firmware-dependent, and confirm the timestamp semantics the device exposes, because exposure-time versus arrival-time stamping differs across streams even on integrated hardware.

Q2. We already recorded a large corpus without sync events. Is it unusable?

Not necessarily, but its alignment must now be estimated rather than anchored. Cross-correlation of physically coupled signals, such as IMU motion against optical flow or audio impacts against visual events, can recover offset estimates for many sessions, with confidence that varies by how much correlated activity each recording contains: sessions with vigorous motion align well, static sessions may not align at all. The honest workflow is triage: run correlation-based estimation across the corpus, retain sessions where the offset estimate is sharp and the residual meets the error budget, flag low-confidence sessions for restricted use, and add sync events to the protocol before the next collection run. Recovery is real but partial, which is exactly why the sync event is protocol-mandatory going forward.

Q3. What tolerance should we set for gaze-to-video alignment?

Derive it from the labels rather than adopting a universal number. The bounding physics: saccades complete in roughly 20 to 80 milliseconds, and during a fast head turn the gaze point can cross an object boundary in a similar window, so the tolerance question is how far a gaze target label can shift in time before it lands on the wrong object in your actual scenes. A defensible procedure is empirical: take representative episodes, artificially shift the gaze stream by candidate offsets, and measure at what shift the gaze-target annotation begins to change. In our experience that experiment typically motivates single-frame tolerance at 30 Hz for manipulation scenes with adjacent objects, but the point of the procedure is that your scenes, not a blog post, set your number.

Q4. Is Precision Time Protocol worth the hardware investment over NTP for a collection rig?

It depends on which stream pairs cross the network and what their error budget is. The comparison has two dimensions, and the second is the one that usually decides it. On accuracy, NTP typically disciplines clocks to within a few milliseconds under good conditions while PTP reaches sub-millisecond on supported hardware. On jitter, the timestamp-to-timestamp wobble of that offset, the gap between the approaches is wider, and jitter is what label alignment actually experiences, because a stable bias is removable by one correction while jitter is not removable at all. The decision procedure is the error budget: list the cross-network stream pairs, take the tightest tolerance among them, and compare it against measured NTP performance on your actual network, measuring both the mean offset and its variance rather than nominal figures. Many rigs land on a hybrid, hardware triggering for the high-rate pairs and NTP for the rest, which buys the guarantee where it matters without re-cabling the whole rig.

Q5. Who should own synchronization, the collection team or the annotation team?

Collection owns creating it; annotation owns refusing to work without proof of it. The mechanisms that make alignment possible, clock architecture, sync events, timestamp logging, exist only at capture time and belong in the collection protocol with episode validity gated on them. The verification artifact, measured offsets and drift per session, is the handoff document: annotation intake checks for it the way it checks for consent records, and sessions without it bounce back rather than entering the labeling queue. Programs that instead discover synchronization problems inside annotation tools resolve them tool by tool and annotator by annotator, which is how one corpus quietly acquires several incompatible alignments.

Sensor Synchronization for Egocentric Robotics Data: IMU, RGB, Depth, and Gaze Alignment Read Post »

Annotate Egocentric Video

How to Annotate Egocentric Video for Robot Manipulation

Udit Khanna

Collecting egocentric video for robot manipulation is now a largely solved problem. Consumer hardware, established capture protocols, and a fast-growing ecosystem of open datasets have made first-person footage the most accessible demonstration data source in robotics. Annotating it correctly is not solved, and that is where most programs lose the advantage they were trying to build. 

The reason annotation matters so much is that egocentric footage contains information that standard video annotation pipelines were not designed to extract. Hand-object contact state, gaze direction at the moment of action, precise 3D joint positions, and task phase transitions are all present in the data. They are available only as training signals if the annotation pipeline is configured to capture them. A standard object detection and action labeling pipeline applied to egocentric footage will produce correct labels that miss everything that makes the egocentric perspective valuable.

This blog covers the complete annotation stack for egocentric robot manipulation video: what labels are required at each level, what annotation quality standards apply, and what quality control processes distinguish annotation programs that produce a reliable policy-training signal from those that produce correctly formatted but misleading supervision. 

Key Takeaways

  • Egocentric video requires annotation at four levels: episode, segment, frame, and sensor stream. Annotation at one level cannot substitute for annotation at another, and missing any level produces a training set with systematic gaps.
  • Hand-object contact annotation is the most consequential label in manipulation video and the one most commonly done wrong. Contact onset and offset must be identified at the frame level, not the second level, and contact quality must be assessed, not just contact presence.
  • Gaze annotation is only meaningful when it identifies the fixation target, not just the gaze direction. A gaze direction vector that points at a cluttered scene tells the policy very little. A gaze target label that identifies the specific object or region the demonstrator was fixating on is what makes gaze information useful for policy learning.
  • Sensor stream synchronization must be verified before annotation begins. A contact label applied to a frame that is 50 milliseconds offset from the corresponding tactile or force reading produces a training signal that is systematically wrong at the most critical moments of a manipulation task.
  • Cross-embodiment annotation requires robot-agnostic task descriptions alongside robot-specific action data. EgoDex uses SE(3) annotations (poses in the special Euclidean group, capturing full 3D position and orientation) for 25 joints of both hands per frame as its joint-level ground truth; programs building datasets for cross-embodiment training should understand what their target format requires before annotation begins.

The Four Annotation Levels for Egocentric Manipulation Video

Level 1: Episode-Level Annotation

Episode-level annotation assigns labels to the entire recorded demonstration as a unit. The minimum required fields are task identity, task success or failure, a natural language task description, and collection metadata covering the hardware used, the scene configuration, and the demonstrator identifier. For programs training instruction-conditioned or language-conditioned policies, natural language task descriptions are a first-class annotation modality rather than optional metadata, and their quality, specifically whether they describe what the task accomplishes in the language that users will actually use, determines how well the policy learns language grounding.

Episode-level annotation also supports dataset balancing. Coverage metadata across scene type, object category, and task type is what enables the training pipeline to identify and address coverage gaps systematically rather than training on whatever distribution the collection produced by default.

Level 2: Segment-Level Annotation

Segment-level annotation divides an episode into labeled temporal segments corresponding to meaningful task phases. For manipulation tasks, the standard phase decomposition is approach, pre-grasp, grasp, transport, pre-place, place, and release. Each phase has different action requirements and different error modes, and a training pipeline that applies equal supervision weight to all phases will underweight the contact-rich phases where precision matters most.

Segment boundaries should be defined by the physical state of the task, specifically by changes in the contact state between the hand and the objects in the scene, rather than by visual heuristics such as hand speed or proximity. A segment boundary defined by contact state change is consistent across demonstrators and object types. A boundary defined by visual heuristics is demonstrator-specific and object-specific in ways that produce inconsistent training signal.

Level 3: Frame-Level Annotation

Frame-level annotation assigns labels to individual video frames, typically at the full capture rate or at a defined subsampling rate, depending on the task dynamics. The four label types required for manipulation policy training are: object state, tracking the position and manipulation status of each task-relevant object; end-effector state, recording gripper aperture and spatial relationship to the target; contact state, identifying whether contact is occurring and characterizing its quality; and task phase label at each frame, enabling phase-weighted training loss. EgoDex sets the current precision benchmark for this level of annotation: SE(3) poses for 25 joints of both hands at every frame, captured at 30 Hz via on-device simultaneous localization and mapping (SLAM) using multiple calibrated Apple Vision Pro cameras. Programs that need joint-level annotation at this precision for dexterous manipulation tasks should treat EgoDex’s annotation schema as the reference format.

Level 4: Sensor Stream Annotation

Modern egocentric capture rigs produce data streams beyond video: inertial measurement unit (IMU) data, eye gaze tracking, depth video, and, in precision setups, joint tracking. Sensor stream annotation assigns labels to these streams that synchronize with and extend the video annotation. The critical requirement is that synchronization is verified before annotation begins. A gaze target label applied to a gaze vector offset by 50 milliseconds from the corresponding video frame yields incorrect information about what the demonstrator was attending to at the moment of a critical manipulation event. At 30 Hz, 50 milliseconds is 1.5 frames. At 60 Hz, it is 3 frames. 

These offsets are small enough to be invisible in individual annotation reviews and large enough to corrupt the training signal for contact-rich tasks systematically. Synchronization verification therefore belongs at the start of the pipeline as a pre-annotation gate, confirming temporal alignment across all streams before any labeling begins, rather than as a correction applied after errors are discovered.

Hand-Object Contact Annotation: The Most Critical Label

Why Contact State Is Different From Contact Presence

Contact presence is a binary label: the hand is or is not touching an object. Contact state is a richer annotation that includes contact onset and offset at the frame level, the spatial location of contact on the object surface, the character of the contact (fingertip pinch, palmar wrap, or lateral pinch, for instance), and a quality assessment of whether the contact configuration is mechanically stable under the forces the subsequent task phase will apply.

The quality assessment is what most annotation programs skip and what causes the most policy failures. A grasp that passes the contact presence check but is rated as mechanically marginal because the object is held at the fingertip edge rather than centered will produce a training example that teaches the policy a grasp pattern that fails under any perturbation. In our experience running contact quality review at production scale, even a dataset where roughly one in ten grasps is mechanically marginal but labeled successful is enough to teach the policy to accept and reproduce that margin. The proportion is illustrative; the mechanism is not.

Annotation Protocol for Contact Quality

Contact quality assessment requires annotators with physical intuition about manipulation mechanics, not general-purpose video labelers. The annotation guidelines must specify, with examples, what a stable contact looks like for the specific object types in the dataset, what a marginal contact looks like, and what an unstable contact looks like. Calibration on a set of twenty to thirty representative examples before the main annotation pass establishes consistent application of these criteria across the annotation team. Inter-annotator agreement on contact quality for the calibration set, measured before production annotation begins, is the quality gate that determines whether the annotation process is ready to scale. 

In our experience, agreement below roughly 80 percent on contact quality labels for the calibration set is a signal that the guidelines need revision, not that the annotators need more practice. This threshold is a working heuristic drawn from production annotation programs rather than a published standard, and teams should calibrate it to the stakes of their specific task.

Gaze Annotation: Making the Target Explicit

Gaze direction data from a head-mounted eye tracker gives the angular direction of the demonstrator’s gaze at each frame. In a cluttered scene with multiple objects, this direction vector intersects with a region of the scene but does not identify which specific element within that region the demonstrator was fixating on. Annotating gaze direction without annotating gaze target produces data that tells the policy the demonstrator was looking somewhere in the vicinity of the action, which is far less informative than knowing they were specifically fixating on the handle of the mug rather than the mug body.

Gaze target annotation identifies the specific object, object part, or scene region that the demonstrator was attending to at each keyframe. This label is what enables gaze-conditioned policy learning, where the policy learns to attend to the same targets the demonstrator attended to at the same task phases. The most efficient annotation approach is to label gaze targets at keyframes corresponding to task phase transitions rather than at every video frame, and to propagate the label forward until the next keyframe where the gaze target changes. Without this target-level grounding, eye tracking data remains decorative sensor output rather than usable supervision.

Cross-Embodiment Annotation Requirements

Programs building egocentric datasets for cross-embodiment training face an additional annotation requirement that single-robot programs do not: the action representation must be robot-agnostic at the task description level while preserving robot-specific data at the control level. This two-level structure is what allows trajectories from human demonstrators wearing Apple Vision Pro to be co-trained with robot teleoperation data without requiring the training pipeline to reconcile incompatible action spaces.

The robot-agnostic layer consists of the natural language task description, the 3D spatial trajectory of the hand or end-effector in a world coordinate frame, and the contact state sequence. These are expressible in a coordinate system that is independent of the specific robot kinematics. The robot-specific layer consists of the joint angles and gripper commands that translate the spatial trajectory into commands for a specific robot embodiment. Annotating only the robot-specific layer locks the dataset to a single embodiment; adding the robot-agnostic layer is what opens it to co-training with egocentric human demonstration data.

How Digital Divide Data Can Help

Digital Divide Data builds egocentric annotation pipelines that extract the full training signal from first-person manipulation footage, not just correctly formatted labels.

Our annotation teams are trained specifically on egocentric manipulation video, with quality control designed to catch the failures that matter: mechanically marginal grasps labeled as successful, and gaze-direction labels that miss the actual fixation target. That covers the frame-level stack in full: contact state, gaze target, object state, and task phase, at production scale.

For multi-modal rigs, we handle synchronization verification and label integration across video, IMU, gaze, and joint-tracking streams, with temporal alignment confirmed as a pre-annotation gate rather than discovered after the dataset is built. And for programs starting from scratch, we work upstream of annotation itself: protocol design, hardware selection, and schema design that keeps collection and annotation aligned before either begins.

If your pipeline produces contact presence but not contact quality, gaze direction but not gaze target, or robot-specific action data without robot-agnostic task descriptions, the footage you have collected is worth more than the signal you are pulling from it. Talk to an expert.

Conclusion

The annotation stack for egocentric robot manipulation video is substantially more demanding than for standard manipulation video, and for good reason: the information that makes egocentric data valuable is precisely the information that standard annotation pipelines were not designed to capture. Contact quality, gaze target, sensor synchronization, and robot-agnostic task description are the labels that determine whether egocentric footage produces a policy that generalizes or one that merely passes the training loss.

Programs that collect egocentric video without building the annotation pipeline to match it are leaving the most important part of the data value on the table. What does your current egocentric annotation pipeline produce at the contact quality, gaze target, and sensor synchronization levels, and is that the complete annotation stack your training pipeline actually needs?

References

Kareer, S., Patel, D., Punamiya, R., Mathur, P., Cheng, S., Wang, C., Hoffman, J., & Xu, D. (2024). EgoMimic: Scaling imitation learning via egocentric video. In Conference on Robot Learning (CoRL). https://arxiv.org/abs/2410.24221

Hoque, R., Huang, P., Yoon, D. J., Sivapurapu, M., & Zhang, J. (2025). EgoDex: Learning dexterous manipulation from large-scale egocentric video. arXiv. https://arxiv.org/abs/2505.11709

Punamiya, R., Kareer, S., Liu, Z., Citron, J., Qiu, R., Cai, X., Gavryushin, A., Chen, J., Liconti, D., Zhu, L. Y., et al. (2026). EgoVerse: An egocentric human dataset for robot learning from around the world. arXiv. https://arxiv.org/abs/2604.07607

Frequently Asked Questions

Q1. Why does gaze annotation matter for robot manipulation policy training?

Gaze annotation tells the policy what the demonstrator was attending to at each moment of the task, which is information that the video frames alone do not reliably convey in cluttered scenes. At task phase transitions, where the demonstrator shifts from fixating on the approach target to fixating on the grasp point to fixating on the placement target, the gaze label captures the intended focus of attention that determines what the next action should be. Policies trained with gaze target labels learn to attend to the same task-relevant features at the same task phases as the demonstrator. Policies trained without gaze information must infer the relevant features from the action sequence alone, which produces weaker generalization to new object arrangements.

Q2. What frame rate should egocentric video be annotated at for manipulation tasks?

The annotation rate depends on the task dynamics. For slow, deliberate manipulation tasks like assembly or placement, annotating every fifth frame at 30 Hz, roughly six frames per second, captures phase transitions and contact events with adequate resolution. For fast, dynamic tasks like catching or rapid sequencing, full frame-rate annotation or at least every other frame is required to capture contact onset and offset accurately. The contact quality assessment should always be performed at the frame where contact is first established and at the frame where it ends, regardless of the general annotation rate, because these are the frames with the highest policy training value and the highest annotation error cost.

Q3. How do you handle occlusion in egocentric manipulation annotation?

Occlusion, where the demonstrator’s own hand or arm blocks the camera’s view of the object being manipulated, is the most frequent annotation challenge in egocentric footage. The standard approaches are: maintaining the last observed object state label until contact state changes, using depth video to infer 3D position when the color camera (RGB) view is occluded, and marking occluded frames with an occlusion flag that allows the training pipeline to apply reduced loss weight to those frames. Frames with complete occlusion of the primary task object during contact should be flagged rather than guessed, because a guessed label during contact is worse than a missing label.

Q4. How do you build an annotation calibration set for contact quality?

Select twenty to thirty episodes representing the full range of contact quality the dataset contains: clear examples of stable grasps across the object types in the collection, clear examples of mechanically marginal grasps at different stages of marginality, and clear examples of unstable contact that would fail under load. Have every annotator on the team label the calibration set independently, then measure inter-annotator agreement on the contact quality dimension specifically. The calibration review session should examine every disagreement on contact quality cases to determine whether the disagreement stems from guideline ambiguity, which requires guideline revision, or from annotator interpretation differences, which requires calibration discussion. The calibration set should be retained as a reference benchmark for ongoing quality monitoring throughout the annotation program.

Q5. What action representation format is required for cross-embodiment training with egocentric human data?

Cross-embodiment training requires a two-layer action representation. The robot-agnostic layer captures the 3D spatial trajectory of the hand or end-effector in a world coordinate frame, the contact state sequence, and the natural language task description. This layer can be aligned across human demonstrations and robot data from different embodiments. The robot-specific layer captures the joint angles and gripper commands that map the spatial trajectory to the specific robot. The Open X-Embodiment dataset established a widely adopted schema for the robot-specific layer. For the hand-level data from egocentric human demonstrations, EgoDex uses SE(3) annotations for 25 joints of both hands as the ground truth format. Programs building datasets intended for cross-embodiment training should decide on both layers before collection and annotation begin, because converting action representations after the fact is significantly more expensive than designing the annotation schema correctly upfront.

How to Annotate Egocentric Video for Robot Manipulation Read Post »

Egocentric Datasets

Why Egocentric Datasets are Becoming the New Standard for Training Robotics Models

Udit Khanna

Robot training data has a perspective problem. Most demonstration datasets are collected from fixed external cameras, ceiling rigs, or third-person views that watch the robot execute a task from outside. These perspectives are convenient to set up, but they produce a fundamental mismatch at deployment: the robot’s onboard camera is not mounted on the ceiling. It sees the world from the agent’s own position. 

A policy trained primarily on external perspectives must close a viewpoint gap at inference time that the training data did not address. Research on manipulation tasks has shown that adding an egocentric wrist-mounted view improves task success by more than 50 percent over third-person baselines on tasks requiring fine-grained spatial alignment. The field has absorbed this finding and is now moving fast.

Egocentric datasets, data collected from the point of view of the acting agent, are no longer a niche research track. A wave of large-scale releases in 2025 and 2026 has pushed egocentric human demonstration data into the mainstream of robot learning. The reason is both practical and principled: human egocentric video is far cheaper to collect than robot teleoperation data, covers a vastly larger range of tasks and environments, and when aligned correctly, transfers meaningfully to robot policy performance.

This blog covers the current state of egocentric datasets for robotics, what makes them effective, what alignment and annotation work they require, and what the data programs behind them actually look like in practice. Physical AI data services and video annotation services are the two capabilities most directly involved in building egocentric data programs that produce robot policies capable of generalizing beyond controlled collection environments.

Key Takeaways

  • Egocentric data captures the world from the perspective of the acting agent. This preserves the spatial, contact, and gaze signals that external cameras lose, and it matches the inference-time viewpoint of the deployed robot.
  • The performance evidence is now substantial. EgoMimic demonstrated 34 to 228 percent relative improvement in task score over state-of-the-art imitation learning baselines. EgoVerse showed up to 30 percent relative gains from co-training across multiple robots and tasks. EgoScale achieved a 54 percent improvement in average success rate over a no-pretraining baseline using over 20,854 hours of egocentric video.
  • Human egocentric demonstrations are cheaper to collect and faster to scale than robot teleoperation. A person wearing smart glasses can capture diverse manipulation tasks across real environments at a fraction of the cost and setup time required for a teleoperation rig.
  • Raw egocentric footage is not training-ready. Hand-object contact labels, gaze target annotation, task phase segmentation, and cross-embodiment action alignment are what convert first-person video into a usable supervision signal for a robot policy.
  • Dataset diversity drives generalization more than volume alone. The best-performing egocentric programs sample across environments, objects, lighting conditions, and demonstrators systematically rather than collecting large volumes in a narrow setting.

What Egocentric Data Is and Why It Matters for Robotics

The Viewpoint Mismatch Problem

A robot policy trained on external camera footage must solve two problems simultaneously at deployment: it must execute the task, and it must compensate for the viewpoint difference between the training data it learned from and the sensor stream it is actually receiving. This compensation is rarely explicit. It shows up as brittleness when the camera angle changes, when object positions shift relative to the robot’s own position, or when the spatial precision required by the task exceeds what the external viewpoint could reliably convey.

Egocentric data eliminates this mismatch by design. When the training data is collected from the same perspective the robot’s camera occupies at deployment, the policy learns spatial relationships, distances, and contact geometries in the coordinate frame it will actually use. This is not a marginal improvement in the conditions that matter most for contact-rich manipulation, precise insertion, delicate placement, and dexterous grasping. It is often the difference between a policy that generalizes and one that does not.

What Egocentric Data Captures That External Cameras Cannot

The information advantage of egocentric data goes beyond viewpoint alignment. Hand-object contact is clearer from the agent’s perspective because the hands are closer to the camera and less likely to be occluded by the robot’s own body. Gaze direction, where the demonstrator is looking at each moment, is only accessible from a head-mounted or wrist-mounted camera. Relative depth and proximity between the end-effector and a target object are more accurately represented from the robot’s own viewpoint than from a ceiling camera that may be meters away from the action.

These signals matter because they are what contact-rich manipulation tasks depend on. A policy that cannot accurately represent the spatial relationship between its gripper and a target during the approach phase will fail at grasp. A policy that cannot detect contact state from its own viewpoint will fail at placement. Video annotation services that are built specifically for egocentric footage, extracting hand-object contact, gaze, and proximity labels frame by frame, produce the supervision signals that make these capabilities learnable from human demonstration data.

The Current Landscape of Egocentric Datasets for Robotics

The Scale That Has Emerged in the Past 18 Months

The quantity and quality of publicly available egocentric datasets for robotics has changed dramatically since late 2024. EgoScale (Grauman et al., 2026) trained a VLA model on over 20,854 hours of action-labeled egocentric human video and demonstrated a log-linear scaling law between human data scale and validation loss, with that loss strongly correlating to downstream robot performance. This is the first published evidence of a scaling law connecting egocentric human data volume directly to robot policy quality.

EgoVerse, released in April 2026 by a consortium spanning Georgia Tech, Stanford, UC San Diego, ETH Zurich, MIT, and Meta Reality Labs, provides 1,362 hours of egocentric demonstrations across 1,965 tasks, 240 scenes, and 2,087 demonstrators from multiple countries. The dataset was designed explicitly for robot learning and validated through a multi-robot co-training study across multiple labs, with consistent gains of up to 30 percent relative improvement across different robot embodiments.

Apple’s EgoDex (Hoque et al., 2025) adds a precision layer that most large-scale datasets lack: 829 hours of egocentric video paired with 3D tracking of every joint of each finger at 30 Hz, captured via Apple Vision Pro across 194 tabletop manipulation tasks. The fine-grained hand pose annotation in EgoDex addresses the finger-level precision gap that earlier large-scale datasets did not cover.

What Makes Egocentric Data Work: Alignment and Annotation

The Embodiment Gap and How Data Programs Address It

Human hands and robot grippers do not move the same way. A human grasps an egg with compliant fingers that distribute force naturally. A robot gripper applies force through two rigid surfaces at fixed positions. An egocentric dataset that records human hand demonstrations without addressing this kinematic difference will produce a training signal that teaches the robot to imitate human hand shapes it cannot replicate.

Alignment techniques address this by mapping human hand trajectories to robot-executable action representations. This can be done through retargeting, which converts human hand poses to robot joint configurations, or through observation-space alignment, which finds shared representations between human and robot visual inputs. The specific approach depends on the robot hardware and task structure, but all of them require the annotation infrastructure to capture precise 3D hand pose data at the frame level before any alignment can be performed.

What Annotation Egocentric Data Requires

Frame-level annotation for egocentric robotics data is more demanding than for standard video datasets. At minimum, a training-ready egocentric episode requires: contact state labels identifying when and where the hand is making contact with an object; hand pose annotations capturing 3D joint positions across all fingers; task phase segmentation dividing the episode into approach, grasp, transport, place, and release phases; object state labels tracking what each manipulated object is doing at each timestep; and natural language task descriptions that connect the visual demonstration to instruction-conditioned policy architectures. 

Physical AI data services that are designed for egocentric collection rather than adapted from standard annotation pipelines produce this full annotation stack as a coordinated output rather than requiring separate annotation passes for each label type.

Sensor Synchronization Across Modalities

Modern egocentric capture rigs produce multiple simultaneous data streams: RGB video, IMU data, eye gaze tracking, depth, and, in precision setups like Apple Vision Pro, millimeter-accurate hand joint tracking. These streams run at different sampling rates and accumulate timing offsets that must be resolved before annotation begins. A contact label applied to a gaze sample that is 50 milliseconds offset from the corresponding visual frame produces a training signal that is systematically wrong about what the policy was attending to at the moment of contact. Sensor data annotation programs that include synchronization verification as a pre-annotation step, not a post-annotation correction, prevent this class of systematic error from propagating through the full dataset.

Collection Protocol Design for Egocentric Robotics Data

Why Diversity Planning Matters More Than Volume

The EgoScale finding of a log-linear scaling law between data volume and validation loss might suggest that collecting more data is always the right investment. What the same paper also demonstrates is that the diversity of the collection, across environments, objects, and demonstrators, determines how much of that scaling benefit transfers to robot deployment. A dataset of 20,000 hours collected in three environments by ten demonstrators will produce a policy with a much narrower generalization range than a dataset of the same size collected across hundreds of environments by thousands of demonstrators.

EgoVerse’s design reflects this. Its 1,362 hours span 240 distinct scenes and 2,087 demonstrators from multiple countries, not because those numbers were an arbitrary target but because the researchers found that domain-aligned data is crucial for effective scaling. A smaller, more diverse dataset consistently outperforms a larger, narrower one when the evaluation includes out-of-distribution tasks and environments. Data collection and curation services that build scene diversity, object diversity, and demonstrator diversity into the collection protocol from the start, rather than treating coverage as something to assess after the collection is complete, produce egocentric datasets with the generalization properties that deployment requires.

Hardware Selection and Its Impact on Data Quality

The hardware used for egocentric capture directly determines what information is available for annotation and what alignment techniques are applicable. Head-mounted cameras like Meta Project Aria provide eye gaze tracking alongside RGB video, making gaze-based annotation possible. Apple Vision Pro provides the most precise finger-joint tracking currently available in a consumer device, making fine-grained dexterous manipulation annotation feasible at scale. Wrist-mounted cameras provide a closer view of hand-object contact but lose head-level gaze information.

The choice is not purely a quality decision. It is also a scalability decision. Devices that require professional setup and controlled environments limit how many demonstrators can be recruited and how varied the collection environments can be. Consumer devices that a trained demonstrator can set up independently scale to orders of magnitude more collection capacity. The EgoVerse framework explicitly addressed this by supporting multiple hardware options so that the diversity of demonstrators and environments would not be constrained by hardware availability.

Privacy and Consent Built Into the Collection Process

Egocentric data, by definition, captures bystanders, workspaces, and environmental details that were not the intended focus of the collection. Programs that treat privacy review as a post-collection step consistently discover that a portion of their data is unusable because identifiable individuals or sensitive locations appear in footage that cannot be retroactively anonymized without destroying the annotation value. Consent protocols and bystander redaction need to be designed into the collection workflow before a single recording is made.

How Digital Divide Data Can Help

Digital Divide Data supports robotics teams building egocentric data programs at production scale, from collection protocol design through the full annotation stack. For programs designing egocentric collection protocols, physical AI data services cover hardware selection, diversity planning across scenes and demonstrators, consent and privacy workflow design, and the structured collection protocols that produce annotatable footage rather than raw video that requires substantial rework. 

For programs annotating collected egocentric episodes with the frame-level labels that robot policy training requires, video annotation services provide annotation teams trained specifically on egocentric manipulation footage, producing hand-object contact, gaze target, task phase, and object state labels at the quality and consistency that policy training demands. For programs handling the IMU, depth, and joint-tracking streams that modern egocentric rigs produce alongside video, sensor data annotation covers the multi-modal synchronization and labeling that makes the full sensor stack usable.

If your robotics data program is collecting third-person demonstrations and wondering why generalization to deployment environments is limited, the viewpoint gap is a likely contributor. Talk to an expert.

Conclusion

Egocentric datasets are becoming the standard input for serious robotics training programs because the evidence for their effectiveness has become too strong to ignore. A 54 percent improvement in success rate from large-scale egocentric pretraining, up to 30 percent relative gains from co-training with human demonstrations, and viewpoint alignment that closes the gap between training and deployment all point in the same direction: the agent’s own perspective is the right perspective to train from.

The data programs behind these results share a common structure. They plan for scene and demonstrator diversity before collection begins, build annotation pipelines specifically for egocentric footage rather than adapting general-purpose ones, and treat sensor synchronization as a prerequisite rather than an afterthought. If your team is collecting robot training data today, the question worth asking is whether your collection viewpoint matches the viewpoint your deployed policy will actually operate from.

References

Kareer, S., Patel, D., Punamiya, R., Mathur, P., Cheng, S., Wang, C., Hoffman, J., & Xu, D. (2024). EgoMimic: Scaling imitation learning via egocentric video. In Conference on Robot Learning (CoRL). https://arxiv.org/abs/2410.24221

Punamiya, R., Kareer, S., Liu, Z., Citron, J., Qiu, R., Cai, X., Gavryushin, A., Chen, J., Liconti, D., Zhu, L. Y., et al. (2026). EgoVerse: An egocentric human dataset for robot learning from around the world. arXiv. https://arxiv.org/abs/2604.07607

Hoque, R., Huang, P., Yoon, D. J., Sivapurapu, M., & Zhang, J. (2025). EgoDex: Learning dexterous manipulation from large-scale egocentric video. arXiv. https://arxiv.org/abs/2505.11709

Grauman, K., Westbury, A., Byrne, E., Chavis, Z., Furnari, A., Girdhar, R., Hamburger, J., Jiang, H., Liu, M., Liu, X., et al. (2022). Ego4D: Around the world in 3,000 hours of egocentric video. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR). https://arxiv.org/abs/2110.07058

Frequently Asked Questions

Q1. We already collect data from robot-mounted wrist cameras. Is that the same as egocentric data?

In viewpoint terms, yes: a wrist-mounted camera is egocentric because it captures the scene from the robot’s own perspective. Whether it functions as egocentric data in the sense that benefits policy training depends entirely on the annotation pipeline. Most wrist-camera programs apply standard object detection and success labeling without extracting hand-object contact state, gaze, or task phase labels specific to the egocentric perspective. Having first-person footage and having a pipeline that extracts what first-person footage uniquely provides are two different things. The question is not what camera you have. It is what your annotation pipeline does with it.

Q2. What is the embodiment gap and how do egocentric human datasets address it?

The embodiment gap is the kinematic and morphological difference between a human hand and a robot gripper. A human demonstration recorded from an egocentric perspective shows hand movements that a rigid-fingered robot cannot directly replicate. Egocentric datasets address this through alignment techniques that either retarget human hand poses to robot joint configurations or learn shared observation-space representations between human and robot visual inputs. The EgoMimic framework, for instance, uses cross-domain data alignment to co-train on human and robot data simultaneously so the policy learns to use the information in the human demonstrations without being constrained to replicate the exact hand shape.

Q3. How does a team decide between collecting egocentric human data and more robot teleoperation data?

The decision depends on what the data program needs. Robot teleoperation data is collected from the actual robot hardware, which means the action representation is directly usable and the embodiment gap is zero. It is also expensive, slow to scale, and limited to environments where the robot can be deployed for data collection. Egocentric human data is cheaper, faster to collect, and can cover environments and tasks that teleoperation cannot reach at reasonable cost. EgoScale’s finding that one additional hour of egocentric human data improves policy quality more than one additional hour of robot data, at scale, suggests the two are complementary rather than substitutable. The practical answer for most programs is to use egocentric human data to bootstrap new tasks and cover environmental diversity, and teleoperation to calibrate the final policy to the specific robot hardware.

Q4. What hardware is needed to collect egocentric robotics training data?

The options range from consumer devices to research-grade rigs, and the choice involves tradeoffs between data quality, scalability, and annotation capability. Meta Project Aria glasses provide eye gaze tracking alongside RGB video and were used in EgoMimic. Apple Vision Pro provides millimeter-accurate finger-joint tracking across 25 joints per hand, used in EgoDex and the Qwen-RobotManip training pipeline. Custom head-mounted rigs with action-labeled video, used in EgoScale, offer the most flexibility but the highest setup cost per demonstrator. Consumer wrist cameras and modified action cameras are the lowest barrier to entry and scale most easily to large numbers of demonstrators and environments. The EgoVerse framework supports multiple hardware types simultaneously specifically to avoid letting hardware availability constrain collection diversity.

Q5. What annotation is specifically required for egocentric data that standard video annotation does not provide?

Standard video annotation typically produces object detection boxes, action labels, and scene classification at the clip or episode level. Egocentric robotics annotation requires substantially more: frame-level hand-object contact state identifying when and where contact occurs; 3D hand poses tracking at the joint level, not just bounding box detection; task phase segmentation dividing the episode into manipulation-relevant stages; object state tracking recording what each manipulated object is doing at each frame; and natural language task descriptions tied to the specific episode content rather than generic action labels. Additionally, synchronization verification across multiple sensor streams, RGB video, IMU, depth, and gaze, must be confirmed before annotation begins to prevent systematic label offset errors.

Why Egocentric Datasets are Becoming the New Standard for Training Robotics Models Read Post »

Training Datasets for Robotic

How to Build Training Datasets for Robotic Manipulation: Demonstration Data, Annotation, and Quality Control

Robotic manipulation is one of the hardest data collection problems in machine learning. A language model trains on text that already exists in abundance on the internet. A vision model trains on images that can be scraped, filtered, and labeled at scale. A manipulation policy is trained on demonstration trajectories that must be collected physically, one episode at a time, in real environments or in carefully constructed simulations. The data does not exist until someone generates it, and generating it well requires decisions about hardware, collection protocol, scene diversity, and annotation standards that determine whether the resulting model generalizes or merely overfits to the collection setup.

The field is moving fast. Cross-embodiment datasets pooling trajectories across dozens of robot platforms and hundreds of task types have demonstrated that scale and diversity drive generalization in manipulation learning. The annotation standards and quality control processes that turn raw demonstration data into training-ready episodes, however, receive less attention than the collection infrastructure and the model architectures trained on the resulting data.

This blog covers what a production-grade manipulation dataset actually requires: how demonstration data is collected, what annotations need to be captured, and how quality control prevents the failures that only surface at deployment. Physical AI data services and video annotation services are the two capabilities most directly involved in building manipulation datasets that produce policies capable of generalizing beyond the collection environment.

Key Takeaways

  • Demonstration data for robotic manipulation must be collected physically or in high-fidelity simulation. The annotation and quality control standards applied to that data determine whether the resulting policy generalizes to deployment environments.
  • Episode-level annotation captures what a trajectory is trying to accomplish. Frame-level annotation captures the precise state of the robot and environment at each timestep. Both are required for manipulation policy training.
  • Task success is not a binary label in manipulation. Policies trained on coarse success labels learn behaviors that pass the label criteria but fail on the physical variation that deployment introduces.
  • Scene diversity and object diversity are as important as demonstration volume. A dataset of ten thousand demonstrations from five object types in one scene will produce a more brittle policy than a smaller dataset with genuine scene and object coverage.
  • Human-in-the-loop quality control is not optional for manipulating data. Annotators who cannot recognize whether a grasp is stable or a placement is physically viable will pass failures into the training set that automated filters cannot catch.

What Demonstration Data for Manipulation Requires

The Collection Problem

Demonstration data is collected by recording a robot or a human operator performing a manipulation task: picking an object, placing it in a target location, assembling components, or executing a multi-step task sequence. Each recorded episode captures the sequence of observations and actions that produced a successful or unsuccessful task execution. The policy trained on this data learns to reproduce the demonstrated behavior in new environments.

The quality of the resulting policy is directly determined by the quality and diversity of the demonstrations. Demonstrations collected in a single lab environment with a fixed set of objects produce policies that generalize poorly to new environments, new objects, and new lighting conditions. Demonstrations collected at scale across varied environments, object sets, and task configurations produce policies with the coverage required for deployment.

Teleoperation vs. Autonomous Collection

Most high-quality manipulation demonstration data is collected through teleoperation: a human operator controls the robot in real time to execute tasks, and the operator’s control inputs and the resulting robot states are recorded as the training data. Teleoperation produces high-quality demonstrations because a skilled operator can navigate the physical contingencies that arise in real environments, recover from near-failures, and complete tasks in ways that purely autonomous collection cannot replicate.

The annotation burden for teleoperated demonstrations differs from autonomous collection. Teleoperated episodes need annotation that captures the operator’s intent at each stage of the task, the task completion status at the episode level, and the quality of the physical execution at the frame level. Data collection and curation services that include structured teleoperation protocols alongside the annotation pipeline produce demonstration datasets where the collection and annotation stages are designed together rather than sequenced independently.

Episode-Level and Frame-Level Annotation

What Episode-Level Annotation Captures

Episode-level annotation assigns labels to each recorded demonstration as a complete unit. The minimum required fields are task identity, task success or failure, and a brief description of what the episode was attempting to accomplish. For manipulation policies trained on language-conditioned or instruction-following architectures, natural language task descriptions are a required component of every episode annotation, not an optional enrichment.

Episode-level annotation also captures metadata about the collection context: the scene configuration, the object set used, the robot platform, and any environmental conditions that vary across the collection. This metadata is what allows the training pipeline to balance the dataset across scene types, object categories, and task types rather than training on whatever distribution the collection produced by default.

What Frame-Level Annotation Captures

Frame-level annotation assigns labels to individual timesteps within an episode. For manipulation tasks, the critical frame-level labels are object state, end-effector state, contact state, and task phase. Object state captures whether an object is grasped, in motion, or at rest, and in what configuration. End-effector state captures gripper aperture, contact forces where available, and the spatial relationship between the end-effector and the target object or surface.

A frame-level annotation record for a single timestep typically looks something like this in practice:

{“timestep”: 142, “object_state”: {“id”: “mug_03”, “status”: “grasped”, “pose”: [x, y, z, qx, qy, qz, qw]}, “end_effector_state”: {“gripper_aperture”: 0.018, “contact_force”: [0.4, 0.1, 2.3], “distance_to_target”: 0.002}, “contact_state”: “stable_contact”, “task_phase”: “transport”}

Each field maps to a specific training signal. The object_state.status field, which moves from approaching to grasped to released across an episode, is what lets a model learn the discrete state transitions a task moves through. The contact_force vector inside end_effector_state is what distinguishes a firm, centered grasp from one that is barely holding the object, a distinction that a binary success label cannot make. The task_phase field is the value that drives the phase-weighted loss described below: a training pipeline can assign higher loss weight to frames labeled grasp or place than to frames labeled transport, because errors during contact-rich phases are more consequential than errors during free-space movement.

Task phase annotation divides an episode into labeled stages: approach, grasp, transport, place, and release. Phase labels are what allow the training pipeline to apply different loss weighting to different stages of the task, which matters because the failure modes associated with the approach are different from those associated with grasp, and a model that weights all phases equally will underfit the phases where precision is highest.

Fine-grained frame-level annotation requires annotators who understand the physical mechanics of the manipulation task being annotated. An annotator who cannot distinguish a stable grasp from a marginal one will label marginal grasps as successful, introducing systematic failures into the training set at exactly the points where the policy needs the most reliable supervision signal. Video annotation services that include domain expertise in robotic manipulation mechanics produce frame-level annotations that reflect the physical realities of the task rather than surface-level pattern matching on the visual appearance of the episode.

Quality Control for Manipulation Datasets

Why Automated Filters Are Not Enough

Automated quality control for manipulating data can filter obvious failures: episodes with missing sensor modalities, episodes that end before the task window closes, and episodes with out-of-range sensor readings. What automated filters cannot catch is the physically marginal case: a grasp that looks successful in the video but is held with a contact configuration that would drop the object under any perturbation, a placement that appears to reach the target but is not mechanically stable, a task completion that passes the binary label criteria but executes in a way that will not generalize to slightly different object weights or surface textures.

These marginal cases are the ones that cause policies to fail at deployment. A policy trained on a dataset where ten percent of ‘successful’ demonstrations are physically marginal will learn a behavior that reproduces that margin. In deployment, where the physical environment is not a controlled collection setup, the marginal behavior fails consistently.

Human-in-the-Loop Review for Physical Validity

Human quality review for manipulating data requires annotators with physical intuition about the tasks being reviewed. The reviewer needs to be able to watch a manipulation episode and identify whether the grasp is stable, whether the object placement is physically viable, whether the robot’s approach trajectory would generalize to a slightly different object position, and whether the task completion would survive the perturbations the deployment environment will introduce.

This is a fundamentally different skill requirement from text annotation or image classification. It requires annotators who have either direct experience with robotic manipulation or strong physical intuition developed through adjacent domains. Review teams staffed with general-purpose annotators produce quality control that catches visual anomalies but passes physical failures.

Dataset Balance and Coverage Auditing

A manipulation dataset can pass individual episode quality checks while still being unbalanced in ways that produce brittle policies. If ninety percent of demonstrations use objects of similar weight, size, and texture, the policy learns a manipulation behavior calibrated to that distribution. Object diversity at the dataset level requires deliberate coverage auditing: checking that the final dataset includes adequate representation across object categories, size ranges, texture types, and scene configurations before training begins. Data collection and curation services that include dataset-level coverage auditing as a standard component of the curation process produce training datasets with the balance that generalizable manipulation policies require.

How Digital Divide Data Can Help

Digital Divide Data supports robotics teams building manipulation training datasets across the full data pipeline, from collection protocol design through annotation and quality control. For programs collecting teleoperation demonstration data, physical AI data services cover collection protocol design, scene and object diversity planning, and the structured teleoperation workflows that produce demonstrations with consistent annotation coverage across task phases. 

For programs annotating collected manipulation episodes, video annotation services provide domain-aware annotation teams capable of applying frame-level labels for object state, end-effector state, contact state, and task phase, with quality control processes designed to catch physically marginal demonstrations rather than only visual failures. For programs evaluating whether collected datasets produce the policy generalization their deployment requires, model evaluation services design evaluation frameworks built around the deployment environment rather than the collection environment.

If your manipulation dataset collection program does not have annotation standards and quality control processes designed for physical validity, the policy failures at deployment will trace back to the dataset. Talk to an expert.

Conclusion

Manipulation of the dataset quality is determined at collection and annotation, not at training. The diversity decisions made during collection, the annotation standards applied to each episode and frame, and the quality control processes that distinguish physically valid demonstrations from marginal ones are what separate training datasets that produce generalizable policies from those that produce policies that work in the lab and fail in deployment.

The field has demonstrated that scale and diversity drive generalization in manipulation learning. Building datasets with the scale and diversity that generalization requires means treating collection, annotation, and quality control as an integrated program rather than three sequential steps.

Before your next collection run, it is worth checking your pipeline against four specific questions: 

  1. Does every episode carry frame-level labels for object state, end-effector state, contact state, and task phase, or only episode-level success and failure? 
  2. Has anyone audited your dataset’s scene and object distribution against your actual deployment targets, or only against what was convenient to collect? 
  3. Are your human reviewers screening for physically marginal grasps and placements, or only for visually obvious failures? 
  4. And if you are building toward cross-embodiment training, is your action schema aligned to a shared standard now, before conversion becomes the expensive afterthought it always becomes later? 

A pipeline that cannot answer all four with a clear yes has a specific, fixable gap rather than a vague data quality problem.

References

Khazatsky, A., Pertsch, K., Nair, S., Balakrishna, A., Dasari, S., Karamcheti, S., Nasiriany, S., Srirama, M. K., Chen, L. Y., Ellis, K., et al. (2024). DROID: A large-scale in-the-wild robot manipulation dataset. arXiv:2403.12945. https://arxiv.org/abs/2403.12945

O’Neill, A., Rehman, A., Maddukuri, A., Gupta, A., Padalkar, A., Lee, A., Pooley, A., Gupta, A., Mandlekar, A., Jain, A., et al. (2024). Open X-Embodiment: Robotic learning datasets and RT-X models. In the IEEE International Conference on Robotics and Automation. https://arxiv.org/abs/2310.08864

Belkhale, S., Cui, Y., & Sadigh, D. (2023). Data quality in imitation learning. In Advances in Neural Information Processing Systems, 36. https://arxiv.org/abs/2306.02437

Black, K., Brown, N., Driess, D., Esmail, A., Equi, M., Finn, C., Fusai, N., Groom, L., Hausman, K., Ichter, B., et al. (2024). π0: A vision-language-action flow model for general robot control. arXiv:2410.24164. https://arxiv.org/abs/2410.24164

Frequently Asked Questions

Q1. How many demonstration episodes does a manipulation policy need to generalize reliably?

There is no universal number because the required volume depends on task complexity, scene diversity, and object diversity. A policy trained on a narrow task with limited object variation can generalize adequately with hundreds of demonstrations. A policy intended to generalize across many object types, scene configurations, and task variations needs thousands of diverse demonstrations. Cross-embodiment datasets have shown that diversity drives generalization more reliably than raw volume. A smaller dataset with genuine coverage across scene types and object categories will typically produce a more capable policy than a larger dataset with narrow coverage.

Q2. What is the difference between episode-level and frame-level annotation, and when is each required?

Episode-level annotation labels the demonstration as a whole: task identity, success or failure, natural language task description, and collection metadata. Frame-level annotation labels individual timesteps: object state, end-effector state, contact state, and task phase. Episode-level annotation is required for all manipulation datasets. Frame-level annotation is required for policies trained with dense supervision signals, such as those using imitation learning with phase-weighted loss, or for policies trained on instruction-following architectures where the relationship between natural language commands and physical states needs to be captured at a fine-grained level.

Q3. How do you identify physically marginal demonstrations during quality control?

Physically marginal demonstrations require reviewers with physical intuition about the manipulation task. The indicators include grasps where the object is held at the edge of the gripper contact surface rather than centered, placements where the object is technically at the target but in a mechanically unstable configuration, approach trajectories that would require unusually precise alignment to replicate, and task completions that depend on specific surface friction properties. Automated filters that check for sensor completeness and episode duration will not catch these. Human review by annotators familiar with manipulation mechanics is the only reliable method.

Q4. How should object and scene diversity be planned before collection begins?

Define the object categories, size ranges, texture types, and weight classes that the policy needs to handle in deployment. Design the collection protocol to sample deliberately across those dimensions rather than collecting whatever is convenient. For scene diversity, identify the surface types, lighting conditions, and environmental configurations that the deployment context will include and ensure each is represented in the collection. Audit the dataset against these coverage specifications before training begins, not after. Discovering coverage gaps after training requires collecting more data, which is expensive. Discovering them before training allows the collection protocol to be adjusted.

Q5. What annotation format is required for cross-embodiment training?

Cross-embodiment training requires annotation that captures robot-agnostic task descriptions alongside robot-specific action and state data. The task description must be in natural language and describe what the episode accomplishes rather than how the specific robot executed it. The action and state data must be formatted in a standard schema that allows trajectories from different robot platforms to be combined in the same training batch.

How to Build Training Datasets for Robotic Manipulation: Demonstration Data, Annotation, and Quality Control Read Post »

Evaluate VLA Model

How to Evaluate VLA Model for Real-World Deployment: Grounding, Planning, and Action Fidelity

Kevin Sahotsky

Here’s a question I get from robotics and physical AI teams more often than I used to: we have a VLA model that looks impressive in the demo, how do we know if it will actually hold up once it leaves the lab? It’s a fair question, and the honest answer is that most teams do not have a good way to answer it yet. The benchmarks the model was trained and reported against often measure something narrower than what deployment actually requires.

Vision-Language-Action models are being evaluated in the way earlier generations of computer vision models were evaluated: a held-out test set, a success rate, and a leaderboard position. That approach tells you how the model performs on a distribution similar to its training data. It tells you very little about whether the model will ground a spoken instruction correctly in a cluttered warehouse, plan a multi-step task when the first attempt fails, or execute an action with the physical fidelity that a real task requires. This is particularly relevant for robotics program leads, physical AI product teams, and operations leaders evaluating whether a VLA model is ready to move from a controlled pilot into a live deployment.

This blog walks through the three capabilities that actually determine whether a VLA model is deployment-ready: grounding, planning, and action fidelity, and what evaluating each of them looks like in practice. Model evaluation services and video annotation services are the two capabilities most directly involved in building VLA evaluation programs that predict real-world performance rather than benchmark performance.

Key Takeaways

  • Standard VLA benchmarks measure performance on a distribution similar to the training data. They do not reliably predict performance in a specific deployment environment with its own object sets, lighting, and task variations.
  • Grounding, planning, and action fidelity are three distinct capabilities that fail independently. A model can ground language well and still fail at multi-step planning, or plan well and still execute with poor physical fidelity.
  • Out-of-distribution evaluation, testing on object placements, lighting, and task variations the model has not seen, is a better predictor of deployment performance than in-distribution benchmark scores.
  • Action fidelity cannot be assessed from success rate alone. Two policies with the same success rate can have very different margins for error, and that margin is what determines reliability at scale.
  • A model evaluation program built around your specific deployment task taxonomy will catch failure modes that a general VLA leaderboard never surfaces.

Why Standard Benchmarks Undersell the Real Question

What Leaderboard Scores Actually Measure

Most published VLA benchmarks evaluate models on tasks and environments that are either simulated or closely matched to the training distribution. A model can score well on these benchmarks because the test conditions are similar enough to what it has already seen. That is a legitimate measure of in-distribution capability. It is not a measure of whether the model will work in your warehouse, your kitchen, or your assembly line, where the objects, the lighting, and the task variations will not match the benchmark distribution.

This gap matters more for physical AI than it did for earlier generations of language or vision models, because the cost of a wrong answer is physical. A chatbot that gives an unhelpful response is an inconvenience. A robot that misjudges a grasp or executes the wrong action in a live environment is a safety and operational problem.

Out-of-Distribution Performance Is the Real Signal

Recent benchmarking work in the field has made a point that matters here: models trained primarily on action data can transfer reasonably well to environments that resemble their training distribution, but performance drops sharply when visual conditions or task mechanics shift outside that distribution. That is the gap that matters for deployment. If your environment, your object set, or your task structure differs meaningfully from what the model was trained on, the benchmark score tells you very little about what will happen in production.

The practical implication is that evaluation needs to be built around your specific deployment context, not borrowed wholesale from a published leaderboard. A model that ranks well on a general benchmark may still fail consistently on the specific variations your environment introduces.

Grounding: Does the Model Understand What You Are Asking?

What Grounding Failures Look Like

Grounding is the model’s ability to connect a language instruction to the correct object, location, or action in its visual field. A grounding failure looks like the model picking up the wrong object when two similar items are present, or misinterpreting a spatial reference like “the one on the left” when the scene has shifted from how it appeared in training.

Grounding failures are often invisible in simple test environments because there is only one plausible object or location for the model to act on. They become visible the moment you add visual clutter, similar-looking objects, or ambiguous spatial language, which is exactly what real environments contain in abundance.

The business cost of a grounding failure shows up as rework and damaged trust rather than a single dramatic incident. A model that picks up the wrong part on an assembly line creates a defect that gets caught downstream, at a higher cost than catching it at the source. A model that misreads a spatial instruction in a fulfillment center sends the wrong item, which becomes a customer-facing SLA breach and a return to process. Multiply a small grounding error rate by daily production volume, and the cost stops looking small.

Evaluating Grounding Under Realistic Ambiguity

A grounding evaluation needs deliberately ambiguous scenes: multiple objects of similar type, instructions that require spatial or relational reasoning, and language phrasings that vary from the canonical form the model may have been trained on. Video annotation services that label ground-truth object references and spatial relationships in evaluation footage give you the basis for scoring whether the model’s grounding matches what a human would understand the instruction to mean, rather than just whether the model picked up some object.

Planning: Does the Model Handle Multi-Step Tasks and Recover From Failure?

Single-Step Success Hides Planning Weakness

Many real tasks require a sequence of actions, and a model can execute each action competently while still failing at the task because it does not sequence them correctly, does not recognize when an earlier step failed, or cannot adapt the plan when the environment does not match its expectation. A model evaluated only on isolated single-step actions will look far more capable than it will behave in a multi-step task.

Hierarchical approaches that separate high-level planning from low-level execution have shown that grounding ambiguous instructions and adapting plans dynamically remains one of the harder open problems in the field. That should inform how much weight you put on a model’s single-step benchmark score relative to its actual planning behavior.

Planning failures are typically what cause unplanned downtime, not a single bad action. A robot that cannot recognize a failed step will either stall and wait for human intervention, which stops the line, or continue executing a plan built on a false assumption, which can damage product or equipment before anyone notices. Both outcomes carry a direct cost in lost throughput, and the second carries an added repair or scrap cost on top of it.

Designing an Evaluation for Recovery Behavior

Planning evaluation should deliberately introduce failure points: an object that is not where the model expects it, a step that cannot be completed on the first attempt, or a change in the environment mid-task. The question is not whether the model can execute a clean multi-step task when everything goes as expected. It is whether the model notices when something has gone wrong and adapts rather than continuing to execute a plan based on a stale assumption.

Action Fidelity: How Precisely Does the Model Execute?

Why Success Rate Alone Is Not Enough

Two policies can report the same success rate on a benchmark while having very different margins for error. One policy might complete a grasp with a wide, stable margin every time. Another might complete the same grasp at the edge of what is mechanically possible, succeeding in the test conditions but failing the moment an object’s weight, texture, or position shifts slightly. Success rate does not distinguish between these two cases, and that distinction is exactly what determines whether a model is reliable at production scale.

Action fidelity evaluation requires looking past the binary success label to the quality of the execution itself: trajectory smoothness, contact stability, and how close the action came to the failure boundary, even when it technically succeeded.

A narrow action fidelity margin is the kind of risk that does not show up until volume increases or conditions drift slightly, and then it shows up as a safety incident or an equipment damage claim rather than a quality metric. A grasp that succeeds at the edge of mechanical stability in a pilot of fifty units can fail consistently at a production volume of five thousand, once object weight or surface friction varies even slightly from the pilot batch. That is the gap between a model that looked ready in evaluation and one that was not.

Building Action Fidelity Into the Evaluation Protocol

This requires frame-level review of execution quality, not just episode-level success labels. Model evaluation services that score action fidelity on dimensions like grasp stability margin and trajectory precision, not just task completion, surface the difference between a model that succeeds reliably and one that succeeds narrowly.

Building an Evaluation Program Around Your Deployment, Not the Leaderboard

The most useful thing you can do before deploying a VLA model is to define your own task taxonomy: the specific objects, environments, instruction phrasings, and failure scenarios your deployment will actually involve. Then evaluate the model against that taxonomy directly, rather than relying on how it ranks on a general benchmark.

This is not a one-time gate before launch. Models get updated, deployment environments evolve, and new task variations show up that your original evaluation set did not anticipate. Data collection and curation services that continuously sample new deployment scenarios into your evaluation set keep the evaluation program honest as the deployment context changes.

Signs Your Current Evaluation Is Not Enough, and Whether to Build or Buy

Not every team is at the same starting point, and it is worth being honest about where you actually are before investing further. A few signs your current evaluation program is not enough: your only performance number comes from a published benchmark or the model provider’s own reported metrics; you have never tested the model against object types, lighting, or instruction phrasings specific to your facility; your evaluation set has not changed since the pilot, even though your deployment environment has; or you are relying on field incident reports, rather than a structured evaluation process, to tell you when something is wrong.

If two or more of these are true, the question becomes whether to build this evaluation capability in-house or bring in a partner to run it. Building in-house makes sense if you already have ML engineers who understand evaluation design, your deployment environment is stable enough that a one-time investment in tooling will keep paying off, and you have the headcount to maintain the evaluation set as conditions change. Buying makes sense if your team’s strength is in the application and the robotics integration rather than in evaluation methodology, if your deployment environment is still evolving and the evaluation set will need frequent updates, or if you need this running before your next deployment milestone and do not have the lead time to build the capability from scratch. Most teams that choose to buy are not outsourcing judgment; they are outsourcing the ongoing labor of keeping an evaluation set current, which is the part that erodes fastest when left to a part-time internal owner.

How Digital Divide Data Can Help

Digital Divide Data supports robotics and physical AI teams building VLA evaluation programs that are grounded in the specific environments and tasks those models will face. For programs designing grounding and action fidelity evaluations, model evaluation services build evaluation frameworks around your deployment task taxonomy, with scoring dimensions that go beyond binary success rate to capture execution quality and failure margins. 

For programs that need labeled ground truth for grounding and planning evaluation, video annotation services provide annotation of object references, spatial relationships, and task phase structure in evaluation footage. For programs that need to keep their evaluation sets current as deployment environments evolve, data collection and curation services continuously source new evaluation scenarios from the field rather than relying on a static benchmark.

If your VLA evaluation program is built around a published benchmark rather than your actual deployment task taxonomy, you will not see the failure modes that matter until they show up in production. Talk to an expert.

Conclusion

A VLA model that looks strong on a published benchmark can still fail in your specific deployment, because the benchmark was never designed to predict performance in your environment. Grounding, planning, and action fidelity are three distinct capabilities that each fail in their own way, and a benchmark score that averages across all three will hide exactly the failure you need to catch before deployment.

The teams that get this right build their own evaluation taxonomy around the objects, environments, and task variations their deployment will actually involve, and they keep updating it as conditions change. What does your current VLA evaluation actually tell you about how the model will behave in your specific environment, not a benchmark’s?

References

Guruprasad, P., Wang, Y., et al. (2025). Benchmarking the generality of vision-language-action models. https://arxiv.org/abs/2512.11315

Li, X., Hsu, K., Gu, J., Pertsch, K., Mees, O., Walke, H. R., Fu, C., Lunawat, I., Sieh, I., Kirmani, S., et al. (2024). Evaluating real-world robot manipulation policies in simulation. arXiv. https://arxiv.org/abs/2405.05941

Zhou, J., Ye, K., Liu, J., Ma, T., Wang, Z., Qiu, R., Lin, K., Zhao, Z., & Liang, J. (2025). Exploring the limits of vision-language-action manipulations in cross-task generalization. arXiv. https://arxiv.org/abs/2505.15660

Frequently Asked Questions

Q1. How is evaluating a VLA model different from evaluating a standard computer vision model?

A vision model is typically evaluated on a single capability, like classification or detection accuracy, against a static test set. A VLA model has to be evaluated across three interacting capabilities at once: whether it understands the instruction, whether it plans the right sequence of actions, and whether it executes those actions with enough physical precision to succeed. A model can be strong in one of these and weak in another, and a single aggregate success rate will not tell you which one is the problem.

Q2. What does an out-of-distribution evaluation set actually look like for a VLA model?

It is a test set built deliberately to differ from the model’s likely training distribution: object types it has not seen paired with familiar ones, lighting and background conditions different from the training environment, and instruction phrasings that vary from the canonical form. The goal is not to make the test unfairly hard. It is to find the boundary of where the model’s competence actually stops, which a test set drawn from the same distribution as the training will not reveal.

Q3. How do you evaluate a model’s ability to recover from a failed step in a multi-step task?

Build evaluation scenarios that deliberately introduce a failure partway through a task: move an object slightly, interrupt the action, or change the environment mid-sequence. Then assess whether the model recognizes that the expected state did not occur and adapts, or whether it continues executing a plan based on its original assumption. This requires reviewing the full episode, not just the outcome, because a model can recover successfully through an inefficient path or fail silently while still producing a result that looks plausible at a glance.

Q4. What is a reasonable success rate to expect from a VLA model before deployment?

There is no single universal threshold, because the right number depends on the cost of failure in your specific task, but rough industry ranges give you a starting anchor. Low-stakes sorting or bin-picking tasks with cheap recovery from a miss are often deployed in the 90 to 95 percent success range, with a human or a simple fallback catching the rest. Tasks involving variable or fragile objects, such as warehouse pick-and-pack with mixed SKUs, generally need to clear 95 to 98 percent before the rework cost stops eating the labor savings. Tasks operating near people, expensive equipment, or in safety-relevant contexts, such as collaborative assembly or surgical-adjacent applications, are typically held to 99 percent or higher, often paired with a hard mechanical or software safety layer rather than relying on the model’s success rate alone. These are starting anchors, not certifications. What matters more than clearing a number is understanding the failure modes behind whatever rate you observe: whether failures are concentrated in specific object types, specific instruction phrasings, or specific task phases. That breakdown tells you whether the gap is fixable with more targeted data or whether it reflects a more fundamental limitation.

How to Evaluate VLA Model for Real-World Deployment: Grounding, Planning, and Action Fidelity Read Post »

Humanoid Training Data and the Problem Nobody Is Talking About

Humanoid Training Data and the Problem Nobody Is Talking About


Spend a week reading humanoid robotics coverage, and you will hear a great deal about joint torque, degrees of freedom, battery runtime, and the competitive landscape between Figure, Agility, Tesla, and Boston Dynamics. These are real and important topics. They are also the visible part of a much larger iceberg. The part below the waterline is data: the enormous, structurally complex, expensive-to-produce training data that determines whether a humanoid robot that can walk and lift boxes in a controlled warehouse pilot can also navigate an unexpected obstacle, pick up an unfamiliar container, or recover gracefully from a failed grasp in a real facility with real variation.

In this blog, we examine why humanoid training data is harder to collect and annotate than text or image data, what specific data modalities system requires, and what development teams need to build real-world systems.

What Humanoid Training Data Actually Involves

The modality stack

A production-capable humanoid robot learning to perform a manipulation task in a real environment needs training data that captures the full sensorimotor loop of the task. That means egocentric RGB video from cameras mounted on or near the robot’s head, capturing what the robot sees as it acts. It means depth data providing metric scene geometry. It means 3D LiDAR point clouds for spatial awareness in larger environments. It means joint angle and joint velocity time series for every degree of freedom in the kinematic chain. It means force and torque sensor readings at the wrist and end-effector. And for dexterous manipulation tasks, it means tactile sensor data from fingertip sensors that can distinguish the difference between a secure grip and one that is about to slip.

The annotation requirements that follow

Raw multi-modal sensor data is not training data. It becomes training data through annotation: the labeling of object identities and spatial positions, the segmentation of task phases and sub-task boundaries, the labeling of contact events, grasp outcomes, and failure modes, the assignment of natural language descriptions to action sequences, and the quality filtering that removes demonstrations that are too noisy, too slow, or too inconsistent to contribute usefully to policy learning. Each of these annotation tasks has different requirements, different skill demands, and different quality standards. Producing them at the volume and consistency that foundation model training needs is not a bottleneck that better algorithms alone will resolve. It is a data collection and annotation infrastructure problem, and it requires dedicated annotation capacity built specifically for physical AI data.

Teleoperation: The Primary Data Collection Method and Its Limits

Why teleoperation dominates humanoid data collection

Teleoperation, where a human operator directly controls the humanoid robot’s movements while the robot records its sensor outputs and the operator’s control signals as a training demonstration, has become the dominant method for humanoid training data collection. The reason is straightforward: it is the most reliable way to generate high-quality demonstrations of complex tasks that the robot cannot yet perform autonomously. A teleoperated demonstration shows the robot what success looks like at the level of sensor-to-action detail that imitation learning algorithms require.

The quality problem in teleoperated demonstrations

Teleoperated demonstrations vary enormously in quality. An operator who is fatigued, distracted, or performing an unfamiliar task will produce demonstrations that include inefficient trajectories, hesitation pauses, unnecessary corrective movements, and failed attempts that have to be discarded or carefully annotated as negative examples. Demonstrations produced by expert operators in controlled conditions transfer poorly to the diversity of real operating environments. A demonstration of picking up a specific bottle in a specific lighting condition, at a specific position on a shelf, does not generalize to picking up a different container at a different position in different light. Generalization requires demonstration diversity, and producing diverse demonstrations of sufficient quality is expensive.

The annotation layer on top of teleoperated demonstrations adds further complexity. Determining which demonstrations are high-quality enough to include in the training set, where in each demonstration the relevant task phases begin and end, and whether a grasp that succeeded in the demonstration would generalize to variations of the same task: these are judgment calls that require annotators with domain knowledge. Human-in-the-loop annotation for humanoid training data is not the same as image labeling. It requires annotators who understand embodied motion, task structure, and the relationship between sensor signals and physical outcomes.

Imitation Learning and the Data Volume Problem

Imitation learning, where a robot policy is trained to reproduce the actions observed in human demonstrations, is the dominant learning paradigm for humanoid manipulation tasks. Its appeal is clear: if you can show the robot what to do with enough fidelity and enough variation, it can learn to reproduce that behavior across a range of conditions. The challenge is that imitation learning’s performance typically scales with both the volume and diversity of demonstration data. A policy trained on 50 demonstrations of a task in one configuration may perform reliably in that configuration but fail in any configuration that differs meaningfully from the training distribution. Achieving the kind of generalization that makes a humanoid robot commercially useful, the ability to perform a task across the range of objects, positions, lighting conditions, and human interaction patterns that a real deployment environment involves requires a demonstration library that may run to thousands of episodes per task category.

What makes demonstration data diverse enough to generalize

The diversity requirements for humanoid demonstration data are more demanding than they might appear. It is not sufficient to vary the visual appearance of the scene. A demonstration library that includes images of the same object in ten different lighting conditions, but always at the same height and orientation, has not solved the generalization problem. True generalization requires variation across object instances, object positions and orientations, operator approaches, surface properties, partial occlusions, and interaction sequences. Producing that variation systematically, and annotating it consistently, requires a data collection methodology that is closer to scientific experimental design than to ad hoc video capture. 

The Sim-to-Real Gap: Why Simulation Data Alone Is Not Enough

What simulation can and cannot do for humanoid training

Simulation is an attractive solution to the data volume problem in humanoid robotics, and it does provide genuine value. Simulation operations can generate locomotion training data at a scale that physical collection cannot match, exposing a locomotion controller to millions of terrain configurations, perturbations, and recovery scenarios that would take years to collect physically. 

The sim-to-real gap is the problem that limits how far simulation can be pushed as a substitute for real-world data in humanoid training. Humanoid robots are highly sensitive to physical variables, including surface friction, object deformation, contact dynamics, and the timing of force transmission through compliant joints. Simulation models of these phenomena are approximations. The approximations that are good enough for locomotion training are often not good enough for dexterous manipulation training, where the difference between a successful grasp and a failed one may depend on contact dynamics that even sophisticated simulators do not fully replicate.

The data annotation demands of sim-to-real transfer

Managing the sim-to-real gap requires real-world data for calibration and transfer validation. A team that trains a manipulation policy in simulation needs annotated real-world data from the target environment to measure the size of the gap and to identify which aspects of the policy need fine-tuning on real demonstrations. That fine-tuning step requires its own demonstration collection and annotation pipeline, operating at the intersection of simulation-aware annotation and real physical deployment data. DDD’s digital twin validation services and simulation operations capabilities are built to support exactly this kind of iterative sim-to-real data workflow, ensuring that the transition from simulation training to physical deployment is grounded in real-world data at every calibration stage.

The annotation challenges specific to sim-to-real transfer are also worth naming directly. Annotators working on sim-to-real data need to label not only what happened in the real-world interaction, but why the policy behaved differently from the simulation expectation. Identifying the specific contact dynamics, object properties, or environmental conditions that explain a performance gap requires physical intuition that cannot be reduced to simple object labeling. It is closer to failure mode analysis than to standard annotation work.

Why Touch Matters More Than Vision for Dexterous Tasks

The current dominant paradigm in humanoid robot perception is vision-first: cameras capture what the robot sees, and perception algorithms process that visual data to plan manipulation actions. For many tasks, this is sufficient. Picking up a rigid object from a known position against a contrasting background is tractable with vision alone. But the manipulation tasks that would make a humanoid commercially valuable in real environments, sorting mixed containers, handling deformable materials, performing assembly operations with tight tolerances, adjusting grip when an object begins to slip, are tasks where tactile and force data are not supplementary. They are necessary.

The manipulation bottleneck that the humanoid industry is beginning to acknowledge is partly a tactile data problem. A robot that cannot sense contact forces and fingertip pressure cannot adjust grip dynamically, cannot detect an impending drop, and cannot handle objects whose properties vary in ways that vision does not reveal. Current fingertip tactile sensors exist and are being integrated into leading humanoid platforms, but the training data infrastructure for tactile-augmented manipulation is still in early development.

What tactile data annotation requires

Tactile sensor data annotation is among the least standardized modalities in the Physical AI data ecosystem. Pressure maps, shear force readings, and vibrotactile signals from fingertip sensors need to be labeled in the context of the manipulation task they accompany, correlating contact events with grasp outcomes, surface properties, and the visual and kinematic data recorded simultaneously. The multisensor fusion demands of tactile-augmented humanoid data are significantly higher than those of vision-only systems, because the temporal synchronization requirements are strict and the physical interpretation of the sensor signals requires annotators who understand both the sensor physics and the task structure being labeled.

Why annotation quality matters more at foundation model scale

At the scale of foundation model training, annotation quality errors do not average out. They compound. A systematic labeling error in task phase boundaries, consistently applied across thousands of demonstrations, will produce a model that learns the wrong task decomposition. A set of demonstrations that are annotated as successful but that include borderline or partially failed grasps will produce a model with an optimistic view of its own manipulation reliability. The quality standards that matter for smaller-scale policy training become critical at foundation model scale, where the training corpus is large enough that individual annotation errors have diffuse effects that are difficult to diagnose after the fact. Investing in high-quality ML data annotation and structured quality assurance protocols from the start of a humanoid data program is considerably more cost-effective than attempting to audit and correct a large, inconsistently annotated corpus later.

What the Data Infrastructure Gap Means for Commercial Timelines

The honest assessment of where the industry stands

The humanoid robotics programs that are most credibly advancing toward commercial deployment in 2026 are the ones that have invested seriously in their data infrastructure alongside their hardware development. 

For development teams that do not have access to large proprietary deployment environments to generate operational data, the path to the demonstration volume and diversity that commercially viable generalization requires runs through specialist data infrastructure: teleoperation setups capable of producing high-quality, diverse demonstrations at volume, annotation teams with the domain knowledge to label multi-modal physical AI data to the standards that foundation model training demands, and quality assurance pipelines that can maintain consistency across large demonstration corpora.

The cost reality that is underweighted in roadmaps

Humanoid robotics roadmaps published by development teams and market analysts tend to foreground hardware milestones and underweight data infrastructure costs. The cost of collecting, synchronizing, and annotating a demonstration library large enough to support meaningful generalization is not a rounding error in a humanoid development budget. For a team targeting deployment across multiple task categories in a real operating environment, the data infrastructure investment is likely to be comparable to, and in some cases larger than, the hardware development cost. Teams that discover this late in the development cycle face difficult choices between delaying deployment to build the data they need and accepting a narrower generalization than their product roadmaps promised. Physical AI data services from specialist partners offer an alternative: access to annotation infrastructure and domain expertise that development teams can engage without building the full capability in-house.

How DDD Can Help

Digital Divide Data provides comprehensive humanoid AI data solutions designed to support development programs at every stage of the training data lifecycle. DDD’s teams have the domain expertise and operational capacity to handle the multi-modal annotation demands that humanoid robotics training data requires, from synchronized video and depth annotation to joint pose labeling, task phase segmentation, and grasp outcome classification.

On the teleoperation and demonstration data side, DDD’s ML data collection services support the design and execution of structured demonstration collection programs that produce the diversity and quality that imitation learning algorithms need. Rather than capturing demonstrations opportunistically, DDD works with development teams to define the coverage requirements for their operational design domain and design data collection protocols that systematically address those requirements.

For teams building toward Large Behavior Models and vision-language-action systems, DDD’s VLA model analysis capabilities and multi-modal annotation workflows support the natural language annotation, task phase labeling, and cross-task consistency checking that foundation model training data requires. DDD’s robotics data services extend this support to the broader robotics data ecosystem, including annotation for locomotion training data, environment mapping for simulation foundation models, and quality assurance for sim-to-real transfer validation datasets.

Teams working on the tactile and force data frontier can engage DDD’s annotation specialists for the physical AI data modalities that require domain-specific expertise: contact event labeling, grasp outcome classification, and the correlation of multisensor fusion data across tactile, kinematic, and visual streams. For C-level decision-makers evaluating their data infrastructure strategy, DDD offers a realistic assessment of what production-grade humanoid training data requires and a delivery model that scales with the program.

Build the data infrastructure your humanoid robotics program actually needs. Talk to an expert!

Conclusion

The humanoid robotics industry is at a genuine inflection point, and the coverage of that inflection point reflects a real shift in what these systems can do. What the coverage does not yet fully reflect is the structural dependency between what humanoid robots can do in controlled demonstrations and what they can do in the real-world environments that commercial deployment actually involves. That gap is primarily a data gap. The manipulation tasks, the environmental diversity, the dexterous skill generalization, and the recovery from unexpected failures that would make a humanoid robot genuinely useful in an industrial or domestic setting require training data at a volume, diversity, and multi-modal quality that most development programs have not yet built the infrastructure to produce. Recognizing that the data infrastructure is the critical path, not an implementation detail to be addressed after the hardware is ready, is the first step toward realistic commercial planning.

The programs that close the gap first will not necessarily be the ones with the best actuators or the most capable base models. They will be the ones who treat Physical AI data infrastructure as a first-class engineering investment, building the teleoperation capacity, annotation pipelines, and quality assurance frameworks that turn raw sensor data into training data capable of generalizing to the real world. The hardware plateau that the industry is approaching makes this clearer, not less so. When mechanical capability is no longer the differentiator, the quality of the data behind the intelligence becomes the thing that determines which programs reach commercial scale and which ones remain compelling prototypes.

References 

Welte, E., & Rayyes, R. (2025). Interactive imitation learning for dexterous robotic manipulation: Challenges and perspectives — a survey. Frontiers in Robotics and AI, 12, Article 1682437. https://doi.org/10.3389/frobt.2025.1682437

NVIDIA Developer Blog. (2025, November 6). Streamline robot learning with whole-body control and enhanced teleoperation in NVIDIA Isaac Lab 2.3. https://developer.nvidia.com/blog/streamline-robot-learning-with-whole-body-control-and-enhanced-teleoperation-in-nvidia-isaac-lab-2-3/

Rokoko. (2025). Unlocking the data infrastructure for humanoid robotics. Rokoko Insights. https://www.rokoko.com/insights/unlocking-the-data-infrastructure-for-humanoid-robotics 

Frequently Asked Questions

What types of sensors generate training data for humanoid robots?

Production-grade humanoid training requires synchronized data from cameras, depth sensors, LiDAR, joint encoders, force-torque sensors at the wrist, IMUs, and fingertip tactile sensors, all recorded at high frequency during demonstration or operation episodes.

How many demonstrations does a humanoid robot need to learn a manipulation task?

It varies significantly by task complexity and demonstration diversity, but research suggests hundreds to thousands of diverse demonstrations per task category are typically needed for meaningful generalization beyond the specific training configurations.

Why can’t humanoid robots just use simulation data instead of expensive real demonstrations?

Simulation is useful for locomotion and coarse motor training, but dexterous manipulation requires accurate contact dynamics and surface properties that simulators still do not replicate with sufficient fidelity, making real-world demonstration data necessary for the most challenging tasks.

What is the sim-to-real gap and why does it matter for humanoid deployment?

The sim-to-real gap refers to the performance drop when a policy trained in simulation is deployed on real hardware, caused by differences in physics, sensor noise, and contact dynamics between the simulated and real environments that require real-world data to bridge. 

Humanoid Training Data and the Problem Nobody Is Talking About Read Post »

VLAAutonomy

Vision-Language-Action Models: How Foundation Models are Transforming Autonomy

Vision-Language-Action (VLA) models are revolutionizing how machines comprehend and engage with the world. They combine three capabilities: seeing, reasoning, and acting. Instead of only recognizing what’s in front of them or describing it in words, these models can now decide what to do next. That might sound like a small step, but it changes everything about how we think of autonomy.

The idea that language can guide machines toward meaningful action raises questions about control, intent, and the reliability of such actions. VLA systems may appear capable, but they still depend on the statistical correlations buried in their training data. When they fail, their mistakes can look strangely human, hesitant, sometimes overconfident, and often difficult to diagnose. This tension between impressive generalization and uncertain reliability is what makes the current phase of embodied AI so fascinating.

In this blog, we explore how Vision-Language-Action models are transforming the autonomy industry. We’ll trace how they evolved from vision-language systems into full-fledged embodied agents, understand how they actually work, and consider where they are making a tangible difference.

Understanding Vision-Language-Action Models

Researchers started to integrate action grounding, the ability to connect perception and language with movement. These Vision-Language-Action (VLA) models don’t just recognize or describe. They can infer intent and translate that understanding into physical behavior. In practice, that might mean a robot arm identifying the correct tool and tightening a bolt after a natural language command, or a drone navigating toward a visual cue while adapting to obstacles it hadn’t seen before.

Formally, a VLA model is a single architecture that takes multimodal inputs, text, images, sometimes even video, and outputs either high-level goals or low-level motor actions. What sets it apart is the feedback loop. The model doesn’t just observe and respond once; it continuously updates its understanding as it acts. That loop between perception and execution is what allows it to operate in dynamic, unpredictable environments like a warehouse floor or a moving vehicle.

It’s tempting to think of a VLA as simply a large language model with a camera attached, but that analogy doesn’t hold for long. VLA systems learn through sensorimotor experience, often combining simulated and real-world data to capture cause-and-effect relationships. They develop a sense of temporal context, what just happened, what is happening now, and what should happen next. In other words, they start to connect words to consequences. That distinction may seem subtle, yet it’s exactly what enables the shift from static perception to active intelligence.

How Vision-Language-Action Models Work

At the core, VLA brings together three subsystems: perception, reasoning, and control, and trains them to speak a shared computational language. Each part matters, but it’s the way they interact that gives these models their edge.

Perception begins with multimodal encoders

These components take in data from multiple sensors, images, LiDAR, depth maps, and sometimes even textual context, and transform them into a shared representation of the environment. It’s not just about identifying what’s in front of the system but about forming a spatial and semantic map that can guide action. For instance, a warehouse robot might fuse RGB images with depth input to distinguish between stacked boxes and open walkways, using that fused map to plan its movement.

Language-conditioned policy

This is where a transformer backbone interprets a human instruction like “move the blue cylinder closer to the wall” and converts it into a set of high-level goals or continuous control vectors. What’s happening here is subtle: the model is not following a pre-programmed routine but translating an abstract linguistic command into an internal logic that can be executed by an agent.

Action decoding

This is where the model outputs actual motor commands. Some VLAs use diffusion policies, a probabilistic method that samples multiple potential actions before settling on the most likely one, while others rely on autoregressive controllers that predict a sequence of small, incremental motions. Each approach has trade-offs: diffusion models tend to generalize better to novel tasks, while autoregressive ones are faster and more deterministic.

Closed-loop grounding

They don’t simply act and stop; they act, observe, and adjust. After each movement, new sensory input flows back into the encoder, allowing the model to refine its next decision. This loop mimics how humans operate, continually checking and recalibrating as we perform a task. The ability to respond to environmental feedback in real time is what makes these models viable for embodied applications like mobile robotics or autonomous driving.

If you were to visualize this process, it would look less like a straight pipeline and more like a circular feedback system:

Instruction → Perception → Policy Reasoning → Action → Updated Perception.

That constant cycle of observation and correction is what separates a passive vision-language model from an active one. It’s also what allows VLA architectures to maintain stability in unpredictable conditions, whether that’s a drone compensating for a sudden gust of wind or a robotic arm adapting its grip as an object slips.

Why Vision-Language-Action Models are Important for Autonomy

The autonomy industry has long been defined by a trade-off between precision and adaptability. Traditional systems are predictable because they operate within well-defined boundaries, but that predictability comes at the cost of flexibility. Vision-Language-Action models disrupt this balance by introducing a kind of learned adaptability, systems that can interpret ambiguous instructions, reason through uncertainty, and act without explicit reprogramming. For companies building drones, autonomous vehicles, or industrial robots, that capability signals a practical turning point.

Cross-Platform Generalization

One of the most compelling advantages of VLA models is cross-platform generalization. VLAs can often be fine-tuned once and then deployed across multiple embodiments. A policy trained on a manipulator arm in simulation might perform reasonably well on a different robot in the real world after minimal calibration. For an industry that spends significant time and money on retraining models for each new platform, this shift is economically meaningful.

Zero-shot task learning

VLA-based systems can perform entirely new tasks from natural language instructions without needing additional datasets. For example, a warehouse robot could be told, “Sort the fragile items on the left and the rest on the right,” and figure out how to execute that without prior exposure to that specific task. This kind of adaptability reduces downtime and increases autonomy in dynamic industrial or service settings where environments change faster than training cycles.

Data Efficiency 

Projects like AutoRT have introduced what researchers call a “constitution loop”, a semi-autonomous method where robots propose their own data collection tasks, execute them, and use feedback from large language models to evaluate their performance. It’s a recursive form of self-supervision that cuts down on the expensive and time-consuming process of human annotation. For companies scaling large fleets of autonomous systems, these feedback loops represent both cost savings and a path toward more diverse, representative training data.

Safety and explainability

The two areas where traditional end-to-end learning models have struggled. Because VLA systems reason through language-conditioned representations, their internal decision-making processes are often more interpretable. When a robot hesitates before grasping a cup or chooses a slower route, its intermediate reasoning can sometimes be inspected through generated language outputs: “the cup appears unstable,” “the shorter path is obstructed.” This interpretability doesn’t make them foolproof, but it does make them easier to audit and debug compared with opaque control networks.

Industry-Specific Use Cases of Vision-Language-Action Models

The influence of Vision-Language-Action models is already spreading across several branches of the autonomy ecosystem.

Autonomous Driving

Instead of relying solely on object detection and trajectory forecasting, autonomous vehicles can reason about semantic cues: a pedestrian holding a phone near a crosswalk or a cyclist glancing over their shoulder. These subtle indicators help models anticipate human behavior, making decision-making less mechanical. The challenge, of course, lies in translating this interpretive strength into dependable, real-time control. Latency, hardware constraints, and uncertainty estimation still limit commercial adoption.

Industrial and Logistics Robotics

A robot trained in simulation to organize tools can now apply that knowledge to stacking boxes or sorting products in a fulfillment center. The real value here is operational: fewer human interventions, faster reconfiguration of robotic systems, and adaptive handling of unexpected layouts or objects. Companies experimenting with these systems often report smoother workflows but still face integration hurdles, especially in legacy industrial setups that were never designed for learning-based control.

Defense and Aerospace

VLAs can interpret strategic objectives expressed in natural language and translate them into executable plans for multi-agent teams. Aerial drones, for instance, can receive high-level instructions like “survey the northern ridge and maintain formation spacing,” then dynamically coordinate their flight paths. This ability to merge top-down guidance with situational awareness makes VLAs appealing for reconnaissance, search and rescue, and disaster response. Yet these are precisely the domains where safety validation, trust calibration, and oversight become most urgent.

Healthcare and Service Robotics

Robots assisting in hospitals or eldercare settings need to interpret not just verbal commands but also social context. A system that can understand a nurse saying, “Hand me the smaller syringe, not the new one,” or a patient asking, “Could you move this closer?” demonstrates a level of nuance that rule-based systems cannot match. VLA-driven interaction enables a form of responsiveness that feels less like automation and more like collaboration. Even so, ethical considerations, privacy, accountability, and the emotional expectations people place on such systems remain under active debate.

Challenges in Vision-Language-Action Models

Understanding VLA challenges is essential, not only for improving technical performance but also for setting realistic expectations about what these systems can and cannot do.

Data diversity and embodiment mismatch

Most VLAs are trained on a mix of simulated and real-world data, yet the transition between the two remains imperfect. Simulators can model physics and visuals convincingly, but they often fail to capture the noise, friction, and unpredictability of real environments. A model that performs flawlessly in a digital warehouse may struggle when the lighting shifts or when objects reflect glare. Bridging that gap requires better domain randomization and richer multimodal datasets, efforts that are costly and slow to produce.

Real-time inference and scaling

Transformer-based architectures, while expressive, are computationally heavy. Running them on embedded processors in drones, vehicles, or handheld devices introduces latency that can turn a safe maneuver into a delayed one. Hardware acceleration and model compression offer partial relief, but they tend to trade precision for speed. As a result, developers often find themselves balancing the elegance of large architectures against the practical constraints of real-world deployment.

Standardization and interoperability

The field lacks shared evaluation pipelines, cross-platform APIs, and common action representations. Each research group defines its own interface for connecting perception, language, and control, which makes collaboration cumbersome. Without open standards, progress risks becoming fragmented, with isolated breakthroughs rather than collective advancement.

Read more: Sensor Fusion Explained: Why Multiple Sensors are Better Than One

Recommendations for Vision-Language-Action Models

Several pragmatic steps could help researchers, policymakers, and industry teams build models that are not only capable but also dependable.

Explainability-by-design

 Instead of treating interpretability as an afterthought, researchers could embed mechanisms that allow VLA systems to express their reasoning in natural language or symbolic form. This would make it easier to audit decisions and trace errors after deployment. The approach is already being tested in some robotics labs, where models are prompted to “verbalize” their intent before acting, a surprisingly effective safeguard against unsafe or ambiguous behavior.

Open Benchmarking and Evaluation

Independent initiatives like VLATest are valuable, but they need institutional backing and community participation to gain legitimacy. The field could benefit from a consortium-driven framework similar to how the ImageNet challenge standardized computer vision research a decade ago. Benchmarks that measure not just accuracy but also robustness, adaptability, and safety could create more accountability and accelerate meaningful progress.

Edge Optimization

Many autonomy systems rely on hardware with strict power and latency limits. Developing compact or hierarchical VLA architectures, where smaller sub-models handle local decisions while larger models manage higher-level reasoning, could help balance responsiveness with depth of understanding. Progress here will likely depend on collaboration between model designers, chip manufacturers, and system integrators.

Academic–Industry Partnerships

The gap between laboratory success and real-world deployment remains wide, and bridging it requires joint investment. Companies working on logistics, autonomous mobility, or industrial robotics could collaborate with universities to co-develop datasets, share evaluation metrics, and test transfer learning strategies. These partnerships should also include ethicists and regulatory advisors, ensuring that safety and accountability are part of the design process rather than afterthoughts.

How We Can Help

As Vision-Language-Action models transition from research labs into real-world deployments, the biggest barrier is not the algorithms themselves but the data they depend on. High-quality multimodal data, visual, textual, and sensor-based, is the foundation that allows these models to learn how to perceive, reason, and act coherently. This is where Digital Divide Data (DDD) plays a crucial role.

DDD specializes in end-to-end data lifecycle management for AI systems, helping organizations prepare, annotate, and validate the kind of complex, multimodal datasets that modern VLA models require. Our teams have deep experience working with visual, spatial, and linguistic data at scale, ensuring that every data point is accurate, contextual, and ethically sourced. Whether the goal is to train a model to interpret traffic scenes for autonomous driving or to fine-tune a robotic control policy on language-guided tasks, we provide the structure and human expertise needed to make that data usable and trustworthy.

Read more: The Pros and Cons of Automated Labeling for Autonomous Driving

Conclusion

Vision-Language-Action models represent more than another step in AI development; they mark a structural shift in how machines connect perception with behavior. For years, autonomy depended on pre-defined logic and hand-crafted control rules. Now, with VLAs, systems can learn from examples, interpret ambiguous instructions, and adapt to new situations with minimal retraining. It is a subtle but powerful change: autonomy is no longer just about automation, it is about understanding context and responding intelligently to it.

What is clear is that Vision-Language-Action models have expanded the vocabulary of autonomy itself. They have turned passive observation into interactive understanding, and in doing so, they have redrawn the boundary between human direction and machine initiative. The future of autonomy will belong to those who can balance this new capability with rigor, transparency, and care.

Partner with Digital Divide Data to build the data foundation for safer, smarter, and more context-aware autonomous systems.


References

DeepMind. (2024, January). Shaping the future of advanced robotics. DeepMind Blog. https://deepmind.google/

Google Research. (2023, October). Open X-Embodiment: Robotic learning datasets and RT-X models. arXiv:2310.XXXXX.

Zhou, X., Liu, M., Yurtsever, E., Zagar, B. L., Zimmer, W., Cao, H., & Knoll, A. C. (2023). Vision-language models in autonomous driving: A survey and outlook. arXiv. https://arxiv.org/abs/2310.14414

Kawaharazuka, K., Oh, J., Yamada, J., Posner, I., & Zhu, Y. (2025). Vision-language-action models for robotics: A review towards real-world applications. arXiv. https://arxiv.org/abs/2510.07077

Guruprasad, P., Sikka, H., Song, J., Wang, Y., & Liang, P. P. (2024). Benchmarking vision, language, & action models on robotic learning tasks. arXiv. https://arxiv.org/abs/2411.05821


Frequently Asked Questions

Q1. Are Vision-Language-Action models a form of general artificial intelligence?
Not exactly. While VLAs integrate perception, reasoning, and action, they are still specialized systems. They excel at sensorimotor coordination and contextual reasoning but remain limited to the domains and data they were trained on. They represent a step toward more general intelligence, not its arrival.

Q2. How do VLAs compare to reinforcement learning systems?
Reinforcement learning focuses on trial-and-error optimization for specific tasks. VLAs, in contrast, combine large-scale multimodal learning with grounded control. They often use reinforcement learning for fine-tuning but start from a foundation of language and vision pretraining, which gives them broader adaptability.

Q3. What industries are most likely to adopt VLA models first?
Autonomous mobility, industrial robotics, and defense are leading adopters because they already rely on perception-action loops. However, healthcare, logistics, and service robotics are rapidly experimenting with language-guided systems to improve flexibility and user interaction.

Q4. Are there ethical risks specific to VLA systems?
Yes. Because these models interpret and act on natural language, misinterpretation can lead to unintended behavior. Privacy issues also arise when they operate in human environments with cameras and microphones. Ethical deployment requires transparent decision logging and consistent human oversight.

Vision-Language-Action Models: How Foundation Models are Transforming Autonomy Read Post »

Scroll to Top