Celebrating 25 years of DDD's Excellence and Social Impact. ✖

Robotics

VLAAutonomy

Vision-Language-Action Models: How Foundation Models are Transforming Autonomy

Vision-Language-Action (VLA) models are revolutionizing how machines comprehend and engage with the world. They combine three capabilities: seeing, reasoning, and acting. Instead of only recognizing what’s in front of them or describing it in words, these models can now decide what to do next. That might sound like a small step, but it changes everything about how we think of autonomy.

The idea that language can guide machines toward meaningful action raises questions about control, intent, and the reliability of such actions. VLA systems may appear capable, but they still depend on the statistical correlations buried in their training data. When they fail, their mistakes can look strangely human, hesitant, sometimes overconfident, and often difficult to diagnose. This tension between impressive generalization and uncertain reliability is what makes the current phase of embodied AI so fascinating.

In this blog, we explore how Vision-Language-Action models are transforming the autonomy industry. We’ll trace how they evolved from vision-language systems into full-fledged embodied agents, understand how they actually work, and consider where they are making a tangible difference.

Understanding Vision-Language-Action Models

Researchers started to integrate action grounding, the ability to connect perception and language with movement. These Vision-Language-Action (VLA) models don’t just recognize or describe. They can infer intent and translate that understanding into physical behavior. In practice, that might mean a robot arm identifying the correct tool and tightening a bolt after a natural language command, or a drone navigating toward a visual cue while adapting to obstacles it hadn’t seen before.

Formally, a VLA model is a single architecture that takes multimodal inputs, text, images, sometimes even video, and outputs either high-level goals or low-level motor actions. What sets it apart is the feedback loop. The model doesn’t just observe and respond once; it continuously updates its understanding as it acts. That loop between perception and execution is what allows it to operate in dynamic, unpredictable environments like a warehouse floor or a moving vehicle.

It’s tempting to think of a VLA as simply a large language model with a camera attached, but that analogy doesn’t hold for long. VLA systems learn through sensorimotor experience, often combining simulated and real-world data to capture cause-and-effect relationships. They develop a sense of temporal context, what just happened, what is happening now, and what should happen next. In other words, they start to connect words to consequences. That distinction may seem subtle, yet it’s exactly what enables the shift from static perception to active intelligence.

How Vision-Language-Action Models Work

At the core, VLA brings together three subsystems: perception, reasoning, and control, and trains them to speak a shared computational language. Each part matters, but it’s the way they interact that gives these models their edge.

Perception begins with multimodal encoders

These components take in data from multiple sensors, images, LiDAR, depth maps, and sometimes even textual context, and transform them into a shared representation of the environment. It’s not just about identifying what’s in front of the system but about forming a spatial and semantic map that can guide action. For instance, a warehouse robot might fuse RGB images with depth input to distinguish between stacked boxes and open walkways, using that fused map to plan its movement.

Language-conditioned policy

This is where a transformer backbone interprets a human instruction like “move the blue cylinder closer to the wall” and converts it into a set of high-level goals or continuous control vectors. What’s happening here is subtle: the model is not following a pre-programmed routine but translating an abstract linguistic command into an internal logic that can be executed by an agent.

Action decoding

This is where the model outputs actual motor commands. Some VLAs use diffusion policies, a probabilistic method that samples multiple potential actions before settling on the most likely one, while others rely on autoregressive controllers that predict a sequence of small, incremental motions. Each approach has trade-offs: diffusion models tend to generalize better to novel tasks, while autoregressive ones are faster and more deterministic.

Closed-loop grounding

They don’t simply act and stop; they act, observe, and adjust. After each movement, new sensory input flows back into the encoder, allowing the model to refine its next decision. This loop mimics how humans operate, continually checking and recalibrating as we perform a task. The ability to respond to environmental feedback in real time is what makes these models viable for embodied applications like mobile robotics or autonomous driving.

If you were to visualize this process, it would look less like a straight pipeline and more like a circular feedback system:

Instruction → Perception → Policy Reasoning → Action → Updated Perception.

That constant cycle of observation and correction is what separates a passive vision-language model from an active one. It’s also what allows VLA architectures to maintain stability in unpredictable conditions, whether that’s a drone compensating for a sudden gust of wind or a robotic arm adapting its grip as an object slips.

Why Vision-Language-Action Models are Important for Autonomy

The autonomy industry has long been defined by a trade-off between precision and adaptability. Traditional systems are predictable because they operate within well-defined boundaries, but that predictability comes at the cost of flexibility. Vision-Language-Action models disrupt this balance by introducing a kind of learned adaptability, systems that can interpret ambiguous instructions, reason through uncertainty, and act without explicit reprogramming. For companies building drones, autonomous vehicles, or industrial robots, that capability signals a practical turning point.

Cross-Platform Generalization

One of the most compelling advantages of VLA models is cross-platform generalization. VLAs can often be fine-tuned once and then deployed across multiple embodiments. A policy trained on a manipulator arm in simulation might perform reasonably well on a different robot in the real world after minimal calibration. For an industry that spends significant time and money on retraining models for each new platform, this shift is economically meaningful.

Zero-shot task learning

VLA-based systems can perform entirely new tasks from natural language instructions without needing additional datasets. For example, a warehouse robot could be told, “Sort the fragile items on the left and the rest on the right,” and figure out how to execute that without prior exposure to that specific task. This kind of adaptability reduces downtime and increases autonomy in dynamic industrial or service settings where environments change faster than training cycles.

Data Efficiency 

Projects like AutoRT have introduced what researchers call a “constitution loop”, a semi-autonomous method where robots propose their own data collection tasks, execute them, and use feedback from large language models to evaluate their performance. It’s a recursive form of self-supervision that cuts down on the expensive and time-consuming process of human annotation. For companies scaling large fleets of autonomous systems, these feedback loops represent both cost savings and a path toward more diverse, representative training data.

Safety and explainability

The two areas where traditional end-to-end learning models have struggled. Because VLA systems reason through language-conditioned representations, their internal decision-making processes are often more interpretable. When a robot hesitates before grasping a cup or chooses a slower route, its intermediate reasoning can sometimes be inspected through generated language outputs: “the cup appears unstable,” “the shorter path is obstructed.” This interpretability doesn’t make them foolproof, but it does make them easier to audit and debug compared with opaque control networks.

Industry-Specific Use Cases of Vision-Language-Action Models

The influence of Vision-Language-Action models is already spreading across several branches of the autonomy ecosystem.

Autonomous Driving

Instead of relying solely on object detection and trajectory forecasting, autonomous vehicles can reason about semantic cues: a pedestrian holding a phone near a crosswalk or a cyclist glancing over their shoulder. These subtle indicators help models anticipate human behavior, making decision-making less mechanical. The challenge, of course, lies in translating this interpretive strength into dependable, real-time control. Latency, hardware constraints, and uncertainty estimation still limit commercial adoption.

Industrial and Logistics Robotics

A robot trained in simulation to organize tools can now apply that knowledge to stacking boxes or sorting products in a fulfillment center. The real value here is operational: fewer human interventions, faster reconfiguration of robotic systems, and adaptive handling of unexpected layouts or objects. Companies experimenting with these systems often report smoother workflows but still face integration hurdles, especially in legacy industrial setups that were never designed for learning-based control.

Defense and Aerospace

VLAs can interpret strategic objectives expressed in natural language and translate them into executable plans for multi-agent teams. Aerial drones, for instance, can receive high-level instructions like “survey the northern ridge and maintain formation spacing,” then dynamically coordinate their flight paths. This ability to merge top-down guidance with situational awareness makes VLAs appealing for reconnaissance, search and rescue, and disaster response. Yet these are precisely the domains where safety validation, trust calibration, and oversight become most urgent.

Healthcare and Service Robotics

Robots assisting in hospitals or eldercare settings need to interpret not just verbal commands but also social context. A system that can understand a nurse saying, “Hand me the smaller syringe, not the new one,” or a patient asking, “Could you move this closer?” demonstrates a level of nuance that rule-based systems cannot match. VLA-driven interaction enables a form of responsiveness that feels less like automation and more like collaboration. Even so, ethical considerations, privacy, accountability, and the emotional expectations people place on such systems remain under active debate.

Challenges in Vision-Language-Action Models

Understanding VLA challenges is essential, not only for improving technical performance but also for setting realistic expectations about what these systems can and cannot do.

Data diversity and embodiment mismatch

Most VLAs are trained on a mix of simulated and real-world data, yet the transition between the two remains imperfect. Simulators can model physics and visuals convincingly, but they often fail to capture the noise, friction, and unpredictability of real environments. A model that performs flawlessly in a digital warehouse may struggle when the lighting shifts or when objects reflect glare. Bridging that gap requires better domain randomization and richer multimodal datasets, efforts that are costly and slow to produce.

Real-time inference and scaling

Transformer-based architectures, while expressive, are computationally heavy. Running them on embedded processors in drones, vehicles, or handheld devices introduces latency that can turn a safe maneuver into a delayed one. Hardware acceleration and model compression offer partial relief, but they tend to trade precision for speed. As a result, developers often find themselves balancing the elegance of large architectures against the practical constraints of real-world deployment.

Standardization and interoperability

The field lacks shared evaluation pipelines, cross-platform APIs, and common action representations. Each research group defines its own interface for connecting perception, language, and control, which makes collaboration cumbersome. Without open standards, progress risks becoming fragmented, with isolated breakthroughs rather than collective advancement.

Read more: Sensor Fusion Explained: Why Multiple Sensors are Better Than One

Recommendations for Vision-Language-Action Models

Several pragmatic steps could help researchers, policymakers, and industry teams build models that are not only capable but also dependable.

Explainability-by-design

 Instead of treating interpretability as an afterthought, researchers could embed mechanisms that allow VLA systems to express their reasoning in natural language or symbolic form. This would make it easier to audit decisions and trace errors after deployment. The approach is already being tested in some robotics labs, where models are prompted to “verbalize” their intent before acting, a surprisingly effective safeguard against unsafe or ambiguous behavior.

Open Benchmarking and Evaluation

Independent initiatives like VLATest are valuable, but they need institutional backing and community participation to gain legitimacy. The field could benefit from a consortium-driven framework similar to how the ImageNet challenge standardized computer vision research a decade ago. Benchmarks that measure not just accuracy but also robustness, adaptability, and safety could create more accountability and accelerate meaningful progress.

Edge Optimization

Many autonomy systems rely on hardware with strict power and latency limits. Developing compact or hierarchical VLA architectures, where smaller sub-models handle local decisions while larger models manage higher-level reasoning, could help balance responsiveness with depth of understanding. Progress here will likely depend on collaboration between model designers, chip manufacturers, and system integrators.

Academic–Industry Partnerships

The gap between laboratory success and real-world deployment remains wide, and bridging it requires joint investment. Companies working on logistics, autonomous mobility, or industrial robotics could collaborate with universities to co-develop datasets, share evaluation metrics, and test transfer learning strategies. These partnerships should also include ethicists and regulatory advisors, ensuring that safety and accountability are part of the design process rather than afterthoughts.

How We Can Help

As Vision-Language-Action models transition from research labs into real-world deployments, the biggest barrier is not the algorithms themselves but the data they depend on. High-quality multimodal data, visual, textual, and sensor-based, is the foundation that allows these models to learn how to perceive, reason, and act coherently. This is where Digital Divide Data (DDD) plays a crucial role.

DDD specializes in end-to-end data lifecycle management for AI systems, helping organizations prepare, annotate, and validate the kind of complex, multimodal datasets that modern VLA models require. Our teams have deep experience working with visual, spatial, and linguistic data at scale, ensuring that every data point is accurate, contextual, and ethically sourced. Whether the goal is to train a model to interpret traffic scenes for autonomous driving or to fine-tune a robotic control policy on language-guided tasks, we provide the structure and human expertise needed to make that data usable and trustworthy.

Read more: The Pros and Cons of Automated Labeling for Autonomous Driving

Conclusion

Vision-Language-Action models represent more than another step in AI development; they mark a structural shift in how machines connect perception with behavior. For years, autonomy depended on pre-defined logic and hand-crafted control rules. Now, with VLAs, systems can learn from examples, interpret ambiguous instructions, and adapt to new situations with minimal retraining. It is a subtle but powerful change: autonomy is no longer just about automation, it is about understanding context and responding intelligently to it.

What is clear is that Vision-Language-Action models have expanded the vocabulary of autonomy itself. They have turned passive observation into interactive understanding, and in doing so, they have redrawn the boundary between human direction and machine initiative. The future of autonomy will belong to those who can balance this new capability with rigor, transparency, and care.

Partner with Digital Divide Data to build the data foundation for safer, smarter, and more context-aware autonomous systems.


References

DeepMind. (2024, January). Shaping the future of advanced robotics. DeepMind Blog. https://deepmind.google/

Google Research. (2023, October). Open X-Embodiment: Robotic learning datasets and RT-X models. arXiv:2310.XXXXX.

Zhou, X., Liu, M., Yurtsever, E., Zagar, B. L., Zimmer, W., Cao, H., & Knoll, A. C. (2023). Vision-language models in autonomous driving: A survey and outlook. arXiv. https://arxiv.org/abs/2310.14414

Kawaharazuka, K., Oh, J., Yamada, J., Posner, I., & Zhu, Y. (2025). Vision-language-action models for robotics: A review towards real-world applications. arXiv. https://arxiv.org/abs/2510.07077

Guruprasad, P., Sikka, H., Song, J., Wang, Y., & Liang, P. P. (2024). Benchmarking vision, language, & action models on robotic learning tasks. arXiv. https://arxiv.org/abs/2411.05821


Frequently Asked Questions

Q1. Are Vision-Language-Action models a form of general artificial intelligence?
Not exactly. While VLAs integrate perception, reasoning, and action, they are still specialized systems. They excel at sensorimotor coordination and contextual reasoning but remain limited to the domains and data they were trained on. They represent a step toward more general intelligence, not its arrival.

Q2. How do VLAs compare to reinforcement learning systems?
Reinforcement learning focuses on trial-and-error optimization for specific tasks. VLAs, in contrast, combine large-scale multimodal learning with grounded control. They often use reinforcement learning for fine-tuning but start from a foundation of language and vision pretraining, which gives them broader adaptability.

Q3. What industries are most likely to adopt VLA models first?
Autonomous mobility, industrial robotics, and defense are leading adopters because they already rely on perception-action loops. However, healthcare, logistics, and service robotics are rapidly experimenting with language-guided systems to improve flexibility and user interaction.

Q4. Are there ethical risks specific to VLA systems?
Yes. Because these models interpret and act on natural language, misinterpretation can lead to unintended behavior. Privacy issues also arise when they operate in human environments with cameras and microphones. Ethical deployment requires transparent decision logging and consistent human oversight.

Vision-Language-Action Models: How Foundation Models are Transforming Autonomy Read Post »

ISRFusion

How ISR Fusion Redefines Decision-Making in Defense Tech

ISR fusion is the integration of data from diverse domains, space, air, land, sea, cyber, and even open-source intelligence, into a unified operational picture. It brings together information from drones, satellites, ground-based sensors, cyber monitoring systems, and social media feeds, creating an interconnected intelligence ecosystem. The value lies not just in the volume of data collected, but in the ability to analyze and correlate it quickly using advanced tools such as artificial intelligence and machine learning.

This shift is redefining how decisions are made in defense environments. Instead of commanders sifting through fragmented data streams, fused ISR provides actionable intelligence in near real time. It reduces latency between detection and response, enhances predictive capabilities, and supports interoperability across allied forces.

In this blog, we will explore what ISR fusion is and why it matters, examine its advantages and the decision-making shifts it enables, and assess the challenges and risks that come with implementation.

The Evolving Defense Landscape

Modern conflict unfolds across a multidomain environment that stretches from the seabed to space and extends into cyberspace and the information domain. Land, sea, air, cyber, and space operations are increasingly interlinked, with actions in one domain triggering consequences across others. This interconnected battlespace demands a level of situational awareness and responsiveness that traditional ISR systems were never designed to deliver.

The speed of emerging threats is compounding the challenge. Hypersonic weapons can travel at several times the speed of sound, compressing decision timelines to mere minutes. Artificial intelligence is being used by adversaries to automate disinformation campaigns, cyber intrusions, and even battlefield deception. In parallel, the rise of autonomous systems, from drone swarms to cyberbots, creates highly dynamic and unpredictable scenarios that require constant monitoring and rapid response.

Adding to this complexity is the overwhelming volume of raw data that defense organizations must process. Modern ISR assets, from satellites and high-altitude drones to ground-based sensors and naval radar, generate petabytes of information every day. Without effective integration and filtering, this abundance of data becomes a liability rather than an advantage. Commanders risk being inundated with uncorrelated inputs, slowing decision-making at precisely the moment when speed is most critical.

This evolving defense landscape has made it clear that relying on isolated data streams and sequential analysis is no longer sufficient. To maintain decision superiority, militaries require systems that can synthesize diverse intelligence sources into coherent, timely insights. This is the environment in which ISR fusion has become not only relevant but indispensable.

What is ISR Fusion?

ISR fusion refers to the process of integrating intelligence, surveillance, and reconnaissance data from a wide array of sources into a single, coherent operational picture. Unlike traditional ISR, which relied on sequential collection and compartmentalized analysis, fusion emphasizes simultaneity, correlation, and cross-domain awareness. The aim is to transform fragmented sensor feeds into unified intelligence that is directly actionable for commanders.

At the heart of ISR fusion is data integration. Modern defense operations collect inputs from satellites, unmanned aerial vehicles, maritime radars, ground-based sensors, cyber monitoring platforms, and even open-source channels. Each of these generates valuable but incomplete snapshots of the operational environment. When viewed in isolation, they risk leaving critical gaps. Fusion bridges those gaps by aligning and correlating disparate streams so that patterns, anomalies, and threats emerge with greater clarity.

Artificial intelligence and machine learning play a central role in this process. Algorithms can filter out noise, detect correlations invisible to human analysts, and prioritize information based on operational relevance. For instance, an AI system can match radar tracks with satellite imagery and electronic signals to confirm whether a fast-moving object is a commercial aircraft, an adversarial drone, or a hypersonic missile. This automation not only accelerates analysis but also increases confidence in the accuracy of intelligence.

Cloud and edge architectures further enable ISR fusion. Data can be processed locally at the edge, close to the sensor, to support time-sensitive decisions such as air defense responses. At the same time, centralized cloud platforms can integrate larger datasets for strategic assessments. This dual processing model ensures that fused ISR supports both tactical agility and long-term planning.

Advantages of ISR Fusion in Defense Tech

ISR fusion offers defense organizations a series of advantages that go beyond incremental improvements in intelligence gathering. It fundamentally changes the way information is processed, shared, and acted upon, providing measurable gains in both speed and effectiveness.

Acceleration of decision cycles

By correlating data from multiple sensors in near real time, ISR fusion reduces the time between detection and response. Commanders no longer have to wait for siloed reports to be compiled and cross-checked. Instead, fused intelligence delivers a holistic picture that enables immediate action, a capability that is vital in environments where hypersonic weapons or cyberattacks can unfold within minutes.

Enhanced situational awareness

ISR Fusion enables defense forces to see across domains simultaneously, capturing the interactions between air, land, sea, cyber, and space activities. This multidomain perspective helps to uncover threats that might remain hidden in single-sensor analysis. For example, a radar track might appear unremarkable until it is correlated with satellite imagery and electronic signal data that together reveal an adversarial pattern of movement.

Coordination across allied forces

In multinational operations, the ability to share and interpret fused intelligence in standardized formats ensures that all participants operate from a common picture of the battlespace. This reduces misunderstandings, enhances interoperability, and supports more cohesive action, particularly in coalitions, where diverse systems must function as one.

Resilience against adversarial tactics

ISR fusion mitigates risks by combining data from multiple independent sources, making it harder for an adversary to distort the overall picture. By verifying signals against other inputs, fusion strengthens confidence in the integrity of the intelligence.

Read more: How Administrative Data Processing Enhances Defense Readiness

Core Decision-Making Shifts Enabled by ISR Fusion

The integration of ISR fusion into defense operations is not simply about faster data processing. It redefines how decisions are made across the tactical, operational, and strategic levels of command. Four critical shifts illustrate this transformation.

From data to decision

Traditional ISR systems often left commanders drowning in raw information with limited tools for synthesis. Fusion changes this dynamic by applying AI and advanced analytics to vast data streams, turning them into intelligence products that are immediately usable. The result is a direct path from collection to decision, without the bottlenecks of manual correlation and delayed reporting.

From centralized to distributed command

In the past, ISR outputs were funneled up to centralized headquarters, where senior staff interpreted them before issuing guidance to units in the field. This model introduced time lags that could prove costly in fast-moving operations. With ISR fusion, edge processing delivers actionable intelligence directly to tactical commanders, enabling them to make informed decisions autonomously while still aligning with overall mission objectives.

From reactive to predictive

Instead of waiting for adversary actions to unfold, fused ISR enables forces to anticipate them. Machine learning models identify patterns and anomalies that may indicate hostile intent, such as unusual troop movements or shifts in electronic signatures. Predictive intelligence allows commanders to prepare countermeasures in advance, turning defense into a proactive rather than a reactive effort.

From siloed to interoperable

Perhaps the most transformative shift is the ability to create a shared operational picture across services and allied nations. ISR fusion standardizes data into formats that can be easily exchanged and interpreted across platforms. This ensures that intelligence originates from the same coherent view. Such interoperability strengthens coalition decision-making and ensures collective readiness in complex joint operations.

Challenges and Risks in ISR Fusion

While ISR fusion offers unprecedented opportunities to improve defense decision-making, it also introduces new complexities that must be carefully managed. These challenges are not purely technical but extend into organizational, ethical, and strategic domains.

Information overload versus decision overload

ISR Fusion is designed to filter and simplify massive data streams, but poorly configured systems can still overwhelm commanders with too much information. The risk is that decision-makers may face paralysis at critical moments if the intelligence presented is not prioritized or contextualized effectively. Balancing comprehensiveness with clarity remains a key challenge.

Bias in AI fusion models

Machine learning algorithms are only as good as the data on which they are trained. If datasets contain errors, omissions, or inherent biases, fused outputs may misclassify threats or misrepresent battlefield realities. In a high-stakes environment, such errors can lead to flawed decisions with strategic consequences. Addressing bias through rigorous validation and diverse training data is essential.

Interoperability gaps across allied systems

One of the greatest promises of ISR fusion is interoperability across services and nations. Yet, differences in data standards, classification levels, and proprietary systems remain significant barriers. Without harmonization, fusion efforts risk creating fragmented pictures that limit coalition effectiveness.

Governance and ethics

As AI plays a larger role in fusing intelligence, the question of accountability becomes more pressing. How much autonomy should machines have in identifying threats or recommending actions? Ensuring that human oversight remains central is not only an ethical obligation but also a safeguard against unintended escalation. Establishing clear rules of engagement for human–machine collaboration is vital to maintaining trust.

How We Can Help

The promise of ISR fusion depends on more than advanced sensors and algorithms. It requires clean, structured, and reliable data that can be trusted to drive decisions in complex environments. This is where Digital Divide Data (DDD) plays a critical role.

Data preparation and annotation

AI-driven ISR systems rely on well-labeled datasets to identify and classify objects, signals, and patterns with accuracy. DDD provides large-scale data annotation services, including image, video, and signal labeling, ensuring that fusion models are trained on high-quality datasets.

Multilingual open-source intelligence support

ISR fusion increasingly incorporates open-source data, much of it generated in diverse languages and cultural contexts. DDD’s multilingual expertise allows this information to be structured, translated, and contextualized for defense applications, expanding the scope of intelligence inputs while maintaining precision.

Human-in-the-loop validation

Even the most advanced AI models require human oversight to ensure that their outputs are valid and error-free. DDD supports human-in-the-loop workflows that combine machine efficiency with human judgment, creating a safeguard against bias and misclassification in ISR fusion pipelines.

Scalable data operations

Defense organizations often face the challenge of scaling data workflows without sacrificing quality or speed. DDD has the operational infrastructure to support high-volume, time-sensitive projects, making it a trusted partner for missions where reliability and responsiveness are paramount.

DDD ensures that the data foundations of ISR fusion are both strong and dependable.

Conclusion

ISR fusion marks a fundamental turning point in how defense organizations make decisions. Where traditional ISR provided fragmented streams of data that had to be pieced together manually, fusion delivers a coherent and actionable operational picture at the speed of modern conflict. This transformation enables commanders to move from reacting to threats after they emerge to anticipating and countering them before they materialize.

ISR fusion is the foundation of decision dominance in the era of AI-driven conflict. Militaries that can integrate diverse intelligence streams, secure them against disruption, and build trust between human operators and machine analysis will hold a decisive advantage. Those that fail to adapt risk being overwhelmed by both the speed and complexity of tomorrow’s battlespace.

Partner with Digital Divide Data to transform raw ISR streams into structured, actionable intelligence that powers faster and more reliable defense decisions.


References

Defence Science and Technology Laboratory. (2024, October). Designing Defence’s next-generation multi-satellite system. UK Ministry of Defence. https://www.gov.uk/dstl

Defence Science and Technology Laboratory. (2025, September 10). Building the digital targeting web. UK Ministry of Defence. https://www.gov.uk/dstl

RAND Corporation. (2025). Improving sense-making with AI: A roadmap for the Department of the Air Force. RAND Corporation. https://www.rand.org


FAQs

Q1. How does ISR fusion differ from traditional command and control systems like C4ISR?
C4ISR encompasses command, control, communications, computers, intelligence, surveillance, and reconnaissance. ISR fusion is a subset that focuses specifically on integrating and correlating intelligence data streams. While C4ISR provides the broader framework, fusion is what makes the intelligence component faster, more reliable, and interoperable.

Q2. Can ISR fusion be applied outside of military contexts?
Yes. Civilian applications include disaster response, border security, critical infrastructure protection, and counter-terrorism. By integrating data from drones, satellites, and open-source channels, ISR fusion can help first responders and security agencies make faster and more accurate decisions.

Q3. What role does commercial technology play in ISR fusion?
Commercial satellite operators, AI vendors, and cloud service providers supply many of the tools and platforms that defense organizations integrate into ISR fusion pipelines. This accelerates innovation but also raises concerns about dependency, resilience, and security in high-threat environments.

Q4. How do militaries address data classification challenges in multinational fusion?
Nations often use layered classification systems and secure federated architectures that allow allies to share relevant intelligence without disclosing sensitive national sources. NATO’s federated sensor initiatives are an example of how classification barriers can be managed while preserving coalition effectiveness.

Q5. What are the future frontiers of ISR fusion?
Emerging areas include quantum sensing, drone swarms feeding into fusion networks, and the use of digital twins for simulating battlespace conditions before deployment. These innovations will push ISR fusion from real-time awareness toward anticipatory decision-making on a global scale.

How ISR Fusion Redefines Decision-Making in Defense Tech Read Post »

image2B252842529

MassRobotics and Digital Divide Data Partner to Accelerate the Future of Robotics and Autonomy

MassRobotics, the largest independent robotics innovation hub, and Digital Divide Data (DDD), a global leader in human-in-the-loop services for AI and autonomy, today announced a new associated network partnership designed to help robotics companies move faster, smarter, and with greater confidence.

Robotics and autonomous systems depend on accurate data, validated models, and the ability to handle tricky real-world scenarios. DDD brings years of experience providing human-in-the-loop services, such as data annotation, sensor validation, perception training, and edge-case review, that are critical to making robots safer and more reliable. By teaming up with MassRobotics, DDD will support the startups and scaling companies in the MassRobotics community as they bring next-generation robotics to market.

Why This Partnership Matters

  • For robotics startups: Access to proven, scalable human-in-the-loop services that can reduce development time and strengthen autonomy performance.

  • For DDD: A chance to work side by side with innovators solving the hardest challenges in robotics and autonomy, applying its expertise where it can have the most impact.

Leadership Perspectives

“MassRobotics is thrilled to welcome Digital Divide Data as an Associated Network Partner. Their deep expertise in AI and data operations brings invaluable support to our startup community, helping companies scale smarter and faster. This collaboration strengthens our ecosystem and empowers the next generation of robotics innovators to grow even bigger and bolder.”

 – Colleen Anderson, Director, Community and Events, MassRobotics

“We’re thrilled to partner with MassRobotics and be a value added member of their extended robotics community. Boston is a long-time hotspot for innovation and technology, and we strongly believe that this relationship will let us expand our Data Operations business with more of such advanced tech companies in Physical AI, Robotics and ML-CV space. Much more to come!”

 – Sahil Potnis, VP Product and Partnerships, Digital Divide Data Leadership

About MassRobotics

MassRobotics is the world’s largest independent robotics hub dedicated to accelerating robotics innovation, commercialization and adoption. Our mission is to help create and scale the next generation of successful robotics and Physical AI technology companies by providing entrepreneurs and startups with the workspace, resources, programming and connections they need to develop, prototype, test and commercialize their products and solutions. While MassRobotics originated and is headquartered in Boston, we are reaching and supporting robotics acceleration and adoption globally and are working with startups, academia, industry and governments both domestically and internationally.

About Digital Divide Data

Digital Divide Data (DDD) is a global leader in human-in-the-loop services for AI, robotics, and autonomy. With expertise in data annotation, sensor validation, perception model training, and real-time edge-case intervention, DDD supports leading technology companies in building safe, scalable, and reliable autonomous systems.

Media Contact: Preeti Srivastava (preeti.srivastava@digitaldividedata.com)

MassRobotics and Digital Divide Data Partner to Accelerate the Future of Robotics and Autonomy Read Post »

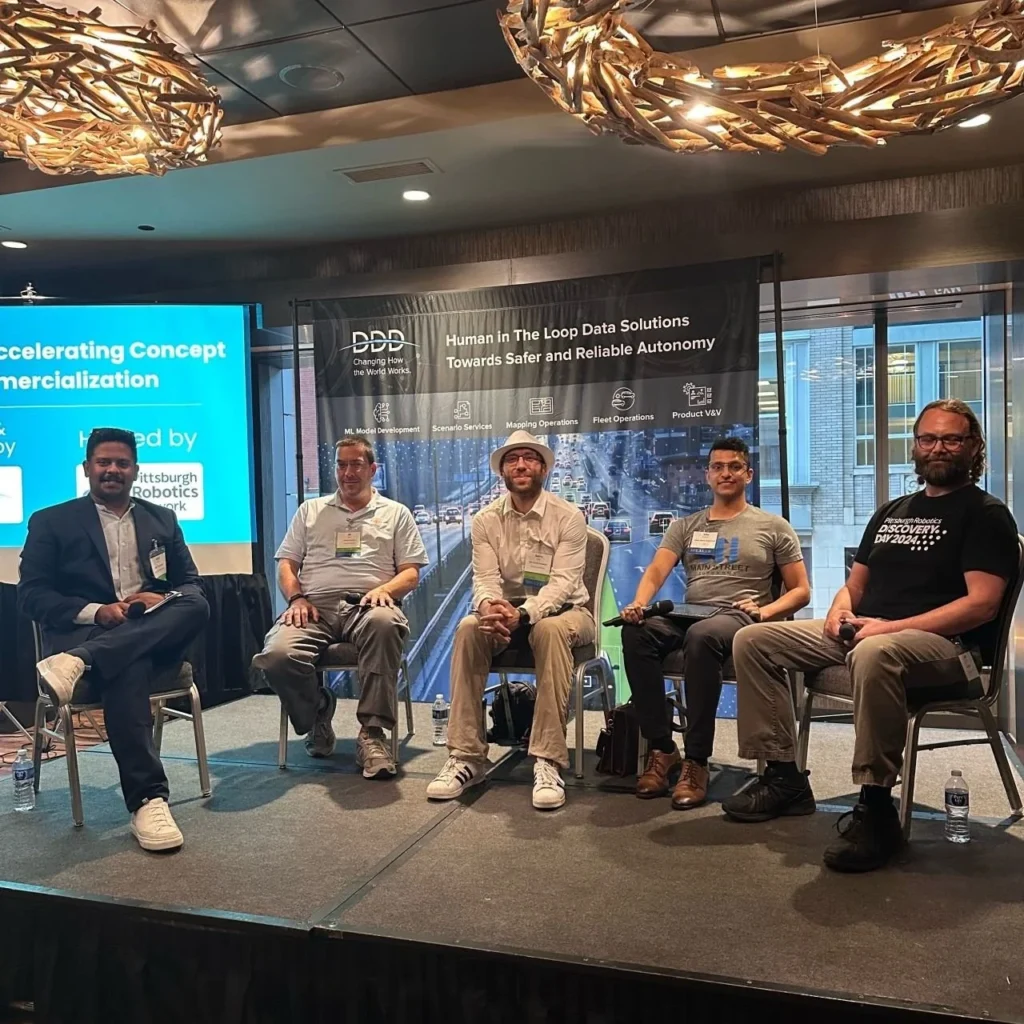
Panel discussion on Physical AI, robotics, and autonomous systems at a Pittsburgh industry event

Physical AI: Accelerating Concept to Commercialization – Post Event Briefings

Digital Divide Data (DDD) in collaboration with the Pittsburgh Robotics Network (PRN) hosted an evening full of robotics and physical AI conversations in Pittsburgh last month. The event was structured around a panel of experts from different Autonomous Systems’ areas and moderated by Sahil Potnis, VP of Product and Partnerships at DDD. The panel consisted of Al Biglan, Head of Robotics at Gecko Robotics; Barry Rabkin, Director of Marketing at Near Earth Autonomy; Jake Panikulam, CEO at Mainstreet Autonomy and Jeff Johnson, CTO at Mapless AI.

This event was all about how smart machines, like self-driving cars and robots, are starting to show up in everyday life. The term Physical AI just means using artificial intelligence in things that move or do physical work, not just computer programs. These machines are becoming more common in places like factories, warehouses, roads, and homes. As this technology grows, it is important to understand not just how it works, but how it fits into real life and helps people in meaningful ways.

The opening keynote was a message from Sameer Raina, DDD CEO and President, about making sure more people have access to specialized jobs in tech. DDD helps people from underrepresented communities get experience in technology by doing important work, like organizing and labeling data that AI systems use to learn. DDD’s mission is to make sure that the rise of AI creates opportunity for everyone, not just a few. This includes veterans, people from low-income backgrounds, and others who may not normally have a way into the tech world. The panel then talked about what it really takes to go from an idea or a concept to a working commercial product. One of the big takeaways was that trying to build everything yourself can slow you down. It is better to team up with others, focus on what you are best at, and get to the finish line faster and more efficiently. Collaboration is not a weakness, it is a smart strategy to build the right ecosystem.

Another big topic was data. A lot of companies collect more information than they know what to do with. Sometimes they stop tracking things too early, or they toss out data that turns out to be really useful later. When handled the right way, that data can help fix problems, improve safety, and make smarter decisions. In some cases, it can even point to issues that engineers didn’t realize were happening. The panel encourages everyone to think of data as a powerful tool that can make or break a project. The panel also talked about how important it is to think beyond the tech. Just building something cool is not enough. You have to understand who will use it, explain it clearly, and make sure it actually solves a problem. Good planning, strong partnerships, and real communication are just as important as the machine itself.

Looking to the future, everyone agreed that we will see more smart machines all around us. Not to replace people, but to work with them making things easier, safer, and more helpful in daily life. The big message was that for physical AI to succeed, it needs to be useful, trusted, and built with people in mind. With the right mindset, teamwork, and purpose, physical AI can help improve everyday life for all kinds of communities.

The diversity of the panel was very much visible and appreciated by the audience. We ended the evening with a common sentiment of organizing more of such panel talks! Onward to more of such exciting events.

Physical AI: Accelerating Concept to Commercialization – Post Event Briefings Read Post »

Humanoids2BDDD

Building Better Humanoids: Where Real-World Challenges Meet Real-World Data

Humanoids don’t get a practice round. The minute they step into a warehouse, interact with humans, or navigate an unstructured environment, we expect them to perform safely, reliably, and without the luxury of trial and error that defined earlier robotics generations.

Despite these high stakes, momentum in the humanoid industry is exciting. Major players are moving from lab prototypes to real commercial pilots, and the early results look promising.

Amazon is piloting Agility’s Digit humanoid robots for material handling at Amazon warehouses, focusing on tote recycling and movement in dynamic environments. In 2022, Agility raised $150M, with Amazon’s Industrial Innovation Fund participating.

Figure’s humanoid robot, Figure 01, completed its first autonomous warehouse task in 2024, picking and placing objects. Figure AI has raised more than $675M from investors including Microsoft, OpenAI, and Nvidia. Meanwhile, Sanctuary’s Phoenix robot has been deployed in retail environments for tasks like stocking shelves and folding clothes, completing a world-first commercial deployment at a Canadian Tire store in 2023.

But these early wins tell only part of the story. Commercial readiness still lags way behind the headlines. Most humanoids today work only under carefully controlled conditions. When they succeed, it’s usually because someone spent weeks tuning the environment to match the robot’s quirks, not because the robot adapted to the real world.

That gap between viral demos and deployable systems is still wide. And companies betting big on humanoid technology are learning that brilliant engineering alone won’t bridge it. You need rock-solid validation systems that prove your robot works before you ship it, not after something goes wrong.

The biggest bottleneck? Real-world testing is brutally expensive and risky. Industry experts estimate that physical robot testing can cost $10,000 to $100,000 per week, according to a 2023 survey of robotics startups. Beyond the expense, real-world environments are inherently limited—no single warehouse, military base, or factory floor can expose a humanoid to the breadth of conditions it will eventually face. And when things go wrong, they go wrong fast. A 2022 OSHA report cited that 40% of warehouse automation incidents involved robots colliding with objects or people.

Smart teams are working around these challenges by leaning hard into simulation, synthetic data, and human-in-the-loop workflows, not as backup plans, but as the foundation of a scalable robotics pipeline that actually works in messy, complicated, human environments.

Key Challenges in Humanoid Robotics

Building deployable humanoids isn’t just a mechanical problem. It’s a systems-level challenge that spans perception, decision-making, human interaction, and safety validation. The hurdles standing between promising prototypes and scalable, field-ready platforms are distinct but interconnected challenges.

Cluttered and unpredictable environments

Human environments are cluttered, inconsistent, and emotionally charged. Imagine a humanoid stepping into a busy warehouse and immediately encountering a spilled box of screws. Someone shouts “Watch out!” from across the floor. A coworker extends a hand, but are they offering or asking for help? These moments happen dozens of times every shift, yet they’re not the dramatic edge cases that make headlines. They’re Monday through Friday realities. Teaching a robot to navigate them is where things get complicated.

Here’s the thing: Industrial robots have it easy. They work in controlled, predictable spaces where everything has its place. But humanoids? They’re stepping into our messy, intuitive world. A warehouse worker spots a tilted pallet and immediately thinks “danger.” A maintenance tech reads someone’s slumped shoulders and knows they need backup. These insights come from years of human experience, the kind of pattern recognition that doesn’t fit neatly into code.

The need for generalists instead of specialists

Most robots today are specialists; they excel at one task under predictable conditions. Humanoids need to be generalists who can switch between tasks, adapt to new layouts, and work with incomplete information. As Pieter Abbeel of Covariant AI has noted, robots typically fail not because they can’t perform a task, but because they struggle to adapt when conditions change even slightly.

Training for this kind of flexibility requires exposure to thousands of scenarios, including the rare and ambiguous ones that break most systems. That’s driving the shift toward synthetic data and curated scenario libraries. Companies like Covariant AI and Boston Dynamics report that up to 80% of their robot training data now comes from simulation and synthetic environments, not real-world trials.

And here’s where it gets tricky, because synthetic data quality makes or breaks everything. The difference between a functional prototype and a deployable humanoid is annotation precision. Your annotators must correctly label every sensor input: LIDAR point clouds, RGB feeds, depth maps, so the robot learns to distinguish between a cardboard box and a crouched human, between someone waving hello and someone signaling distress. It’s not basic labeling work. You need annotators with deep robotics knowledge and an understanding of human behavior patterns.

But annotation precision is just one piece of the puzzle. The generalist challenge goes beyond perception. Humanoids working alongside people need social intelligence, knowing when to pause, when to ask for help, and when to step back entirely. Training for those protocols calls for data that captures how humans actually behave under stress, fatigue, and time pressure. Not easy stuff to synthesize.

The cost and risk of real-world testing

The economics of physical testing create a brutal bottleneck as well. At such high costs, extensive real-world testing quickly becomes a luxury only the most well-funded teams can afford. And those numbers don’t even include the hidden costs, damaged equipment, stalled operations, and even safety incidents that shut down entire facilities.

Cost isn’t the only problem. Real-world testing environments are fundamentally limited. Your single warehouse can’t expose a robot to every lighting condition, floor texture, or human interaction pattern it might encounter across different facilities. A retail pilot can’t capture the full spectrum of customer behaviors or how seasonal merchandise changes affect navigation.

Those examples show exactly why smart teams are turning to simulation as more than just a backup plan. As MIT reports, a 2024 study in Science Robotics found that robots trained with a mix of synthetic and real data performed 30% better in novel scenarios than those trained only on real-world data. The breakthrough insight? Synthetic environments let you systematically explore edge cases that would be rare, expensive, or downright dangerous to recreate physically.

But the catch is that your synthetic data is only as good as the human expertise behind it. Creating realistic scenarios means understanding not just what objects look like, but how they behave under different conditions, how shadows mess with object recognition, how human posture shifts when someone’s exhausted versus alert, and how environmental factors throw off sensor readings. That level of nuance requires expert annotators who get both the technical requirements and the messy realities of deployment.

Simulation limitations and validation gaps

The most advanced robotics teams are pushing beyond basic simulation toward sophisticated digital twin environments that mirror real-world complexity. Boston Dynamics uses a hybrid approach: real-world testing at its Waltham, MA facility and extensive simulation of its Atlas robot’s acrobatic movements, like jumping and navigating obstacles.

But even the most sophisticated simulation needs HITL validation to make sure synthetic training actually translates to human-compatible behavior. In 2024, Figure AI partnered with OpenAI to use large language models for robot planning and HITL review, allowing humans to intervene and provide feedback during ambiguous tasks. This partnership illustrates a broader trend in the industry.

The HITL approach extends far beyond real-time intervention. It’s also critical for comprehensive data curation and labeling. Expert annotators review robot behavior, label edge cases, and provide the contextual understanding that bridges algorithmic decision-making and human expectations. You need annotators who don’t just see what’s happening, but understand what it means for robot safety and performance in the real world.

Covariant AI’s robots use reinforcement learning in simulation, plus human-in-the-loop feedback to correct errors and improve generalization. The human expertise in this loop is less about fixing mistakes and more about encoding a nuanced understanding of human environments into training data that robots can actually learn from.

This approach scales beautifully. Teams can create thousands of scenario variations: lighting changes, obstacle placements, human behavior patterns, and stress-test performance at a massive scale. HITL review sharpens those models further, helping robots learn both to execute tasks and to align with human expectations.

The validation challenge gets even trickier when you consider system-wide reliability. As Gill Pratt, CEO of Toyota Research Institute, has noted, the real world is full of edge cases. You can’t anticipate them all, but you can build systems that learn from them.

So, where do edge cases leave the industry? The path forward is becoming clearer.

What’s Next for Humanoid Robotics

The leap from prototype to product in humanoid robotics isn’t about better joints or faster processors. It’s about nailing the real-world stack: perception, planning, actuation, and human alignment, all working together seamlessly.

Sensor calibration will matter more than ever

Picture a humanoid walking the same hallway 10 times and hitting 10 lighting conditions. Can its vision systems still spot a dropped wrench or tell a crouched worker from a cardboard box? Most current sensor fusion approaches assume you’re working in controlled environments. Real deployment calls for systems that self-calibrate and maintain performance across wildly variable conditions.

Sensor calibration is where high-quality training data becomes critical. Your robots need exposure to thousands of object examples under different lighting, from various angles, in multiple contexts, all precisely labeled by experts who understand the subtle differences that actually matter for robot perception. But even perfect sensors need the right training foundation.

Simulation will continue to scale training and testing

Simulation’s value depends entirely on realism and relevance, making scenario curation based on actual field data and human review a core competency for robotics teams. The numbers back it up: Experts project that the global humanoid robot market will grow from $1.8B in 2023 to $13.8B by 2030, at a CAGR of 33.5%. Teams that can validate performance at scale will capture disproportionate value in this expanding market. All of this progress, however, will require new approaches to validation.

The need for new validation tools is increasing

The ISO 10218 and ISO/TS 15066 standards govern industrial robot safety, but as of 2025, no unified standard exists for humanoids in mixed human-robot environments. As humanoids grow more capable, their potential impact, good or bad, grows with them. Proving your system can recover from unexpected inputs or respond to emergent events isn’t optional. It’s table stakes.

The reality is that innovation is accelerating, but validation tools, coverage metrics, and scalable feedback loops are lagging. Until that gap closes, your deployment will be gated not by what humanoids can do in the lab, but by what they can prove in the field.

The most innovative teams already treat validation as a competitive advantage, not just a compliance headache. They’re using simulation to both train robots and build a systematic understanding of how human-robot collaboration works under pressure. They’re using HITL workflows to both fix errors and encode human intuition into scalable systems.

The companies that dominate this space will be those with access to the highest-quality labeled data, data that captures not just what objects look like but also how they behave, how humans interact with them, and how robots should respond. This level of data quality calls for specialized expertise in data annotation, scenario curation, and human-robot interaction patterns.

Closing Thoughts: Humanoids Outside the Lab

The dream of humanoids helping in hospitals, warehouses, and disaster zones is closer than ever. But we won’t get there by skipping the hard parts. We’ll get there by meeting complexity with clarity, and novelty with rigor.

At DDD, we specialize in high-quality data annotation and human-in-the-loop review that makes safe, reliable humanoid deployment possible. From complex video and sensor data labeling to scenario curation and expert review, we’re here to help your robotics teams build the data foundation systems you need to succeed in real-world environments. If you’re building, testing, or deploying such systems, let’s talk.

Capability alone will not define the next era of robotics. Context, data, and collaboration will, and the time to shape it is now.

Building Better Humanoids: Where Real-World Challenges Meet Real-World Data Read Post »

Objectdetection

Facial Recognition and Object Detection in Defense Tech

In a high-stakes defense environment, the speed and accuracy of information can define the outcome of missions, protect national borders, and save lives. Among the most critical enablers are facial recognition and object detection technologies.

These AI-driven systems are no longer confined to experimental labs or civilian applications; they are becoming central to how the military manages surveillance, secure facilities, conduct reconnaissance, and make tactical decisions in real time.

Facial recognition allows security forces to identify persons of interest across vast datasets, video feeds, and live drone surveillance, enabling more proactive threat detection and response. Object detection, on the other hand, powers everything from automated monitoring of suspicious vehicles and unattended baggage to identifying targets in combat zones. Whether deployed in UAVs scanning for threats over hostile terrain or in fixed-location cameras guarding critical infrastructure, these technologies form the backbone of a modern defense ecosystem that depends on automation for both strategic intelligence and real-time decision-making.

This blog explores how facial recognition and object detection in defense tech are transforming surveillance, threat detection, and decision-making. While also navigating challenges and recommendations, shaping their deployment.

Facial Recognition in Defense Tech

Facial recognition systems have rapidly evolved into indispensable tools for defense and security operations. Their applications extend beyond traditional surveillance, offering critical capabilities in identity verification, border control, watchlist monitoring, and mission-specific intelligence. However, as these systems mature, so do the tactics designed to undermine them, requiring equally advanced countermeasures and ongoing attention to legal and ethical implications.

Adversarial Attacks & Defenses

One of the most significant challenges facing facial recognition in defense is the emergence of adversarial attacks designed to fool AI systems. Cloaking techniques, which involve subtly altering a person’s appearance using algorithmically generated patterns, can render facial recognition systems ineffective. These patterns, often invisible to the human eye, are crafted to manipulate the model’s feature extraction layers, preventing accurate identification or causing deliberate misclassification.

To counter such threats, new defense systems are being developed that aim to purify the training data and harden recognition models against cloaked inputs. Among the most notable advancements is a training-time purification approach that filters out adversarial noise before it can corrupt the model. This method significantly reduces the success rate of cloaking attacks by refining the representation space, allowing the AI to learn more robust and generalized features. These defenses are particularly valuable in military systems that rely on long-term deployment in dynamic environments, where attackers may exploit open-source cloaking tools to bypass surveillance.

Cross-Spectrum Recognition

In operational scenarios where lighting is poor or visibility is limited, such as night-time patrols, covert surveillance, or operations in smoke-filled or foggy environments, traditional facial recognition systems based on visible light imagery become unreliable. To address these limitations, defense organizations are investing in cross-spectrum recognition technologies.

Cross-spectrum facial recognition leverages thermal-to-visible synthesis, a process that uses AI to generate a visible-light approximation of a thermal image. This allows standard recognition algorithms, trained on visible-light data, to function effectively even in complete darkness. By bridging the gap between thermal and visual spectrums, these technologies enable round-the-clock monitoring capabilities, particularly useful in perimeter defense, reconnaissance missions, and special operations conducted under low-light conditions.

Ethical & Legal Dimensions

As the use of facial recognition expands within defense tech operations, it raises critical questions around privacy, civil liberties, and accountability. Large-scale government surveillance programs, such as those managed by intelligence and law enforcement agencies, have sparked debate over the potential for misuse, biased algorithms, and a lack of transparency.

Programs run by defense tech have incorporated facial recognition into domestic and international intelligence workflows, often without full public disclosure or regulatory oversight. At the same time, research initiatives such as those under IARPA (Intelligence Advanced Research Projects Activity) aim to advance recognition capabilities to unprecedented levels of accuracy and scale.

The growing power of these systems has led to increasing calls for legislative guardrails and oversight mechanisms. Key concerns include the disproportionate impact of facial recognition errors on minority communities, the use of facial data without consent, and the potential for these tools to be used in ways that infringe on constitutional rights. For defense, maintaining public trust means not only building technically sound systems but also ensuring they are governed by clear policies, ethical frameworks, and transparent accountability structures.

Object Detection in Defense Tech

Object detection has become a cornerstone capability in modern defense operations, enabling automated systems to interpret visual data with speed and accuracy that surpasses human capability. From identifying potential threats in surveillance footage to guiding unmanned systems in complex combat environments, object detection plays a vital role in both strategic intelligence and real-time mission execution. As defense technology increasingly converges with AI, object detection is reshaping how information is gathered, targets are tracked, and operational decisions are made.

AI-Powered ISR & Targeting

Intelligence, Surveillance, and Reconnaissance (ISR) operations have traditionally relied on human analysts to interpret visual data collected from aerial and ground sensors. Today, AI-powered object detection systems are transforming ISR by automating the analysis of vast image and video datasets. One of the most prominent initiatives in this space is Project Maven, a U.S. Department of Defense program designed to integrate AI into battlefield decision-making. At the core of Project Maven is the ability to detect, classify, and track objects of interest, such as vehicles, weapons, or individuals, in drone footage and satellite imagery.

This automation dramatically accelerates the targeting cycle, reducing the time between identification and engagement of high-value targets. Object detection algorithms allow for real-time threat assessments, flagging suspicious movements or equipment without requiring constant human oversight. Beyond surveillance, object detection is also enabling advanced capabilities in unmanned ground vehicles (UGVs) and aerial systems. These platforms use AI to autonomously navigate terrain, track moving targets, and even assist in guiding munitions with high precision. In high-risk or GPS-denied environments, such autonomy can be critical to mission success and troop safety.

Adversarial Vulnerabilities

Despite its effectiveness, object detection is not immune to deception. Adversaries have developed techniques to exploit weaknesses in AI vision systems, most notably through patch-based adversarial attacks. These involve attaching carefully designed patterns, often resembling innocuous symbols or geometric shapes, to objects or vehicles to confuse or mislead detection algorithms. The result can be a failure to recognize a weapon, a misclassification of a hostile asset, or the complete evasion of automated tracking.

To counter these threats, defense researchers are developing inpainting-based defenses. These techniques aim to detect and digitally remove the adversarial patches from the input image before the object detection system processes it. By restoring a more “natural” visual representation, these defenses help the system recover its detection accuracy. In parallel, adversaries have also turned to more traditional forms of evasion such as camouflage, thermal masking, and concealment using foliage or terrain features. These low-tech countermeasures remain surprisingly effective, especially when combined with AI-targeted adversarial designs, underscoring the need for resilient, multi-modal detection systems.

System Integration & Ethics

As object detection systems become more integrated across defense platforms, their effectiveness increasingly depends on seamless fusion with other sensors and computing systems. Multi-modal integration, combining visible-spectrum cameras with thermal, infrared, radar, and acoustic sensors, provides a more comprehensive and reliable picture of the battlefield. Edge computing architectures allow this data to be processed locally on devices such as drones or autonomous vehicles, enabling low-latency decision-making even in disconnected or hostile environments. Predictive analytics further enhances these systems by using historical data and real-time observations to anticipate threats before they materialize.

However, the integration of object detection into weapons systems, particularly autonomous ones, raises profound ethical and legal questions. As lethal autonomous weapon systems (LAWS) become more capable, concerns about accountability, proportionality, and the risk of unintended engagements intensify. International discussions continue around the regulation or outright ban of fully autonomous weapons, with debates centered on the acceptable level of human control. For defense agencies, balancing technological advancement with ethical responsibility is critical, not only for compliance with international norms but also for maintaining legitimacy in the eyes of the global community.

Read more: Fleet Operations for Defense Autonomy: Bridging Human Control and AI Decisions

Challenges & Recommendations of Facial Recognition and Object Detection

Data Quality and Bias in Military AI

One of the most pressing challenges in deploying facial recognition and object detection in defense is the issue of poor data quality and model bias. AI systems trained on limited or non-representative datasets often perform inconsistently across different environments, lighting conditions, or demographic groups. In operational terms, this means identity mismatches in facial recognition or misclassification of key objects in surveillance feeds.

The recommendation here is to build more robust and representative datasets tailored to defense use cases, incorporating variations in terrain, time of day, atmospheric conditions, and population diversity. This should be complemented with continuous data auditing and the use of domain-specific data augmentation to help models generalize more effectively and reduce inherent biases.

False Positives, False Negatives, and Decision Integrity

A closely related concern is the occurrence of false positives and false negatives. In mission-critical defense operations, a false positive could result in the misidentification of a civilian as a hostile actor, while a false negative could allow a threat to go undetected. Both scenarios carry significant consequences for safety and mission outcomes.

To mitigate this, systems should be designed to include confidence scores and uncertainty estimates, giving human operators more nuanced insights into the AI’s decision-making. Additionally, employing ensemble models and multi-sensor fusion, such as combining visual and thermal data, can enhance reliability and minimize the chances of critical errors.

Adversarial Threats to Visual Recognition

Adversarial attacks are another significant threat to AI vision systems in defense. These include facial cloaking techniques that evade recognition and patch-based attacks that confuse object detection algorithms. Such tactics can effectively render AI systems blind to genuine threats. The defense against this lies in incorporating adversarial training methods that expose models to simulated attacks during development. Preprocessing techniques, like inpainting and data purification, can help restore the integrity of manipulated inputs. Creating adversarial testing environments also allows defense organizations to proactively assess vulnerabilities and improve system robustness before live deployment.

Human-AI Collaboration in High-Stakes Operations

The lack of structured human-AI collaboration frameworks presents another operational gap. Overreliance on AI systems without sufficient human oversight can result in blind trust and potentially catastrophic decisions. Conversely, sidelining AI can reduce efficiency and slow down responses.

A balanced approach involves integrating human-in-the-loop workflows, where AI assists rather than replaces decision-makers. This setup should include interpretable outputs and user interfaces that clearly communicate system confidence and rationale. Equally important is training defense personnel to understand AI limitations, fostering an environment of informed trust rather than unquestioning dependence.

Governance, Ethics, and Regulatory Oversight

The rapid integration of facial recognition and object detection into defense workflows has outpaced the development of regulatory and ethical oversight mechanisms. This creates uncertainty around issues such as privacy, consent, accountability, and adherence to international laws of engagement.

The recommendation here is to establish transparent and enforceable governance frameworks that define permissible applications and usage boundaries. This includes creating data governance policies, ethical review boards, and ensuring auditability of AI systems through explainable models and usage logs.

Operational Resilience in Mission-Critical Scenarios

Finally, mission readiness under operational stress remains a persistent concern. Defense AI systems must function reliably even in degraded environments, where communication is limited, adversaries deploy countermeasures, or natural conditions obscure visibility.

To address this, systems should be equipped with edge-processing capabilities to operate autonomously when disconnected from central servers. They should also be subjected to rigorous testing in both simulated and real-world defense scenarios to ensure resilience, adaptability, and fail-safe performance under pressure.

How We Can Help

Digital Divide Data (DDD) is uniquely positioned to support the defense tech in building resilient, ethical, and mission-ready AI systems through high-quality data services and scalable human-in-the-loop solutions. As AI adoption accelerates in surveillance, targeting, and threat detection workflows, the success of these applications increasingly depends on the quality, diversity, and security of the underlying data. DDD’s capabilities directly address these requirements.

We provide large-scale, high-fidelity data collection and annotation services tailored to defense and security contexts. This includes labeling of facial images under varied lighting, occlusion, and environmental conditions, as well as complex object detection tasks involving aerial, thermal, and multi-sensor imagery. By drawing from global, diverse data sources and using trained, security-vetted annotators, DDD helps ensure that AI models are trained on datasets that minimize bias and maximize operational generalizability.

We integrate human-in-the-loop workflows that enhance system reliability in high-stakes environments. Whether it’s verifying edge-case detections, annotating adversarial scenarios, or maintaining the accuracy of evolving datasets, DDD’s skilled teams offer continuous validation and refinement, critical for AI systems deployed in dynamic, adversarial settings. These workflows not only improve accuracy but also build in accountability and transparency, which are increasingly required in defense AI applications.

Our defense tech solutions are 100% U.S owned, operated by a U.S. workforce, and led by veterans. All data used in defense programs remains securely housed within the United States, ensuring compliance with data sovereignty requirements and the highest standards of national data protection.

Read more: Geospatial Data & GEOINT Use Cases in Defense Tech and National Security

Conclusion

As global threats grow more sophisticated, the defense sector is turning to advanced technologies like facial recognition and object detection to maintain strategic advantage and national security. These AI-driven capabilities are no longer experimental; they are embedded in mission-critical systems such as surveillance drones, unmanned vehicles, biometric access controls, and real-time targeting platforms.

To harness the full potential of these technologies, it is essential to strike a careful balance between technical innovation and responsible implementation. Defense systems must be built on diverse, high-quality datasets, hardened against manipulation, and designed with human oversight and ethical safeguards at their core. Investing in robust AI infrastructure is not just a matter of technological superiority; it is a matter of trust, accountability, and long-term resilience.

The future will depend not just on how powerful these systems become, but on how ethically, securely, and effectively they are deployed.

Partner with DDD to build secure, mission-ready AI systems using facial recognition and object detection in defense tech. Talk to our experts

Facial Recognition and Object Detection in Defense Tech Read Post »

Geo252BIntelligence252B2528GeoINT2529

Geospatial Data & GEOINT Use Cases in Defense Tech and National Security

Geospatial data has become a foundational asset in defense tech and national security operations. It broadly encompasses any information tied to a location, from satellite imagery and topographic maps to real-time sensor feeds and 3D models. In the defense sector, its significance has grown rapidly as the nature of warfare and intelligence gathering has shifted from static battlefield maps to dynamic, data-driven decision environments.

Geospatial data is now critical across various military functions: from early-warning systems and target acquisition to mission planning, logistics, and situational awareness. It underpins operations in diverse and complex terrains, urban battlegrounds, maritime chokepoints, and cyber-physical domains alike. Its value extends beyond just defense, supporting disaster response, infrastructure protection, and even pandemic monitoring.

This blog explores geospatial data & GEOINT use cases in defense and national security, highlighting how these technologies are driving recent innovations and operational strategies.

The Evolution of Geospatial Intelligence (GEOINT)

The roots of geospatial intelligence trace back to traditional cartography and reconnaissance, where physical maps and manual image interpretation formed the basis of battlefield strategy. Over time, as technology advanced, so did the sophistication of GEOINT. The rise of satellite imaging in the Cold War era marked a turning point, providing nations with a new level of visibility across borders and theaters of conflict. Today, that capability has expanded dramatically, with real-time feeds, hyperspectral imagery, and AI-assisted analysis redefining what is possible.

Modern GEOINT is no longer confined to static maps. It has evolved into a dynamic, multi-dimensional intelligence discipline that integrates geospatial data with artificial intelligence, machine learning, and real-time sensor fusion. These technologies enable defense analysts and commanders to not only visualize physical environments but also to predict movement, monitor behavioral patterns, and detect anomalies across domains.

Geospatial intelligence now plays a pivotal role in what are known as multi-domain operations, coordinated efforts that span land, air, sea, cyber, and space. Whether it’s supporting precision strikes, mapping urban terrain in real time, enabling autonomous drone navigation, or protecting digital infrastructure, GEOINT serves as the connective tissue between data and decisions in modern warfare.

This evolution marks a paradigm shift. What began as a supporting function is now a central pillar of national defense strategies, enabling speed, accuracy, and adaptability in complex, rapidly changing environments.

Use Cases of Geospatial Data and GEOINT in Defense Tech & National Security

Intelligence, Surveillance, and Reconnaissance (ISR)

Intelligence, Surveillance, and Reconnaissance (ISR) is a foundational pillar of modern military operations, enabling decision-makers to understand, anticipate, and respond to threats with speed and accuracy. At its core, ISR involves the collection, processing, and dissemination of information about adversarial forces, terrain, and activity, often under time-sensitive conditions. Today, geospatial data sits at the heart of this process.

The Role of Geospatial Data in ISR

Modern ISR relies heavily on geospatial data derived from satellites, manned aircraft, unmanned aerial vehicles (UAVs), ground-based sensors, and maritime platforms. These sources produce vast volumes of high-resolution imagery and telemetry data that must be interpreted rapidly to provide actionable intelligence. Geospatial intelligence (GEOINT) enables operators to:

  • Monitor adversarial movements and deployments

  • Detect changes in terrain, infrastructure, or activity patterns

  • Track time-series data to assess trends or anticipate actions

  • Fuse visual, radar, and multispectral data for more accurate detection

Geospatial data enhances ISR by anchoring intelligence within precise coordinates and temporal contexts, transforming raw visuals into operational insight.

AI and Foundation Models in ISR

The increasing complexity and volume of ISR data have accelerated the adoption of AI and machine learning models, particularly foundation models trained on vast datasets of satellite and aerial imagery. These models can:

  • Detect vehicles, aircraft, ships, and facilities automatically

  • Classify objects and activities (e.g., convoy movement, construction, force buildup)

  • Identify anomalies (e.g., sudden changes in terrain or unreported infrastructure)

  • Operate under diverse conditions, including night and poor weather (using SAR and thermal imagery)

Mission Planning and Terrain Analysis

Effective mission planning is impossible without a deep understanding of the physical, environmental, and structural complexities of the operational environment. In modern warfare, where the landscape can range from dense urban centers to remote mountainous terrain, geospatial data is the bedrock of planning, simulation, and tactical decision-making.

Why Terrain Intelligence Matters

Before boots hit the ground or autonomous systems are deployed, commanders must know:

  • Where threats may be hidden

  • Which paths offer the least resistance or exposure

  • How the landscape may affect communications or visibility

  • What risks do natural and man-made obstacles pose

Geospatial terrain analysis provides this foresight. It allows forces to rehearse missions virtually, conduct route feasibility studies, and tailor strategies to the terrain’s demands, minimizing the risk of surprise and optimizing operational efficiency.

Key Technologies in Terrain Analysis

Digital Elevation Models (DEMs):
DEMs offer precise height information of surface features, critical for planning helicopter landings, artillery placements, and line-of-sight (LOS) communications. In hilly or forested areas, they help anticipate visual obstructions or ambush points.

Land Use and Land Cover (LULC) Classification:
Geospatial tools classify terrain, such as urban, forest, desert, wetland, or agricultural zones. These classifications influence mobility, camouflage, and risk of detection. For instance, armored vehicles may avoid swampy terrain, while infantry units might use forests for cover.

3D Urban Mapping and Mesh Modeling:
Urban warfare demands a granular understanding of building layouts, alleyways, underground structures, and vertical access points (e.g., rooftops or subways). Advanced photogrammetry and LiDAR-derived 3D models are now routinely used for close-quarters mission rehearsals.

Real-Time Atmospheric and Environmental Data Integration:
Weather conditions, wind, fog, precipitation, and dust can dramatically impact visibility, aircraft performance, or the effectiveness of infrared sensors. Geospatial platforms now ingest meteorological data in real time to adapt plans dynamically.

Terrain Navigation and Autonomous Systems:
For drones, unmanned ground vehicles (UGVs), and autonomous naval vessels, terrain-aware navigation is essential. These systems use geo-tagged data to calculate elevation, identify natural barriers, and localize themselves even in GPS-denied environments.

Applications in Defense Scenarios

  • Reconnaissance and Infiltration: Identify safe and stealthy ingress/egress routes.

  • Fire Planning: Adjust artillery firing angles based on topography and slope.

  • Search and Rescue (SAR): Map out safe zones and terrain risk for deployment teams.

  • Logistics and Mobility Planning: Ensure convoys or supply chains avoid bottlenecks or bridges that can’t support heavy loads.

  • Cyber-Physical Simulations: Integrate terrain data into wargames and training simulators to test tactics in accurate virtual environments.

Border and Maritime Surveillance

Securing national boundaries both on land and at sea is a complex, resource-intensive endeavor that demands constant vigilance. In a time of increasing geopolitical tension, transnational crime, and illicit maritime activity, defense and homeland security agencies are turning to geospatial intelligence to ensure sovereignty, detect threats, and safeguard trade routes.

Geospatial surveillance systems are now the backbone of persistent monitoring, offering unmatched capabilities in detecting, classifying, and responding to suspicious activity across remote borders, coastal zones, and open oceans.

Geospatial Technologies in Use

Synthetic Aperture Radar (SAR):
Unlike traditional optical sensors, SAR can penetrate cloud cover and operate in total darkness, making it ideal for round-the-clock border and maritime surveillance. SAR is capable of detecting vehicle tracks, terrain disturbances, and unusual vessel movements even in low-visibility environments such as deserts, mountainous terrain, and high seas.

Thermal and Infrared Imaging:
Thermal sensors are instrumental in detecting heat signatures of individuals, vehicles, or boats, especially in night operations or during adverse weather. This capability is critical in identifying illegal border crossings, human trafficking movements, or unregistered vessels avoiding radar detection.

Automatic Identification Systems (AIS):
AIS transponders on ships transmit identity, position, course, and speed data. However, not all vessels use AIS legally. By fusing AIS data with SAR and electro-optical imaging, defense systems can detect “dark vessels” that deliberately disable their AIS to avoid detection, often used in smuggling, illegal fishing, or piracy.

Change Detection Algorithms and Pattern Recognition:
Satellite imagery over time allows agencies to compare changes in terrain or maritime routes. For example, repeated land disturbances near a border fence could signal illegal excavation or tunnel building, while altered shipping routes may indicate evasive behavior.

Persistent Surveillance from UAVs and HAPS (High-Altitude Pseudo Satellites):
Drones and high-altitude balloons equipped with EO/IR and radar payloads offer long-dwell surveillance over isolated or inaccessible regions, providing high-resolution feeds for both human analysts and AI systems.

Key Defense Applications

  • Border Security Monitoring: Detecting unauthorized crossings, vehicle incursions, and contraband movement across land borders in deserts, forests, or mountainous terrain.

  • Maritime Domain Awareness (MDA): Tracking vessel traffic, flag state violations, and illegal maritime operations in exclusive economic zones (EEZs) and critical chokepoints.

  • Anti-Piracy and Counter-Smuggling Operations: Identifying fast, unregistered boats operating off known smuggling corridors or near strategic maritime infrastructure.

  • Illegal Fishing Detection: Monitoring protected marine zones and identifying fishing trawlers operating without permits or in restricted areas a key issue in Southeast Asia, West Africa, and the Pacific.

  • Disaster and Refugee Movement Tracking: Supporting humanitarian missions by monitoring mass maritime migrations, especially in regions affected by conflict or natural disasters.

Read more: Top 10 Use Cases of Gen AI in Defense Tech & National Security

Autonomous Systems Navigation

Integration of autonomous systems into military operations is transforming how missions are conducted across air, land, and sea. Whether it’s unmanned ground vehicles (UGVs) conducting resupply, drones performing reconnaissance, or naval assets patrolling contested waters, the effectiveness of these autonomous platforms hinges on access to accurate and dynamic geospatial data.

Unlike manned missions, autonomous operations require a deeper pre-programmed understanding of the environment and the ability to adapt in real-time, often in GPS-denied or signal-contested scenarios. This is where high-fidelity geospatial intelligence becomes critical.

The Role of Geospatial Data in Autonomy

Autonomous military platforms must constantly answer three questions: Where am I? What’s around me? How do I get to the target location safely? 

Geospatial data provides the foundational input for all three, enabling machines to navigate, avoid hazards, and complete missions with minimal human intervention.

Core Components Enabling Autonomous Systems Navigation

High-Definition (HD) Maps:
HD maps contain precise representations of terrain features, road geometries, elevation profiles, obstacle zones, and traversable areas. These maps, often created using LiDAR and high-resolution satellite imagery, help autonomous vehicles understand not just location but context, such as sharp turns, inclines, restricted areas, and potential ambush sites.

Terrain-Referenced Navigation (TRN):
In GPS-denied or spoofed environments (a common tactic in modern electronic warfare), autonomous systems use terrain features like ridgelines, valleys, or man-made structures to localize themselves. By comparing onboard sensor inputs (camera, LiDAR, radar) with pre-mapped terrain models, they can navigate with a high degree of certainty even when GNSS is unavailable.

Simultaneous Localization and Mapping (SLAM):
For drones and ground vehicles operating in uncharted or dynamic environments, SLAM enables real-time mapping and localization. Geospatial SLAM systems fuse vision, radar, and inertial data to build and update their own maps while moving, critical for navigating unknown battlefields or collapsed urban areas.

Real-Time Map Updating via Recon Assets:
Autonomous systems don’t operate in isolation. Reconnaissance drones or satellites can relay updates on terrain changes, like roadblocks, craters, or enemy movement, which are then streamed to ground units to revise pathfinding decisions on the fly. This dynamic data flow is essential for last-mile operations, where outdated maps could mean mission failure or system loss.

Obstacle Detection and Avoidance:
Using fused geospatial and onboard sensor data, autonomous systems can classify and avoid obstacles such as debris, enemy assets, water bodies, or structural ruins, key for both stealth and safety in contested zones.

Use Cases in Defense Operations

  • Last-Mile Logistics: Autonomous ground convoys deliver supplies to forward operating bases or evacuation zones without risking human drivers in conflict areas.

  • Aerial Reconnaissance and Target Acquisition: UAVs use terrain and map data to fly at low altitude (terrain-following flight) to avoid radar detection while scanning specific geofenced regions.

  • Minefield Navigation: Unmanned platforms can use geospatial data and sensors to navigate around or clear suspected minefields autonomously.

  • Undersea Mapping and Patrol: Autonomous underwater vehicles (AUVs) rely on geospatial bathymetry and sonar-based SLAM to patrol and map littoral or deep-sea environments, often in strategic chokepoints.

Read more: Fleet Operations for Defense Autonomy: Bridging Human Control and AI Decisions

How We Can Help

As the demand for precise, actionable geospatial intelligence (GEOINT) grows across defense and national security, the ability to transform raw spatial data into mission-ready insights becomes a strategic imperative. Digital Divide Data (DDD) delivers tailored GEOINT solutions that empower defense organizations to gain a tactical and strategic edge.

DDD supports key geospatial workflows central to defense operations:

Map Building for Operational Planning:
DDD enables the creation of high-resolution, annotated maps that are essential for route planning, terrain analysis, and mission execution. These maps are enriched with geo-referenced features such as road networks, infrastructure, and elevation profiles.

Disaster Modeling and Humanitarian Support:
Leveraging satellite imagery and change detection models, DDD supports disaster response scenarios by generating geospatial layers that help defense and relief agencies assess damage, identify access routes, and coordinate aid delivery.

Satellite Navigation (SatNav) Validation:
We assist in validating SatNav systems by mapping and classifying terrain features used in autonomous vehicle localization and targeting systems. Our services help improve navigational accuracy in GPS-contested or denied environments.

Imagery Intelligence (IMINT) for Battle Damage Assessment (BDA):
Our teams are trained in IMINT workflows to support post-strike analysis. We annotate and interpret aerial and satellite imagery to evaluate strike accuracy, infrastructure damage, and residual threats, key for BDA and national security targeting operations.

DDD’s expertise lies not only in data processing but in delivering intelligent outputs that meet the standards required by defense analysts, AI developers, and ISR teams. With a dedicated US workforce and a focus on ethical impact, DDD ensures mission-critical geospatial workflows are supported with precision, scalability, and confidentiality.

Conclusion

As global defense strategies evolve to meet the demands of asymmetric warfare, cyber-physical threats, and rapid-response operations, geospatial data has emerged as a critical enabler of modern military capability. From strategic surveillance to autonomous navigation and real-time battlefield coordination, geospatial intelligence is no longer a supporting element; it is the foundation upon which decisions are made and missions are executed.

Yet, with this strategic importance comes the responsibility to build secure, interoperable, and ethically sourced geospatial ecosystems. As defense organizations scale their use of AI and automation, the demand for high-quality, annotated, and mission-specific geospatial data will only increase.

Let’s build smarter, safer, and more strategic defense ecosystems together. Talk to our experts

Geospatial Data & GEOINT Use Cases in Defense Tech and National Security Read Post »

shutterstock 2404121267

Enhancing Image Categorization with the Quantized Object Detection Model in Surveillance Systems

As surveillance technologies continue to evolve, their role in maintaining public safety, enforcing law and order, and monitoring critical infrastructure becomes increasingly indispensable. Central to the efficacy of these systems is the ability to process visual information rapidly and accurately. Image categorization is at the core of this capability, classifying visual data into predefined categories such as humans, vehicles, or suspicious objects.

With the rising deployment of surveillance systems across smart cities, airports, borders, and industrial zones, there’s a growing need to make these systems more intelligent and efficient. One promising approach that addresses both performance and resource constraints is the use of quantized object detection models. These models offer a compelling balance between computational speed and categorization accuracy, making them ideal for modern surveillance deployments.

In this blog, we will discuss object detection in surveillance systems and how quantized object detection models are reshaping image categorization. We’ll explore the challenges of categorizing visual data in real-world surveillance environments, define what quantized models are and how they work, and examine the specific advantages they bring to the table.

Image Categorization in Surveillance and Associated Challenges

Image recognition, at its core, involves assigning labels to objects or scenes captured in visual data. In the context of general computer vision, this might seem like a straightforward process. But when you introduce real-world surveillance environments into the equation, the complexity rises dramatically.

Surveillance systems aren’t operating in controlled lab conditions, they’re monitoring busy streets, crowded public transport terminals, remote borders, industrial facilities, and more. These environments are unpredictable, fast-paced, and often noisy, both visually and audibly.

One of the biggest hurdles is the sheer variability in the data. Unlike curated datasets used to train traditional models, surveillance footage often includes obstructions, varying light conditions (nighttime, glare from headlights, heavy shadows), different angles, and partial views of people or objects. An object might be partially hidden by another or captured at a resolution that makes it hard to distinguish. For example, identifying a person wearing a hood in a shadowed alley or detecting a small object on a cluttered sidewalk is far more difficult than recognizing clearly labeled items in a dataset.

Another layer of complexity comes from the real-time performance expectations. Surveillance isn’t just about recording; it’s about actively analyzing and reacting. Whether it’s a city-wide camera network or a drone patrolling a perimeter, the system needs to process data continuously and make decisions.

The volume of data generated by surveillance systems is enormous. A single high-definition camera running 24/7 can produce terabytes of video data per week. Multiply that by dozens, hundreds, or thousands of cameras in a city or facility, and you’re dealing with an overwhelming amount of visual information. It’s not feasible, either technically or financially, to send all this data to the cloud for analysis. The processing has to happen closer to the source, which introduces another challenge: resource constraints.

Edge devices like cameras, drones, or embedded sensors typically don’t have the luxury of high-end GPUs or abundant memory. They’re designed to be lightweight and energy-efficient. Running large, traditional deep learning models on these devices is impractical. These models can be too slow, too power-hungry, and too demanding in terms of memory and thermal management. As a result, there’s a growing demand for models that are compact, efficient, and still capable of handling the nuanced demands of surveillance categorization.

In short, image categorization in surveillance is not just a technical problem, it’s an operational and logistical challenge that sits at the intersection of AI, hardware constraints, and real-world complexity. And this is precisely where innovations like quantized object recognition models come in, offering the potential to bridge the gap between what’s technically possible and what’s practically deployable.

What is a Quantized Object Recognition Model?

In the realm of machine learning, especially deep learning, models are traditionally built using high-precision numbers, specifically, 32-bit floating point (FP32) values. These numbers are used to represent everything from the weights of neural networks to the activation values calculated during inference.

While this level of precision ensures accuracy, it also comes with a significant computational cost. Large models can be slow to run, require a lot of memory, and consume substantial energy, especially problematic when deploying to edge devices like security cameras, drones, or embedded systems in surveillance environments.

This is where quantization enters the picture. Quantization is the process of reducing the precision of a model’s parameters and computations. Instead of using 32-bit floats, quantized models use lower-bit formats such as 16-bit, 8-bit, or even 4-bit integers. This seemingly simple reduction can lead to significant benefits: smaller model sizes, faster inference times, and lower power consumption. It allows developers to compress large neural networks into lightweight versions that can run efficiently on limited hardware, without having to fundamentally redesign the model architecture.

A quantized object recognition model is exactly what it sounds like: an object detection model, such as YOLO (You Only Look Once), SSD (Single Shot Multibox Detector), or MobileNet, that has been quantized to operate more efficiently. These models are trained to detect and classify objects (like people, vehicles, or bags) in an image or video feed, and quantization makes them more suitable for real-time use in edge-based surveillance systems.

There are two main types of quantization methods:

  1. Post-Training Quantization – This is applied after the model is trained. It’s fast and easy but may result in slight drops in accuracy, especially if the original model is sensitive to precision loss.

  2. Quantization-Aware Training (QAT) – In this approach, the model is trained with quantization in mind from the beginning. It simulates lower-precision operations during training, helping the model learn to adapt. This generally results in better performance after quantization, especially in complex tasks like object detection.

How Quantized Object Recognition Model Improves Image Categorization

Quantized models are reshaping how we approach image categorization in surveillance systems, primarily by making intelligent analysis possible on devices that were previously too resource-constrained to run modern deep learning models. Their impact is felt not only in technical efficiency but also in the way they influence operational workflows and real-time decision-making in high-stakes security environments. Let’s discuss how this model improves image categorization:

Real-Time Processing on Edge Devices

With quantized models, the image categorization task can happen locally on the device itself. A security camera equipped with a quantized model can identify vehicles, detect weapons, or differentiate between authorized and unauthorized personnel, right at the source, without the need to send video data to a data center. This dramatically shortens response time and also alleviates bandwidth demands, which is crucial for large-scale deployments where hundreds of devices are simultaneously streaming video.

Scalability and Cost Efficiency

Quantized models enable surveillance systems to scale more cost-effectively. When models require fewer resources, organizations can deploy them across a wider range of hardware: older devices, smaller drones, portable surveillance kits, and low-power embedded processors. This is particularly valuable in large-scale deployments like smart cities or airport security networks, where infrastructure costs can increase rapidly.

The cost savings go beyond just hardware. Quantized models reduce energy consumption, which extends the operational time of battery-powered devices and lowers overall energy costs. In military or remote applications where power sources are limited, this added efficiency means longer missions and fewer interruptions.

Improved Data Privacy and Security

Performing categorization tasks locally with quantized models also enhances privacy and data security. Instead of transmitting raw video footage, which may contain sensitive personal or strategic information, only metadata or categorization results (e.g., “suspicious vehicle detected in zone 3”) need to be sent back to a central system. This approach aligns with modern privacy protocols and regulatory requirements, especially in public surveillance scenarios where personal data protection is a concern.

Maintaining Accuracy in Resource-Limited Conditions

Quantized models can be fine-tuned on surveillance-specific datasets. This domain adaptation helps ensure the model continues to perform well in varied lighting, weather, and background conditions, hallmarks of real-world surveillance environments. In many cases, this tuned performance rivals or even exceeds that of bulkier, full-precision models running in idealized lab settings.

Enables Continuous Operation and Edge Learning

With lower processing demands, quantized models contribute to more stable and sustained system operation. Surveillance devices can remain active longer without overheating or needing to offload tasks. And as adaptive learning technologies mature, it’s becoming possible to retrain or fine-tune quantized models on-device using small amounts of new data, a concept known as edge learning. This allows surveillance systems to improve over time, adapting to new threats, behavioral patterns, or environmental changes without requiring a complete retraining cycle.

Application Scenarios

In border security applications, quantized models deployed on UAVs or thermal cameras help detect unauthorized crossings or movement patterns that deviate from the norm. Their efficiency allows them to process high-definition video feeds on the fly, delivering actionable intelligence directly to security personnel.

Another compelling use case is in public event monitoring. During large gatherings or protests, security forces use surveillance systems to detect anomalies such as sudden crowd dispersals, aggressive behavior, or the presence of weapons. With quantized models, such capabilities can be extended to mobile devices, allowing law enforcement teams to analyze video streams from body-worn cameras or drones in real time.

Learn more: Synthetic Data Generation for Edge Cases in Perception AI

Future Outlook

Looking ahead, the use of quantized models in surveillance is expected to expand significantly. As edge computing becomes more powerful and widespread, we can anticipate a shift toward fully decentralized AI surveillance systems capable of operating autonomously and securely.

The convergence of quantized models with other technologies, such as multi-modal learning, sensor fusion, and federated learning, will open new possibilities. For instance, future systems might combine audio, thermal, and visual data in quantized form to deliver holistic situational awareness. Furthermore, emerging standards around secure AI deployment will make it easier to validate and certify quantized models for use in sensitive applications.

Learn more: How AI-Powered Object Detection is Reshaping Defense

Conclusion

Quantized object recognition models represent a pivotal advancement in the field of AI-powered surveillance. By enabling efficient and accurate image categorization on edge devices, they solve one of the biggest challenges in scaling smart surveillance systems. These models are not just tools of convenience; they are strategic enablers that allow security systems to operate faster, smarter, and more autonomously. As technology continues to evolve, their role will only grow more central in the effort to build safe and resilient public and private spaces.

At DDD, we help organizations deploy and scale AI-powered object detection and categorization in real-world surveillance environments. Have questions about integrating advanced object recognition into your security systems? Talk to our experts today.

References:

NVIDIA. (n.d.). Jetson edge AI benchmark. NVIDIA Developer. https://developer.nvidia.com/embedded/jetson-benchmarks

Intel. (n.d.). OpenVINO™ toolkit overview. Intel Developer Zone. https://www.intel.com/content/www/us/en/developer/tools/openvino-toolkit/overview.html

Papers with Code. (n.d.). Object detection on COCO. https://paperswithcode.com/sota/object-detection-on-coco

Song, H., Wang, X., Bai, X., Wang, C., & Li, X. (2023). Vision-based object detection in autonomous driving: A survey. Expert Systems with Applications, 234, 120103. https://doi.org/10.1016/j.eswa.2023.120103

Enhancing Image Categorization with the Quantized Object Detection Model in Surveillance Systems Read Post »

shutterstock 1936992973

How AI-Powered Object Detection is Reshaping Defense

Artificial Intelligence (AI) is now a central pillar of how nations protect their people, borders, and interests. Among its many applications, object detection stands out for its immediate impact on national security.

By teaching machines to identify people, vehicles, weapons, and other objects in images and videos, governments and defense organizations are enhancing how they monitor threats, respond to crises, and maintain strategic advantages.

From surveillance drones patrolling borders to satellites tracking troop movements across continents, AI-driven systems are increasing speed, accuracy, and operational efficiency in unprecedented ways. This shift is not only making defense systems smarter but also reducing human workloads and error, allowing military personnel and analysts to focus on what truly matters.

In this blog, we explore how object detection is revolutionizing national security by enhancing situational awareness, accelerating decision-making, and reducing risk across every level.

The Rise of AI in National Security

AI-powered object detection systems use algorithms trained on large volumes of annotated data to recognize and classify objects in real time. Whether it’s a drone identifying enemy vehicles in rough terrain or a surveillance camera picking up suspicious behavior in a high-traffic area, the technology allows defense forces to react quickly and precisely.

A key example is Project Maven, which was launched by the U.S. Department of Defense in 2017. This initiative was developed to harness AI for analyzing vast volumes of drone footage and extracting actionable intelligence. Project Maven dramatically reduced the manual workload for military analysts by enabling AI to identify and flag people, vehicles, and other objects of interest in real time. The project improved operational timelines and the overall quality of intelligence gathered from ISR (intelligence, surveillance, and reconnaissance) assets. These enhancements allowed defense teams to accelerate mission planning and improve response times in high-risk environments.

Another example is Shield AI, a San Diego-based defense technology firm that builds AI pilots for autonomous aircraft. Their flagship platform, Hivemind, enables drones to operate in GPS-denied or communication-degraded environments without human input. These AI-powered reconnaissance tools enable real-time object detection and terrain navigation, allowing drones to scout heavily contested or dangerous areas safely.

This advancement significantly improves ISR capabilities as it minimizes the risk of human error, reduces false positives, and increases mission success rates through autonomous situational awareness. This project represents the future of deploying smart, self-directed aerial systems that support critical operations without placing personnel in harm’s way.

Key Applications of Object Detection in National Security

Object detection is transforming nearly every aspect of defense operations by enabling systems to “see” and understand complex visual environments. Below are several of its most critical applications:

Surveillance and Reconnaissance

AI-driven surveillance tools, like drones, satellites, and fixed cameras, are redefining how military and security teams monitor territories. With the ability to detect and track people, vehicles, and movements in real time, these tools dramatically reduce the risk of human oversight and improve response times.

AI models trained on vast datasets can distinguish between ordinary civilian activity and potentially threatening behavior, minimizing false alarms and enabling more informed situational awareness.

Border Security and Counterterrorism

AI-based object detection plays a pivotal role in identifying unauthorized border crossings, spotting concealed weapons, and flagging suspicious actions. These systems are particularly effective in remote or high-traffic areas where human monitoring is difficult.

Integrated with facial recognition and license plate scanning, they support law enforcement and homeland security in preempting potential threats. AI also enables more efficient data fusion from multiple sources, such as ground sensors, surveillance footage, and biometric records.

Battlefield Intelligence and Tactical Advantage

On the front lines, real-time image and video analysis offers soldiers a decisive edge. AI systems ingest drone feeds and satellite imagery to identify enemy positions, detect hidden explosives, and assess terrain risks.

This information, delivered almost instantly, helps commanders make faster, smarter decisions. By reducing the fog of war, AI object detection enhances strategic planning and coordination between units.

Mine and IED Detection

Autonomous ground vehicles and drones equipped with object detection can identify improvised explosive devices (IEDs) or landmines buried underground or hidden in debris. Using visual cues and sensor data, these systems help ensure safe navigation for troops and minimize the risk of casualties. Their ability to continuously learn and adapt makes them more effective with every mission.

Cybersecurity and Decision-Making

Object detection in the digital realm helps monitor network activity for unusual patterns, potentially flagging cyber threats before they escalate. Coupled with other AI capabilities, these systems can correlate physical and digital data, such as identifying suspicious persons near a sensitive facility following a cyberattack.

Predictive Maintenance and Supply Chain Optimization

AI-powered detection systems are also used to monitor military equipment, vehicles, aircraft, and weapons systems, for signs of wear or malfunction. By spotting issues before they become critical, maintenance can be performed proactively, reducing downtime. Similarly, AI helps forecast supply needs and streamline logistics, as demonstrated in the U.S. Navy’s LAI (Logistics AI Integration) initiative.

Humanitarian and Investigative Support

AI object detection supports broader missions as well, such as law enforcement investigations into trafficking and exploitation. By analyzing video footage and online content, these systems can spot patterns of suspicious behavior or identify known criminals. In conflict zones, they help identify humanitarian needs by tracking displaced populations or damaged infrastructure.

Other Areas

AI’s impact extends far beyond traditional defense scenarios. Here are some additional areas where object detection and AI technologies are making a difference:

  • Language Translation & Communication: Real-time translation tools powered by AI help military personnel communicate across linguistic barriers in multinational operations.

  • Predictive Maintenance: AI can detect early signs of equipment failure, reducing downtime and increasing the efficiency of military assets.

  • Supply Chain Optimization: The U.S. Navy’s Logistics AI Integration (LAI) program is a prime example of how AI predicts supply needs and enhances logistics planning.

  • Human Trafficking & Exploitation Prevention: AI monitors online platforms and detects suspicious behavior patterns to assist in preventing human trafficking and exploitation.

Read more: Red Teaming For Defense Applications and How it Enhances Safety

Technical Challenges in Object Detection

Despite its promise, AI object detection faces significant hurdles that developers and defense tech must address to ensure system reliability and resilience. One major concern is vulnerability to adversarial attacks. In such cases, malicious actors intentionally introduce subtle, misleading data that can cause an AI system to misidentify or overlook objects, posing a serious threat in mission-critical environments. For example, researchers have demonstrated that adding noise to images or manipulating pixels can trick AI models into misclassifying vehicles, weapons, or people.

To combat these risks, the AI research community is exploring several techniques. One emerging approach is the use of conditional diffusion models, which are generative methods that help AI systems produce more robust and realistic predictions by modeling uncertainty in data. When trained properly, these models can resist manipulations and better generalize to new or unpredictable scenarios. Additionally, robust training techniques, such as adversarial training, ensemble methods, and data augmentation, are proving effective in hardening AI models against deceptive inputs.

Another foundational challenge lies in ensuring high-quality training data. Inaccurate or inconsistent labels can weaken model performance, especially when AI is tasked with identifying nuanced threats across diverse terrains and contexts. This is where precise data labeling and annotation become mission-critical. It’s not just about quantity but also accuracy, context, and consistency. Continuous fine-tuning and real-world testing are also necessary to adapt models to evolving conditions and threat profiles.

Finally, the importance of data governance and ethical considerations cannot be overstated. Systems that analyze sensitive environments must be developed with transparency and accountability to avoid unintended consequences, such as biased detections or privacy violations.

How Digital Divide Data (DDD) Supports National Security

We provide high-quality data services to enhance the effectiveness of national security technology. Here’s how:

Data Labeling & Annotation – Our experts ensure precise image, video, and sensor data labeling to train reliable detection AI models.

LLM Fine-Tuning & RLHF – We refine large language models and incorporate human feedback to enhance decision-making capabilities.

Red Teaming for AI Systems – Our rigorous testing identifies vulnerabilities and biases, strengthening the reliability of security technologies.

Data Engineering & Analysis – We collect, clean, and structure data to improve real-time threat detection and intelligence gathering.

Impact Sourcing Model – DDD employs skilled professionals from underserved communities, delivering top-tier services while promoting social impact.

By leveraging our expertise, national security organizations can enhance precision, security, and efficiency.

Learn more: Gen AI for Government: Benefits, Risks and Implementation Process

Object detection helps defense teams spot threats faster, make better decisions, and reduce risks. But for these systems to work perfectly, they need high-quality data and thoughtful development behind them.

At Digital Divide Data (DDD), we specialize in ML data services that make AI smarter and more reliable, from labeling images and videos to testing systems for bias and vulnerability.

Let’s talk about how we can support your next AI project.

How AI-Powered Object Detection is Reshaping Defense Read Post »

Scroll to Top