Celebrating 25 years of DDD's Excellence and Social Impact. ✖

ADAS

Digital Twin Validation

Digital Twin Validation for ADAS: How Simulation Is Replacing Miles on the Road

The argument for extensive real-world testing in ADAS development is intuitive. Drive enough miles, encounter enough situations, and the system will have seen the breadth of conditions it needs to handle. The problem is that the arithmetic does not support the strategy. 

Demonstrating safety at a statistically meaningful confidence level for a full-autonomy system would require hundreds of millions, possibly billions, of real-world miles, run at a pace no single development program can sustain within any reasonable timeline. 

The events that determine whether an automatic emergency braking system fires correctly when a cyclist cuts across at night, or whether a lane-keeping system handles an unmarked temporary lane on a construction approach, are not the events that accumulate steadily during normal testing. They surface occasionally, in conditions that make systematic analysis difficult, and often in circumstances where no one is watching carefully enough to capture what happened. The rarest events are precisely the ones that most need to be tested deliberately and repeatedly.

This blog examines what digital twin validation actually involves for ADAS programs, how sensor simulation fidelity determines whether results transfer to real-world performance, and what data and annotation workflows underpin an effective digital twin program. 

What a Digital Twin for ADAS Validation Actually Is

The term digital twin has accumulated enough promotional weight that it now covers a wide range of things, some genuinely sophisticated and some that amount to a conventional simulator with better graphics. In the specific context of ADAS validation, a digital twin has a reasonably precise meaning: a virtual environment that models the vehicle under test, the sensor suite on that vehicle, the road infrastructure the vehicle operates within, and the other road users it interacts with, at a fidelity level sufficient to produce sensor outputs that a real ADAS perception and control stack would respond to in the same way it would respond to the real-world equivalents.

The test of a digital twin’s validity is not whether it looks realistic to a human observer. It is whether the system being tested behaves in the digital twin as it would in the corresponding real scenario. A twin that produces beautiful photorealistic renders but whose simulated LiDAR point clouds have noise characteristics that differ from those of a real sensor will produce test results that do not transfer. A system that passes in simulation may fail in the field, not because the scenario was wrongly constructed but because the sensor simulation was insufficiently faithful to the physics of the hardware it was supposed to represent.

The components that define simulation fidelity

A production-grade digital twin for ADAS validation has several interdependent components. The vehicle dynamics model must replicate how the test vehicle responds to control inputs under realistic conditions, including stress scenarios like emergency braking on reduced-friction surfaces. 

The environment model must replicate road geometry, surface material properties, and surrounding road user behavior in physically grounded ways. And the sensor simulation layer, where most of the difficulty lives, must replicate how each sensor in the multisensor fusion stack responds to the simulated environment, including the degradation modes that matter most for safety testing: LiDAR scatter in precipitation, camera behavior under low light, and radar multipath behavior near metallic infrastructure. Sensor simulation fidelity is the component that most frequently limits the usefulness of digital twin validation in practice, and it is the one most directly dependent on the quality of underlying real-world annotation data.

Sensor Simulation Fidelity: The Core Technical Challenge

LiDAR simulation and why physics matters

LiDAR is among the most demanding sensors to simulate accurately. Real sensors fire discrete laser pulses and measure the time of flight of reflected light. The returned point cloud is shaped by scene geometry, surface reflectivity, and atmospheric conditions affecting pulse propagation. Rain, fog, and airborne particulates all introduce scatter that modifies the point cloud in ways that directly affect the perception algorithms operating on it and the 3D LiDAR annotation used to build ground-truth training data for those algorithms.

A high-fidelity LiDAR simulator must model the angular resolution and range characteristics of the specific sensor being tested, apply realistic reflectivity based on material properties of every surface in the scene, and introduce atmospheric degradation that varies with simulated weather conditions. 

High-fidelity digital twin framework incorporating real-world background geometry, sensor-specific specifications, and lane-level road topology produced LiDAR training data that, when used to train a 3D object detector, outperformed an equivalent model trained on real collected data by nearly five percentage points on the same evaluation set. That result illustrates the ceiling for what high-fidelity simulation can achieve. It also illustrates why fidelity is non-negotiable: a simulator that misrepresents surface reflectivity or atmospheric scatter will generate a training-validation gap that no amount of hyperparameter tuning will fully close.

Camera simulation and the domain adaptation problem

Camera simulation presents a structurally different set of challenges. Real automotive cameras are complex electro-optical systems with specific spectral sensitivities, noise floors, lens distortions, rolling shutter effects, and dynamic range limits. A simulation that renders scenes using a game engine’s default camera model produces images that differ from real sensor output in precisely the conditions where safety matters most: low light, the edges of dynamic range, and environments where lens flare or bloom are factors.

Two main approaches have emerged for closing this gap. Physics-based camera models, which simulate light propagation, surface material interactions, lens optics, and sensor electronics explicitly, produce high-fidelity outputs but are computationally intensive. Data-driven approaches using neural rendering techniques, including neural radiance fields and Gaussian splatting, can reconstruct real-world scenes with high realism at lower computational cost for captured environments, but they lack the flexibility to generate novel scenarios that differ substantially from the captured training distribution. Most mature programs use a combination, applying physics-based modeling for safety-critical validation scenarios where fidelity is paramount and data-driven rendering for large-scale scenario sweeps where throughput is the priority.

Radar simulation

Radar simulation is arguably harder than LiDAR or camera simulation because the electromagnetic phenomena involved are more complex and less amenable to the ray-tracing approximations that work reasonably well for optical sensors. Physically accurate radar simulation must model multipath reflections, Doppler frequency shifts from moving objects, polarimetric properties of target surfaces, and the interference patterns that arise in dense traffic. 

Unreal Engine environment represents one of the more mature approaches to this problem, generating detailed radar returns including tens of thousands of reflection points with accurate signal amplitudes within a photorealistic simulation environment. For ADAS programs increasingly moving toward raw-data sensor fusion rather than object-list fusion, this level of radar simulation fidelity becomes necessary for meaningful validation rather than an optional enhancement.

The Data Infrastructure Behind a Reliable Digital Twin

Real-world data as the foundation

A digital twin does not materialize from scratch. The environment models, sensor calibration parameters, traffic behavior distributions, and road geometry that populate a production-grade digital twin all derive from real-world data collection and annotation. Building a digital twin of a specific urban intersection requires photogrammetric capture of the intersection’s three-dimensional geometry, material property data for each road surface element, and empirical traffic behavior data characterizing how vehicles and pedestrians actually move through the space. All of that data requires annotation before it becomes usable. DDD’s simulation operations services are built around exactly this dependency, ensuring that data feeding a simulation environment meets the standards the environment needs to produce trustworthy test results.

The quality chain is direct and unforgiving. An environment model built from inaccurately annotated photogrammetric data misrepresents road geometry in ways that propagate through every test run conducted in that environment. Surface material properties that are incorrectly labeled produce incorrect sensor outputs, which produce incorrect model responses, none of which will transfer to real hardware. The annotation quality of the underlying real-world data is not a secondary consideration in digital twin validation. It is the foundation on which everything else depends.

Scenario libraries and how they are constructed

The value of a digital twin validation program is proportional to the breadth and coverage quality of the scenario library it tests against. A scenario library is a structured collection of test cases, each specifying the environment type, initial vehicle state, behavior of surrounding road users, any infrastructure conditions relevant to the test, and the expected system response. Building a comprehensive library requires systematic analysis of the operational design domain, identification of safety-relevant scenario categories within that domain, and construction of specific annotated instances of each category in a format the simulation environment can execute.

This is where ODD analysis and edge case curation connect directly to the digital twin workflow. ODD analysis defines the boundaries of the operational domain the system is designed for, determining which scenario categories belong in the test library. Edge case curation identifies the rare, safety-critical scenarios that most need simulation coverage precisely because they cannot be reliably encountered in real-world fleet testing. Together, they determine what the digital twin program actually validates, and gaps in either translate directly into gaps in the safety case.

Annotation for sensor simulation validation

Validating sensor simulation fidelity requires annotated real-world data collected under conditions corresponding to the simulated scenarios. If the digital twin needs to simulate a junction at dusk in moderate rain, the validation process requires real sensor data from a comparable junction under comparable conditions, with relevant objects annotated to ground truth, so simulated sensor outputs can be quantitatively compared against what real hardware produces. 

This is a specialized annotation task sitting at the intersection of ML data annotation and sensor physics. It requires annotators who understand multi-modal sensor data structures and the physical processes that determine whether a simulated output is genuinely faithful to real hardware behavior. Teams that treat this as a commodity annotation task tend to discover the inadequacy of that assumption when their simulation results diverge from real-world performance at an inopportune moment.

What Simulation Can Reach That Physical Testing Cannot

The categories simulation was designed for

The strongest argument for digital twin validation is the coverage it provides in scenario categories where physical testing is genuinely impractical. Dangerous scenarios top that list. A test of how an AEB system responds when a child runs from behind a parked car directly into the vehicle’s path cannot be safely conducted with a real child. In a digital twin, that scenario can be executed thousands of times, with systematic variation of the child’s speed, trajectory, starting distance, the vehicle’s initial speed, road surface friction, and ambient light. Each variation is reproducible on demand, producing runs that physical testing cannot replicate under controlled conditions.

Weather extremes offer another category where simulation provides coverage that physical testing cannot schedule reliably. Dense fog at sunrise over wet asphalt, heavy snowfall on a motorway approach, direct sun glare at a westward-facing junction at late afternoon: all can be parameterized in a high-fidelity digital twin and tested systematically. A physical program that wanted equivalent weather coverage would need to wait for the right meteorological conditions, mobilize quickly when they appeared, and accept that exact conditions could not be reproduced for follow-up runs after a system change. The reproducibility advantage of simulation alone, independent of scale, provides meaningful validation depth that physical testing cannot match.

The domain gap as a structural limit

The domain gap between simulation and reality remains the fundamental constraint on how far digital twin evidence can be pushed without physical corroboration. No matter how high the fidelity, there will be aspects of the real world that the simulation does not capture with full accuracy. The question is not whether the gap exists but how large it is for each relevant scenario category, which performance dimensions it affects, and whether the scenarios that produce passing results in simulation are the same scenarios that would produce passing results on a test track.

Quantifying the domain gap requires a systematic comparison of system behavior in matched simulation and real-world scenarios. This is expensive to do comprehensively, so most programs use it selectively, validating the twins’ fidelity for specific scenario categories and calibrating confidence in simulation evidence accordingly. Programs that skip this calibration, treating simulation results as equivalent to physical test results without establishing the fidelity basis, build a safety case on a foundation they have not verified.

Hardware-in-the-loop as a bridge

Hardware-in-the-loop testing, where real ADAS hardware connects to a virtual environment that provides synthetic sensor inputs in real time, occupies a useful middle ground between pure software simulation and track testing. HIL setups allow actual ADAS ECUs and perception stacks to process synthetic sensor data under real timing constraints, catching failure modes that arise from hardware-software interaction but would not surface in a purely software simulation. The sensor injection systems required for HIL testing, which convert simulated sensor outputs into the electrical signals a real ECU expects, are themselves complex engineering systems whose fidelity contributes to the overall validity of the results they produce.

What a Mature Digital Twin Validation Program Actually Looks Like

The validation pyramid

Mature digital twin validation programs organize their testing across a layered architecture. At the base are large-scale automated simulation runs testing individual functions across broad scenario spaces, potentially covering millions of test cases. In the middle layer are hardware-in-the-loop tests validating software-hardware integration for critical scenarios. At the top are track evaluations and limited real-world testing that calibrate confidence in simulation results and satisfy regulatory physical test requirements. Performance evaluation against a stable, versioned scenario library in simulation provides a consistent regression benchmark that physical testing cannot replicate, since track conditions and ambient environment vary unavoidably between test sessions.

The ratio of simulation to physical testing has been shifting steadily toward simulation as digital twin fidelity improves and regulatory acceptance grows. Programs that were running most of their validation miles on physical roads five years ago may now be running the majority of their scenario coverage in simulation, with physical testing focused on calibration runs, regulatory demonstrations, and specific scenario categories where the domain gap is known to be larger and where physical corroboration carries more weight.

Continuous integration and the speed advantage

One structural advantage of digital twin validation over physical testing is its natural compatibility with continuous integration development workflows. A software update that would take weeks to validate through track testing can be run against a full scenario library in simulation overnight. Development teams can catch regressions quickly and maintain a higher release cadence without sacrificing validation coverage. 

Autonomous driving programs increasingly use simulation-based regression testing as a gating requirement for software changes, ensuring that every modification is validated against the full scenario library before being promoted to the next development stage. The economics of this approach favor programs that invest early in building a well-maintained, high-coverage scenario library that grows with the program.

The feedback loop from deployment

Digital twin environments are most valuable when they remain connected to real-world operational experience. Incidents from deployed vehicles, near-miss events flagged by safety operators, low-confidence detection events, and novel scenario types identified through ODD monitoring should all feed back into the digital twin scenario library, generating new test cases that directly address the failure modes operational deployment has revealed. This feedback loop transforms a digital twin from a static artifact built at program initiation into a living development tool that improves as the program matures. Programs that treat their scenario library as fixed after initial validation are leaving most of the long-term value of digital twin validation on the table.

Common Failure Modes in Digital Twin Validation Programs

Overconfidence in simulation results

The failure mode that most frequently undermines digital twin programs in practice is treating simulation results as equivalent to physical test results without establishing the fidelity basis that would justify that equivalence. A team that runs hundreds of thousands of simulation test cases and reports a high pass rate has produced meaningful evidence only if the simulation environment has been validated against real-world data for the tested scenario categories. Without that validation, high simulation pass rates can provide a false sense of security. The scenarios that fail in the real world may be precisely the scenarios for which the simulation was least faithful to actual physics.

Scenario library gaps

Another common failure mode is scenario library gaps, where the set of test cases run in simulation does not reflect the actual breadth of the operational design domain. Teams sometimes build libraries around the scenarios that are easiest to generate rather than the ones that are most safety-relevant. The edge case curation process is specifically designed to address this problem, identifying rare but high-consequence scenarios that must be covered regardless of the difficulty of constructing them in simulation. A digital twin program whose scenario library has not been systematically reviewed for ODD coverage gaps is likely to have tested the easy scenarios comprehensively and the important ones insufficiently.

Annotation quality in the simulation foundation

A third major failure mode is annotation quality problems in the underlying real-world data used to build or calibrate the simulation environment. Environmental geometry that is inaccurately captured, material properties that are mislabeled, or traffic behavior data that is unrepresentative of the actual deployment environment all degrade simulation fidelity in ways that are often invisible until real-world performance diverges from simulation predictions. 

Teams that invest heavily in simulation tooling but treat the underlying data annotation as a commodity task typically discover this mismatch at the worst possible moment. High-quality annotation in the simulation foundation data is not optional. It is among the most cost-effective investments in overall simulation program quality available.  

How DDD Can Help

Digital Divide Data provides dedicated digital twin validation services for ADAS and autonomous driving programs, supporting the data and annotation workflows that underpin effective simulation-based testing. DDD’s approach starts from the recognition that a digital twin is only as reliable as the data that builds and validates it, and that annotation quality in the underlying real-world data determines whether simulation results actually transfer to real-world performance.

On the simulation foundation side, DDD’s simulation operations capabilities support scenario library development, simulation environment data annotation, and systematic validation of sensor simulation fidelity against annotated real-world reference datasets. DDD annotation teams trained in multisensor fusion data produce the high-quality labeled datasets needed to validate whether simulated LiDAR, camera, and radar outputs match real-world sensor behavior under the conditions that matter most for safety testing.

For programs preparing regulatory submissions that include simulation-based evidence, DDD’s safety case analysis and performance evaluation services support the documentation and evidence generation required to demonstrate that the digital twin validation program meets the credibility standards regulators and certification bodies expect. 

Talk to our expert and accelerate your ADAS validation program with a simulation-backed data infrastructure built to production quality.

Conclusion

Digital twin validation is not a shortcut around the hard work of ADAS development. It is a way of doing that work more thoroughly than physical testing can reach on its own. The scenarios that matter most for safety are precisely the ones physical testing cannot encounter efficiently: the rare, the dangerous, and the meteorologically specific. 

A well-built digital twin, grounded in high-quality annotated data and systematically validated against real sensor outputs, makes it possible to test those scenarios deliberately, repeatedly, and at a scale that produces evidence meaningful enough to support both internal safety decisions and regulatory submissions. The teams that build this capability well, treating sensor simulation fidelity and annotation quality as foundational requirements rather than implementation details, will validate more completely, iterate more quickly, and produce safety cases that hold up under scrutiny from regulators who are themselves becoming more sophisticated about what credible simulation evidence actually looks like.

Regulators are not accepting all simulation results: they are accepting results from environments that have been demonstrated to be fit for purpose. That demonstration requires the same careful attention to data quality, annotation standards, and systematic validation that governs the rest of the Physical AI development pipeline. Digital twin validation does not reduce the importance of getting data right. If anything, it raises the stakes, because the credibility of every test result that flows through the simulation depends on the quality of the real-world data the simulation was built from and calibrated against.

References

Alirezaei, M., Singh, T., Gali, A., Ploeg, J., & van Hassel, E. (2024). Virtual verification and validation of autonomous vehicles: Toolchain and workflow. IntechOpen. https://www.intechopen.com/chapters/1206671

Volvo Autonomous Solutions. (2025, June). Digital twins: The ultimate virtual proving ground. Volvo Group. https://www.volvoautonomoussolutions.com/en-en/news-and-insights/insights/articles/2025/jun/digital-twins–the-ultimate-virtual-proving-ground.html

Siemens Digital Industries Software. (2025, August). Unlocking high fidelity radar simulation: Siemens and AnteMotion join forces. Simcenter Blog. https://blogs.sw.siemens.com/simcenter/siemens-antemotion-join-forces/

United Nations Economic Commission for Europe. (2024). Guidelines and recommendations for ADS safety requirements, assessments, and test methods. UNECE WP.29. https://unece.org/transport/publications/guidelines-and-recommendations-ads-safety-requirements-assessments-and-test

Frequently Asked Questions

How is a digital twin different from a conventional ADAS simulator?

A digital twin is continuously calibrated against real-world sensor data and validated to ensure its outputs match real hardware behavior, whereas a conventional simulator approximates reality without that ongoing fidelity verification and calibration loop.

What sensor is hardest to simulate accurately in a digital twin?

Radar is generally the most difficult to simulate with full physical accuracy because electromagnetic phenomena such as multipath reflection and Doppler effects require computationally expensive full-wave modeling, whereas LiDAR and camera simulation can be approximated more tractably with existing methods.

How often should a digital twin scenario library be updated?

Scenario libraries should be updated continuously as operational data reveals new edge cases, ODD boundaries shift, or system changes introduce new failure modes, rather than being treated as static artifacts constructed once at program initiation.

Digital Twin Validation for ADAS: How Simulation Is Replacing Miles on the Road Read Post »
In-Cabin AI

In-Cabin AI: Why Driver Condition & Behavior Annotation Matters

As vehicles move toward higher levels of automation, monitoring the human behind the wheel becomes just as important as monitoring traffic. When control shifts between machine and driver, even briefly, the system must know whether the person in the seat is alert, distracted, fatigued, or simply not paying attention.

Driver Monitoring Systems and Cabin Monitoring Systems are no longer optional features available only on premium trims. They are becoming regulatory expectations and safety differentiators. The conversation has shifted from convenience to accountability.

Here is the uncomfortable truth: in-cabin AI is only as reliable as the quality of the data used to train it. And that makes driver condition and behavior annotation mission-critical.

In this guide, we will explore what in-cabin AI actually does, why understanding human state is far more complex, how annotation defines system performance, and what a practical labeling taxonomy looks like.

What In-Cabin AI Actually Does

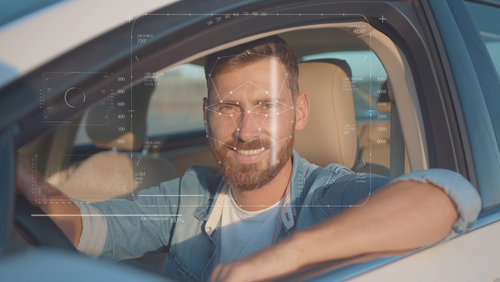
At a practical level, In-Cabin AI observes, measures, and interprets what is happening inside the vehicle in real time. Most commonly, that means tracking the driver’s face, eyes, posture, and interaction with controls to determine whether they are attentive and capable of driving safely.

A typical system starts with cameras positioned on the dashboard or steering column. These cameras capture facial landmarks, eye movement, and head orientation. From there, computer vision models estimate gaze direction, blink duration, and head pose. If a driver’s eyes remain off the road for longer than a defined threshold, the system may classify that as a distraction. If eye closure persists beyond a certain duration or blink frequency increases noticeably, it may indicate drowsiness. These are not guesses in the human sense. They are statistical inferences built on labeled behavioral patterns.

What makes this especially complex is that the system is continuously evaluating capability. In partially automated vehicles, the car may handle steering and speed for extended periods. Still, it must be ready to hand control back to the human. In that moment, the AI needs to assess whether the driver is alert enough to respond. Is their gaze forward? Are their hands positioned to take control? Have they been disengaged for the past thirty seconds? The system is effectively asking, several times per second, “Can this person safely drive right now?”

Understanding Human State Is Hard

Detecting a pedestrian is difficult, but at least it is visible. A pedestrian has edges, motion, shape, and a defined spatial boundary. Human internal state is different. Monitoring a driver involves subtle behavioral signals. A slight head tilt, a prolonged blink, a gaze that drifts for a fraction too long.

Interpretation depends on context. Looking left could mean checking a mirror. It could mean looking at a roadside billboard. The model must decide. And the data is inherently privacy sensitive. Faces, eyes, expressions, interior scenes. Annotation teams must handle such data carefully and ethically.

A model does not learn fatigue directly. It learns patterns mapped from labeled behavioral signals. If the annotation defines prolonged eye closure as greater than a specific duration, the model internalizes that threshold. If distraction is labeled only when gaze is off the road for more than two seconds, that becomes the operational definition.

Annotation is the bridge between pixels and interpretation. Without clear labels, models guess. With inconsistent labels, models drift. With carefully defined labels, models can approach reliability.

Why Driver Condition and Behavior Annotation Is Foundational

In many AI domains, annotation is treated as a preprocessing step. Something to complete before the real work begins. In-cabin AI challenges that assumption.

Defining What Distraction Actually Means

Consider a simple scenario. A driver glances at the infotainment screen for one second to change a song. Is that a distraction? What about two seconds? What about three? Now, imagine the driver checks the side mirror for a lane change. Their gaze leaves the forward road scene. Is that a distraction?

Without structured annotation guidelines, annotators will make inconsistent decisions. One annotator may label any gaze off-road as a distraction. Another may exclude mirror checks. A third may factor in steering input. Annotation defines thresholds, temporal windows, class boundaries, and edge case rules.

  • How long must the gaze deviate from the road to count as a distraction?
  • Does cognitive distraction require observable physical cues?
  • How do we treat brief glances at navigation screens?

These decisions shape system behavior. Clarity creates consistency, and consistency supports defensibility. When safety ratings and regulatory scrutiny enter the picture, being able to explain how distraction was defined and measured is not optional. Annotation transforms subjective human behavior into measurable system performance.

Temporal Complexity: Behavior Is Not a Single Frame

A micro sleep may last between one and three seconds. A single frame of closed eyes does not prove drowsiness. Cognitive distraction may occur while gaze remains forward because the driver is mentally preoccupied. Yawning might signal fatigue, or it might not. If annotation is limited to frame-by-frame labeling, nuance disappears.

Instead, annotation must capture sequences. It must define start and end timestamps. It must mark transitions between states and sometimes escalation patterns. A driver who repeatedly glances at a phone may shift from momentary distraction to sustained inattention. This requires video-level annotation, event segmentation, and state continuity logic.

Annotators need guidance. When does an event begin? When does it end? What if signals overlap? A driver may be fatigued and distracted simultaneously.

The more I examine these systems, the clearer it becomes that temporal labeling is one of the hardest challenges. Static images are simpler. Human behavior unfolds over time.

Handling Edge Cases

Drivers wear sunglasses. They wear face masks. They rest a hand on their chin. The cabin lighting shifts from bright sunlight to tunnel darkness. Reflections appear on glasses. Steering wheels partially occlude faces. If these conditions are not deliberately represented and annotated, models overfit to ideal conditions. They perform well in controlled tests and degrade in real traffic.

High-quality annotation anticipates these realities. It includes occlusion flags, records environmental metadata such as lighting conditions, and captures sensor quality variations. It may even assign confidence scores when visibility is compromised. Ignoring edge cases is tempting during early development. It is also costly in deployment.

Building a Practical Annotation Taxonomy for In-Cabin AI

Taxonomy design often receives less attention than model architecture. A well-structured labeling framework determines how consistently human behavior is represented across datasets.

Core Label Categories

A practical taxonomy typically spans multiple dimensions. Some organizations prefer binary labels. Others choose graded scales. For example, distraction might be labeled as mild, moderate, or severe based on duration and context.

The choice affects model output. Binary systems are simpler but less nuanced. Graded systems provide richer information but require more training data and clearer definitions.

It is also worth acknowledging that certain states, especially emotional inference, may be contentious. Inferring stress or aggression from facial cues is not straightforward. Annotation teams must approach such labels with caution and clear criteria.

Multi-Modal Annotation Layers

Systems often integrate RGB cameras, infrared cameras for low light performance, depth sensors, steering input, and vehicle telemetry. Annotation may need to align visual signals with CAN bus signals, audio events, and sometimes biometric data if available. This introduces synchronization challenges.

Cross-stream alignment becomes essential. A blink detected in the video must correspond to a timestamp in vehicle telemetry. If steering correction occurs simultaneously with gaze deviation, that context matters. Unified timestamping and structured metadata alignment are foundational.

In practice, annotation platforms must support multimodal views. Annotators may need to inspect video, telemetry graphs, and event logs simultaneously to label behavior accurately. Without alignment, signals become isolated fragments. With alignment, they form a coherent behavioral narrative.

Evaluation and Safety: Annotation Drives Metrics

Performance measurement depends on labeled ground truth. If labels are flawed, metrics become misleading.

Key Evaluation Metrics

True positive rate measures how often the system correctly detects fatigue or distraction. False positive rate measures over-alerting. A system that identifies drowsiness five seconds too late may not prevent an incident.

Missed critical events represent the most severe failures. Robustness under occlusion tests performance when visibility is impaired. Each metric traces back to an annotation. If the ground truth for drowsiness is inconsistently defined, true positive rates lose meaning. Teams sometimes focus heavily on model tuning while overlooking annotation quality audits. That imbalance can create a false sense of progress.

The Cost of Poor Annotation

Alert fatigue occurs when drivers receive excessive warnings. They learn to ignore the system. Unnecessary disengagement of automation frustrates users and reduces adoption. Legal exposure increases if systems cannot demonstrate consistent behavior under defined conditions. Consumer trust declines quickly after visible failures.

Regulatory penalties are not hypothetical. Compliance increasingly requires clear evidence of system performance. Annotation quality directly impacts safety certification readiness, market adoption, and OEM partnerships. In many cases, annotation investment may appear expensive upfront. Yet the downstream cost of unreliable behavior is higher.

Why Annotation Is the Competitive Advantage

Competitive advantage is more likely to emerge from structured driver state definitions, comprehensive edge case coverage, temporal accuracy, bias-resilient datasets, and high-fidelity behavioral labeling. Companies that invest early in deep taxonomy design, disciplined annotation workflows, and safety-aligned validation pipelines position themselves differently.

They can explain their system decisions. They can demonstrate performance across diverse populations. They can adapt definitions as regulations evolve. In a field where accountability is rising, clarity becomes currency.

How DDD Can Help

Developing high-quality driver condition and behavior datasets requires more than labeling tools. It requires domain understanding, structured workflows, and scalable quality control.

Digital Divide Data supports automotive and AI companies with specialized in-cabin and driver monitoring data annotation solutions. This includes:

  • Detailed driver condition labeling across distraction, drowsiness, and engagement categories
  • Temporal event segmentation with precise timestamping
  • Occlusion handling and environmental condition tagging
  • Multi-modal data alignment across video and vehicle telemetry
  • Tiered quality assurance processes for consistency and compliance

Driver monitoring data is sensitive and complex. DDD applies structured protocols to ensure privacy protection, bias awareness, and high inter-annotator agreement. Instead of treating annotation as a transactional service, DDD approaches it as a long-term partnership focused on safety outcomes.

Partner with DDD to build safer in-cabin AI systems grounded in precise, scalable driver behavior annotation.

Conclusion

Autonomous driving systems have become remarkably good at interpreting the external world. They can detect lane markings in heavy rain, identify pedestrians at night, and calculate safe following distances in milliseconds. Yet the human inside the vehicle remains far less predictable. 

If in-cabin AI is meant to bridge the gap between automation and human control, it has to be grounded in something more deliberate than assumptions. It has to be trained on clearly defined, carefully labeled human behavior.

Driver condition and behavior annotation may not be the most visible part of the AI stack, but it quietly shapes everything above it. The thresholds we define, the edge cases we capture, and the temporal patterns we label ultimately determine how a system responds in critical moments. Treating annotation as a strategic investment rather than a background task is likely to separate dependable systems from unreliable ones. As vehicles continue to share responsibility with drivers, the quality of that shared intelligence will depend, first and foremost, on the quality of the data beneath it.

FAQs

How much data is typically required to train an effective driver monitoring system?
The volume varies depending on the number of behavioral states and environmental conditions covered. Systems that account for multiple lighting scenarios, demographics, and edge cases often require thousands of hours of annotated driving footage to achieve stable performance.

Can synthetic data replace real-world driver monitoring datasets?
Synthetic data can help simulate rare events or challenging lighting conditions. However, human behavior is complex and context-dependent. Real-world data remains essential to capture authentic variability.

How do companies address bias in driver monitoring systems?
Bias mitigation begins with diverse data collection and balanced annotation across demographics. Ongoing validation across population groups is critical to ensure consistent performance.

What privacy safeguards are necessary for in-cabin data annotation?
Best practices include anonymization protocols, secure data handling environments, restricted access controls, and compliance with regional data protection regulations.

How often should annotation guidelines be updated?
Guidelines should evolve alongside regulatory expectations, new sensor configurations, and insights from field deployments. Periodic audits help ensure definitions remain aligned with real-world behavior.

References

Deans, A., Guy, I., Gupta, B., Jamal, O., Seidl, M., & Hynd, D. (2025, June). Status of driver state monitoring technologies and validation methods (Report No. PPR2068). TRL Limited. https://doi.org/10.58446/laik8967
https://www.trl.co.uk/uploads/trl/documents/PPR2068-Driver-Fatigue-and-Attention-Monitoring_1.pdf

U.S. Government Accountability Office. (2024). Driver assistance technologies: NHTSA should take action to enhance consumer understanding of capabilities and limitations (GAO-24-106255). https://www.gao.gov/assets/d24106255.pdf

Cañas, P. N., Diez, A., Galvañ, D., Nieto, M., & Rodríguez, I. (2025). Occlusion-aware driver monitoring system using the driver monitoring dataset (arXiv:2504.20677). arXiv.
https://arxiv.org/abs/2504.20677

In-Cabin AI: Why Driver Condition & Behavior Annotation Matters Read Post »

in cabin2Bmonitoring2Bsolutions2Bfor2Bautonomous2Bvehicles

In-Cabin Monitoring Solutions for Autonomous Vehicles

As autonomous vehicles (AVs) move steadily toward higher levels of automation, the focus on safety and performance has broadened. As vehicles assume more control, understanding the in-cabin monitoring systems on how occupants behave, respond, or require assistance becomes just as critical.

This includes being able to detect medical emergencies, unsafe or erratic behavior, improper use of safety restraints, or situations that could compromise privacy or security.

In-cabin monitoring is no longer a supplementary feature but a prerequisite for intelligent systems that can personalize experiences, improve crash response through adaptive airbag deployment, and even provide fallback control in critical scenarios. As autonomy shifts human drivers into passive occupants, the car must become contextually aware of what is happening inside.

This blog explores in-cabin monitoring solutions for autonomous vehicles and highlights the key functions, critical technologies driving their development.

Key Functions of In-Cabin Monitoring Systems in AVs

In-Cabin Monitoring Systems (ICMS) encompass a range of technologies and models designed to assess and interpret the state of the vehicle’s occupants and interior environment. These systems are not monolithic; rather, they comprise several interrelated subsystems, each responsible for a specific function that contributes to overall safety, comfort, and user personalization. Below are the core components that define modern ICMS implementations:

Driver Monitoring Systems (DMS):
With higher levels of driving automation, the driver transitions from a constant operator to a fallback-ready user. This makes it essential to assess driver readiness and cognitive state in real time. DMS typically tracks fatigue, distraction, intoxication, and gaze or attention level. AI models process facial landmarks, eye movement, and head pose to infer whether the driver is alert and capable of resuming control if needed.

Occupant Monitoring Systems (OMS):
OMS focuses on the broader cabin, ensuring that all passengers are accounted for and safe. This includes detecting seat occupancy, verifying seatbelt usage, identifying children or unattended passengers, and assessing occupant posture. Systems must adapt to complex seating configurations and dynamically identify scenarios such as a child sleeping in a booster seat or an adult reclining across two seats.

Environmental Monitoring
While not core to all ICMS, environmental sensing enhances occupant safety and comfort by tracking lighting conditions, in-cabin temperature, and air quality. This data can support automatic climate adjustments or trigger alerts in the case of unsafe air or thermal levels.

Emergency Detection
A growing area of focus is identifying medical or behavioral emergencies. These include detecting if a passenger has fainted, is unresponsive, or is displaying aggressive or erratic movements. This capability is critical for shared AVs where there is no human driver to intervene in real-time.

Together, these functions form the backbone of ICMS, enabling vehicles to move beyond reactive safety and toward proactive, context-aware decision-making.

Personalization Features

The role of ICMS is no longer confined to safety. These systems now underpin personalization features, adjusting climate settings, recommending media, or even modifying airbag deployment based on occupant age or posture.

This dual-purpose trajectory is shaping industry standards and pushing automakers to think of ICMS not only as a regulatory requirement but as a strategic advantage. With regulatory bodies in regions like the EU mandating DMS in new vehicle models, widespread adoption is inevitable.

As the industry transitions into autonomy at scale, ICMS will become central to how vehicles understand and interact with humans, both drivers and passengers alike.

Technologies Powering In-Cabin Monitoring Systems

The effectiveness of In-Cabin Monitoring Systems hinges on a tightly integrated stack of sensors, computer vision models, and AI algorithms. These technologies work together to interpret complex, real-world occupant behavior with speed and precision. As the automotive industry evolves, so does the sophistication of the tools powering ICMS.

Sensor Suite: From RGB to mmWave
ICMS begins with data collection, and the choice of sensors plays a critical role in performance. Most systems use a mix of RGB cameras, infrared (IR) sensors for night vision, and Time-of-Flight (ToF) or depth cameras to capture three-dimensional spatial data. In some cases, mmWave radar is added to provide robust detection even in occluded conditions (e.g., blankets covering a child) or poor lighting. While LiDAR has proven valuable for external sensing, its in-cabin use is still limited due to cost and integration complexity.

Computer Vision and AI Models
Once data is captured, AI models process and analyze it in real-time. Common techniques include:

  • Object and Pose Detection: Frameworks like YOLO (You Only Look Once) and MTCNN (Multi-task Cascaded Convolutional Networks) are used to detect faces, hands, and body posture. These detections are crucial for downstream tasks like fatigue or gaze estimation.

  • Emotion and Demographic Classification: Convolutional Neural Networks (CNNs) and multi-modal classifiers are used to infer emotions, age, and gender, all of which can be inputs for adaptive systems such as climate control, infotainment preferences, or emergency response prioritization.

  • Activity Recognition: Advanced models trained on multi-task datasets can identify complex behaviors such as eating, texting, sleeping, or aggressive movement. These are essential for both safety and personalization.

Sensor Fusion Models
Combining modalities enhances system robustness. For example, radar + infrared fusion helps identify passengers in low-light conditions or when parts of the body are occluded. Sensor fusion also improves reliability across various environmental conditions, making the system suitable for 24/7 deployment in real-world scenarios.

Annotation and Dataset Requirements
Training accurate models requires extensive, high-quality data. ICMS datasets must include detailed annotations such as:

  • Facial keypoints and gaze vectors

  • Posture labels and pose classification

  • Multi-occupant scenarios with occlusions or overlapping bodies

Complex edge cases, like detecting a child in a booster seat while partially obscured by an adult, require custom annotation pipelines. Datasets like TICaM (Thermal In-Car Monitoring) offer a foundation, but real-world applications often demand project-specific data collection and labeling strategies.

Learn more: Simulation-Based Scenario Diversity in Autonomous Driving: Challenges & Solutions

In-Cabin Monitoring Solutions for Autonomous Vehicles

As automotive companies race to build intelligent, context-aware vehicles, the demand for high-quality annotated data to train In-cabin monitoring systems has never been greater. This is where Digital Divide Data (DDD) plays a pivotal role. With deep expertise in behavioral data annotation and AI workflow integration, DDD enables AV companies to accelerate the development and deployment of in-cabin monitoring solutions.

Specialized Expertise in DMS and OMS
DDD’s annotation teams are trained to label complex behavioral signals essential for Driver and Occupant Monitoring Systems. Whether it’s detecting micro-expressions that indicate fatigue or accurately labeling multi-occupant postures, DDD provides the precision and context needed to train reliable models.

Custom Annotation Pipelines for Complex Scenarios
No two ICMS projects are the same. From labeling facial keypoints in low-light conditions to identifying subtle gestures across overlapping bodies, DDD develops custom pipelines tailored to each client’s model architecture and objectives. These pipelines include bounding boxes, segmentation masks, gaze tracking, posture classification, and gesture labeling, delivered with consistent accuracy at scale.

Global Workforce, Localized Compliance
With a global talent pool trained on safety-critical annotation workflows, DDD combines speed and scalability with high-quality results. Annotations undergo multiple layers of validation, often using human-in-the-loop (HITL) systems that ensure continuous learning and refinement.

HITL-Driven Feedback Loops
To maximize model performance, DDD integrates continuous feedback mechanisms between annotation teams and client-side model developers. This enables active learning, where challenging edge cases, such as partial occlusions or ambiguous gestures, are iteratively labeled and used to retrain models for improved accuracy.

Learn more: Enhancing In-Cabin Monitoring Systems for Autonomous Vehicles with Data Annotation

Conclusion

As vehicles move closer to full autonomy, In-Cabin Monitoring Systems (ICMS) are emerging as foundational components, not just for safety, but for delivering intelligent, human-centric experiences. From detecting driver fatigue to adapting cabin environments based on occupant behavior, ICMS is shaping how future vehicles will interact with passengers.

This transformation demands more than just sophisticated algorithms; it requires precise, context-aware data to train systems that can interpret human nuances in real-time. As the automotive industry accelerates toward L4–L5 autonomy, the importance of high-quality annotated data and flexible, scalable labeling workflows cannot be overstated.

By bridging the gap between raw data and intelligent models, DDD empowers autonomous vehicle stakeholders to build ICMS that are safe, adaptive, and ready for real-world deployment.

To learn more, talk to our AV experts.

In-Cabin Monitoring Solutions for Autonomous Vehicles Read Post »

AdobeStock 595255234

The Crucial Link Between Data Annotation and Autonomous Cruise Control Systems

With the advancement of transportation technology, autonomous driving is slowly starting to seep into our vehicles every year, making them more independent and smarter. This is illustrated by advanced autonomous cruise control systems (ACC) that can receive live data and use predictions to adapt their speed to the traffic flow, making the ride both safe and comfortable.

These systems fuse information from Lidar, radar, ultrasound, video, thermal, and GPS sensors, each one comprehensively labeled to synthesize a “global view.”

Data annotation for autonomous driving is a way of tagging raw data to identify critical situations on the road for the ML models to react and make important decisions. This allows the autonomous vehicles to ‘see’ their environment such as identifying, classifying, and locating objects that are not only nearby but also differentiating between vehicles, pedestrians, and obstructions.

In this blog, we will explore the interlinking of data annotation with autonomous cruise control in autonomous vehicles, its various annotation techniques, and associated challenges.

Understanding Autonomous Cruise Control Systems

Autonomous+Cruise+Control

Autonomous cruise control (ACC) systems are an essential component of ADAS to incorporate features like lane keeping, traffic management, and automated steering. Instead of simple distance-keeping models with alarms, these systems have become automation wonders that use radar to control speed and prevent collision. Today, ACC systems not only improve the safety of the vehicle but drastically reduce congestion and rear-end collisions.

These technologies consist of sensors that detect and warn the driver about any potential threats or collisions when driving. For example; when this situation occurs a red light begins to flash with an alert showing ‘brake now’ appears on the dashboard, along with an audible warning to help the driver slow down the vehicle. The effective use of autonomous cruise control systems will maximize traffic flow due to its spatial awareness.

The Role of Data Annotation in Autonomous Cruise Control Systems

Data annotation is a big step in training data for autonomous cruise control. The process involves extensive and thorough identification and classification of data which considerably improves the training process for these systems. Machine learning algorithms need to be trained in different driving situations and scenarios to make these ACC systems highly accurate and safe in real-world situations.

Reorganizing this labeled data not only aids in its interpretation but subsequently reduces the amount of computational power required and increases the number of sensors that can be efficiently utilized. Whenever there are limited sensors or data available in any scenario, then a pre-annotated dataset can act as a booster for system performance. It enables the vehicle to evaluate different situations from various angles, improving its decision-making process.

Now that we have understood how data annotation helps ACC systems, let’s take a closer look at the different types of data annotation techniques and their use case scenarios.

  • Manual Annotation – As the name suggests, these are primary types of annotations where a human carries out the entire annotation process.

  • Bounding Box Labeling – This method is effective for fast detection, such as detecting cars or pedestrians. This means putting boxes around objects in an image and is a simple, low-effort labeling task.

  • Semantic Segmentation – This technique provides a label to every pixel of an image which specifies the category each object falls into, useful for more granular analysis and understanding of objects in the scene.

  • Instance Segmentation – Similar to semantic segmentation it goes further by distinguishing between different instances of the same type of object within the scene.

  • Lane and Drivable Area Marking – This is an annotation type that is particularly used for autonomous driving, lane marking, and marking the drivable area found by the vehicle.

  • Point Cloud Data Annotation – This technique is applied in 3D modeling, as it is used for labeling the data acquired from LiDAR sensors that are needed for constructing the vehicle’s understanding of its surroundings in three dimensions.

  • Video Motion Prediction – Annotating video data to predict future object motions for anticipatory actions in autonomous driving

  • Contextual or Sensor Data Annotation – This can be a specific set of labels according to context or sensor readings, used for certain scenarios or conditions.

These various data annotation services cater to different needs within autonomous cruise control systems, enhancing their performance and reliability by providing detailed and accurate data for training machine learning algorithms.

Challenges in Data Annotation for Autonomous Cruise Control

Data annotation is very complex when it comes to Autonomous Cruise Control systems. However, the biggest challenge is data collection. The root cause is ingrained in collecting diverse and comprehensive driving data in the most realistic driving scenarios. It is also difficult to obtain consistent data over different driving routes because it is nearly impossible to deliver a clean drive test on the exact same route with a consistent reference driver.

Let’s say that you have acquired high-quality data, the next challenge is to create labeling guidelines that do not too closely adhere to the reference driver behavior. This becomes a daunting task in an urban landscape, which is characterized by non-linear scenarios and variance in human driving styles. The chances are quite high for the ACC system to unknowingly learn poor driving behaviors from the data that mirrors the human driving behavior which may not be desirable.

In addition, modifying the guidelines on what is considered to be newer information or re-assessed behavior of data remains difficult. The process itself is prone to inherent biases, a common problem across machine learning applications but most amplified in traffic-related studies as those bear socio-legal implications. The intrinsic limitations of existing algorithms, combined with the practical constraints on resources for creating large new datasets, make this process unfeasible to execute at scale.

Quality Control

Accurate data annotations are critical, especially since wrong data can actually end up executing incorrect driving decisions and posing serious risks. Standardizing annotation is beneficial to ease the integration of diverse modules into a unified system. However, this standardization comes with its own errors due to discrepancies in the annotating process.

Some strategies to address these error types include a thorough

  • Training of annotators.

  • Multiple annotations by selected experts on the data.

  • Use of simpler ML models (i.e.: models trained only for assisting annotators).

  • Collaborative platforms where annotators can talk about edge cases.

Exploring advanced quality control mechanisms and developing new tools for training data could significantly improve the reliability of datasets used in autonomous driving. While each of these contributes to improved data quality, the variability associated with human judgment presents an ongoing challenge that is addressed through a combination of human factors and machine learning techniques as well as collaborative platforms.

Pathway to Innovation and Future Trends

Data annotation plays a pivotal role in the development of autonomous driving technologies, particularly by refining cruise control systems. Enhancing this process could potentially stem from collaborative efforts among researchers, practitioners, and industry leaders. This includes the integration of machine learning and automation to improve the scalability and efficiency of data annotation. Given the rapid advancements in computer vision and machine learning, they provide significant enhancements to image-based annotation methods which could considerably reduce time of implementation while tremendously increasing system precision.

An interesting direction for autonomous systems is shadow mode neural networks. These networks are trained on the same data inputs as traditional autopilot systems, but their response patterns are monitored based on what they do in real-time driving scenarios. This has the effect of incremental adaptation over time in reliability, whereby learning when exactly the vehicle should brake/be cautious when getting close to something.

Another avenue is with the accessibility of raw GPS data also appears to be heading toward a more unified approach globally. The goal is to create a common standard that would facilitate the sharing of this data and thus reduce the mistakes of navigation systems based on GPS information. An international incentive system using harmonized past trends will encourage more extensive collaboration among stakeholders possessing the data.

Furthermore, as this industry matures, the attention to regulatory and standardization principles is increasing, especially in annotation for data referring to how training of autonomous driving systems happens and what validity shall take place. Regulations governing driver licensing, vehicle safety ratings, and crash tests can also be used as a model for stricter annotation standards that could promote safer practices. Not only would it increase the accountability of driving, but also motivate car manufacturers to build safer cars.

Moving ahead, incorporating LiDAR data to measure Doppler shifts, could provide additional information about how fast other vehicles are moving improving autonomous systems to respond to changing speed environments. This is one step in a process that will involve thousands of experts over the years, all synthesizing many systems and challenging each other to navigate the safe adoption of these technologies into everyday use.

Resolving these aspects will bring us closer to truly reliable, efficient, and safer autonomous automobile solutions opening the path for the widespread acceptance and implementation of such technologies in the near future.

Read more: Ground Truth Data in Autonomous Driving – Challenges and Solutions

Final Thoughts

When it comes to Autonomous Cruise Control (ACC) systems, the importance of making quick decisions is critical when driving in the real world. Data annotation provides essential information that algorithms require to process and connect sensor data with operational systems. A well-trained output from these ADAS models allows these systems to recognize better and respond to hazards in challenging scenarios.

How Can We Help?

As a data labeling and annotation company, we provide comprehensive solutions for data annotation and labeling for autonomous cruise control systems to enhance reliability and safety in real-world situations. Talk to our experts about how DDD can help you with your autonomous driving projects.

The Crucial Link Between Data Annotation and Autonomous Cruise Control Systems Read Post »

In2Bcabin2Bmonitoring2Bsystems

Enhancing In-Cabin Monitoring Systems for Autonomous Vehicles with Data Annotation

Building autonomous vehicles begins by acknowledging the importance of in-cabin monitoring systems. While driving, occupants generate essential information such as user preferences and behavioral patterns, this data can be used as a foundation to build safer and more efficient autonomous vehicles.

Data annotation for driver monitoring systems labels relevant facial features, eye movement, and body postures to indicate signs of distraction and fatigue. This allows AI systems to alert the driver in case of emergency, prevent accidents, and make autonomous vehicles safer. In this blog, we will learn how driver monitoring systems work, what type of data is collected, and discuss the data annotation process for in-cabin monitoring systems.

What is an In-Cabin Monitoring System?

A driver monitoring system or in-cabin monitoring system for autonomous vehicles is a collection of software and hardware that monitor driver behavior and detect potential risks. These AI systems are trained using a variety of driver data, sensors, and cameras to detect any potential threat and send warning signals accordingly.

How does it work?

A driver monitoring system utilizes a driver-facing camera, installed into the vehicle’s dashboard or dash cam. These cameras capture facial expressions and movements using LED lights. After analyzing every movement AI systems get a better picture of the driver’s state of mind, attentiveness, and safety.

These devices check variations of the driver and signal decreased driving abilities whenever necessary. For example, a person constantly blinking may suggest fatigue and the driver needs to rest. These warning signs are generally displayed on a control panel, notified by sound alerts, and vibrations in the steering wheel. Other signs of driver monitoring systems include head tilting, eye constrictions, driver behavior analysis, driver distraction monitoring, speed monitoring, and more.

What type of data is collected in-cabin monitoring?

The sensors track eye movements, facial expressions, and body posture to assess the concentration and alertness of the driver. It also senses the position of passengers to optimize safety features and comfort settings.

Real-time information is collected from sensors and cameras about the vehicle’s interior and exterior surroundings. These systems capture and analyze driver behavior and passenger presence, so AI can quickly respond to dynamic situations keeping in mind safety, efficiency, and comfortable driving.

Data Annotation for In-Cabin Monitoring 

The process of annotating in-cabin monitoring data includes meticulously labeling diverse data sets containing information from the vehicle’s sensors and cameras. Accurate tagging of data requires human annotators and automated systems to accurately tag sensory and visual data with specific metadata. This includes annotating specific points in images to mark the driver’s position and actions, enabling AI systems to predict and analyze behavior. Accurate annotations enable AI systems to predict driver behavior and enhance the safety of autonomous vehicles.

How Annotation Improves the Accuracy and Reliability of Monitoring Systems

Data annotation for driver monitoring systems improves its accuracy and reliability by providing appropriate labeled data that allows ML to recognize and interpret driving patterns effectively. Annotated data sets enable monitoring systems to accurately distinguish between normal and abnormal behavior, enhancing the system’s ability to make real-time decisions. The iterative approach of training data for monitoring systems leads to more refined and accurate algorithms capable of making decisions in real-time.

Types of Annotations for in-cabin monitoring

Bounding Boxes in driver monitoring systems involve drawing boxes around persons or objects in an image or video. These bounding boxes specify the position and boundary of the individuals present inside the cabin, allowing systems to identify and track occupants. Human annotators use various tools to annotate and structure raw sensor data for ML models.

Semantic segmentation is used to label each pixel of an image to an integrated class of objects. This allows systems to distinguish between different objects, and elements in the background and identify the overall context of the scene by segmenting road, sky, and other vehicles in the environment.

Keypoint Annotation is used to identify precise anatomical features of occupants, such as their nose, mouth, eyes, and joints for pose estimation, gesture recognition, and drowsiness detection. Additionally, they are used in identifying and analyzing facial expressions and emotional labels that determine the emotional condition such as sad, happy, and surprised corresponding to facial expressions.

Object Recognition allows annotating different objects inside the cabin to help recognize and classify objects such as electronic devices, bags, and more to enhance understanding of the cabin.

Temporal segmentation tracks the time intervals during specific activities within the cabin such as eating, reading, talking, or using mobile devices.

Challenges in Annotating Diverse In-Cabin Activities

Due to the variability and complexity of human behavior inside the cabin annotating diverse activities can pose various challenges. To analyze subtle facial expressions to identify fatigue to normal, reflexes during emergencies, requires highly accurate and precise annotations to work effectively. Additionally, varying lighting conditions can obscure visual data in videos and images which can pose challenges for annotators to identify and annotate accurately.

Privacy and Data Security Concerns In-Cabin Monitoring 

Deploying DMS raises various concerns about data security and privacy. Continuously monitoring vehicle occupants and collecting sensitive information such as biometric data and facial expressions, require a rigorous procedure to safeguard privacy. In these scenarios, data anonymization can be utilized to remove or mask personally identifiable information to protect personal data.

Driver monitoring systems can unlock new possibilities to prioritize user trust and regulatory compliance. Gesture control systems can allow intuitive interchange among infotainment systems and vehicle control, which can enhance driver convenience and reduce distraction. Furthermore, vital sign monitoring can be utilized to detect subtle physiological changes such as fatigue, stress, and medical emergencies and potentially save lives.

Occupant personalization, gesture control, and vital sign monitoring should comply with data protection regulations such as the (GDPR) General Data Protection Regulation. These systems must offer transparency to their users so occupants understand what type of data is collected, who is collecting it, and how it’s being used. The human-in-the-loop process anonymizes data training and assures that data handling meets legal requirements.

By learning individual preferences, DMS can customize the in-cabin experience for each user as per his needs and comfort. This personalization includes adjusting the driver seat, and climate control, and suggesting a personalized music playlist. As vehicles transcend into higher levels of autonomy, Driver management systems will be highly adaptable in transitioning from manual to autonomous driving modes. By monitoring the driver’s engagement, DMS can ensure safe handoffs to avoid accidents caused by complacency or disengagement.

Read More: Top 8 Use Cases of Digital Twin in Autonomous Driving

The Future of In-Cabin Monitoring Systems

DMS is critical for autonomous driving to ensure the safety of the vehicle and occupants, using advanced computer vision, behavioral analysis, and object detection to mitigate risks. However, real-world environments are inherently complex and unpredictable which requires adaptable monitoring systems backed by diverse training data of high quality. These systems must be trained using data where HITL data labeling is involved to ensure AI models interpret surroundings accurately.

As technology advances, in-cabin monitoring systems are realizing their potential, but it’s important to address the ethical and societal implications. Striking an equilibrium between innovation and human values is critical. The symbiotic relationship between driver management systems and humans-in-the-loop can be the driving force in this journey.

Read More: Utilizing Multi-sensor Data Annotation To Improve Autonomous Driving Efficiency

How Can DDD Help?

As a data labeling and annotation company, we utilize a human-in-the-loop process to refine the accuracy and reliability of in-cabin monitoring systems by ensuring high-quality data training, ethical protocols, real-world use cases, and exceeding performance standards. We are dedicated to transforming the future of autonomous driving with safer roads and more enjoyable journeys.

Enhancing In-Cabin Monitoring Systems for Autonomous Vehicles with Data Annotation Read Post »

Scroll to Top