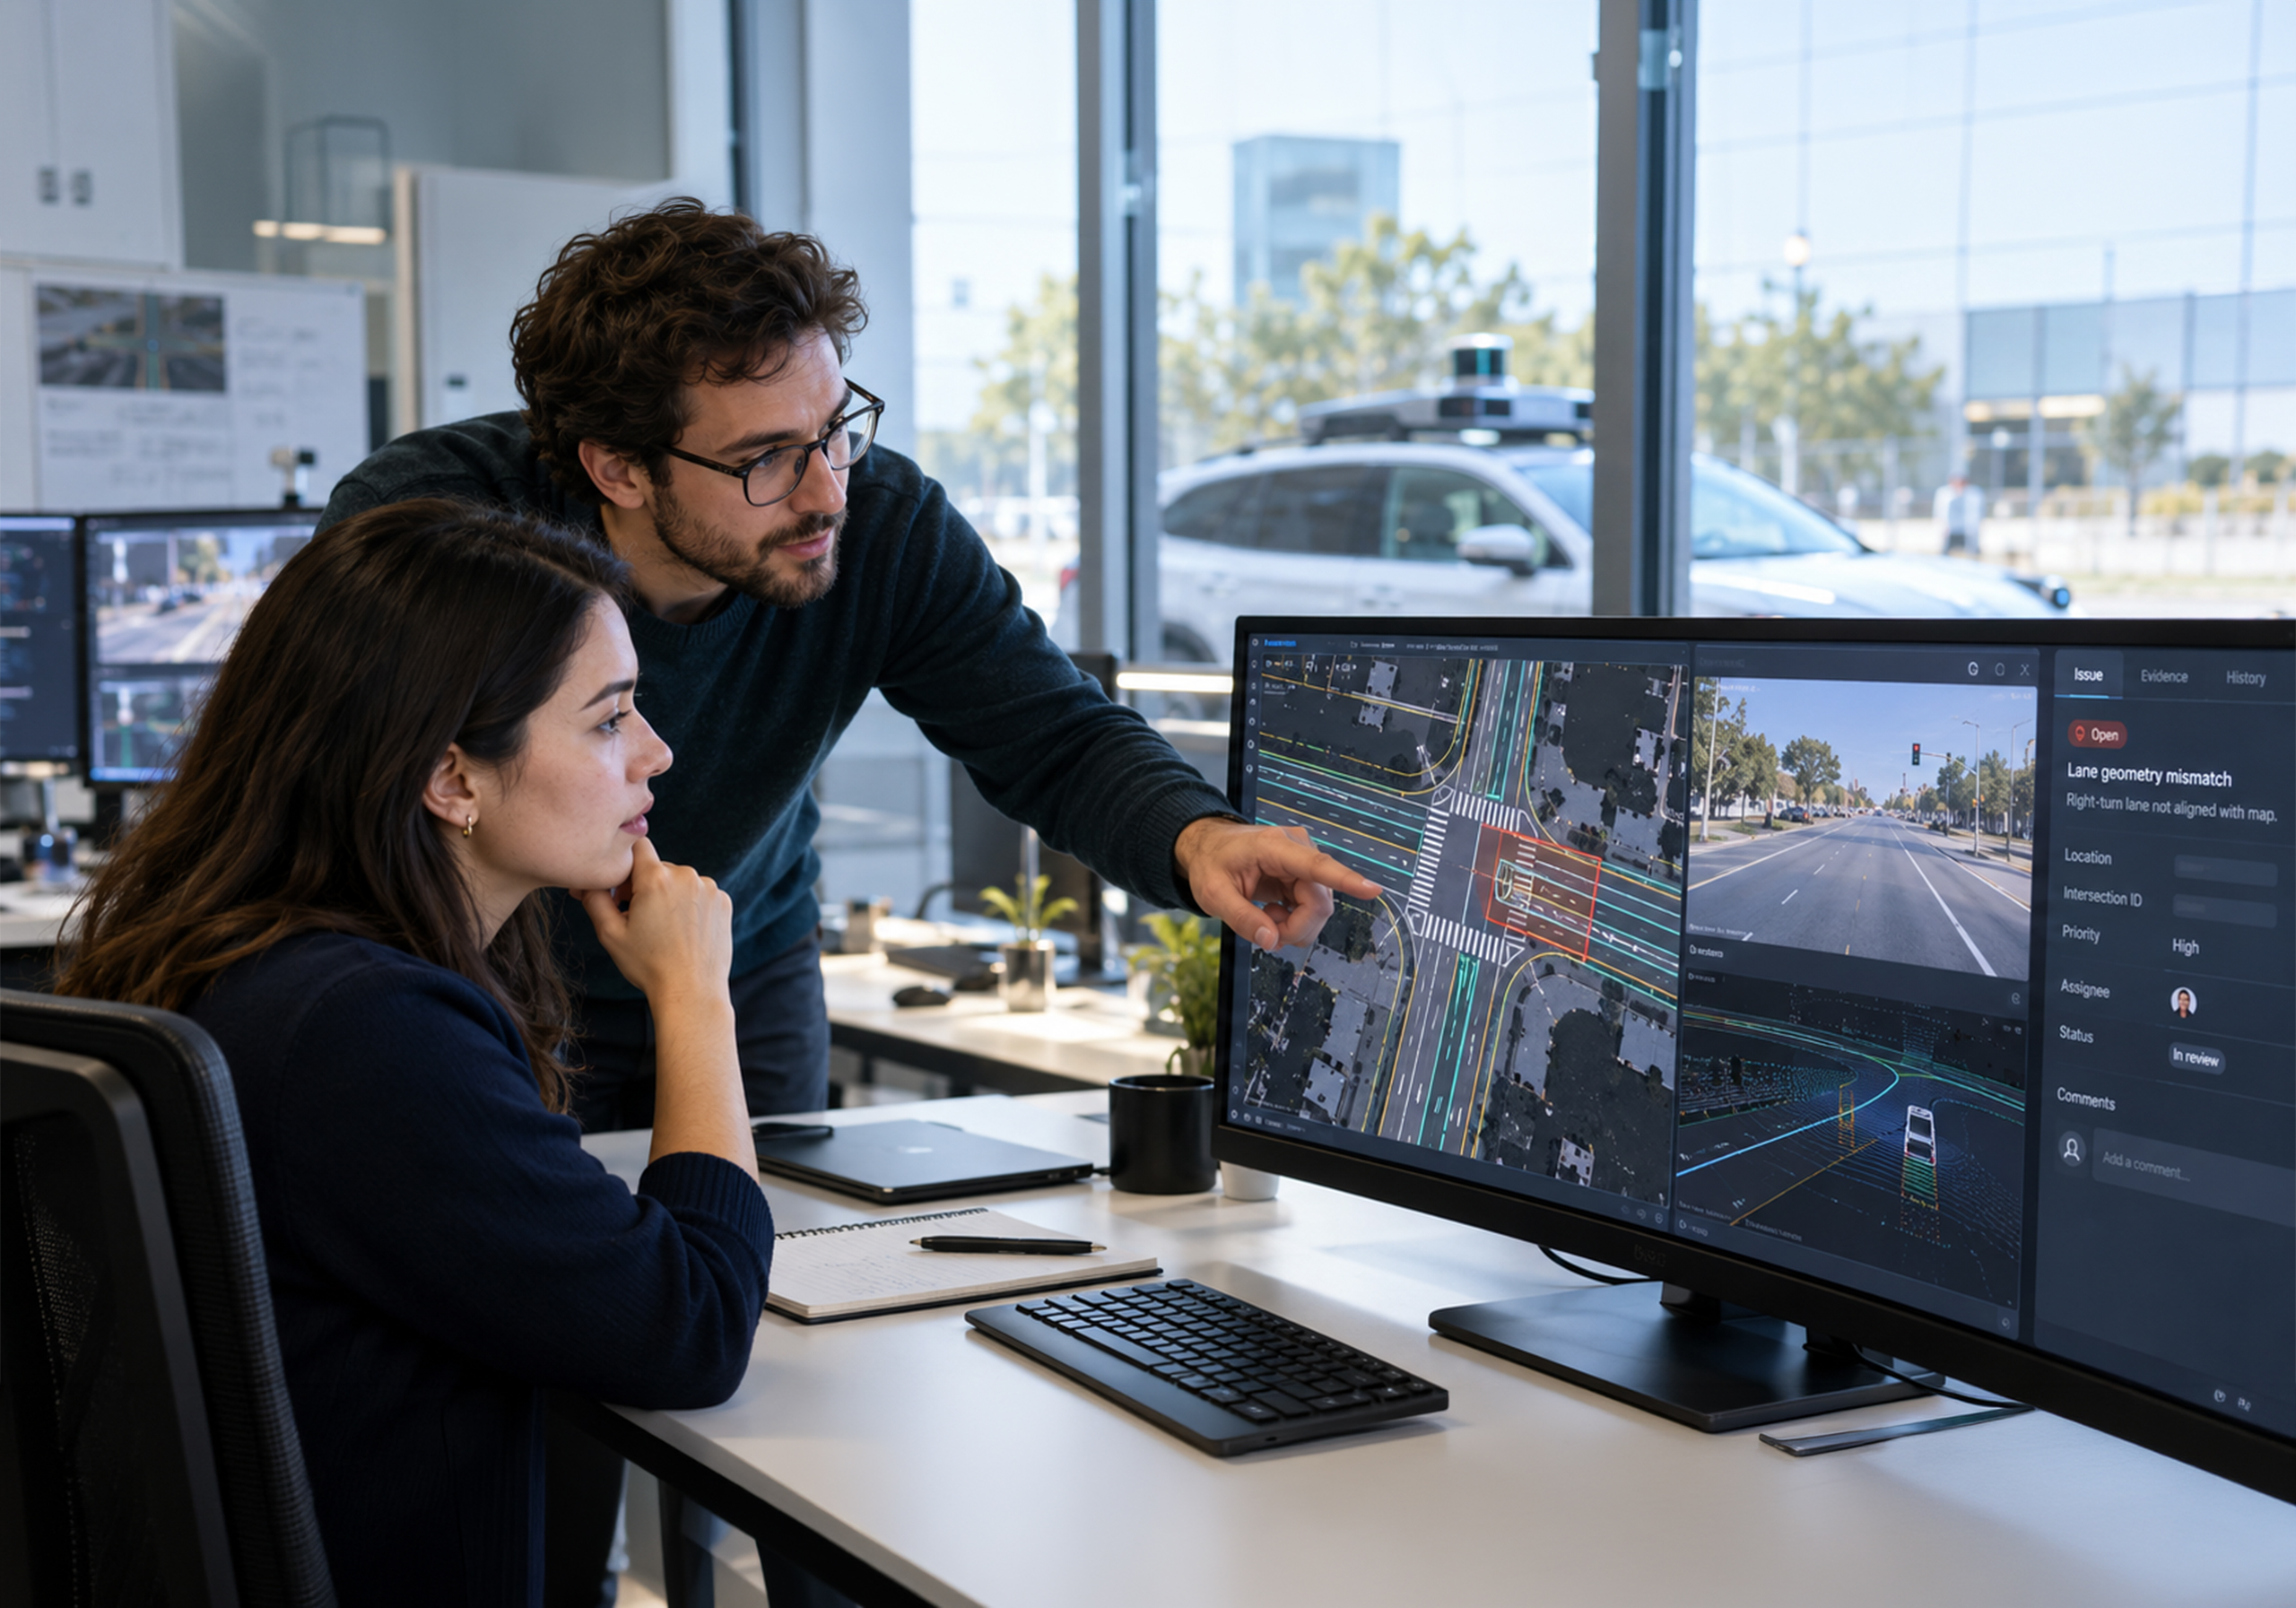
Autonomous driving map issue triage turns map defect signals into reproducible tickets, rates each defect by safety impact, routes it to the owner, and verifies the fix before release. Evidence that a triage program works includes tickets a second reviewer can replay, severity calls that survive independent review, and closure QA that rejects bad fixes. Whether triage runs in-house or through managed map issue triage services, a falling backlog says little unless reopen rates and escaped defects are tracked alongside it. The same discipline applies whether a correction lands in dense lane-level HD map annotation layers or in a lightweight ADAS map. For SAE Level 3 and Level 4 automated driving, the review must also check how the driving system responded when its map no longer matched the road.
Map defects do not fail evenly. A wrong point-of-interest name costs a little user trust, but a missing stop line or a broken lane connection can put a vehicle somewhere it should not be. The key questions involve what a ticket must contain, who sets severity, how duplicates merge, who commits the fix, and how anyone confirms the fix worked.
Key Takeaways
- Every map problem report should include the exact location, the map version used and supporting evidence, so someone else can check it and see the same problem.
- How dangerous a map mistake is and how soon it gets fixed are two separate decisions, and mixing them up can bury the most serious problems.
- Several reports about the same problem should be merged into one, and reports that disagree should be settled with fresh evidence before anyone changes the map.
- The team that owns each part of the map should make the final change, while the people reviewing reports suggest the fix and supply the proof.
- A second person should confirm that each fix solved the problem without breaking anything nearby, since a closed report does not always mean a correct map.
- When comparing programs or vendors, look for clearly defined numbers, especially how often fixed problems come back, because a count of closed reports says little on its own.
What Is Autonomous Driving Map Issue Triage?
Autonomous driving map issue triage is the process of receiving, verifying, classifying, and routing reports that a map no longer matches the road. It covers dense HD maps and lightweight sparse maps, plus the routing and attribute layers on top of them. Many defects first appear during performance evaluation of the autonomy stack, when a localization drop or a planning error traces back to the map. Teams also call this work map defect triage, map feedback triage, or HD map issue management.
An HD map is a centimetre-level model of the road with lane-level semantics such as boundaries, connectivity, signs, and speed limits. A 2023 survey of high-definition maps describes these maps as a strong prior that helps automated vehicles interpret their surroundings. That strength is also the risk. When the road changes and the map does not, the vehicle starts from a wrong assumption.
Researchers frame the detection side of this problem as HD map change detection. The Trust, but Verify study on HD map change detection defined it as deciding when sensor data and map data stop agreeing because the world changed. The authors also noted that dedicated mapping vehicles cannot revisit roads often enough, so maps go stale between surveys. If a stack treats a stale map as a hard prior, it can make confident decisions on outdated information.
Where do map issue signals come from?
Triage intake usually draws on several channels at once. Evidence quality varies by channel, so the intake form should record the source. A fleet disagreement flag arrives with sensor data, while a customer complaint may carry only a map pin. Common sources of map issue reports include the following.
- Fleet telemetry and map-disagreement flags from onboard perception.
- Disengagement and safety-driver reports tied to road segments.
- Automated map validation checks for topology, geometry, or attribute violations.
- Internal QA and simulation runs that expose routing or planning anomalies.
- Customer escalations and end-user feedback from navigation products.
- Feedback tools and APIs from third-party map providers.
What are the stages of a map triage workflow?
A dependable triage pipeline moves every report through the same states. Each state produces evidence that the next stage depends on. Skipping a stage usually shows up later as a reopened ticket.
- Intake: Capture source, location, map version, and evidence.
- Reproduce: A second reviewer confirms the same mismatch from the same evidence.
- Deduplicate: Link to a canonical ticket or open a new one.
- Assess severity: Rate impact against a written rubric.
- Prioritize and route: Schedule the fix and assign the owning team.
- Correct: The map owner edits the authoritative map database.
- Closure QA: An independent reviewer verifies the fix and checks for regressions.
- Release and monitor: Ship the build and watch for re-reports at that location.
How Does Map Triage Differ for SAE Level 3 and Level 4?
SAE Level 3 and Level 4 describe what an automated driving feature is responsible for, not newer versions of map software. At Level 3, the automated driving system (ADS) drives within defined conditions, but a fallback-ready user is expected to respond to a request to intervene. At Level 4, the ADS must also handle fallback within its operational design domain (ODD) without relying on a human driver. That difference changes the evidence a map triage team needs, even when the road defect is the same.
Imagine a newly closed lane that is still shown as open on the map. For a Level 3 feature, reviewers should check how the system detected the mismatch, whether it issued an appropriate request to intervene when needed, and what happened after the alert. The ticket should preserve the system mode, warning and response timestamps, driver response, and relevant sensor and planning logs. Correcting the map alone does not establish that the handover behavior was safe.
In a Level 4 service, there may be no driver available to take over. The review should therefore examine whether the ADS handled the closure safely, for example by rerouting or reaching a minimal risk condition if it could not continue. The team should also record the affected route or geofence, ODD conditions, any temporary operating restriction, and the evidence needed before that restriction is lifted. The right response depends on the system and the event; Level 3 and Level 4 do not prescribe one universal map format.
Both levels still need the basic map correction and independent QA described below. The additional check is whether the automated driving feature behaved appropriately during the original map disagreement. SAE’s Automated Vehicle Safety Consortium also recommends monitoring changes in the operating environment and evaluating any resulting safety concerns before normal operation resumes.
What Belongs in a Reproducible Autonomous-Map Issue Ticket?
A reproducible ticket is one that a reviewer who has never seen the report can open, replay, and reach the same conclusion. Many intake forms record what someone saw and leave out when, where, and on which map build. Map defects are tied to a place, a map build, and a moment in time. A ticket missing any of the three tends to bounce between teams. A complete ticket carries these fields:
- Location: Map tile ID, affected element IDs, and coordinates with the datum stated.
- Map version: The exact map build or release hash in use.
- Observation context: Timestamp, drive or log ID, vehicle software version, and heading.
- Automation context: The engaged SAE driving level, feature mode, applicable ODD conditions, and any intervention or fallback event relevant to the report.
- Evidence package: Camera frames, LiDAR snippets, or a bird’s-eye overlay of sensor data on the map.
- Observed vs. expected state: What the map says and what the road shows, in one sentence each.
- Defect class: A fixed-taxonomy value such as lane geometry, lane connectivity, regulatory attribute, localization landmark, or routing rule.
- Replay instructions: A log segment, simulation scenario, or route that reproduces the mismatch.
- Source and confidence: The channel that produced the report and how much corroboration exists.
The observed-versus-expected field does most of the work. It forces the reporter to state the defect in terms a map editor can act on. The timestamp matters almost as much, since a lane closure seen three weeks ago may have changed again.
Some reports cannot be reproduced from the evidence on hand. A good workflow gives these a needs-information state with its own clock, and lets triage request a re-drive or field check when sensor coverage is poor. Closing them as “cannot reproduce” tends to hide real defects, especially on roads the fleet rarely visits. The Trust, but Verify authors noted that real map changes are rare and must be located by hand in space and time, so thin evidence should be expected.
How Should Severity Differ From Ticket Priority?
Severity and priority answer different questions, and mixing them is a common triage error. Severity is a property of the defect: how much harm it could cause if the vehicle trusted the map at that location. Priority is a property of the schedule, including how soon the fix should ship, given exposure, release timing, and available mitigations. A high-severity defect on a road outside the operational design domain (ODD) may wait, while a moderate defect on a busy robotaxi route may move up the queue.
Severity should come from a written rubric applied by trained reviewers. Reporters should not choose it, because people tend to rate their own reports highest and the scale drifts. Priority belongs to the program or release owner, who can weigh fleet exposure against business commitments. When a team wants to defer a fix, it should lower the priority and leave the severity intact, so later queries for safety-critical defects stay accurate.
A four-level rubric is usually enough for map defects. Define each level by its effect on vehicle behavior. Draw the examples from the team’s own map layers so reviewers recognize them.
| Severity | Definition | Map defect examples |
|---|---|---|
| S1 Critical | Could lead to unsafe motion if the vehicle trusts the map | Lane connectivity into oncoming traffic; missing stop line; speed limit mapped above the legal limit |
| S2 Major | Degrades localization, routing, or compliance without direct collision risk | Shifted localization landmarks; missing turn restriction; stale lane marking type |
| S3 Minor | Affects comfort, efficiency, or route choice | Slightly wrong curvature on a gentle bend; incorrect road class that lengthens routes |
| S4 Cosmetic | No effect on vehicle behavior | Misspelled street name; offset point-of-interest pin |
Rubrics drift unless they are calibrated. Have two reviewers rate the same weekly sample of tickets independently, and track their agreement with a statistic such as Cohen’s kappa. Disagreements then become calibration examples that sharpen the rubric. A severity override rate, meaning the share of severities changed after initial triage, shows whether first-pass ratings can be trusted.
How Should Duplicate or Conflicting Map Reports Be Handled?
One real defect often produces many reports, especially on busy roads. Each duplicate should be linked to a single canonical ticket, and the report count should feed priority as a measure of exposure. Merging should keep a history of what was combined, so a wrong merge can be split later without losing evidence. A practical matching key combines the tile or element ID, the defect class, and a time window.
Matching does not need to start sophisticated. An empirical study of duplicate bug report detection found that a simpler technique beat newer, more complex ones on most projects in its benchmark. Data age and tracker choice also shifted its results. For map teams, that argues for starting with spatial and element-ID keys, measuring merge accuracy, and adding learned similarity only where simple keys fall short.
Conflicting reports are harder. Two vehicles may disagree about the same lane, or a fresh report may contradict a recent survey. Treat each conflict as an evidence-weighting problem: compare observation dates, sensor quality, and the number of independent observations on each side. Safety-critical reports can trigger an interim mitigation, such as routing around the segment, while corroboration builds. If the evidence still conflicts, keep the ticket blocked and request a re-drive or field check.
Temporary changes cause many of these conflicts. Work zones shift lanes for weeks and then revert, which is one reason construction-zone data gaps cause autonomous vehicle failures. Tickets should record whether a change looks temporary or permanent, because the fix differs. A temporary change may need a time-bound overlay, while a permanent one needs a base-map edit.
Who Makes the Final Map Correction?
The final correction should be made by the team that owns the authoritative map database for that layer. Triage diagnoses the defect and proposes a fix. The map owner commits the edit to the production map. Separate roles give every change a single, auditable path and stop two teams from fixing the same element in different ways.
Ownership usually follows the map layer and should be written down before the first ticket arrives. Ambiguous ownership is where tickets stall. A typical split looks like this:
- Lane geometry and topology: The HD map production team.
- Regulatory attributes such as speed limits and turn restrictions: The attribution or compliance team.
- Localization landmarks: The localization or mapping-infrastructure team.
- Routing graph and navigation rules: The routing team.
- Temporary overlays such as work zones: The live-map or operations team.
A triage team adds the most value when its proposed fix is precise enough for the owner to apply quickly. That means suggested geometry or attribute values, the evidence behind them, and alternate sources such as recent imagery. For S1 defects, a two-person rule is a sensible safeguard: one person edits and a second approves before the map build is cut. Every commit should reference the ticket ID, so the audit trail links evidence, decision, and change.
How Can Closure QA Catch a Bad Fix?
A ticket marked resolved is a claim, and closure QA is the step that tests it. Bad fixes happen often enough in map editing that skipping this step tends to inflate resolution numbers while the map stays wrong. The most frequent patterns are easy to name:
- The edit lands on the wrong element or the wrong side of a divided road.
- The fix is partial, such as corrected geometry with stale lane connectivity.
- The edit breaks neighbors, such as dangling lane successors after a deletion.
- The fix encodes a temporary condition as permanent.
- The change passes schema validation but contradicts the ticket’s sensor evidence.
Each pattern calls for a specific check. Closure QA should run the same sequence every time, and someone other than the editor should run it. The checks below run from cheapest to most expensive:
- Replay the original repro against the new map build and confirm the mismatch is gone.
- Review the change set at the element level and confirm it touches only the intended elements.
- Run topology and attribute validation across the surrounding tile to catch regressions.
- Check the fix against the newest available sensor evidence as well as the original report.
- For S1 and S2 defects, confirm vehicle behavior in log replay or simulation on the affected route.
- For an affected Level 3 feature, replay any request to intervene and its timing. For Level 4, check the ADS response within its ODD, including safe rerouting or a minimal risk response where applicable.
- After release, monitor for re-reports at the same location for a defined window.
The element-level review in step two is where many bad fixes surface. The ArgoTweak benchmark for self-updating HD maps breaks map updates into atomic changes such as geometry edits, marking changes, type changes, insertions, and deletions. Its authors showed that a single aggregate score like mean average precision can hide large differences in how well models update changed regions. They proposed scoring changed and unchanged regions separately, and closure QA benefits from the same split: verify the fix, then verify that nothing else moved.
Low-severity tickets do not always justify the full sequence. A common approach is to run full QA on every S1 and S2 fix and to audit a random sample of S3 and S4 closures. The audit sample should be large enough to estimate a closure error rate with a stated confidence interval.
Which Metrics Make Triage Case Studies Comparable?
Buyers evaluating triage vendors and leaders comparing internal programs run into the same problem. Case studies report numbers with different definitions, so a 40 percent improvement in one says little about another. Comparable evidence needs shared definitions, stated denominators, and splits by severity. The metrics below cover each stage of the workflow.
| Metric | What it shows | How to define it |
|---|---|---|
| Intake reproducibility rate | Ticket quality at intake | Share of tickets a second reviewer can replay without contacting the reporter |
| Needs-info and re-drive rate | Evidence gaps | Share of tickets needing more data before a decision |
| Duplicate merge accuracy | Deduplication quality | Share of audited merges confirmed as correct |
| Severity agreement | Rubric reliability | Cohen’s kappa between independent reviewers on a weekly sample |
| Severity override rate | First-pass accuracy | Share of severities changed after initial triage |
| Time to triage, by severity | Responsiveness | Median time from intake to severity and owner assigned |
| Time to verified fix, by severity | Throughput | Median time from intake to a closure QA pass |
| Closure QA rejection rate | Fix quality | Share of fixes sent back by closure QA |
| Reopen rate | Durability of fixes | Share of closed tickets reopened or re-reported at the same location within a set window |
| Escaped defect rate | End-to-end effectiveness | Defects found by the fleet after release that fell inside triage scope |
Two clocks deserve special attention. Time to triage and time to verify fix slip for different reasons, and a single time-to-close number hides which one is slipping. Reopen and closure QA rejection rates matter just as much, because they show whether speed came at the cost of correct fixes.
For Level 3 and Level 4 programs, also split results by the engaged feature and ODD. Where the client provides these signals, track map-related intervention requests for Level 3 and map-related reroutes or minimal risk events for Level 4. Counts should be considered alongside the number of relevant trips or miles, because the fleet’s exposure may change between reporting periods.
What evidence should a map triage case study include?
Metrics need context before anyone should trust them. A credible case study states the map layers and regions in scope, the severity rubric used, the sample size behind every percentage, and the time window. It should also show redacted example tickets, a calibration record, and the closure QA checklist that produced the numbers. Writing these definitions into contracts follows the same logic as service-level agreements for AI training datasets, where quality terms only hold when each one is measurable.
Some patterns in triage case studies should prompt follow-up questions. Each one hides information a buyer needs to judge the program. Watch for these:
- “Tickets closed” reported without a reopen rate.
- Average resolution time reported without a severity split.
- Accuracy percentages with no sampling method or sample size.
- Before-and-after comparisons that changed scope, region, or rubric between periods.
How Digital Divide Data Can Help
Digital Divide Data runs map issue triage for autonomous driving and ADAS programs as a managed workflow covering intake, verification, severity review, correction suggestions, and delivery. Engagements start with scoping: operational context, map types, issue categories, severity thresholds, and turnaround targets. DDD then builds the error taxonomy, sampling strategy, severity scoring rubric, and accepts or rejects criteria with the client team. GIS analysts and reviewers are trained on the client’s schemas, tools, and escalation paths before they work production tickets.
Intake can combine end-user feedback, QA findings, customer escalations, and fleet telemetry signals, and DDD works inside existing map provider tooling and APIs. Coverage spans road and routing defects, lane geometry and topology in HD map annotation and ADAS map layers, regulatory attributes, and POI data. Each ticket leaves with a clean repro package and a proposed fix backed by metadata and alternate sources the map owner can act on. Multi-level validation and regular calibration sessions keep severity calls consistent as volume grows. For work involving SAE Level 3 or Level 4 features, the agreed ticket template can also capture automation mode, ODD context, and fallback evidence supplied by the client.
Deliverables include issue reports, change logs, severity summaries, and GIS-ready outputs. DDD can stand up a triage pod in weeks, aligned to the client’s schemas, tools, and SLAs, under secure workflows for sensitive geospatial data. The aim is a triage record that holds up when a safety team or a buyer asks to see the evidence.
Build a map triage program whose closed tickets stay closed. Talk to a Map Expert.
Conclusion
Map triage produces two things: corrected map data and the evidence that each correction is right. Reproducible tickets make diagnosis fast, a calibrated severity rubric keeps attention on safety, clear ownership keeps edits auditable, and closure QA confirms each fix. Teams that measure reopen rates, severity agreement, and escaped defects can show a safety reviewer exactly why the map deserves trust. Teams that count only tickets closed tend to discover their bad fixes through the fleet. For Level 3 and Level 4 deployments, that evidence should also show how the driving system handled the mismatch, not only that the map changed.
Triage also sits inside a wider map program. Choices about map density shape what can break and who fixes it, a trade-off covered in DDD’s comparison of HD map annotation vs. sparse maps for physical AI.
References
Elghazaly, G., Frank, R., Harvey, S., & Safko, S. (2023). High-definition maps: Comprehensive survey, challenges, and future perspectives. IEEE Open Journal of Intelligent Transportation Systems. https://doi.org/10.1109/OJITS.2023.3295502
Lambert, J., & Hays, J. (2021). Trust, but verify: Cross-modality fusion for HD map change detection. Proceedings of the Neural Information Processing Systems Track on Datasets and Benchmarks. https://arxiv.org/abs/2212.07312
Wild, L., Valencia, R., & Jensfelt, P. (2025). ArgoTweak: Towards self-updating HD maps through structured priors. https://arxiv.org/abs/2509.08764
Zhang, T., Han, D., Vinayakarao, V., Irsan, I. C., Xu, B., Thung, F., Lo, D., & Jiang, L. (2023). Duplicate bug report detection: How far are we? ACM Transactions on Software Engineering and Methodology. https://arxiv.org/abs/2212.00548
Frequently Asked Questions
What should a map issue ticket include for an autonomous vehicle?
A good ticket includes the exact location and element IDs, the map build version, the time and drive log, and sensor evidence. It also states what the map shows versus what the road shows, the defect class, and how to replay the problem. The test is simple: someone who has never seen the report should be able to open it and reach the same conclusion.
What is the difference between severity and priority in map triage?
Severity describes how much harm a map defect could cause if the vehicle trusted it, and it comes from a written rubric. Priority describes how soon the fix should ship, based on things like how many vehicles drive that road and when the next release goes out. If a fix has to wait, teams should lower the priority and leave the severity unchanged.
How do you know if a map fix actually worked?
Someone other than the editor replays the original problem on the new map build. That reviewer confirms only the intended map elements changed and runs validation on the surrounding area. After release, the team watches for new reports at the same location, and a rising reopen rate is a sign that fixes are not holding.
Who makes the final correction to an autonomous vehicle map?
The team that owns the main map database for that layer makes the final edit. For example, the HD map production team fixes lane geometry and the compliance team fixes speed limits. The triage team diagnoses the issue and proposes a fix with evidence, and for the most serious defects a second person approves the change before release.
How does map issue triage differ between SAE Level 3 and Level 4?
Level 3 triage checks whether the system detects map errors, requests driver intervention when needed, and records the driver’s response. Level 4 triage focuses on how the vehicle handles map errors independently, through safe rerouting or fallback. Both require verified map corrections and checks to ensure the issue does not recur.
Udit Khanna leads the delivery of scalable AI and data solutions at Digital Divide Data, with a deep specialization in Physical AI. With a background in presales, solutioning, and customer success, he brings a mix of technical depth and business fluency, helping global enterprises move their AI projects from prototype to real-world deployment without losing momentum.