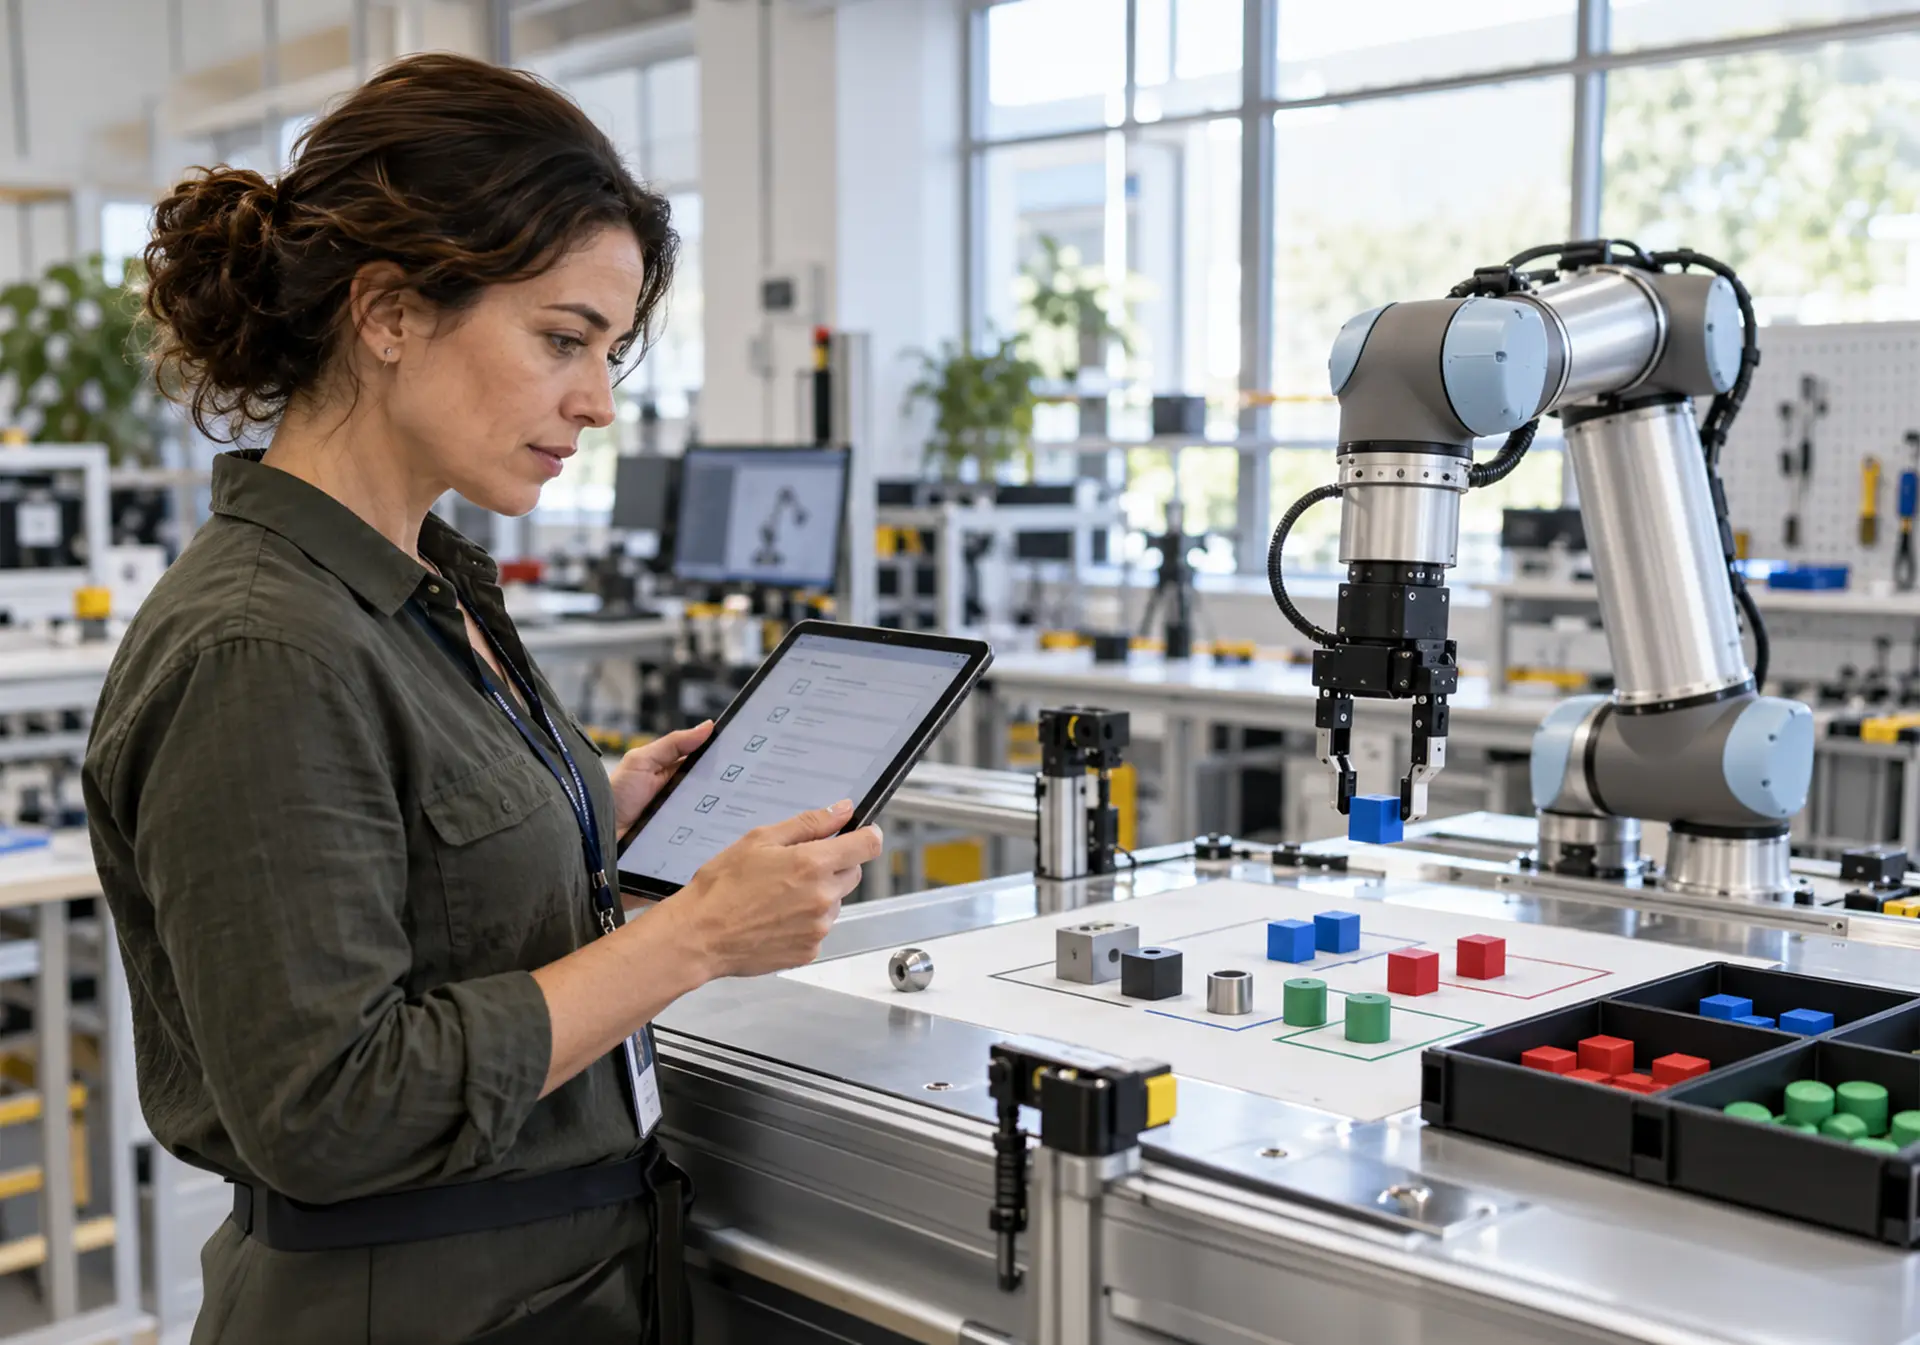
A physical AI validation test protocol is the agreed plan that defines what the system must do, how each behavior is tested, and what evidence counts as a pass. It links requirements to test cases, test cases to acceptance criteria, and results to a traceable evidence package. A credible partner delivering end-to-end product validation services should hand over the protocol, raw logs, a traceability matrix, and a report stating its limits. The release decision itself stays with the manufacturer.
Robotics and AV validation programs tend to stall for three reasons. Acceptance criteria were never made measurable, simulation results were presented as field evidence, or a past pass cannot be reproduced. Each is a protocol problem that tends to surface late, during a safety review or customer acceptance. Whether testing runs in-house or through an external performance evaluation supplier, the protocol decides whether the evidence holds up.
Key Takeaways
- A validation test plan spells out what a robot or self-driving system must do, how each behavior will be tested, and what result counts as a pass.
- Pass rules should be clear, measurable, and agreed before testing starts, so nobody can adjust them later to fit the results.
- A model that scores well on its own can still fail once it runs inside the real machine, so the model and the full product need separate testing.
- Computer simulations and recorded data let teams test many situations quickly, but the riskiest behaviors still need real-world testing.
- Results should be repeatable, which means recording the exact software, settings, and test conditions every time.
- A testing partner should share full records, including failures, but the final decision to launch stays with the company that builds the product.
What Is a Physical AI Validation Test Protocol?
A physical AI validation test protocol is a controlled, versioned document that specifies how a system’s intended behavior will be demonstrated in its intended operating conditions. It sits inside the wider discipline of product verification and validation, usually shortened to V&V. Its outputs feed safety case analysis for autonomous systems when a program must argue that residual risk is acceptable. Teams also call it a validation plan, test protocol, or acceptance test procedure (ATP).
A few terms need fixed meanings before drafting begins. Vendors and buyers often use them loosely, and that looseness turns into disputes at acceptance. This article uses these definitions:
- Verification: Verification asks whether the system was built to specification. Validation asks whether it meets user needs inside its Operational Design Domain (ODD).
- Test case: One executable check with defined preconditions, stimulus, expected outcome, and pass/fail rule.
- Acceptance criteria: Measurable thresholds agreed before testing, usually with a required sample size and confidence level.
- Acceptance evidence: The logs, recordings, metrics, and analysis showing whether each criterion was met.
Practice across the field is uneven. Automotive programs build V&V on ISO 26262 and ISO 21448 (SOTIF), and ISO/PAS 8800 now extends safety guidance to AI elements in road vehicles. Robotics programs using learned manipulation or vision-language-action (VLA) policies often lack a shared template, so buyers increasingly ask partners to show their protocol and evidence format upfront.
What Should a Physical AI Validation Protocol Contain?
A protocol earns its value by removing interpretation. Every requirement should map to at least one test case, every test case to a measurable criterion, and every criterion to a named evidence artifact. A complete protocol usually contains:
- Scope and intended use: Functions under validation, intended users, and exclusions.
- ODD and assumptions: environments, lighting, surfaces, payloads, human presence, and key assumptions.
- Requirements with unique IDs: Each traceable to a hazard, customer need, or regulation.
- Test case specifications: Preconditions, stimulus, expected behavior, and varied scenario parameters.
- Acceptance criteria: Thresholds, sample sizes, confidence levels, and failure and intervention rules.
- Evidence plan: Which tier (offline, simulation, hardware-in-the-loop, or field) satisfies each requirement.
- Configuration baseline: Software build, model checkpoint, firmware, calibration, and sensor layout.
- Entry and exit criteria: What must hold before a test campaign starts, and what closes it.
- Deviation and defect handling: How anomalies are logged, reproduced, triaged, and escalated.
- Roles and independence: who executes, who reviews, and who signs off.
What does a well-written test case look like?
The most common protocol weakness is a criterion nobody can execute. A line such as “the arm should handle parts safely and reliably” gives an evaluator nothing to measure. Research on behaviour-driven acceptance testing of robotic systems proposes writing criteria as Given-When-Then scenarios and running them across variations of robot, object, and environment. In their simulated pick-and-place tests, the same application behaved and failed differently as those variations changed, so each test case should list the parameters it varies.
Consider an illustrative criterion for a warehouse picking cell. Given a tote of approved SKUs under 300 to 1,000 lux, when the robot receives a pick request, it places the item in the target bin without collision. The pass rule could require at least 490 successes in 500 attempts, a 95% lower confidence bound of at least 96%, and every intervention counted as a failure. The numbers are placeholders, and the structure is what matters.
What acceptance evidence should a validation partner deliver?
Buyers evaluating a robotics validation partner should ask for a redacted sample of the evidence package before signing, since published case studies rarely show acceptance criteria in this detail. A useful package lets an internal reviewer re-check any claimed pass without calling the vendor. At minimum, it should include:
- The signed protocol version the tests ran against, with every approved deviation.
- A requirements traceability matrix linking requirement IDs to test cases, results, and evidence files.
- Raw and processed logs, sensor recordings, and video for every run, including failed and aborted runs.
- A defect log with reproduction steps, severity, and the configuration where each defect appeared.
- Metric summaries reporting sample sizes and confidence intervals alongside point estimates.
- A limitations section covering untested conditions, simulation fidelity gaps, and open assumptions.
How Is Model Validation Different From Product Validation?
Model validation asks whether a trained model performs as intended on representative data, using metrics such as precision and recall, trajectory error, or policy success rate. These are usually measured offline or in simulation. While, a product validation asks whether the integrated system, including sensors, compute, actuators, timing, and human operators, does its job in the real operating environment. The gap between the two is measurable.
A 2026 study of real-world perturbation testing of autonomous driving systems applied 72 camera and LiDAR perturbations offline, in hardware-in-the-loop, and on a full-scale vehicle. Some that barely moved offline metrics still pushed the vehicle out of its lane or into parked cars. Model-level metrics alone could not reliably flag the most damaging conditions.
| Dimension | Model validation | Product validation |
| Question answered | Does the model meet its targets on representative data? | Does the integrated system meet user needs in its ODD? |
| Unit under test | A trained model checkpoint | Hardware, software, model, and operator together |
| Typical environment | Offline datasets, log replay, simulation | Hardware-in-the-loop, closed course, field |
| Typical metrics | Precision, recall, trajectory error, success rate | Task success, intervention rate, latency, safety events |
| Role in release | Capability evidence | Deployment evidence |
Both belong in the protocol. Model validation is cheaper and faster, so it works well as a gate for which candidates reach hardware. Product validation is slower and costlier, so reserve it for evidence that only the integrated system can produce.
When Should Acceptance Criteria Be Agreed?
Acceptance criteria should be agreed and signed before the first test case runs. Criteria set after results arrive tend to drift toward whatever the system already achieves, which strips them of evidential value. Agreeing early also forces decisions on sample size, intervention rules, and ODD limits while they are still cheap to change. At sign-off, usually right after ODD definition, both parties should settle three points:
- What sample size and confidence level make a result defensible for this risk level?
- How are operator takeovers, timeouts, and aborted runs counted?
- Which conditions are excluded, and how will the report state those exclusions?
Agreement does not freeze criteria forever. Requirements evolve, and early tests sometimes show a threshold was unrealistic. The protocol should define who can propose a revision, what justification it needs, and how earlier results are treated. Changes made after results are visible should be logged as deviations and flagged in the final report.
How Should Hardware, Simulation, and Offline Evidence Be Combined?
No single test environment can carry a full validation program. Hardware and field testing offer realism but are slow, costly, and hard to repeat, while simulation and offline replay offer scale with fidelity gaps. The protocol should assign each requirement to the tier that can answer it credibly and define how results combine. A typical allocation:
- Offline replay and log-based evaluation: fast, open-loop regression on recorded data for perception and prediction metrics.
- Software-in-the-loop simulation: closed-loop behavior across many scenario variations, for planning logic and edge cases.
- Hardware-in-the-loop (HIL): real compute and interfaces against simulated inputs, for timing, latency, and integration.
- Closed-course and field testing: the real system in real conditions, for final confirmation and sim-to-real checks.
Simulation evidence should count only after its link to reality has been measured. Work on evaluating real-world robot manipulation policies in simulation ran more than 1,500 paired sim-and-real evaluations and reported strong correlation between the two. The authors earned that correlation by reducing control and visual mismatches, then measured it through paired runs. A protocol should require a similar correlation study before simulated passes count as evidence.
The same principle applies to digital twin validation for ADAS, where confidence in simulation depends on comparing system behavior across matched virtual and real-world scenarios. Offline results also need to be interpreted carefully because they do not always predict closed-loop behavior. Offline and simulation testing are therefore most useful for screening failures and expanding scenario coverage, while hardware and field testing should confirm the highest-risk behaviors before deployment.
What Makes a Validation Result Reproducible?
A validation result is reproducible when a different team, using the recorded configuration and inputs, can re-run the test and reach the same verdict. Physical systems make this harder because hardware wears, calibrations drift, and environments change between runs. Reproducibility therefore depends on recording everything that could change the outcome, along with the outcome itself.
The NIST AI Risk Management Framework calls for documenting the test sets, metrics, and tool details used during test, evaluation, verification, and validation (TEVV). These records cost little at test time and a great deal to reconstruct later. For physical AI, that means these controls:
- Version-locked software builds, model checkpoints, firmware, and calibration files, recorded by hash.
- Versioned scenario definitions and simulation seeds, so simulated runs can be regenerated exactly.
- Environment logs for field runs, covering lighting, temperature, surface condition, and layout.
- Every operator intervention, timeout, and abort kept in the record as data.
- Raw sensor data stored with processed metrics, so results can be re-scored if a metric changes.
Reproducibility also defines when to re-validate. The protocol should list triggers such as a new model checkpoint, a sensor or payload change, a firmware update, or an ODD expansion. Each trigger maps to a regression subset, so teams know which evidence still holds and which must be regenerated.
Does a Vendor Validation Report Approve a Product for Release?
A vendor validation report provides evidence, while the release decision remains with the manufacturer or operator. That decision is typically made by safety, quality, and engineering leadership based on the complete safety case. A validation partner can confirm that the defined tests were executed correctly and report which acceptance criteria were met or missed, but it cannot accept residual risk on the manufacturer’s behalf.
A well-written report makes this boundary explicit. It states the protocol version, configuration tested, criteria met and missed, and conditions left untested. It avoids words such as “certified” or “approved” unless an accredited body issued that status. Independence also matters, and it only counts when the partner reports failures as plainly as passes.
How Digital Divide Data Can Help
DDD runs validation as a managed lifecycle, from scoping and protocol design through environment setup, end-to-end and human-centered validation, and reporting. Within DDD’s product validation services, protocol design covers task workflows, functional checks, scenario sets, and acceptance criteria agreed before execution. Reports deliver pass/fail results, requirements traceability, and defect logs with reproduction steps. The work is platform-neutral and plugs into a client’s existing simulation tools and dashboards.
For simulation-heavy programs, DDD’s simulation operations (SimOps) services cover scenario generation and parameterization, orchestrated test execution, and frame-by-frame review of outputs with reality alignment checks. DDD teams also build traceability frameworks that tag results with scenario IDs, environment variables, and sensor configurations. Trained human evaluators review the ambiguous and safety-critical cases that automated checks tend to miss.
Every report is structured to feed the client’s safety case, with limitations stated alongside results. Audit-ready summaries can be tailored to regulatory contexts across automotive, robotics, defense, and medical devices. The release decision stays with the client, and the evidence is organized for independent review.
Build validation evidence that holds up at release review. Talk to an Expert.
Conclusion
A physical AI validation test protocol is where vague goals become checkable commitments. Its quality shows in details: criteria frozen before testing, interventions counted honestly, simulation trusted only after correlation, and limits written down. Programs that get these right move through safety review with fewer surprises. Programs that skip them tend to find their gaps late, often after a field incident or failed acceptance.
As learned policies and VLA models move into robots and vehicles, the distance between a strong benchmark score and a safe product will keep growing.
References
Lambertenghi, S. C., Weil, M., & Stocco, A. (2026). Real-world perturbation testing of autonomous driving systems. arXiv preprint arXiv:2607.04953. https://arxiv.org/abs/2607.04953
Li, X., Hsu, K., Gu, J., Pertsch, K., Mees, O., Walke, H. R., Fu, C., Lunawat, I., Sieh, I., Kirmani, S., Levine, S., Wu, J., Finn, C., Su, H., Vuong, Q., & Xiao, T. (2024). Evaluating real-world robot manipulation policies in simulation. Proceedings of the 8th Conference on Robot Learning (CoRL), PMLR 270. https://arxiv.org/abs/2405.05941
National Institute of Standards and Technology. (2023). Artificial Intelligence Risk Management Framework (AI RMF 1.0) (NIST AI 100-1). U.S. Department of Commerce. https://nvlpubs.nist.gov/nistpubs/ai/NIST.AI.100-1.pdf
Nguyen, M., Wrede, S., & Hochgeschwender, N. (2025). Automated behaviour-driven acceptance testing of robotic systems. IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS). arXiv:2507.05125. https://arxiv.org/abs/2507.05125
Frequently Asked Questions
What should a robotics validation partner deliver at the end of testing?
Expect the signed protocol version, a traceability matrix linking requirements to results, and raw logs for every run, including failures. The package should also include a defect log with reproduction steps, confidence intervals on key metrics, and a list of untested conditions.
Can simulation results replace real-world robot testing?
Simulation results should count as evidence only after a correlation study shows they track real-world performance, and the highest-risk behaviors should still be confirmed on hardware or in the field.
Who decides whether a robot or autonomous vehicle is ready for release?
The manufacturer or operator makes that call, usually through its safety, quality, and engineering leadership. A vendor validation report is evidence that feeds the decision and should state what was tested, what passed, what failed, and what was left untested.
Why do acceptance criteria need to be fixed before testing starts?
Criteria written after results are visible tend to drift toward whatever the system already achieves, which makes them weak evidence. Agreeing early also forces decisions on sample size, intervention rules, and ODD limits while those choices are still cheap to change.
Udit Khanna leads the delivery of scalable AI and data solutions at Digital Divide Data, with a deep specialization in Physical AI. With a background in presales, solutioning, and customer success, he brings a mix of technical depth and business fluency, helping global enterprises move their AI projects from prototype to real-world deployment without losing momentum.