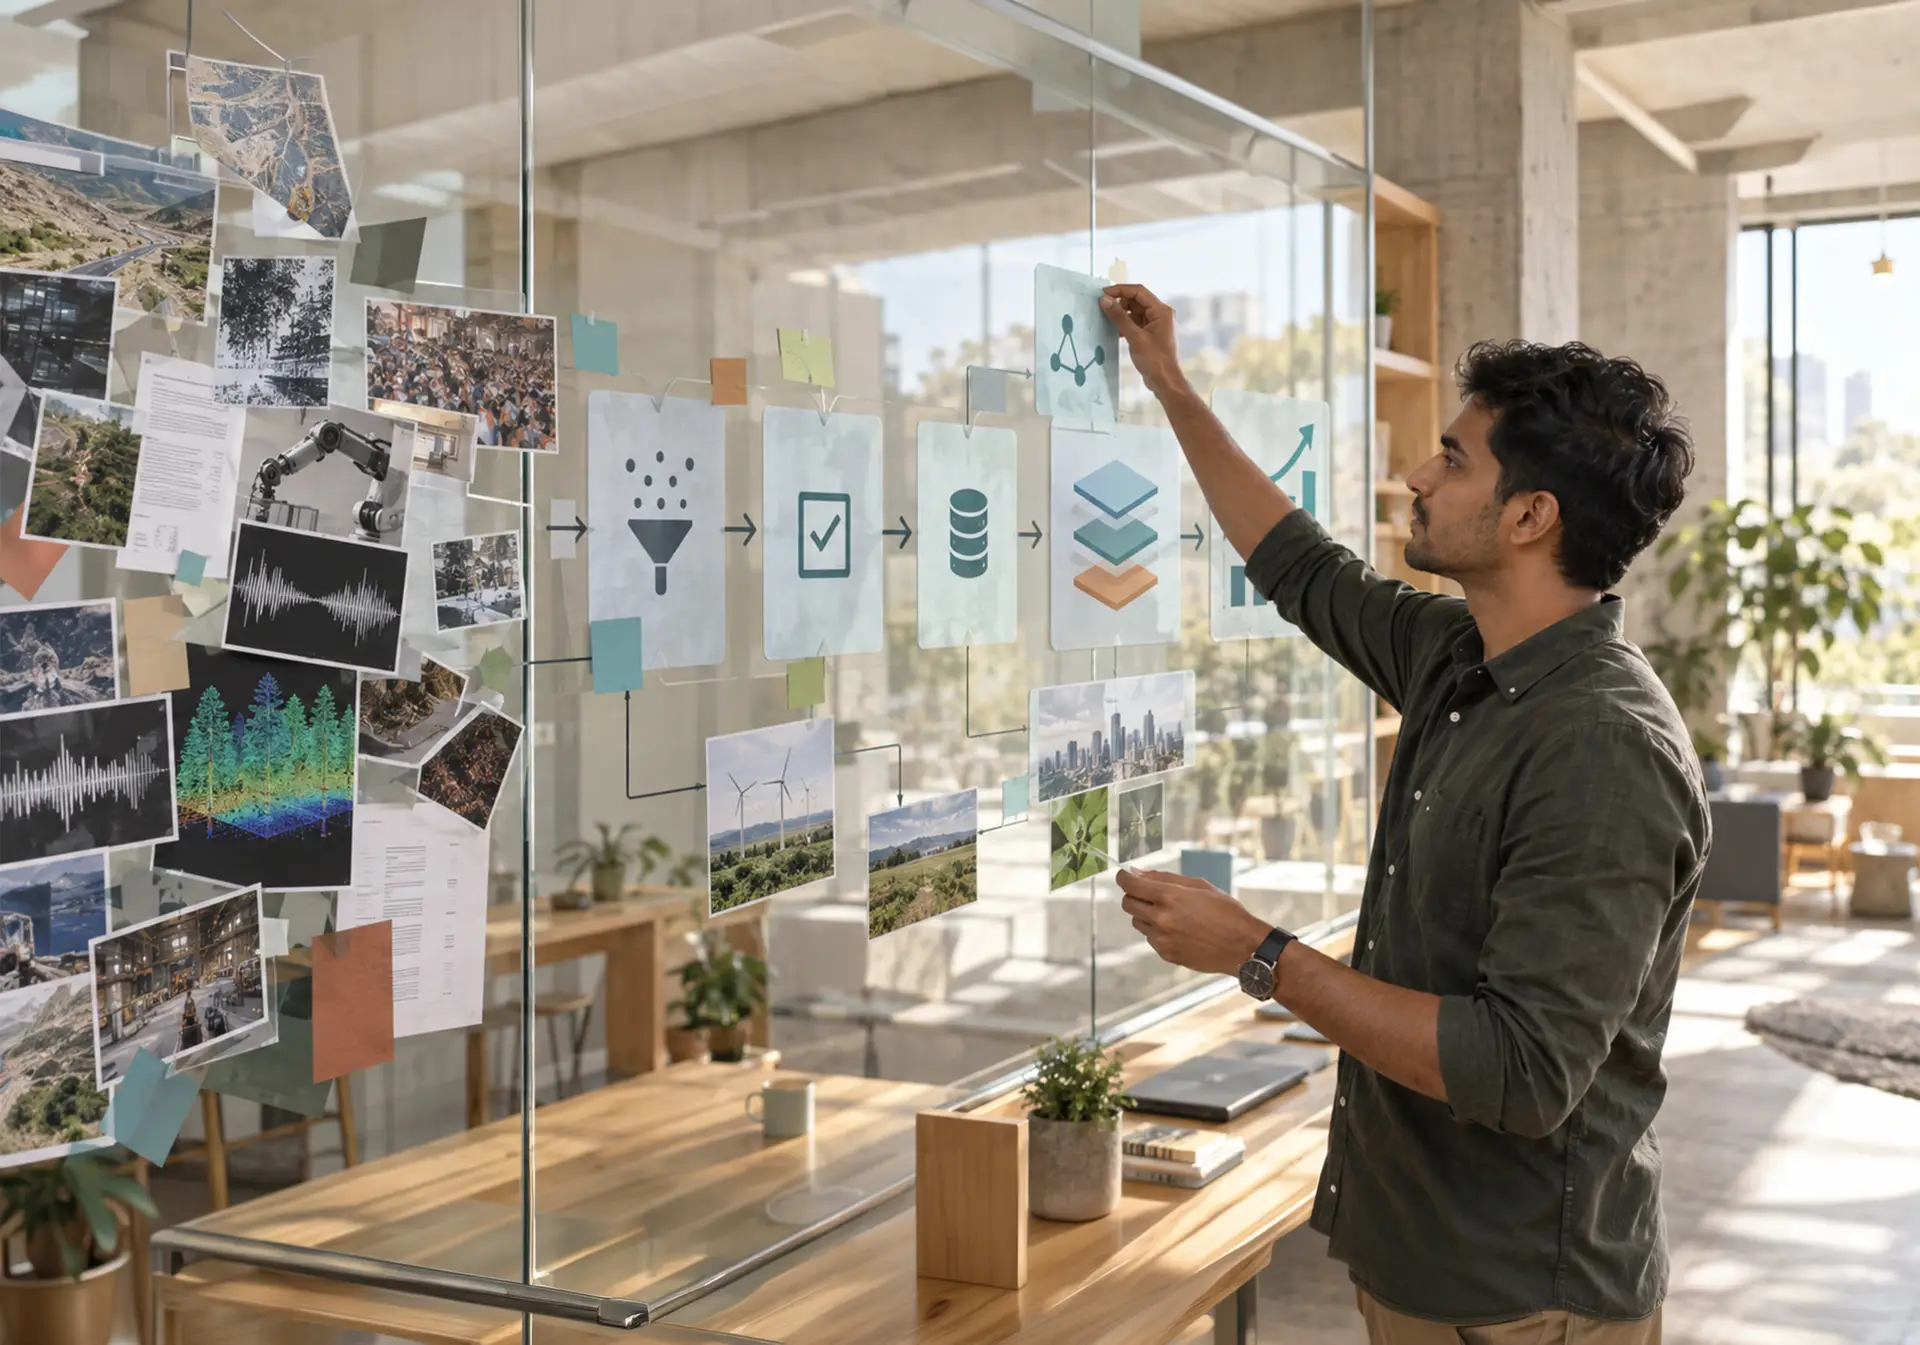
AI data curation services turn raw, fragmented data into controlled datasets that are fit for model training, fine-tuning, evaluation, and continuous improvement. Strong curation covers source qualification, deduplication, normalization, coverage design, enrichment, provenance, quality validation, and version control. Enterprises should evaluate a provider on measurable dataset outcomes, security controls, workflow transparency, and the ability to connect curation decisions to model performance.
Curation decides which examples a model ever sees, so it shapes accuracy, bias, and reliability long before training starts. Teams that treat sourcing as a warm-up to the “real” modeling work tend to inherit those early decisions as production failures. Mature programs run data collection and curation as an engineering discipline with its own tooling, quality standards, and audit trail. This guide explains what curation includes, how it differs from annotation, how providers price the work, and how to evaluate a vendor before you sign.
Key Takeaways
- The quality of the data you feed a model matters more for real-world results than how big or advanced the model is.
- Data curation means choosing, cleaning, balancing, and keeping a record of the right data before any training begins.
- Curation decides what data goes in, while annotation just adds labels to data that has already been chosen, so getting curation wrong makes even perfect labeling useless.
- Prices vary by how the work is charged and by factors like data type, expert knowledge needed, and how carefully it is checked, so a low headline rate can hide the true cost.
- Pick a provider based on how they measure quality, track where data comes from, and respond when things break, rather than on price or a polished sales pitch alone.
- The safest way to test a provider is a small paid trial on your own messy data before committing to a full program.
What are AI data curation services and Where Do They Fit in the AI Model Lifecycle??
AI data curation services are outsourced or co-managed programs that take raw, messy source data and turn it into a training-ready dataset with known quality, coverage, and provenance. The work spans sourcing, filtering, deduplication, class balancing, enrichment, quality scoring, and documentation of where each example came from. Curation sits next to data annotation in the pipeline, though the two answer different questions, which the sections below make explicit. A useful shorthand is that curation decides what belongs in the dataset, while annotation describes what is already in it.
The field has shifted toward a data-centric view of model quality over the past few years. Practitioners consistently find that the composition of the training set determines more of the outcome than incremental changes to architecture. A widely cited Google Research study on data cascades found that data problems are pervasive, appearing in 92% of the AI teams studied, and that data remains the most undervalued part of the workflow. That undervaluation is exactly the gap curation services are built to close.
The priorities vary by model. LLM programs may emphasize semantic deduplication, source quality, language balance, and provenance. Vision, robotics, and ADAS programs add image quality, scenario coverage, temporal continuity, sensor synchronization, and physical plausibility.
What does AI data curation include?
Curation is a sequence of decisions, each of which changes what the model can and cannot learn. At an enterprise scale, a complete curation program typically covers the following stages:
- Sourcing and selection: Deciding which data to bring in, from internal archives, licensed corpora, sensor logs, or targeted collection, and rejecting what does not fit the task.
- Cleaning and deduplication: Removing corrupted records, near-duplicates, and noise that inflates dataset size without adding signal.
- Coverage and balancing: Auditing the distribution so the dataset represents the conditions the system will meet, then filling gaps deliberately.
- Enrichment and structuring: Adding metadata, taxonomy tags, and context that make examples usable for retrieval, training, and evaluation.
- Edge-case mining: Surfacing the rare, high-cost scenarios a model handles badly, which naturally collected data underrepresents by definition.
- Quality scoring and provenance: Recording confidence, review status, and the full lineage of every example so the set is auditable later.
Edge-case work deserves emphasis because it drives most safety-critical failures. Dedicated edge case curation targets the corner cases that a model will meet in deployment yet rarely sees in training. Curating those scenarios on purpose raises reliability where the cost of error is highest.
Two further decisions belong in a modern curation program. The first is the balance between real and synthetic data, since generated examples can fill coverage gaps that are expensive or unsafe to collect, though they need validation before they enter the set. The second is data selection, where active-learning methods prioritize the examples most likely to improve the model and drop redundant ones that add cost without signal. Both decisions are curation work, and both change the economics of a program, because a smaller, well-chosen dataset often trains a stronger model than a larger, noisier one. A provider that treats every example as equally worth keeping is not curating; it is only collecting.
How does data curation improve AI model performance?
Curation improves performance by changing the input the model learns from, which compounds through every downstream stage. Cleaner, better-balanced data reduces the number of confident-but-wrong outputs and improves how the model generalizes to unseen inputs. The argument on criticality of data curation for generative AI is that every generated output reflects the data the model was trained on, so flaws in the set propagate into behavior. This holds across predictive, generative, and agentic systems.
The DataComp benchmark held the training code fixed and let participants compete only on dataset curation, and it showed that better-curated data produced meaningfully stronger models with less compute. The result reframes curation as a direct lever on accuracy rather than a housekeeping task. Teams that invest in it tend to close more of the gap between what a model can achieve and what it actually delivers.
Coverage is the other half of the performance story. A dataset can be clean and still fail because it never exercises the capability areas the task requires. The analysis of the impact of training data on model bias explains that coverage is something to audit rather than assume, and that underrepresented inputs become the model’s blind spots. Curating for coverage raises reliability precisely where naturally collected data is thinnest.
What is the difference between data curation and data annotation?
The two are often bundled together, though they solve different problems and carry different risks. Data curation is the work of deciding what data belongs in the set and preparing it: sourcing, filtering, deduplicating, balancing, enriching, and documenting. Data annotation is the work of adding labels to the data that curation has already selected: bounding boxes, transcriptions, entity tags, preference rankings, and similar. Collection sits upstream of both and refers to sourcing or generating the raw material in the first place.
The practical distinction matters when you scope a project. You can annotate a poorly curated dataset perfectly and still get a weak model, because the labels are accurate on the wrong distribution of examples. Annotation quality is measurable and consequential in its own right. A study of pervasive label errors across ten widely used benchmark datasets found an average of at least 3.3% label errors, rising to 6% in the ImageNet validation set, which was enough to change how models ranked against each other. Curation and annotation each need their own quality controls, and a serious provider treats them as separate disciplines with separate metrics.
How are AI data curation services priced?
Pricing depends on what the work actually is, so buyers should map the model to their volume, complexity, and cadence before comparing quotes. Providers generally use one of four structures, and many combine them across a program:
- Per-unit pricing: A rate per record, image, frame, hour of audio, or document. It works for well-defined, high-volume tasks with stable specifications.
- Per-hour pricing: A rate for reviewer or specialist time. It fits ambiguous, judgment-heavy work where output volume is hard to predict.
- Managed program or retainer: A monthly fee for a dedicated, trained team plus quality and program management. It suits ongoing pipelines that evolve with the model.
- Platform or subscription: A license for tooling, sometimes with services layered on top, priced by seats or throughput.
Several factors move the price within any of these models. Modality raises cost as you move from text to image to video to fused sensor data, since each adds handling and review complexity. Domain expertise adds cost when the work needs clinical, legal, or engineering judgment rather than general labeling. Quality tier matters too, because multi-stage review and higher inter-annotator agreement targets require more human passes. Turnaround, data security requirements, and volatility of the specification all push the number as well. A per-unit quote that ignores these drivers tends to understate the true cost of a production program.
What Does an Enterprise-Grade Curation Workflow Look Like in Production?
Production curation is a repeatable pipeline with explicit acceptance gates. It starts with model objectives and ends with a versioned dataset plus evidence that the release meets agreed quality, coverage, and governance thresholds.
How should the target dataset be defined?
The workflow starts with a sampling frame or dataset specification. It defines modalities, sources, target populations, class distributions, environments, languages, time periods, rare scenarios, permitted content, prohibited content, and acceptance thresholds. This document should be specific enough to measure.
Training, validation, and evaluation sets need separate rules. Training may favor broad coverage and difficult examples, while evaluation needs stable, representative, leakage-controlled samples.
What should happen during a pilot?
A pilot should validate the workflow, not merely produce a small batch. The provider and client should test intake rules, filtering thresholds, ambiguous cases, metadata schema, reviewer calibration, turnaround time, output format, and reporting. A useful pilot creates a baseline for both quality and throughput.
Where feasible, the pilot should compare curated data with model behavior. Even a small offline test can reveal whether proposed quality scores or sampling rules relate to downstream metrics.
Where should automation and human review be used?
Automated systems are effective for format validation, exact and semantic duplicate detection, basic PII detection, image-quality checks, language identification, clustering, anomaly detection, and rule-based filtering. Human reviewers remain important for semantic relevance, ambiguous edge cases, domain-specific validity, cultural context, safety judgments, and adjudication.
Automation depth should follow task risk and ambiguity. Safety-critical, regulatory, and judgment-heavy decisions need stronger human review and documented escalation paths.
What quality gates should a curated release pass?
Release criteria should combine record-level and dataset-level metrics. Record-level checks may include corruption rate, metadata completeness, label defect rate, and schema validity. Dataset-level checks should include duplicate rate, coverage against target, class balance, source distribution, edge-case representation, provenance completeness, and leakage controls.
A release should fail when a critical slice misses its threshold, even if the aggregate metric looks strong. This prevents high-volume common cases from hiding weak performance in rare or high-risk segments.
How does curation continue after deployment?
Production data changes the curation plan. Teams learn which inputs cause errors, which segments drift, which rare events matter, and which source assumptions were wrong. Those signals should feed the next collection and curation cycle.
A mature program maintains a data feedback loop. Model errors guide new sampling, collection, review, and the next versioned release, making curation part of ongoing model maintenance.
How should enterprises evaluate an AI data curation provider?
The questions that predict success are about the human quality layer, governance, and how a provider behaves when something breaks. A connector count or a demo on a curated sample tells you little about performance on messy production data. Evaluate providers against criteria that map to the risks in your program:
- Quality for methodology: Ask how they measure quality, whether they report inter-annotator agreement, and how multi-stage review and gold sets work in practice.
- Domain capability: Confirm they can staff and train specialists for your domain, rather than routing sensitive work to general crowdsourcing.
- Coverage and edge-case process: Ask how they audit distribution and how they find the rare cases your model will fail on.
- Provenance and lineage: Confirm they document data sources, transformations, and guideline versions, so a dataset stays auditable.
- Security and compliance: Look for real documentation behind certifications such as SOC 2 Type 2, ISO 27001, GDPR, and HIPAA, along with deployment options that fit your data-residency rules.
- Failure response: Ask what happens when quality drops, how re-work is priced, and how quickly the team can adjust guidelines.
Programs that cannot document where their data came from face rising regulatory exposure under the EU AI Act and evolving privacy frameworks. A provider that maintains full lineage delivers a compliance asset alongside a training asset, and that distinction grows more valuable with each regulatory cycle.
Structured due diligence beats a capabilities deck. Ask for references from clients in a similar domain, and ask what went wrong on those programs and how the provider recovered, because the recovery story reveals more than the success story. A short, paid pilot on your own messy data is the single most reliable test, since it shows how the team handles ambiguity, edge cases, and specification changes under real conditions. Scoring providers against consistent criteria across a pilot removes most of the guesswork that a sales conversation introduces.
What are the red flags in a data curation vendor proposal?
Several proposal patterns deserve additional diligence because they hide the parts of curation that usually fail under production pressure.
- One accuracy number for the entire program: Dataset quality has multiple dimensions, and an aggregate percentage can hide weak coverage or severe errors in small slices.
- No provenance deliverable: A folder of cleaned files without source lineage, rights metadata, and transformation history creates future governance risk.
- Deduplication described only as exact-match removal: Near-duplicate text, repeated video, similar images, and correlated sessions can remain even when hashes differ.
- No target distribution or coverage specification: Without a defined target, “balanced” becomes subjective and difficult to accept contractually.
- Automation described without human escalation: Automated quality scoring needs a path for ambiguous, high-risk, or domain-specific cases.
- Human review described without calibration metrics: Review teams need guidelines, gold examples, disagreement analysis, and adjudication rules.
- Security claims limited to corporate certifications: Buyers should verify controls at the delivery-center, workstation, data-transfer, and subcontractor levels.
- Pricing that excludes rework caused by provider errors: The contract should define who pays when quality misses agreed thresholds.
- No versioning or reproducibility plan: A training dataset should be recreatable from documented sources, rules, and transformations.
- A pilot built from hand-picked easy samples: Representative difficult data is a better predictor of production performance.
What does an enterprise-grade curation workflow look like in production?
A production curation workflow is continuous, versioned, and instrumented, rather than a one-time cleanup before training. It starts with a shared definition of task, quality thresholds, and coverage targets, then moves data through structured stages with checks at each one. Human-in-the-loop review sits at the center, with automation handling scale and expert reviewers resolving the cases automation cannot. The output is a versioned dataset with recorded lineage, so any later problem can be traced to a specific source and guideline version.
Two properties separate a durable workflow from a fragile one. The first is drift monitoring, since categories get applied inconsistently and new data types appear as a program grows past its original design. The second is traceability, because a fine-tuned model that starts producing off-brand or unsafe outputs needs to be traced to the exact data and guidelines that shaped it. Without that trail, every incident becomes an open-ended investigation instead of a targeted fix. Enterprises that build these properties in early spend far less time firefighting later.
Should you build data curation in-house or buy it?
The decision turns on volume, domain complexity, regulatory exposure, and how much of your model’s accuracy rides on the human quality layer. Building in-house gives you tight control and keeps sensitive data close, though it demands recruiting, training, tooling, and quality management that many teams underestimate. Buying gives you a trained workforce and mature process quickly, at the cost of bringing a partner inside your data boundary. Neither is right in the abstract, and the answer depends on your specifics.
A hybrid model is often the pragmatic answer for larger programs. The enterprise keeps ownership of strategy, sensitive data, and final acceptance, while the provider runs sourcing, curation, annotation, and delivery at scale. This keeps control where it belongs and puts volume where it is handled most efficiently. Vendor selection under this model is an architecture decision with long consequences, so the evaluation criteria above matter more than headline price.
How Digital Divide Data Can Help
Digital Divide Data operates the human quality layer that determines whether a curation program holds up in production. Our data collection and curation services cover the full lifecycle, from ethical sourcing and deduplication through coverage auditing, enrichment, and documented provenance for every source. We run structured human-in-the-loop workflows with multi-stage QA and domain specialists, which keep accuracy high on the ambiguous, safety-critical cases that automation alone misses.
The work is grounded in specific capabilities rather than a generic promise. Our AI data preparation services clean, structure, validate, and enrich raw data into consistent, bias-aware, model-ready sets that improve downstream performance. We embed governance, auditability, and compliance into every workflow, operating under ISO 27001, SOC 2 Type 2, GDPR, and HIPAA-aligned protocols, with flexible delivery models for teams that have strict data-residency requirements. For programs that live or die on rare scenarios, our edge-case pipelines surface and resolve the failure modes a model meets in the real world.
Build a curation program that closes the gap between what your model can do and what it actually delivers. Talk to an Expert.
Conclusion
Curation is the point where most of a model’s accuracy, bias, and reliability are actually decided, well before training begins. The evidence is consistent: better data beats bigger models in most production settings, and coverage gaps become blind spots that surface as failures. Organizations that treat curation as an engineering discipline, with measured quality and documented provenance, ship systems that behave predictably. Those that treat it as a warm-up inherit their early shortcuts as expensive, hard-to-trace incidents.
The buyers who get this right choose partners on quality methodology, provenance, and failure response, rather than on price alone.
References
Gadre, S. Y., Ilharco, G., Fang, A., Hayase, J., Smyrnis, G., Nguyen, T., Marten, R., Wortsman, M., Ghosh, D., Zhang, J., Orgad, E., Entezari, R., Daras, G., Pratt, S., Ramanujan, V., Bitton, Y., Marathe, K., Mussmann, S., Vencu, R., Cherti, M., Krishna, R., Koh, P. W., Saukh, O., Ratner, A., Song, S., Hajishirzi, H., Farhadi, A., Beaumont, R., Oh, S., Dimakis, A., Jitsev, J., Carmon, Y., Shankar, V., & Schmidt, L. (2023). DataComp: In search of the next generation of multimodal datasets. Advances in Neural Information Processing Systems (NeurIPS). https://arxiv.org/abs/2304.14108
Northcutt, C. G., Athalye, A., & Mueller, J. (2021). Pervasive label errors in test sets destabilize machine learning benchmarks. NeurIPS Datasets and Benchmarks Track. https://arxiv.org/abs/2103.14749
Sambasivan, N., Kapania, S., Highfill, H., Akrong, D., Paritosh, P., & Aroyo, L. (2021). “Everyone wants to do the model work, not the data work”: Data cascades in high-stakes AI. Proceedings of the 2021 CHI Conference on Human Factors in Computing Systems. https://dl.acm.org/doi/10.1145/3411764.3445518
Frequently Asked Questions
What are AI data curation services?
They are managed programs that turn raw, messy source data into a training-ready dataset with known quality, coverage, and provenance. The work covers sourcing, cleaning, deduplication, balancing, enrichment, and documentation of where each example came from.
What is the difference between data curation and data annotation?
Curation decides what data belongs in the set and prepares it, while annotation adds labels to the data that curation has already selected. You can annotate a poorly curated dataset perfectly and still get a weak model, because the labels sit on the wrong distribution of examples.
How is AI data curation priced?
Providers usually charge per unit, per hour, as a managed retainer, or through a platform subscription, and many combine these. Cost rises with modality, domain expertise, the quality tier you require, turnaround, and data-security requirements.
Does better data curation actually improve model accuracy?
Yes, and the effect is measurable. The DataComp benchmark held training code fixed and showed that better-curated data produced stronger models with less compute, which makes curation a direct lever on accuracy rather than a housekeeping step.
Udit Khanna leads the delivery of scalable AI and data solutions at Digital Divide Data, with a deep specialization in Physical AI. With a background in presales, solutioning, and customer success, he brings a mix of technical depth and business fluency, helping global enterprises move their AI projects from prototype to real-world deployment without losing momentum.