Celebrating 25 years of DDD's Excellence and Social Impact.

AI Data Training Services

Audit an AI Model for Bias

How to Audit an AI Model for Bias: A Practical Data-Level Checklist

Kevin Sahotsky

Bias in AI models is overwhelmingly a data problem before it is a model problem. The patterns a model learns, the groups it overrepresents or underrepresents, and the shortcuts it takes when making predictions. Almost all of these trace back to characteristics of the data the model was trained on. This is particularly relevant for AI program leads, product managers overseeing model deployments, and compliance teams working in regulated industries where demonstrating fairness is not optional.

This blog walks through a practical data-level checklist for auditing an AI model for bias, covering where bias enters, what to measure, and what the remediation options actually look like. Trust and safety solutions and model evaluation services are the two capabilities most directly involved in identifying and addressing data-level bias before it reaches production.

Key Takeaways

  • Bias in AI models originates in training data far more often than in model architecture. Auditing the architecture without auditing the data misses the root cause.
  • There are three stages where bias enters: data collection, data labeling, and data curation. Each stage requires its own audit approach and cannot be substituted by checks at the other stages.
  • Representation gaps are the most common and most overlooked source of bias. A model trained on data that systematically underrepresents certain groups will produce worse outputs for those groups even when no individual annotation is wrong.
  • Fairness metrics measure different things and can contradict each other. Choosing which metric to optimize requires an explicit decision about what kind of fairness matters for the deployment context.

Where Bias Actually Comes From

Stage 1: Data Collection

The first place bias enters is at collection. If the data collected to train a model does not represent the full range of people, contexts, and conditions the model will encounter at deployment, the model will systematically underperform on the cases that were underrepresented in training. This is not a labeling problem. The labels can all be correct, and the model will still produce biased outputs because it has seen too few examples of certain groups or conditions to learn to handle them well.

Collection bias is the hardest to fix after the fact because it requires going back and collecting more data from the underrepresented cases, which is expensive and time-consuming. The audit question at this stage is simple but easy to defer: does the distribution of the training data match the distribution of the deployment population? Data collection and curation services that audit demographic and contextual coverage before collection ends are far cheaper than auditing after a biased model has reached production.

Stage 2: Data Labeling

The second entry point is labeling. Human annotators apply labels to training data, and those labels reflect the annotators’ own frames of reference, cultural contexts, and implicit associations. An annotator who consistently associates certain names with certain characteristics, or who applies sentiment labels differently across different dialects or writing styles, introduces label-level bias that the model will learn directly. Because label bias looks like signal rather than noise from the model’s perspective, it is often harder to detect than representation gaps.

The audit approach at this stage is inter-annotator agreement disaggregated by subgroup. If annotators agree consistently on majority-group examples but diverge significantly on minority-group examples, the annotation process is introducing differential error rates that the model will inherit. Text annotation services that measure inter-annotator agreement at the subgroup level, not just in aggregate, surface this pattern before it compounds through the full training dataset.

Stage 3: Data Curation

The third entry point is curation. Even when collection and labeling are unbiased, the decisions made about which data to keep, which to filter, and how to balance the training set introduce bias. A curation pipeline that filters out low-confidence examples disproportionately removes data from underrepresented groups, because low-confidence labeling correlates with the annotators’ lower familiarity with those groups. A resampling strategy that balances by category but not by demographic subgroup within category can leave systematic gaps.

Curation bias is the most invisible of the three because it happens in the pipeline rather than in the data itself. The audit requires tracking not just what data was kept but what was removed and why, which most curation pipelines do not do by default.

The Data-Level Bias Audit Checklist

Check 1: Representation Audit

Map the demographic and contextual distribution of your training data against the deployment population. For each group that matters for your deployment context, calculate the proportion in the training set versus the proportion in the population the model will serve. A gap of more than ten percentage points between a group’s representation in training and its representation in the deployment population is a useful starting threshold for flagging meaningful risk, warranting either additional data collection or a fairness constraint during training. The right threshold will vary with deployment context and the stakes involved.

Representation audit tools include demographic classifiers applied to the training set, metadata analysis where demographic fields exist, and external benchmarks that characterize the expected deployment distribution. The output is a coverage map, not a single metric.

Check 2: Label Consistency Audit

Calculate inter-annotator agreement disaggregated by the subgroups relevant to your deployment context. The relevant breakdown depends on the application: for a hiring model, this might be by applicant name type or inferred demographic; for a content moderation model, this might be by dialect or topic type; for a medical model, this might be by patient demographic characteristics in the case descriptions.

As a useful starting threshold, any subgroup showing inter-annotator agreement more than ten percentage points below the overall agreement level is a signal worth investigating, suggesting the labeling process may be applying different standards to different groups. This is the input to annotator calibration and guideline revision, not a reason to discard the data. Model evaluation services that measure subgroup-level annotation consistency as a standard output of the labeling quality process catch this before it accumulates through the full training set.

Check 3: Curation Audit

Document what was removed from the training set and why. For each filtering step, calculate the removal rate disaggregated by subgroup. If a low-confidence filter removes data from one subgroup at twice the rate of another, that filter is introducing a representation gap that did not exist in the raw collected data. The audit does not require abandoning confidence-based filtering. It requires checking whether the filter is applied uniformly across groups and adjusting the threshold or supplementing with additional collection where it is not.

Check 4: Performance Disparity Measurement

Evaluate model performance disaggregated by subgroup across your held-out evaluation set. The relevant metrics depend on the task. For classification tasks, measure precision, recall, and F1 separately for each subgroup. For regression tasks, measure mean error and error variance. For generative tasks, use human evaluation panels drawn from the relevant subgroups rather than automated metrics, because automated metrics often have their own demographic biases.

Performance disparity greater than five percentage points in recall across demographic subgroups on a classification task in a regulated domain is a reasonable benchmark for a material finding requiring remediation before deployment, though the appropriate threshold depends on the regulatory context and the consequences of false negatives for each subgroup.

Check 5: Fairness Metric Selection

Different fairness metrics operationalize different concepts of fairness, and they can mathematically conflict with each other. Demographic parity requires that the positive prediction rate is equal across groups. Equalized odds requires that both the true positive rate and the false positive rate are equal across groups. Calibration requires that predicted probabilities correspond to actual outcome rates for each group. A model cannot simultaneously satisfy all three under most real-world data distributions. Choosing which metric to optimize requires an explicit decision about what fairness means in the deployment context, and that decision should be documented before the model is trained, not after it is evaluated. This survey of fairness concepts in machine learning provides the foundational taxonomy that the checklist items above build on.

Check 6: Regulatory Compliance Documentation

If the model falls under the EU AI Act’s definition of a high-risk AI system, which includes models used in employment, education, credit scoring, law enforcement, and several other categories, the compliance timeline is now settled: following the Digital Omnibus amendment formally adopted by the European Parliament and Council in June 2026, standalone Annex III high-risk AI systems must meet data governance and bias testing requirements by December 2, 2027. 

This is a deferral from the original August 2026 deadline, but the regulatory direction has not changed, and preparation is expected to be underway now. Article 10 of the EU AI Act specifies that training, validation, and testing datasets must be subject to data governance practices, must be relevant, representative, free of errors, and complete, with appropriate statistical properties for the specific population and context in which the system operates. Beyond fines, non-compliance creates a direct commercial risk: EU public procurement frameworks increasingly require AI Act compliance as a condition of tender eligibility, meaning a non-compliant system can disqualify an organization from public contracts before any fine is assessed.

What Remediation Actually Looks Like

Pre-Processing: Fix the Data Before Training

Pre-processing remediation addresses bias at the data level before training begins. The options include resampling underrepresented groups to bring their representation closer to the deployment distribution, reweighting training examples to increase the influence of underrepresented groups on model weights, and targeted data collection to fill coverage gaps identified in the representation audit. Pre-processing remediation is the most durable because it fixes the root cause rather than adjusting the model’s outputs downstream.

In-Processing: Constrain the Training

In-processing remediation adds fairness constraints to the training objective. This typically means adding a penalty term to the loss function that penalizes prediction disparity across demographic groups, or using an adversarial training approach where a separate model is trained to predict the demographic group from the primary model’s outputs. In-processing approaches require that demographic labels are available during training, which is not always the case.

Post-Processing: Adjust the Outputs

Post-processing remediation adjusts the model’s decision thresholds after training to equalize a chosen fairness metric across demographic groups. This is the easiest to implement and the most fragile, because it addresses the symptom rather than the cause. A threshold adjustment that achieves demographic parity on the evaluation set may not generalize to production traffic if the production distribution differs from the evaluation set. Post-processing remediation should be treated as a stopgap while pre-processing and in-processing remediation are implemented.

How Digital Divide Data Can Help

Digital Divide Data supports enterprise AI teams running data-level bias audits and implementing the remediation programs that audit findings require. For programs measuring representation gaps and label consistency across demographic subgroups, model evaluation services design evaluation frameworks disaggregated by the subgroups relevant to the deployment context rather than reporting only aggregate metrics. 

For programs that need targeted data collection to close coverage gaps identified in a representation audit, data collection and curation services source training examples from the underrepresented groups and contexts the audit identified. For programs addressing label-level bias through annotator calibration and guideline revision, trust and safety solutions provide annotation teams with calibration frameworks that measure and reduce subgroup-level annotation inconsistency.

If your model is in production and you haven’t run a data-level bias audit, you’re managing a risk you haven’t measured. Talk to an expert.

Conclusion

The six checklist items above are all data-level activities that need to happen before training and again after evaluation:

  • Representation audit
  • Label consistency audit
  • Curation audit 
  • Performance disparity measurement
  • Fairness metric selection
  • Regulatory compliance documentation

None of them require changes to the model architecture. All of them require discipline about what the training data actually contains and how it was produced.

The organizations that catch bias early are the ones that treat the audit as a standard step in the data program rather than a response to a production failure. What does your current training data pipeline document about the demographic distribution of the data that fed your last model?

References

Mehrabi, N., Morstatter, F., Saxena, N., Lerman, K., & Galstyan, A. (2021). A survey on bias and fairness in machine learning. ACM Computing Surveys, 54(6), 1-35. https://arxiv.org/abs/1908.09635

European Parliament and Council of the European Union. (2024). Regulation (EU) 2024/1689 of the European Parliament and of the Council (EU AI Act). Official Journal of the European Union. https://eur-lex.europa.eu/legal-content/EN/TXT/?uri=CELEX:32024R1689

Raji, I. D., Smart, A., White, R. N., Mitchell, M., Gebru, T., Hutchinson, B., Smith-Loud, J., Theron, D., & Barnes, P. (2020). Closing the AI accountability gap: Defining an end-to-end framework for internal algorithmic auditing. In Proceedings of the ACM Conference on Fairness, Accountability, and Transparency (FAccT). https://arxiv.org/abs/2001.00973

Frequently Asked Questions

Q1. Is bias auditing the same as fairness testing?

They overlap but are not identical. Bias auditing is a broader process that identifies where bias entered the system, covering data collection, labeling, and curation. Fairness testing is a specific evaluation activity that measures whether the model’s outputs meet a chosen fairness criterion. You can run fairness testing without a bias audit, but the results will tell you that a problem exists without telling you where it came from or how to fix it. A full bias audit includes fairness testing as one component alongside the data-level checks that identify root causes.

Q2. Which fairness metric should we use?

There is no universally correct answer because different metrics operationalize different ethical concepts of fairness, and they can mathematically conflict with each other under real-world data distributions. The choice should be driven by the deployment context and the consequences of different error types for each affected group. A credit scoring model where false negatives disproportionately harm one group warrants a different metric than a content moderation model where false positives disproportionately silence one group. Document the choice and the reasoning before training begins, not after.

Q3. How often should a bias audit be run?

Before the first deployment of a model, whenever the training data is updated in a way that changes its composition, whenever the model is retrained or fine-tuned, and at a regular cadence after deployment, typically quarterly for high-stakes applications, to catch distribution drift in the production traffic that the original training set did not anticipate. One-time pre-deployment auditing is insufficient because deployment environments change and model behavior can drift as production traffic diverges from the training distribution.

Q4. What data is needed to run a demographic subgroup analysis?

Ideally, demographic attributes are captured at data collection and preserved through the annotation and curation pipeline so they are available for disaggregated analysis. When this is not the case, demographic attributes can be inferred using name-based classifiers, language model-based classifiers, or proxy variables that correlate with demographic characteristics. Inferred demographics introduce their own error rates and should be treated as approximate rather than definitive. For regulated applications where demographic analysis is required, the most defensible approach is to collect demographic attributes directly and with participant consent at the point of data collection.

Q5. Does a bias audit guarantee the model is fair?

No. A bias audit identifies measurable disparities in the training data and model outputs against specific metrics. It does not guarantee fairness in a philosophical or legal sense, because fairness is context-dependent and the audit’s conclusions are bounded by the metrics chosen, the subgroups analyzed, and the evaluation data used. What a thorough bias audit does provide is documented evidence of due diligence, specific findings that can be addressed through remediation, and a defensible record of what was measured and what was done about it. That is what regulators and enterprise governance programs require.
How to Audit an AI Model for Bias: A Practical Data-Level Checklist Read Post »
AI data pipeline services

The Enterprise Buyer’s Guide to AI Data Pipelines in 2026

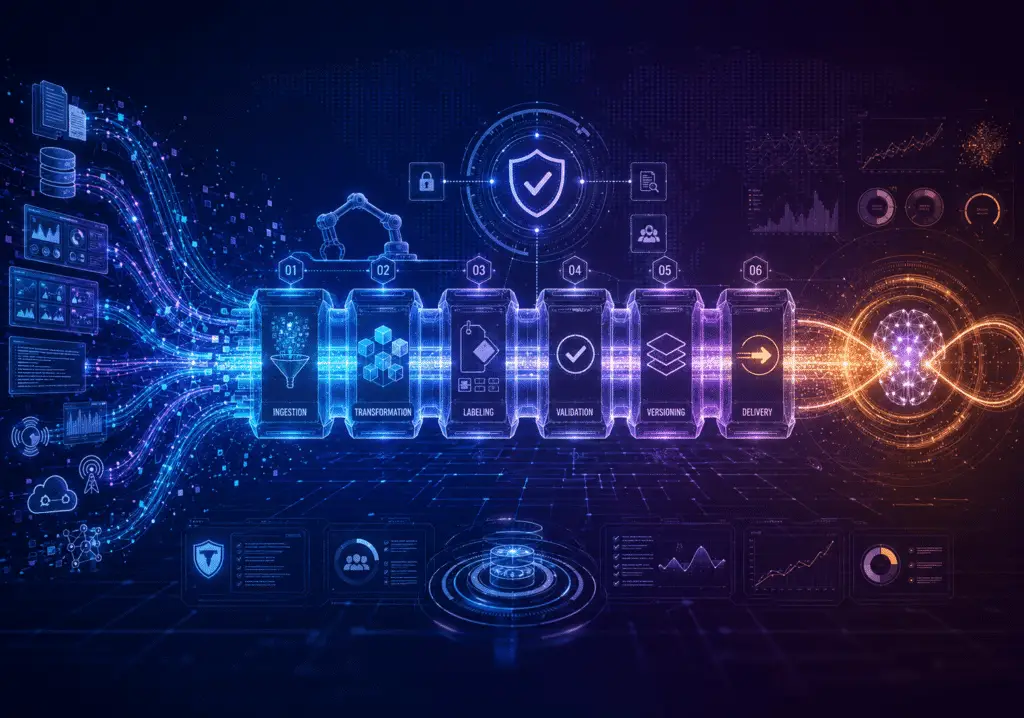
AI data pipeline services are managed, end-to-end workflows that carry raw data through ingestion, transformation, labeling, validation, versioning, and delivery, so machine learning models receive training-ready inputs on a predictable schedule. For enterprise buyers in 2026, the real decision is whether to run this pipeline in-house or hand it to a managed provider that owns the human labeling and quality layer most teams underestimate. The right answer depends on data volume, domain complexity, regulatory exposure, and how much model accuracy rides on annotation quality.

Most AI programs stall in the same place. The architecture is sound, the compute is provisioned, and the pilot works on a curated sample; then production data arrives and the pipeline underneath cannot keep it clean, labeled, and versioned at volume. This is the gap that managed AI data pipeline services are built to close, and the strongest providers pair infrastructure with end-to-end data collection and curation. Buyers who understand what these services include and where they tend to fail are the ones who avoid paying for a pipeline that quietly produces unusable data.

Key Takeaways

  • AI data pipeline services are managed workflows that carry your raw data through collection, cleaning, labeling, checking, versioning, and delivery, so models always get data they can learn from.
  • The work runs in stages, and a weak stage quietly damages every stage after it, which is why quality has to be measured at each handoff rather than at the end.
  • Unlike a normal data pipeline that ends at a report a person reads, an AI pipeline feeds the model directly and loops back for retraining, so mistakes go straight into the model with no human to catch them.
  • Most AI projects fail because of the data underneath them, not the model on top, and the people who label and verify that data are the part companies most often underfund.
  • Building this in-house suits teams with rare, highly specialised data and deep existing expertise, while most enterprises get there faster with a managed or hybrid partner.
  • When comparing vendors, ask for proof including measured labeling accuracy, repeatable datasets, and clear security documentation, instead of trusting claims about quality.

What are AI data pipeline services?

AI data pipeline services are outsourced or co-managed programs that handle the movement, preparation, and quality control of the data feeding a machine learning system. They span the full path from source systems to model-ready datasets, and they usually bundle data engineering for AI with human annotation and validation. The term overlaps with related labels such as data operations and ML data preparation, but the scope stays consistent: get the right data, in the right shape, to the model, repeatedly and reliably. Reliable data pipelines are foundational elements for any AI system, and successful systems treat this as core infrastructure rather than a one-time project.

The distinction that matters for buyers is the one between a data pipeline (the technical plumbing) and AI data pipeline services (the plumbing plus the people and processes that keep the data trustworthy). A pipeline that moves data on schedule but delivers mislabeled or biased examples will train a model that fails in production. Gartner’s analysis of AI-ready data found that through 2026, organizations will abandon 60% of AI projects that lack properly prepared data, and that 63% of organizations either lack or are unsure of the data management practices AI requires. Those failures rarely trace back to the model itself.

This is why the field has shifted toward data-centric AI, where performance gains come from improving the data rather than re-architecting the model. A widely cited survey on data-centric AI describes training-data development, meaning collection, labeling, and preparation, as the primary lever for reliable model behavior. Managed pipeline services operationalize that idea. They wrap disciplined collection, annotation, and quality assurance around the data before it ever reaches training.

It helps to be concrete about what “AI-ready” means, because the phrase gets used loosely. Ready data is aligned to a specific use case, governed at the level of the individual data asset, produced by automated pipelines with quality gates, and quality-assured continuously rather than in periodic audits. Traditional data management runs on reporting cadences, where a quarterly review is fine. Models in production need quality signals measured in hours, and that mismatch is where most pipeline problems begin. A managed service exists to hold that continuous standard, so the internal team does not have to staff for it around the clock.

How does an AI data pipeline work, stage by stage?

An AI data pipeline is a sequence of stages, each with its own failure modes and quality gates. Weakness at any stage propagates downstream, so mature programs measure and control every handoff. The six core stages below describe what a well-run managed service actually delivers.

  1. Ingestion: Raw data is pulled from source systems such as sensors, logs, documents, databases, and third-party feeds, then normalized into a consistent format. Hybrid environments, where legacy on-premises systems sit beside cloud warehouses, are where ingestion most often breaks.
  2. Transformation: Data is cleaned, deduplicated, standardized, and enriched so downstream stages receive predictable inputs. Poor transformation lets duplicate or malformed records reach the model, which then learns patterns that do not exist.
  3. Labeling: Human annotators, often supported by pre-labeling models, add the ground-truth labels a supervised model learns from. This is the stage tooling-first vendors most often underinvest in, and multimodal data annotation across text, image, video, and sensor streams is where domain expertise earns its cost.
  4. Validation: Labeled data is checked for accuracy, consistency, and coverage before it is accepted. Inter-annotator agreement, gold-standard audits, and independent model evaluation turn “we labeled it” into “we can defend this label”.
  5. Versioning: Datasets, labels, code, and configurations are versioned so any training run can be reproduced and any regression can be traced to its source. Without versioning, a drop in model accuracy becomes an unsolvable mystery.
  6. Delivery: Model-ready datasets are handed to training and inference systems on a defined schedule, with quality and freshness service levels attached.

Between these stages sit data contracts, which are agreements about schema, freshness, and quality that each stage must meet before the next accepts its output. When a contract is violated, an alert fires before bad data reaches training. This is the difference between a pipeline that fails loudly and early and one that silently degrades a model over weeks. Strong managed services make these contracts explicit and measurable, so quality is a number on a dashboard rather than a matter of trust.

A production pipeline also includes a feedback loop. Model outputs are monitored, drift is detected, and fresh data is routed back through the same stages for retraining. The loop is what keeps a deployed model accurate as the real world changes around it. In sensor-heavy domains such as autonomous driving, that loop runs constantly because new edge cases appear in the field faster than any fixed dataset can anticipate.

What is the difference between a data pipeline and an AI pipeline?

A traditional data pipeline is a one-way street. It extracts data, transforms it, and loads it into a warehouse or dashboard, where a human reads the result. The pipeline’s job ends at delivery, and a person catches most errors before they cause harm.

An AI pipeline extends that path and closes it into a loop. It adds feature engineering, labeling, model training, and monitoring, then feeds model outcomes back to improve the next cycle. Because a model consumes the data directly, no human reads a dashboard to catch a bad batch, so quality control has to live inside the pipeline. Data orchestration for AI at scale becomes a first-class concern because dozens of stages, datasets, and model versions all have to stay coordinated.

An AI pipeline also introduces structures a reporting pipeline never needs, such as a feature store, which is a governed repository of the processed inputs a model consumes for both training and live inference. Keeping training features and serving features consistent is a problem business intelligence never had to solve, and getting it wrong produces models that score well in testing and fail in production. This is one more reason the AI pipeline demands tighter control than its reporting-era ancestor.

The other difference is standards. A dashboard tolerates a small share of dirty rows because a human discounts them at a glance. A model treats every example as truth and will happily learn from a mislabeled one. That raises the bar on labeling accuracy and validation far above what traditional business intelligence ever required.

How do you build a scalable AI data pipeline?

Scalability is decided early, in the design of the pipeline, and it cannot be bolted on once volume climbs. Teams that build for a pilot’s data volume usually rebuild within a year, because the tooling, quality process, and staffing that work for ten thousand examples collapse at ten million. Designing for the target volume from the start avoids that expensive second build.

Building a pipeline that holds up at scale rests on a few durable principles:

  • Standardize quality gates: Define accuracy thresholds, inter-annotator agreement targets, and freshness service levels, then enforce them automatically at each stage.
  • Version everything: Data, labels, code, and model configurations all need version control so results stay reproducible and regressions stay traceable.
  • Separate the human layer from the tooling layer: Annotation workforces and QA processes should scale independently of the ingestion and transformation stack.
  • Instrument for drift: Continuous monitoring of data and model behavior lets retraining trigger on evidence rather than on a fixed calendar.

The constraint most teams miss is trained people. A scalable pipeline needs a trained, managed annotation workforce with domain knowledge, and standing up that capability internally takes months. McKinsey’s 2025 State of AI survey found that 88% of organizations now use AI in at least one function, yet only about a third have scaled it enterprise-wide, and high performers are far more likely to have defined processes for when model outputs need human validation. The human quality layer, more than the algorithm, is what separates the two groups.

The cost of getting scalability wrong is technical debt that compounds. Data teams that spend most of their time maintaining fragile pipelines are firefighting rather than building, and every quarter of deferred quality work makes the eventual cleanup larger. Designing quality gates, versioning, and a managed workforce into the pipeline from day one is cheaper than retrofitting them once a model is already in production and already trusted by the business.

Managed service or in-house build: which fits your program?

The build-versus-buy decision turns on a few honest questions about cost, speed, and control. Building in-house makes sense when data is highly proprietary, the domain is narrow enough for a small expert team, and the organization already has data engineering and annotation management depth. For most enterprises, that combination is rare. The trade-offs of weighing a data annotation provider against an in-house team usually favor a managed or hybrid model once volume and domain breadth grow.

A managed service accelerates time-to-value and absorbs the operational burden of hiring, training, and retaining annotators. The common objections are real. Fully managed services can raise data-residency and control concerns in regulated industries, and some pricing models penalize scale. Those risks are manageable with the right contract terms, deployment model, and governance, which is why the vendor evaluation below matters as much as the build-versus-buy call itself.

A hybrid model is often the pragmatic answer. The enterprise keeps ownership of strategy, sensitive data, and final acceptance, while the provider runs collection, annotation, validation, and delivery at scale. This keeps control where it belongs and puts volume where it is cheapest to handle.

What should you look for in an AI data pipeline vendor?

Vendor selection is an architecture decision with long consequences, and a connector count on a slide tells you little about whether the data will be trustworthy. The questions that predict success are about the human quality layer, governance, and how a provider behaves when something breaks. The capabilities matrix below gives buyers a structured way to compare providers on what actually drives model performance.

Capability What strong looks like Warning sign
Data collection & curation Sourcing, cleaning, and curation run as a managed service with documented provenance Vendor only labels data you supply, with no curation
Annotation quality Measured inter-annotator agreement, gold-standard audits, domain-trained annotators “High quality” claimed with no metrics attached
Multimodal coverage Text, image, video, audio, and sensor data handled by one provider Single-modality shop staffing a multimodal program
Validation & evaluation Independent evaluation, plus bias and coverage checks before delivery QA limited to occasional spot checks
Versioning & reproducibility Datasets, labels, code, and configs versioned end-to-end No lineage; training runs cannot be reproduced
Governance & security RBAC, encryption in transit and at rest, audit trails, no training on your data Vague compliance badge with no documentation
Deployment model Cloud, hybrid, and on-prem options to fit data-residency rules Cloud-only in a regulated environment
Support & SLAs Documented response times, plus freshness and accuracy service levels SLAs “available on request,” never shown
Pricing predictability Transparent, volume-aware pricing Usage-based billing that punishes scale

For regulated industries, deployment models and compliance coverage often decide the shortlist before any other feature matters. A provider that is cloud-only cannot serve a program with strict data-residency rules, and a generic compliance badge is not the same as documentation you can hand to an auditor. Buyers in healthcare, finance, defense, and public sector should treat the deployment model and the governance posture as gating criteria, then compare on annotation quality and coverage within the providers that clear that bar.

The single most useful filter is evidence. A provider that can show measured annotation accuracy, reproducible datasets, and a documented governance posture is describing a program that will hold up in production. A fuller checklist for how to evaluate AI training data providers usually covers the diligence questions worth asking before a contract is signed.

How Digital Divide Data Can Help

Digital Divide Data runs the full AI data pipeline as a managed service, with the human quality layer built in rather than bolted on. Our teams handle end-to-end data collection and curation, multimodal annotation across text, image, video, audio, and sensor data, and the validation and versioning that keep datasets reproducible. This matters most in Physical AI, ADAS, and autonomous systems, where a single mislabeled sensor frame can propagate into a safety-relevant model error.

Where programs need an independent check on quality, our model evaluation services provide accuracy testing, bias and fairness assessment, and factual-consistency review before models reach production. We also support human preference optimization, red teaming, and trust and safety work, so the pipeline covers not only training data but the evaluation and alignment stages that decide whether a model behaves as intended. Our delivery model is designed to scale a trained, managed annotation workforce without forcing the enterprise to build that capability internally.

Build an AI data pipeline that delivers training-ready data you can actually trust. Talk to an Expert.

Conclusion

The organizations that get AI data pipeline services right in 2026 treat data quality as the core of the program, not a step to finish before the interesting work begins. They measure annotation accuracy, version their datasets, instrument for drift, and choose partners on evidence rather than connector counts. The organizations that get it wrong keep launching pilots on unprepared data and keep landing in the 60% of projects Gartner expects to be abandoned.

The pipeline underneath your model decides whether it scales or stalls. 

References

Gartner. (2025). Lack of AI-Ready Data Puts AI Projects at Risk. Gartner Newsroom. https://www.gartner.com/en/newsroom/press-releases/2025-02-26-lack-of-ai-ready-data-puts-ai-projects-at-risk

McKinsey & Company. (2025). The State of AI in 2025: Agents, Innovation, and Transformation. QuantumBlack, AI by McKinsey. https://www.mckinsey.com/capabilities/quantumblack/our-insights/the-state-of-ai

Zha, D., Bhat, Z. P., Lai, K.-H., Yang, F., Jiang, Z., Zhong, S., & Hu, X. (2025). Data-centric Artificial Intelligence: A Survey. ACM Computing Surveys. https://arxiv.org/abs/2303.10158

Frequently Asked Questions

What are AI data pipeline services in simple terms?

They are managed workflows that move your raw data through ingestion, transformation, labeling, validation, versioning, and delivery, so your machine learning models get clean, training-ready data on a reliable schedule. The provider usually handles both the technical plumbing and the human annotation and quality checks.

What is the difference between a data pipeline and an AI pipeline?

A regular data pipeline is a one-way street that ends at a dashboard a person reads, so a human catches most errors. An AI pipeline adds labeling, training, and monitoring, then loops model outcomes back for retraining, and because a model reads the data directly, quality control has to be built into the pipeline itself.

Should I build my AI data pipeline in-house or use a managed service?

Building in-house makes sense when your data is highly proprietary, your domain is narrow, and you already have data engineering and annotation management depth. For most enterprises, a managed or hybrid model is faster and cheaper once data volume and domain breadth grow, because standing up a trained annotation workforce internally takes months.

What should I look for in an AI data pipeline vendor?

Look for evidence rather than claims, including measured annotation accuracy, gold-standard audits, versioned and reproducible datasets, multimodal coverage, and a documented governance posture with encryption, access controls, and no training on your data. Also check that the deployment model and SLAs fit your industry’s data-residency and reliability requirements.

The Enterprise Buyer’s Guide to AI Data Pipelines in 2026 Read Post »

Essential Capabilities to Look for in AI Data Collection Services

7 Essential Capabilities to Look for in AI Data Collection Services

AI data collection services help enterprises source, capture, and curate the raw data that machine learning models rely on, including text, images, video, audio, and sensor streams. The right partner is defined by seven core capabilities: domain diversity, multimodal data support, geographic and linguistic reach, informed consent and provenance, quality validation, security certifications, and refresh pipelines that keep datasets accurate and current.

The cost of a weak dataset rarely shows up during the pilot. It shows up in production, when a model meets conditions its training data never represented, and accuracy quietly drops. Choosing among AI data collection services deserves the same scrutiny you would apply to any core infrastructure decision. Building these programs well takes end-to-end data collection and curation services engineered for production, and the seven capabilities below are the ones that consistently separate reliable datasets from fragile ones.

Key Takeaways

  • AI data collection services gather and prepare the raw text, images, video, audio, and sensor data that AI models learn from.
  • Weak data usually causes no trouble during testing but breaks the model later, once it faces real-world situations.
  • The data should reflect where your product will actually be used, across different scenarios, regions, languages, and formats.
  • You should always be able to prove the data was gathered with permission and handled to proper security standards.
  • Good providers measure their quality with real numbers instead of just claiming the work is good.
  • Data can become outdated over time, so it needs to be refreshed regularly to keep the model relevant and accurate.

What Are AI Data Collection Services, and How Do They Differ from Annotation?

AI data collection services are provided by specialized companies that source, capture, generate, and curate the datasets used to train and evaluate machine learning models. The work runs from requirements definition through sourcing or capture, cleaning, formatting, and delivery, usually supported by data engineering for AI that moves data at the target volume without breaking quality. Collected data covers every modality a model consumes, including text, images, video, audio, LiDAR and radar point clouds, GPS traces, and structured records.

Collection and annotation are distinct stages of the same pipeline, and buyers who conflate them tend to pick the wrong partner. Collection produces the raw material; annotation adds the labels that tell a model what the raw material means. Data annotation in machine learning turns collected data into trainable examples for the AI models. A strong annotation vendor usually has limited capability to source representative data in the first place, which is why the two functions need to be evaluated on their own terms.

Which Capabilities Separate a Reliable AI Data Collection Partner from a Risky One?

The seven capabilities below are not a wish list, and each one maps to a specific way data programs fail once a model reaches production. They move from the data itself outward: what it covers, where it comes from, how it is checked, how it is secured, and how it stays current. Every one is something you can ask a provider to demonstrate before you sign, which turns a vague quality conversation into a concrete checklist. Read the rest of this guide as that checklist, and hold any partner you consider against all seven.

Capability 1- Domain Diversity: Does the Data Match Your Real Operating Conditions?

A model generalizes only as far as its training data represents the conditions it will face in production. Domain diversity measures whether a dataset spans the environments, edge cases, and rare events of your actual deployment rather than the common “happy path” alone. A pretrainer’s guide to training data reports that domain coverage and data age both measurably affect downstream model quality, which makes coverage a specification to define, not an afterthought. Setting a deliberate data collection strategy for AI training forces those coverage requirements into the brief before collection starts. Ask a prospective partner how they source edge cases and how they prove a dataset covers your operating domain.

Capability 2- Multimodal Support: Can One Partner Handle Text, Image, Video, Audio, and Sensor Data?

Modern AI systems increasingly combine modalities inside a single model, so collection projects now span text, image, video, audio, and sensor data at once. A provider limited to one modality forces you to split the work across vendors, which fragments quality standards and complicates alignment across data types. Capability in multimodal data annotation signals whether a partner can hold labeling schemas and quality bars consistent when the same scene appears as video, audio, and point cloud. For Physical AI, ADAS, and autonomous systems, time-synchronized multimodal capture is a hard requirement, since perception depends on sensor streams that agree with each other frame by frame.

Capability 3- Geographic and Linguistic Reach: Will the Data Represent Your Actual Users?

If your product ships globally, training data drawn from one region or one language will underperform for everyone else. Geographic and linguistic reach determines whether a dataset reflects the demographics, dialects, and physical environments of your real user base. Coverage of low-resource language services is a strong differentiator, since most providers handle high-resource languages well and quietly fall short on the rest. Confirm that reach comes from in-market contributors rather than machine translation of a single source dataset, which strips out cultural and contextual nuance.

Capability 4- Informed Consent and Data Provenance: Can You Prove Where the Data Came From?

Every dataset you deploy carries the legal and ethical history of how it was collected. Informed consent frameworks and clear provenance let you show, on demand, that data was gathered with permission and is licensed for your use. A large-scale audit of dataset licensing and attribution in AI traced more than 1,800 datasets and found licensing and provenance documentation frequently missing or inconsistent, which pushes real legal risk onto downstream users. Documented consent chains and trust and safety solutions are what let an enterprise defend its training data under scrutiny. Treat provenance records as a named deliverable, and require them in writing before collection begins.

Capability 5- Quality Validation: How is Collection and Label Quality Measured?

Quality that is asserted but not measured is a liability. Robust validation reports concrete metrics including inter-annotator agreement, label consistency on repeated samples, and coverage against the agreed specification. A dependable partner runs a multi-layer review and can show the acceptance criteria a dataset passed before delivery. Ask for the numbers, because a provider that cannot report agreement rates or consistency scores is asking you to take quality on faith. Validation is also where pilots and production diverge, since QA that holds at ten thousand samples often breaks at ten million.

Capability 6- Security Certifications: Is Your Data Handled to Enterprise Standards?

Sensitive training data for medical images, financial records, in-cabin footage, etc.,  demands handling that meets recognized standards. Security certifications such as SOC 2 Type II, ISO 27001, GDPR alignment, and sector rules like HIPAA give you an external check on how a provider stores, transfers, and restricts access to your data. These certifications encode access controls and audit trails that determine whether an incident stays contained. Confirm the certification is current and that it covers the specific facilities and workforce assigned to your project, not just the provider’s headquarters.

Capability 7- Ongoing Pipeline Refresh: What Keeps the Dataset from Going Stale?

A dataset is a snapshot, and the world it describes keeps moving. Refresh pipelines re-collect, re-validate, and extend data so a model keeps matching reality as conditions, policies, and edge cases change. The Consent in Crisis audit of the AI data commons found that within a single year, web sources restricted roughly 5% of the tokens in the widely used C4 corpus, and a far larger share of its most actively maintained sources, which steadily erodes the freshness of any static collection. A partner without a standing refresh loop leaves you re-buying the same dataset from scratch each time performance slips. Ask how re-collection is triggered, how often it runs, and how new data is reconciled with the old.

How Digital Divide Data Can Help

Digital Divide Data (DDD) runs enterprise data collection and curation as an end-to-end program rather than a single task. That means sourcing representative data across domains, capturing synchronized multimodal and sensor streams for Physical AI, ADAS, and autonomous systems, and extending coverage into languages and regions where generic providers thin out. Each dataset moves through defined acceptance criteria and multi-layer review, so quality is reported as measured agreement and consistency rather than asserted.

Consent, provenance, and secure handling are built into how the work is delivered, with documented sourcing and trust-and-safety controls that hold up to legal and compliance review. Refresh is treated as part of the engagement, so datasets keep pace with changing conditions instead of decaying after launch. Teams that need domain diversity, multimodal capture, and defensible provenance in one place can consolidate those requirements with a single partner.

Build data collection programs that survive contact with production. Talk to an Expert

Conclusion

The organizations that treat these seven capabilities as procurement requirements catch data problems before a model reaches production. The organizations that treat data collection as a commodity discover the same problems later, in the field, where every fix costs more and moves slower. Domain diversity, multimodal support, reach, consent, validation, security, and refresh are the levers that decide which outcome you get.

Before signing with any provider, work through evaluation of AI training data providers against your own requirements, and plan for the reality to avoid model performance degradation over time unless the underlying data keeps getting refreshed. The dataset you buy today is only as durable as the pipeline that maintains it.

References

Longpre, S., Yauney, G., Reif, E., Lee, K., Roberts, A., Zoph, B., Zhou, D., Wei, J., Robinson, K., Mimno, D., & Ippolito, D. (2023). A Pretrainer’s Guide to Training Data: Measuring the Effects of Data Age, Domain Coverage, Quality, & Toxicity. arXiv preprint arXiv:2305.13169. https://arxiv.org/abs/2305.13169

Longpre, S., Mahari, R., Chen, A. et al. A large-scale audit of dataset licensing and attribution in AI. Nat Mach Intell 6, 975–987 (2024). https://doi.org/10.1038/s42256-024-00878-8

Frequently Asked Questions

What are AI data collection services?

They are specialized providers that source, capture, generate, and curate the raw data used to train and evaluate machine learning models. The work runs from requirements definition through sourcing, cleaning, formatting, and delivery across every modality a model uses, from text to sensor streams.

How is AI training data collected?

It is gathered through a pipeline that defines requirements, sources or captures raw data, cleans and formats it, and delivers it to spec. The goal is coverage of your real operating conditions, including edge cases and rare events, not just the most common scenarios.

What is the difference between data collection and data annotation?

Collection produces the raw data, including the images, video, audio, or records themselves, while annotation adds the labels that tell a model what that material means. They are separate stages, and a strong labeling vendor will not automatically be strong at sourcing representative data.

How do AI data collection services ensure consent and compliance?

Reliable providers use informed consent frameworks and keep documented provenance, so you can prove data was gathered with permission and licensed for your use. Recognized security certifications and trust-and-safety controls give an external check that the handling meets enterprise and regulatory standards.

7 Essential Capabilities to Look for in AI Data Collection Services Read Post »

AI in Supply Chain

AI in Supply Chain: What Demand Forecasting and Logistics Models Need From Training Data

Kevin Sahotsky

Almost every supply chain leader I talk to is already running an AI pilot of some kind: demand forecasting, route optimization, inventory planning. Most of them are also quietly frustrated, because the pilot performed well in the demo and then underdelivered once it touched real operations. The model wasn’t wrong about the math. It was working from data that didn’t reflect the supply chain it was actually being asked to plan for.

This is particularly relevant for supply chain leaders, demand planning teams, and operations executives who are past the pilot stage and trying to figure out why their AI forecasting tool isn’t closing the gap they expected. The industry-wide numbers back this up. Most organizations plan to use AI for supply chain decisions within the next couple of years, but only a small fraction have a formal strategy for getting there, and the gap between adoption and actual readiness is almost always a data gap before it’s a model gap.

This blog covers what demand forecasting and logistics models actually need from their training data to perform reliably in production, not just in a pilot. Data collection and curation services and AI data preparation services are the two capabilities most directly involved in closing the gap between a forecasting model that looks good on a slide and one that actually holds up against real demand volatility.

Key Takeaways

  • Demand forecasting models trained only on historical sales data systematically underperform during demand shifts, because the signal that predicts a shift rarely lives in the sales history itself.
  • Supply chain AI needs data integrated across systems that were never designed to talk to each other. Partner data chaos, not model architecture, is the most common reason forecasting and logistics AI underdelivers.
  • SKU-level and category-level forecasting have very different data requirements, and treating them the same way is one of the most common planning mistakes.
  • Exception and disruption data- the supplier delay, the port closure, the demand spike- is the training signal that determines whether a model can do more than predict business as usual.
  • Human review at the exception layer is what keeps automated forecasting accurate, because full autonomy isn’t the goal right now. Appropriate autonomy is.

Why Forecasting Models Underdeliver Outside the Pilot

Historical Sales Data Is a Starting Point, Not a Foundation

Traditional forecasting leaned almost entirely on historical sales data, and that’s exactly where a lot of AI forecasting pilots still start. The problem is that historical sales data tells you what happened under the conditions that existed at the time. It doesn’t tell you why those conditions are about to change. A model trained purely on sales history will perform reasonably well during stable periods and fail exactly when you need it most, during a demand shift, a new product launch, or a market disruption.

This isn’t a hypothetical concern. Industry data shows AI-powered forecasting can reduce forecast errors meaningfully and cut inventory costs, but those gains depend on the model having access to a broader mix of signals than historical sales curves alone. Retailers that combined external signals with real-time inventory visibility saw the greatest improvements, specifically because the model had something other than the past to reason from.

The Real Bottleneck Is Partner Data Chaos

Ask supply chain leaders what’s actually holding AI back day to day, and the answer that comes up again and again isn’t the model. It’s the mess of formats, systems, and partner data that the model has to be fed from. Suppliers report inventory differently. Carriers report transit status on different schedules. Internal systems were built for different purposes at different times and were never designed to be queried together. Data engineering for AI that builds the integration layer connecting these disparate sources into a consistent, queryable structure is what turns partner data chaos into something a forecasting model can actually use, and it is consistently the unglamorous work that determines whether the visible AI layer performs.

What Demand Forecasting Models Actually Need

SKU-Level vs. Category-Level Forecasting Have Different Data Needs

One of the most common mistakes I see is treating SKU-level and category-level forecasting as the same data problem at different resolutions. They aren’t. Category-level forecasting can tolerate more noise in any individual data point because the aggregation smooths it out. SKU-level forecasting, especially for products with intermittent or erratic demand patterns, needs cleaner, more granular data because there’s no aggregation to hide a labeling error or a missing data point.

This matters most for businesses managing SKU proliferation: large retailers and consumer goods companies that are tracking demand across thousands of individual products. A forecasting approach that works fine at the category level can produce confidently wrong SKU-level forecasts if the underlying data wasn’t curated with that level of granularity in mind from the start.

External Signals Are Not Optional Anymore

The forecasting approaches that are actually moving the needle right now combine internal sales data with external signals: economic indicators, weather patterns, regional events, competitor activity, and social signals where relevant. Collecting and structuring these external signals consistently, so they can be joined to internal sales data on a common timeline, is a data engineering task that most internal teams underestimate the effort of. Data collection and curation services that source and standardize external demand signals on an ongoing basis, not as a one-time enrichment, are what let a forecasting model actually use this information rather than treating it as an occasional input that goes stale.

Seasonality and Intermittent Demand Need Explicit Handling

Demand patterns that are seasonal, intermittent, or erratic break the assumptions that simpler forecasting methods rely on. A model that hasn’t been given enough historical cycles to learn a seasonal pattern, or training data with sparse and irregular intermittent-demand examples, will produce point forecasts that look plausible and are systematically wrong in predictable ways: missing the seasonal peak, or smoothing over the spikes that intermittent-demand products actually exhibit. The fix isn’t a different algorithm. It’s making sure the training data includes enough cycles and enough representation of the demand pattern types the business actually has.

What Logistics and Routing Models Need

Real-Time Data, Not Just Planning Data

Route optimization and ETA prediction depend on data that’s current, not just historical. A model trained on historical transit times without real-time traffic, weather, and carrier status data will optimize for a world that no longer exists by the time the truck leaves the dock. The practical implication is that logistics AI needs a live data pipeline, not a periodically refreshed training set, and the infrastructure to keep that pipeline current is a meaningfully different investment than the one-time data preparation that a static forecasting model might get away with.

Exception Data Is the Most Valuable and Least Collected

Most logistics data pipelines are built to capture the normal case well and the exception case poorly. The supplier delay, the port closure, the carrier capacity shortfall- these are exactly the events that determine whether a logistics AI system adds value beyond what a simple rules engine could already do, and they’re also the events most likely to be missing, inconsistently labeled, or buried in free-text notes rather than structured fields. AI data preparation services that specifically target exception event extraction and structuring, pulling disruption data out of free text and into a consistent schema, give logistics models the training signal they need to do more than optimize for business as usual.

Why Human Review at the Exception Layer Still Matters

Full autonomy in supply chain AI isn’t where the industry actually is right now, and the practitioners closest to deployment are honest about that. The current consensus across the field is that appropriate autonomy, not full autonomy, is the right target for 2026. Automated forecasts paired with human review on exceptions and material categories consistently outperform either fully automated or fully manual approaches.

Building that human review layer into the data pipeline, not as an afterthought but as a designed checkpoint, is what keeps a forecasting system’s error rate from compounding silently. Model evaluation services that score forecast accuracy by category, by exception type, and by demand pattern, rather than as a single aggregate accuracy number, are what let a supply chain team know where the human review needs to be concentrated rather than spread thin across everything.

How Digital Divide Data Can Help

Digital Divide Data supports supply chain and logistics teams building the data foundation that demand forecasting and routing models actually need. For programs that need external demand signals collected and standardized on an ongoing basis, data collection and curation services source and structure economic, weather, and market signals so they can be joined cleanly to internal sales data. 

For programs that need exception and disruption events extracted from free-text logs into structured, model-ready fields, AI data preparation services turn unstructured supplier, carrier, and operations notes into the training signal that logistics models need to handle disruption. For programs connecting fragmented partner and internal systems into a single queryable pipeline, data engineering for AI builds the integration layer that turns partner data chaos into a usable forecasting input.

If your forecasting model performs well in the pilot and underdelivers in production, the gap is almost always in the data feeding it, not the model architecture. Talk to an expert.

Conclusion

The supply chain AI gap that emerges between a strong pilot and a disappointing production rollout is rarely an algorithmic problem. It’s a data problem: historical sales data without external signals, fragmented partner systems never designed to be queried together, and exception events that occur in the operation but never make it into a structured training set. Each of these is solvable, but only if the team treats data integration and curation as the primary investment rather than something the model is supposed to work around.

The organizations pulling ahead in supply chain AI aren’t the ones with the most sophisticated forecasting algorithm. They’re the ones that did the less visible work of making sure their models had real, current, well-structured signal to learn from. What does your current forecasting pipeline actually feed the model, and how much of it is historical sales data alone?

References

Logistics Viewpoints. (2025, December 22). AI in logistics: What actually worked in 2025 and what will scale in 2026. https://logisticsviewpoints.com/2025/12/22/ai-in-logistics-what-actually-worked-in-2025-and-what-will-scale-in-2026/

Inbound Logistics. (2026, January 8). AI in supply chain management: 2026 outlook. https://www.inboundlogistics.com/articles/ai-in-supply-chain-management-how-useful-will-it-be-in-2026/

Frequently Asked Questions

Q1. Why does a demand forecasting model that performed well in a pilot underdeliver once it is deployed at scale?

Pilots are often run on a clean, curated slice of data and a stable demand period. Production exposes the model to the messier reality: fragmented partner data, demand patterns the pilot dataset didn’t include, and exception events that weren’t part of the pilot’s scope. The model’s architecture usually isn’t the problem. The training data it’s actually getting in production is narrower or noisier than what it learned from during the pilot, and that gap is what shows up as underperformance.

Q2. What external data signals matter most for demand forecasting beyond historical sales?

It depends on the category, but the signals that consistently add value are economic indicators relevant to the customer base, weather data for weather-sensitive categories, regional event calendars, and competitor pricing or promotion activity where it’s trackable. The specific mix matters less than having a consistent process for collecting and standardizing whichever signals are relevant to your categories, so the model can actually learn a stable relationship between the signal and the demand shift rather than seeing it inconsistently.

Q3. How should a supply chain team prioritize data investment between forecasting accuracy and logistics optimization?

Start with whichever side is generating the more expensive errors right now. If you’re consistently overstocking or understocking specific categories, the forecasting data investment will pay off faster. If you’re missing delivery windows or absorbing avoidable transportation costs because of routing decisions made on stale data, the logistics data pipeline is the higher-value investment. Most teams need both eventually, but sequencing the investment around your most expensive current error avoids spreading a limited budget too thin to fix either one well.

Q4. How much human review should remain in an automated forecasting and logistics pipeline?

Enough that exceptions and high-consequence categories get a human check before the system acts on them automatically. Full autonomy isn’t where the field is right now, and the practitioners closest to production deployment are explicit that appropriate autonomy, not full autonomy, is this year’s realistic target. A practical approach is to automate the routine, high-confidence cases and route anything flagged as an exception, a material category, or a low-confidence prediction to a human reviewer before it triggers a downstream action.

Q5. What is the most common reason a supply chain AI program stalls after the pilot phase?

Underestimating the data integration work required to move from a pilot dataset to a production data pipeline. A pilot can run on a manually assembled, cleaned dataset. Production requires an ongoing pipeline that ingests, standardizes, and validates data from multiple internal systems and external partners on a continuous basis. Teams that scope the pilot but not the production data infrastructure consistently find that the second phase takes longer and costs more than the first, and that gap is where many programs stall.

AI in Supply Chain: What Demand Forecasting and Logistics Models Need From Training Data Read Post »

Metadata Enrichment

What Is Metadata Enrichment and Why Does It Determine Whether Digitized Content Is Actually Useful

An organization can digitize a million documents and still not be able to find the one it needs. Digitization converts a physical or unstructured asset into a digital file. It does not make that file discoverable, classifiable, or usable by a downstream system. The step that does that work is metadata enrichment, and it is the step most digitization programs underinvest in relative to scanning and OCR.

Metadata enrichment is the process of generating and attaching structured descriptive information to a digitized asset: subject classification, named entities, document type, date and jurisdiction references, relationships to other documents, and the controlled vocabulary terms that a search or retrieval system depends on. Without it, a digitized archive is a large pile of searchable text. With it, the same archive becomes a structured resource that a person or an AI system can navigate, filter, and reason over.

This blog covers what metadata enrichment actually involves, why automated extraction alone is not sufficient for most enterprise content, and what a production-grade enrichment program looks like. AI data preparation services and text annotation services are the two capabilities most directly involved in turning digitized but unstructured content into metadata-enriched, AI-ready assets.

Key Takeaways

  • Digitization and metadata enrichment are different steps with different failure modes. A document can be perfectly digitized and completely unusable if it carries no structured metadata.
  • Automated metadata extraction handles common, well-structured document types reasonably well, but degrades on ambiguous, domain-specific, or low-frequency content types where human review is still required.
  • Inconsistent vocabulary across a collection is the most common cause of poor retrieval performance, and it is usually invisible until someone runs a query that should return everything on a topic and gets back a fraction of it.
  • Metadata schema design has to happen before enrichment begins. Retrofitting a schema onto an already-enriched collection is significantly more expensive than designing it up front.
  • Metadata enrichment is what makes a digitized collection usable by AI systems, not just searchable by keyword. Structured metadata is what allows a retrieval system or a language model to filter, scope, and reason over a collection rather than only matching text strings.

Why Digitization Alone Does Not Make Content Usable

What Digitization Actually Produces

Digitization, in its narrowest sense, converts a physical document into a digital file and extracts the text it contains. The result is searchable text, which is a real improvement over an unsearchable paper or image file. But searchable text only supports keyword matching. It does not tell a system what kind of document this is, who or what it refers to, when it was created, what jurisdiction or department it relates to, or how it connects to other documents in the collection.

An organization with a million digitized contracts can search for a specific word across all of them. It cannot easily ask for all contracts with a specific counterparty, governed by a specific jurisdiction, expiring within a specific window, unless that information has been extracted and structured as metadata. Keyword search and structured retrieval are different capabilities, and only the second one requires enrichment.

The Discoverability Gap in Practice

This gap is well documented at scale, not just theoretical. Europeana, the European Union’s digital cultural heritage platform aggregating more than 55 million objects from museums, libraries, and archives, commissioned a task force to evaluate its own metadata enrichment process across seven datasets. The review found recurring failures at each stage of enrichment: source records linked to the wrong external vocabulary term, enrichments applied inconsistently across similar objects, and multilingual links that introduced incorrect translations rather than useful ones. The underlying objects were already digitized and described. The retrieval problems came specifically from how the enrichment layer was built on top of that description, which is the same gap that shows up in a research library that cannot reliably surface every digitized thesis in a given subfield, or a legal team that cannot generate a report of every contract with a specific risk profile, because the classification was never applied consistently in either case. 

In both cases, the underlying text was successfully digitized. The information the organization actually needed was present in the documents. It was simply never extracted into a form that a system could query directly. That is the gap metadata enrichment closes.

What Metadata Enrichment Actually Involves

Descriptive Metadata

Descriptive metadata captures what a document is about: subject classification, keywords, abstract or summary content, and document type. This is the metadata category most people think of first, and it is what most general-purpose automated tools attempt to generate. For straightforward, well-structured content, automated subject classification can work reasonably well. For domain-specific or ambiguous content, automated classification frequently misclassifies or assigns overly broad categories that do not support precise retrieval.

Entity and Relationship Metadata

Entity metadata identifies the people, organizations, locations, dates, and other named entities referenced in a document. Relationship metadata captures how documents relate to each other: amendments to an original contract, citations between research papers, or correspondence threads connected to an original filing. Entity and relationship metadata are what allow a system to answer questions like every document referencing this person, or every amendment to this specific agreement, rather than only documents containing this specific word.

Building accurate entity metadata at scale requires named entity recognition tuned to the document domain. A general-purpose entity extraction model trained on news text will perform inconsistently on legal filings, medical records, or historical archives, each of which has its own naming conventions, abbreviations, and domain-specific entity types that a general model was never trained to recognize.

Administrative and Technical Metadata

Administrative metadata records information about the digitization and enrichment process itself: when the document was digitized, what process was used, who reviewed and validated the metadata, and what confidence level applies to automated fields that were not manually verified. Technical metadata records the digital characteristics of the file: format, resolution, and the parameters of the digitization equipment used. Both categories matter less for day-to-day retrieval and more for governance, auditability, and long-term preservation, particularly in regulated industries where provenance has to be demonstrable. AI data preparation services that track administrative metadata as a standard component of the digitization and enrichment pipeline produce collections that can withstand an audit of how every metadata field was generated and verified.

Why Automated Extraction Alone Falls Short

Where Automation Performs Well

Automated metadata extraction, using natural language processing and increasingly large language models, performs well on high-volume, well-structured, low-ambiguity content. Standard business correspondence, structured forms, and documents with consistent formatting are reasonable candidates for automated subject tagging, entity extraction, and classification with limited human review.

Where Automation Breaks Down

Automated extraction degrades on domain-specific vocabulary, ambiguous classification boundaries, and low-frequency document types that the underlying model was not well-trained on. A model that has seen a small number of examples of a specific document type in its training data will produce inconsistent or low-confidence classifications for that type, even if it performs well on common document categories.

The degradation is not always obvious from the model’s output. Research on enriching long documents with large language models has found that this kind of misclassification can look plausible and confident even when it is wrong, which is exactly the failure mode that is hardest to catch without human review. An automated metadata program that does not include systematic human validation will accumulate silent errors that compound as the collection grows and as more systems come to depend on the metadata being accurate.

Controlled Vocabulary and Consistency

One of the most common and costly automated extraction failures is inconsistent vocabulary: the same underlying concept tagged with different terms across different documents because the extraction process was not anchored to a controlled vocabulary. A collection where one document is tagged ‘healthcare policy’ and another conceptually identical document is tagged ‘health regulation’ will fragment search results and break any downstream analysis that depends on consistent categorical grouping. Text annotation services that apply a controlled vocabulary consistently across a collection, with human reviewers trained on the specific taxonomy, prevent this fragmentation in a way that unsupervised automated tagging cannot guarantee on its own.

Designing a Metadata Schema Before Enrichment Begins

Why Schema Design Cannot Be an Afterthought

A metadata schema defines what fields exist, what values are valid for each field, and how fields relate to each other. Designing this schema requires understanding how the collection will actually be used: what questions users will ask of it, what systems will consume the metadata downstream, and what level of granularity is useful versus excessive.

Retrofitting a schema onto a collection that has already been enriched without one is significantly more expensive than designing it up front. If a collection was tagged with inconsistent, ad hoc categories and an organization later wants to standardize, every previously enriched document needs to be revisited and reclassified against the new schema. That rework cost is avoidable with upfront schema design, and it is one of the most common reasons enrichment programs end up costing more than originally planned.

Aligning Schema to Standards Where They Exist

For many domains, established metadata standards already exist and provide a starting point rather than requiring a schema to be built from nothing. Dublin Core is a widely used general-purpose standard for digital library and archival content. Domain-specific standards exist for scientific data, legal documents, and other specialized content types. Starting from an established standard and extending it for domain-specific needs produces a schema that is more likely to be interoperable with other systems and easier for new team members or partner organizations to understand.

What a Production-Grade Metadata Enrichment Program Looks Like

Hybrid Automated and Human Review Workflows

Industry research on metadata and AI readiness points to the same conclusion: the most reliable enrichment programs use automated extraction to generate an initial pass at metadata, then route that output through human review calibrated to the confidence level and the sensitivity of the document type. High-confidence, low-stakes classifications can be accepted with spot-check review. 

Low-confidence or high-stakes classifications, such as those affecting compliance, legal risk, or patient safety in healthcare-adjacent collections, require full human verification before the metadata is considered final. AI data preparation services that implement this kind of confidence-tiered review process produce enriched metadata at a cost and speed that pure manual tagging cannot match, without accepting the silent error rate that pure automation introduces.

Ongoing Quality Monitoring

Metadata quality is not a one-time deliverable. As a collection grows and as new document types are introduced, the extraction and classification process needs ongoing monitoring to catch drift: categories that are being applied inconsistently, new document types that the original schema did not anticipate, or entity recognition that is degrading on a specific subset of content. Programs that treat metadata enrichment as a single project rather than an ongoing operational discipline tend to see metadata quality decline gradually as the collection evolves past what the original enrichment process was designed for.

How Digital Divide Data Can Help

Digital Divide Data supports organizations turning large digitized collections into structured, AI-ready assets through metadata enrichment programs designed around the specific schema and quality requirements of each collection. For programs that design the metadata schema and classification taxonomy before enrichment begins, AI data preparation services include schema design grounded in downstream use cases and alignment with existing metadata standards where applicable. 

For programs requiring accurate entity extraction and controlled vocabulary tagging at scale, text annotation services provide annotation teams trained on domain-specific taxonomies who apply controlled vocabulary consistently across a collection. For programs that connect enriched metadata to downstream retrieval, search, or AI training pipelines, data engineering for AI services builds the infrastructure that makes enriched metadata usable by the systems that depend on it.

If your digitized archive is searchable but your teams still cannot find what they need or build the reports they want, the gap is very likely in metadata enrichment, not digitization. Talk to an expert.

Conclusion

Digitization makes content exist in digital form. Metadata enrichment makes that content findable, classifiable, and usable by the systems an organization actually depends on. The two are different problems with different failure modes, and an organization that has invested heavily in digitization without a comparable investment in enrichment will discover that its archive, while searchable, still cannot answer the structured questions its teams actually need answered.

Programs that get enrichment right, design the schema before they start tagging, use automation where it performs reliably, route ambiguous and high-stakes content through human review, and monitor metadata quality on an ongoing basis rather than treating it as a one-time project. 

What questions can your organization not currently answer about its own digitized content, the ones buried in a metadata gap rather than a digitization one?

Frequently Asked Questions

Q1. What is the difference between digitization and metadata enrichment?

Digitization converts a physical or unstructured asset into a digital file and extracts the text it contains, producing content that can be searched by keyword. Metadata enrichment adds structured descriptive information to that content: subject classification, entities, relationships, and controlled vocabulary terms. Digitization makes content exist digitally. Enrichment makes it discoverable, filterable, and usable by downstream systems beyond simple keyword search.

Q2. Can automated tools fully replace human review in a metadata enrichment program?

Not reliably for most enterprise content. Automated extraction performs well on high-volume, well-structured, low-ambiguity content, but degrades on domain-specific vocabulary, ambiguous classification boundaries, and low-frequency document types. The degradation is often not apparent in the model’s output, since a confident-looking misclassification is harder to detect than an obvious error. A hybrid workflow, automated extraction with human review calibrated to confidence level and document sensitivity, produces more reliable metadata than either pure automation or pure manual tagging alone.

Q3. Why does inconsistent vocabulary matter so much for metadata quality?

Because retrieval and analysis systems depend on consistent categorical grouping, if the same underlying concept is tagged with different terms across different documents, a search or filter for one term will miss documents tagged with the other term, even though they describe the same thing. This fragmentation compounds as a collection grows, and it is one of the most common reasons large digitized archives underperform on retrieval despite having reasonably accurate text extraction. A controlled vocabulary, applied consistently, is the fix.

Q4. How do you decide what fields to include in a metadata schema?

Start from how the collection will actually be used: what questions users need to ask of it, what systems will consume the metadata downstream, and what level of granularity is useful without becoming excessive. Align to an existing metadata standard for the domain where one exists, such as Dublin Core for general digital library content or a domain-specific standard for specialized content types, and extend it only as needed for organization-specific requirements. Schema design should happen before enrichment begins, because retrofitting a schema onto an already-enriched collection requires reclassifying everything that was tagged under the old approach.

What Is Metadata Enrichment and Why Does It Determine Whether Digitized Content Is Actually Useful Read Post »

Evaluate VLA Model

How to Evaluate VLA Model for Real-World Deployment: Grounding, Planning, and Action Fidelity

Kevin Sahotsky

Here’s a question I get from robotics and physical AI teams more often than I used to: we have a VLA model that looks impressive in the demo, how do we know if it will actually hold up once it leaves the lab? It’s a fair question, and the honest answer is that most teams do not have a good way to answer it yet. The benchmarks the model was trained and reported against often measure something narrower than what deployment actually requires.

Vision-Language-Action models are being evaluated in the way earlier generations of computer vision models were evaluated: a held-out test set, a success rate, and a leaderboard position. That approach tells you how the model performs on a distribution similar to its training data. It tells you very little about whether the model will ground a spoken instruction correctly in a cluttered warehouse, plan a multi-step task when the first attempt fails, or execute an action with the physical fidelity that a real task requires. This is particularly relevant for robotics program leads, physical AI product teams, and operations leaders evaluating whether a VLA model is ready to move from a controlled pilot into a live deployment.

This blog walks through the three capabilities that actually determine whether a VLA model is deployment-ready: grounding, planning, and action fidelity, and what evaluating each of them looks like in practice. Model evaluation services and video annotation services are the two capabilities most directly involved in building VLA evaluation programs that predict real-world performance rather than benchmark performance.

Key Takeaways

  • Standard VLA benchmarks measure performance on a distribution similar to the training data. They do not reliably predict performance in a specific deployment environment with its own object sets, lighting, and task variations.
  • Grounding, planning, and action fidelity are three distinct capabilities that fail independently. A model can ground language well and still fail at multi-step planning, or plan well and still execute with poor physical fidelity.
  • Out-of-distribution evaluation, testing on object placements, lighting, and task variations the model has not seen, is a better predictor of deployment performance than in-distribution benchmark scores.
  • Action fidelity cannot be assessed from success rate alone. Two policies with the same success rate can have very different margins for error, and that margin is what determines reliability at scale.
  • A model evaluation program built around your specific deployment task taxonomy will catch failure modes that a general VLA leaderboard never surfaces.

Why Standard Benchmarks Undersell the Real Question

What Leaderboard Scores Actually Measure

Most published VLA benchmarks evaluate models on tasks and environments that are either simulated or closely matched to the training distribution. A model can score well on these benchmarks because the test conditions are similar enough to what it has already seen. That is a legitimate measure of in-distribution capability. It is not a measure of whether the model will work in your warehouse, your kitchen, or your assembly line, where the objects, the lighting, and the task variations will not match the benchmark distribution.

This gap matters more for physical AI than it did for earlier generations of language or vision models, because the cost of a wrong answer is physical. A chatbot that gives an unhelpful response is an inconvenience. A robot that misjudges a grasp or executes the wrong action in a live environment is a safety and operational problem.

Out-of-Distribution Performance Is the Real Signal

Recent benchmarking work in the field has made a point that matters here: models trained primarily on action data can transfer reasonably well to environments that resemble their training distribution, but performance drops sharply when visual conditions or task mechanics shift outside that distribution. That is the gap that matters for deployment. If your environment, your object set, or your task structure differs meaningfully from what the model was trained on, the benchmark score tells you very little about what will happen in production.

The practical implication is that evaluation needs to be built around your specific deployment context, not borrowed wholesale from a published leaderboard. A model that ranks well on a general benchmark may still fail consistently on the specific variations your environment introduces.

Grounding: Does the Model Understand What You Are Asking?

What Grounding Failures Look Like

Grounding is the model’s ability to connect a language instruction to the correct object, location, or action in its visual field. A grounding failure looks like the model picking up the wrong object when two similar items are present, or misinterpreting a spatial reference like “the one on the left” when the scene has shifted from how it appeared in training.

Grounding failures are often invisible in simple test environments because there is only one plausible object or location for the model to act on. They become visible the moment you add visual clutter, similar-looking objects, or ambiguous spatial language, which is exactly what real environments contain in abundance.

The business cost of a grounding failure shows up as rework and damaged trust rather than a single dramatic incident. A model that picks up the wrong part on an assembly line creates a defect that gets caught downstream, at a higher cost than catching it at the source. A model that misreads a spatial instruction in a fulfillment center sends the wrong item, which becomes a customer-facing SLA breach and a return to process. Multiply a small grounding error rate by daily production volume, and the cost stops looking small.

Evaluating Grounding Under Realistic Ambiguity

A grounding evaluation needs deliberately ambiguous scenes: multiple objects of similar type, instructions that require spatial or relational reasoning, and language phrasings that vary from the canonical form the model may have been trained on. Video annotation services that label ground-truth object references and spatial relationships in evaluation footage give you the basis for scoring whether the model’s grounding matches what a human would understand the instruction to mean, rather than just whether the model picked up some object.

Planning: Does the Model Handle Multi-Step Tasks and Recover From Failure?

Single-Step Success Hides Planning Weakness

Many real tasks require a sequence of actions, and a model can execute each action competently while still failing at the task because it does not sequence them correctly, does not recognize when an earlier step failed, or cannot adapt the plan when the environment does not match its expectation. A model evaluated only on isolated single-step actions will look far more capable than it will behave in a multi-step task.

Hierarchical approaches that separate high-level planning from low-level execution have shown that grounding ambiguous instructions and adapting plans dynamically remains one of the harder open problems in the field. That should inform how much weight you put on a model’s single-step benchmark score relative to its actual planning behavior.

Planning failures are typically what cause unplanned downtime, not a single bad action. A robot that cannot recognize a failed step will either stall and wait for human intervention, which stops the line, or continue executing a plan built on a false assumption, which can damage product or equipment before anyone notices. Both outcomes carry a direct cost in lost throughput, and the second carries an added repair or scrap cost on top of it.

Designing an Evaluation for Recovery Behavior

Planning evaluation should deliberately introduce failure points: an object that is not where the model expects it, a step that cannot be completed on the first attempt, or a change in the environment mid-task. The question is not whether the model can execute a clean multi-step task when everything goes as expected. It is whether the model notices when something has gone wrong and adapts rather than continuing to execute a plan based on a stale assumption.

Action Fidelity: How Precisely Does the Model Execute?

Why Success Rate Alone Is Not Enough

Two policies can report the same success rate on a benchmark while having very different margins for error. One policy might complete a grasp with a wide, stable margin every time. Another might complete the same grasp at the edge of what is mechanically possible, succeeding in the test conditions but failing the moment an object’s weight, texture, or position shifts slightly. Success rate does not distinguish between these two cases, and that distinction is exactly what determines whether a model is reliable at production scale.

Action fidelity evaluation requires looking past the binary success label to the quality of the execution itself: trajectory smoothness, contact stability, and how close the action came to the failure boundary, even when it technically succeeded.

A narrow action fidelity margin is the kind of risk that does not show up until volume increases or conditions drift slightly, and then it shows up as a safety incident or an equipment damage claim rather than a quality metric. A grasp that succeeds at the edge of mechanical stability in a pilot of fifty units can fail consistently at a production volume of five thousand, once object weight or surface friction varies even slightly from the pilot batch. That is the gap between a model that looked ready in evaluation and one that was not.

Building Action Fidelity Into the Evaluation Protocol

This requires frame-level review of execution quality, not just episode-level success labels. Model evaluation services that score action fidelity on dimensions like grasp stability margin and trajectory precision, not just task completion, surface the difference between a model that succeeds reliably and one that succeeds narrowly.

Building an Evaluation Program Around Your Deployment, Not the Leaderboard

The most useful thing you can do before deploying a VLA model is to define your own task taxonomy: the specific objects, environments, instruction phrasings, and failure scenarios your deployment will actually involve. Then evaluate the model against that taxonomy directly, rather than relying on how it ranks on a general benchmark.

This is not a one-time gate before launch. Models get updated, deployment environments evolve, and new task variations show up that your original evaluation set did not anticipate. Data collection and curation services that continuously sample new deployment scenarios into your evaluation set keep the evaluation program honest as the deployment context changes.

Signs Your Current Evaluation Is Not Enough, and Whether to Build or Buy

Not every team is at the same starting point, and it is worth being honest about where you actually are before investing further. A few signs your current evaluation program is not enough: your only performance number comes from a published benchmark or the model provider’s own reported metrics; you have never tested the model against object types, lighting, or instruction phrasings specific to your facility; your evaluation set has not changed since the pilot, even though your deployment environment has; or you are relying on field incident reports, rather than a structured evaluation process, to tell you when something is wrong.

If two or more of these are true, the question becomes whether to build this evaluation capability in-house or bring in a partner to run it. Building in-house makes sense if you already have ML engineers who understand evaluation design, your deployment environment is stable enough that a one-time investment in tooling will keep paying off, and you have the headcount to maintain the evaluation set as conditions change. Buying makes sense if your team’s strength is in the application and the robotics integration rather than in evaluation methodology, if your deployment environment is still evolving and the evaluation set will need frequent updates, or if you need this running before your next deployment milestone and do not have the lead time to build the capability from scratch. Most teams that choose to buy are not outsourcing judgment; they are outsourcing the ongoing labor of keeping an evaluation set current, which is the part that erodes fastest when left to a part-time internal owner.

How Digital Divide Data Can Help

Digital Divide Data supports robotics and physical AI teams building VLA evaluation programs that are grounded in the specific environments and tasks those models will face. For programs designing grounding and action fidelity evaluations, model evaluation services build evaluation frameworks around your deployment task taxonomy, with scoring dimensions that go beyond binary success rate to capture execution quality and failure margins. 

For programs that need labeled ground truth for grounding and planning evaluation, video annotation services provide annotation of object references, spatial relationships, and task phase structure in evaluation footage. For programs that need to keep their evaluation sets current as deployment environments evolve, data collection and curation services continuously source new evaluation scenarios from the field rather than relying on a static benchmark.

If your VLA evaluation program is built around a published benchmark rather than your actual deployment task taxonomy, you will not see the failure modes that matter until they show up in production. Talk to an expert.

Conclusion

A VLA model that looks strong on a published benchmark can still fail in your specific deployment, because the benchmark was never designed to predict performance in your environment. Grounding, planning, and action fidelity are three distinct capabilities that each fail in their own way, and a benchmark score that averages across all three will hide exactly the failure you need to catch before deployment.

The teams that get this right build their own evaluation taxonomy around the objects, environments, and task variations their deployment will actually involve, and they keep updating it as conditions change. What does your current VLA evaluation actually tell you about how the model will behave in your specific environment, not a benchmark’s?

References

Guruprasad, P., Wang, Y., et al. (2025). Benchmarking the generality of vision-language-action models. https://arxiv.org/abs/2512.11315

Li, X., Hsu, K., Gu, J., Pertsch, K., Mees, O., Walke, H. R., Fu, C., Lunawat, I., Sieh, I., Kirmani, S., et al. (2024). Evaluating real-world robot manipulation policies in simulation. arXiv. https://arxiv.org/abs/2405.05941

Zhou, J., Ye, K., Liu, J., Ma, T., Wang, Z., Qiu, R., Lin, K., Zhao, Z., & Liang, J. (2025). Exploring the limits of vision-language-action manipulations in cross-task generalization. arXiv. https://arxiv.org/abs/2505.15660

Frequently Asked Questions

Q1. How is evaluating a VLA model different from evaluating a standard computer vision model?

A vision model is typically evaluated on a single capability, like classification or detection accuracy, against a static test set. A VLA model has to be evaluated across three interacting capabilities at once: whether it understands the instruction, whether it plans the right sequence of actions, and whether it executes those actions with enough physical precision to succeed. A model can be strong in one of these and weak in another, and a single aggregate success rate will not tell you which one is the problem.

Q2. What does an out-of-distribution evaluation set actually look like for a VLA model?

It is a test set built deliberately to differ from the model’s likely training distribution: object types it has not seen paired with familiar ones, lighting and background conditions different from the training environment, and instruction phrasings that vary from the canonical form. The goal is not to make the test unfairly hard. It is to find the boundary of where the model’s competence actually stops, which a test set drawn from the same distribution as the training will not reveal.

Q3. How do you evaluate a model’s ability to recover from a failed step in a multi-step task?

Build evaluation scenarios that deliberately introduce a failure partway through a task: move an object slightly, interrupt the action, or change the environment mid-sequence. Then assess whether the model recognizes that the expected state did not occur and adapts, or whether it continues executing a plan based on its original assumption. This requires reviewing the full episode, not just the outcome, because a model can recover successfully through an inefficient path or fail silently while still producing a result that looks plausible at a glance.

Q4. What is a reasonable success rate to expect from a VLA model before deployment?

There is no single universal threshold, because the right number depends on the cost of failure in your specific task, but rough industry ranges give you a starting anchor. Low-stakes sorting or bin-picking tasks with cheap recovery from a miss are often deployed in the 90 to 95 percent success range, with a human or a simple fallback catching the rest. Tasks involving variable or fragile objects, such as warehouse pick-and-pack with mixed SKUs, generally need to clear 95 to 98 percent before the rework cost stops eating the labor savings. Tasks operating near people, expensive equipment, or in safety-relevant contexts, such as collaborative assembly or surgical-adjacent applications, are typically held to 99 percent or higher, often paired with a hard mechanical or software safety layer rather than relying on the model’s success rate alone. These are starting anchors, not certifications. What matters more than clearing a number is understanding the failure modes behind whatever rate you observe: whether failures are concentrated in specific object types, specific instruction phrasings, or specific task phases. That breakdown tells you whether the gap is fixable with more targeted data or whether it reflects a more fundamental limitation.

How to Evaluate VLA Model for Real-World Deployment: Grounding, Planning, and Action Fidelity Read Post »

AI Evaluation Program

Why Your AI Evaluation Program Is Missing Cultural Failures, and How to Fix It

Kevin Sahotsky

Here’s a pattern I’ve seen more than once. An enterprise buys access to a frontier model, runs it through internal evaluations, and the results look good. Strong accuracy. Coherent outputs. The team gets comfortable. Then the model enters a customer-facing workflow serving users in the Middle East, Southeast Asia, or Sub-Saharan Africa, and something goes wrong. The outputs are technically correct in a narrow sense but contextually off. Users notice.  This is particularly relevant for AI procurement leads, product teams, and enterprise buyers deploying models in global or multilingual markets.

The evaluation wasn’t wrong. It was just evaluating the wrong thing. Standard benchmarks are predominantly designed around Western, English-language contexts. They measure capability on the kinds of inputs those contexts generate. When the deployment context is different, the benchmark stops being a reliable predictor of real-world performance.

Cultural alignment is becoming a first-order evaluation problem for any enterprise deploying AI in global markets. Model evaluation services and low-resource language services are the two capabilities most directly involved in closing the gap between what standard benchmarks measure and what global deployment actually requires.

Key Takeaways

  • Frontier models are trained predominantly on Western, English-language data. This produces systematic gaps in cultural knowledge, values alignment, and contextual reasoning that standard benchmarks do not surface.
  • Cultural failure is not a language problem. A model can be fluent in Arabic or Hindi while still applying Western cultural assumptions to content produced in those languages.
  • Standard benchmarks do not catch cultural misalignment. Evaluation programs that rely on existing leaderboard benchmarks will miss the failure modes that matter most in global deployments.
  • The evaluation gap is measurable. Culturally grounded human evaluation of production-representative inputs is the only reliable way to understand how a model will perform in a specific cultural context before that context reveals the failure.
  • The fix requires both better evaluation data and better training data. Identifying cultural gaps through evaluation and then closing them through targeted data collection are two sides of the same coin.

Why Frontier Models Fail on Culturally Specific Data

Why Your Training Data Is Setting You Up to Fail Globally

Frontier models are trained on large corpora of text drawn primarily from the English-language web and Western institutional sources. This is not a secret. What is underappreciated is how deeply that training distribution shapes the model’s outputs, even when it’s being asked to produce content in other languages or for other cultural contexts. The model’s prior, its default assumptions about what is typical, appropriate, or correct, reflects the distribution it learned from. That prior doesn’t disappear when the model switches languages.

Multilingual Capability Won’t Save You From Cultural Failures

One of the most persistent misunderstandings in enterprise AI procurement is treating multilingual capability as a proxy for cultural competence. A model can generate grammatically correct Arabic text while simultaneously encoding assumptions about gender roles, family structure, or political norms that do not reflect the cultural context of Arabic-speaking users. Fluency is a surface property. Cultural alignment is a deeper one.

The distinction matters operationally because evaluation programs built around language capability will miss the cultural alignment failures that determine whether a deployment succeeds or fails in a global market. Model evaluation services that treat cultural alignment as a distinct evaluation dimension, separate from language fluency, surface the failure modes that language-focused benchmarks hide.

The Long Tail of Cultural Knowledge

Cultural knowledge is not evenly distributed across the training data, and the imbalance is not random. High-resource languages with large web presences are well-represented. Low-resource languages and the cultural knowledge embedded in communities that use them are systematically underrepresented. This creates a long tail of failure modes: the model handles high-frequency cultural contexts adequately but fails on the specific cultural knowledge that matters most to underserved user populations.

For enterprises deploying AI in markets where that long tail is the core use case, not an edge case, this is a significant operational risk. The evaluation frameworks designed for high-resource language contexts will not surface those failures because they were not designed to.

Why Your Current Evaluation Program Is Leaving You Exposed

Benchmark Saturation and Its Limits

The most widely used LLM benchmarks now report near-ceiling performance for frontier models. This is sometimes interpreted as evidence that the cultural alignment problem is being solved. It isn’t. It’s evidence that the benchmarks are no longer measuring the right things. Benchmark saturation means the evaluation has stopped differentiating between models on dimensions that matter for global deployment, not that the underlying cultural gaps have been closed.

Research on culturally grounded benchmarks designed to be more challenging than existing leaderboard tests consistently finds that even the best-performing frontier models fall significantly short of human performance on culturally specific knowledge tasks. The gap is not small. It is the difference between a model that appears capable on a benchmark and a model that is actually capable in the deployment context that the benchmark was supposed to represent.

Static Benchmarks Against Evolving Models

Standard benchmarks are also static. Once published, they become part of the training and evaluation ecosystem, which means models can be optimized against them directly or indirectly. A model that scores well on a published cultural benchmark may have been trained on data that overlaps with or was derived from that benchmark. Benchmark contamination reduces the signal value of any static evaluation set over time.

Production-representative evaluation, drawing samples from the actual inputs the model will receive in a specific deployment context, is the evaluation approach that does not suffer from contamination because it reflects what users are actually doing, not what benchmark designers anticipated. Data collection and curation services that source evaluation data from production-like inputs in the target cultural context produce evaluation sets that benchmark contamination cannot undermine.

The Absence of Local Human Judgment

The other thing standard evaluation misses is local human judgment. Evaluating whether a model’s output is culturally appropriate for a specific context requires evaluators who are embedded in that context. An evaluation program that uses Western-trained evaluators to assess outputs for Middle Eastern or Southeast Asian users will miss the specific cultural failure modes that those users will encounter.

This is not a minor calibration issue. The cultural knowledge required to identify certain failures, in moral reasoning, in representation of contested history, in application of local norms to specific scenarios, is not accessible to evaluators who do not share that cultural background. Building evaluation programs around locally embedded human judges is not optional for global deployments. It is what makes the evaluation valid.

What Evaluation Should Look Like

Start With the Deployment Context, Not the Benchmark

Effective cultural evaluation starts with a clear specification of the deployment context: what cultural communities will use the system, what tasks they will use it for, and what cultural knowledge, values, and norms are relevant to those tasks. The evaluation design follows from that specification, not from the availability of existing benchmarks.

This sounds obvious. It isn’t how most enterprise evaluation programs are actually structured. Most evaluation programs start with the available benchmarks and check the model against them. Starting from the deployment context and then designing the evaluation to match it is a different workflow that produces different results.

Culturally Grounded Human Evaluation

The core of a culturally grounded evaluation program is human evaluation by annotators who are embedded in the target cultural context. Those annotators assess model outputs against culturally specific quality criteria: does this response reflect accurate cultural knowledge, apply appropriate norms for this context, and represent contested topics in a way consistent with local perspectives? Model evaluation services that recruit and calibrate evaluators from the specific cultural communities a model will serve produce evaluation programs that are valid for those communities rather than approximations derived from more accessible evaluator populations.

One-Time Evaluations Are a Risk You Can’t Afford

Cultural alignment is not a static property. Models are updated. Deployment contexts evolve. New use cases emerge. An evaluation program that runs once before launch and then stops will miss the drift that occurs as these changes accumulate. Programs that treat cultural evaluation as a continuous operational discipline, running regular evaluation cycles against production inputs and updating the evaluation set as the deployment context evolves, maintain a valid signal of cultural alignment throughout the model’s production life.

How Digital Divide Data Can Help

Digital Divide Data has operated in Cambodia, Laos, Kenya, and the US since 2001, which means our annotator teams are embedded in the cultural communities that global AI deployments are often trying to serve. That depth of local presence is what makes our evaluation and data collection programs culturally valid rather than culturally approximated. 

For programs building culturally grounded evaluation frameworks, model evaluation services design evaluation suites built around the specific cultural context of the deployment, with locally embedded human evaluators who assess outputs against culturally specific quality criteria. For programs building the training data needed to close identified cultural gaps, data collection and curation services, and low-resource languages services source culturally representative training examples from the communities the model needs to serve.

If your evaluation program isn’t measuring cultural alignment for the contexts where you’re deploying, that’s worth addressing before the market tells you about the gap. Talk to an expert.

Conclusion

Frontier models are capable. They are not culturally neutral. The training data that produces their capabilities also shapes their defaults, their values, and their blind spots in ways that systematic standard benchmarks do not surface. For enterprise deployments serving global user populations, that gap is an operational risk that shows up after launch when it could have been identified and addressed before it.

The evaluation programs that find these gaps early share a common structure: they start from the deployment context rather than the available benchmarks, they rely on locally embedded human judgment rather than evaluator populations that don’t share the target cultural background, and they treat evaluation as a continuous discipline rather than a pre-launch gate. The enterprises building this discipline now are not doing it as a compliance exercise. They are doing it because the first mover in a regional market that gets the cultural experience right is the one that earns user trust before a competitor with a less careful evaluation program gets the chance to lose it. That advantage is hard to claw back once a market has decided which provider understands it and which one does not. What’s the gap between what your current evaluation program is measuring and what your deployment context actually requires?

References

Cao, Y., et al. (2023). Assessing cross-cultural alignment between ChatGPT and human societies: An empirical study. arXiv. https://arxiv.org/abs/2303.17466

Li, Y., et al. (2024). CulturalBench: A robust, diverse, and challenging benchmark on measuring the (lack of) cultural knowledge of LLMs. arXiv. https://arxiv.org/abs/2410.02677

Huang, J., & Yang, K. (2023). Culturally aware natural language inference. In Findings of EMNLP 2023. Association for Computational Linguistics. https://aclanthology.org/2023.findings-emnlp.745

Adilazuarda, M. F., et al. (2024). Towards measuring and modeling “culture” in LLMs: A survey. arXiv. https://arxiv.org/abs/2403.15412

Frequently Asked Questions

Q1. Our vendor says their model is already multilingual. Isn’t that enough?

Because standard benchmarks are predominantly designed around Western, English-language contexts. A model can score at the top of a leaderboard while having significant blind spots in the cultural knowledge, values, and norms of non-Western communities. The benchmark was not designed to surface those blind spots, so it doesn’t. Culturally grounded evaluation designed around the specific deployment context is the tool that surfaces them.

Q2. We already ran our own internal evaluation, and the model passed. Why isn’t that sufficient?

Because the team running that evaluation was very likely evaluating against the same kind of benchmark the model was trained to do well on, and very likely did not include evaluators from the specific cultural communities the deployment will actually serve. An internal evaluation that does not include locally embedded judgment from your target markets is not measuring cultural alignment, even if it produced a passing result. The pass tells you the model is technically functional. It does not tell you whether it is culturally appropriate for the markets you are entering.

Q3. This sounds expensive and slow. Can’t we just fix issues as they come up after launch?

You can, but the cost shows up on the other side of the ledger instead. Fixing a cultural misalignment issue after launch means it has already reached real users, generated support escalations, and possibly damaged a regional partnership or a brand reputation you cannot easily rebuild. A culturally grounded evaluation program run before launch is an upfront cost with a defined scope. A post-launch fix is an unplanned cost with a reputational tail attached. Most enterprises that have been through both prefer to pay for the first.

Q4. Our model provider already re-trains and updates the model regularly. Doesn’t that keep cultural alignment current automatically?

On a continuous cadence, not just before launch. Models are updated, deployment contexts evolve, and new use cases emerge. A one-time pre-launch evaluation misses the drift that accumulates as these changes occur. Programs that run regular evaluation cycles against production-representative inputs maintain a valid signal of cultural alignment throughout the model’s production life.

Why Your AI Evaluation Program Is Missing Cultural Failures, and How to Fix It Read Post »

Data Annotation Services for Regulated Industries

AI Data Annotation Services in Regulated Industries: What Healthcare, Finance, and Legal Teams Need Differently

AI data annotation services in regulated industries differ from general labeling in three concrete ways: the data carries legal liability (PHI, material non-public information, privileged contract terms), the annotators must hold domain credentials and clearances rather than generalist skills, and every label must leave an audit trail that a regulator can inspect. Healthcare adds HIPAA and de-identification, finance adds model-risk governance and disclosure rules, and legal adds privilege protection and clause-level precision. A vendor that meets these requirements treats compliance as part of the pipeline design, not a contract clause added afterward.

The gap between a general annotation workflow and a compliant one is not a matter of degree. Teams in healthcare, finance, and law increasingly find that the constraint on their AI roadmap is the ability to collect and curate sensitive data lawfully and label it with people qualified to make the judgment calls. That is why data annotation services for these verticals are built around credentialing, access control, and traceability before a single label is drawn.

Key Takeaways

  • Labeling data in regulated industries, such as healthcare, finance, and law, is harder than normal labeling because the data itself is protected by law before anyone touches it.
  • In healthcare, patient identifiers must be stripped out or hidden before any labeling begins, and the people doing the work need medical training.
  • In finance, every label has to be documented and traceable so a reviewer can later prove how a model was built.
  • In law, labels are applied to the exact wording of contract clauses, and the work must protect confidential and privileged terms.
  • A trustworthy annotation partner builds privacy, vetted people, and full record-keeping into the process from the start, not as an afterthought.
  • Companies that plan for these rules early can adopt AI safely, while those that add compliance later usually pay for it during a breach or audit. 

What makes data annotation in regulated industries different?

Data annotation is the process of attaching structured labels to raw data so a model can learn from it, and in machine learning, it spans bounding boxes on images, entity tags on text, and preference rankings on model outputs. Data annotation in machine learning follows the same mechanics everywhere, but the inputs in a regulated vertical are governed by law before they ever reach an annotator. In healthcare, that input is protected health information (PHI); in finance, it is material non-public information and customer financial records; in law, it is privileged and confidential contract language.

Three requirements separate regulated annotation from general labeling. First, a compliance overlay (HIPAA, GDPR, SEC, and FINRA rules, SOX) constrains who may see the data and where it may physically reside. Second, annotator credentialing replaces interchangeable crowd labor with vetted specialists, because the labeling decisions require clinical, financial, or legal judgment. Third, an audit trail records who labeled what, when, and under which guideline version, so the dataset itself can serve as evidence during an inspection or model validation.

These constraints raise the cost and complexity of annotation, which is precisely why large-scale data annotation challenges intensify in regulated settings. Throughput targets collide with access restrictions, and quality assurance has to prove not only that a label is correct but that it was produced inside a controlled environment. The rest of this guide works through each vertical and then through the compliance machinery that applies across all three.

What are the annotation requirements for healthcare AI?

Healthcare AI annotation requirements start with removing or protecting the 18 categories of PHI that HIPAA defines, and they extend to the clinical accuracy of the labels themselves. A clinical note carries names, dates, and identifiers alongside the medical content a model needs to learn, so the first task is de-identification, not labeling. Manual de-identification across millions of records is not feasible on its own, which is why teams pair automated PHI detection with human review to catch the residual cases that pattern matching misses.

What is PHI-safe data annotation?

PHI-safe data annotation means the protected identifiers are removed, masked, or tokenized before annotators work with the remaining text, and any residual exposure is governed by a Business Associate Agreement (BAA) and role-based access. Recent work on PHI handling, including the LLM-empowered privacy-protected annotation approach, shows that purpose-built clinical pipelines can detect PHI at materially higher accuracy than general-purpose models while keeping raw identifiers out of the labeling step. The practical standard is consistent tokenization, so the same identifier always maps to the same surrogate, and longitudinal patient linkage survives de-identification.

Beyond privacy, clinical labels have to capture meaning that general NLP ignores. Negation (“no evidence of stroke”), temporality (“prior MI in 2019”), and medication changes all alter the clinical story, and a model trained on annotations that flatten them will give unsafe suggestions. For AI that qualifies as Software as a Medical Device, the dataset, the labeling process, and the performance monitoring must all be documented across the product lifecycle, because that documentation becomes part of the regulatory submission. Reliable clinical annotation, therefore, depends on annotators with medical training and on data quality standards that define model success rather than generic accuracy thresholds.

How do financial services firms use data annotation?

Financial services firms use data annotation to label transactions, classify financial text, and build the labeled corpora behind fraud detection, credit decisioning, and document processing. Sentiment and intent labels on earnings calls or customer messages, entity tags on filings, and category labels on transactions all feed supervised models. Because these models drive lending, trading, and compliance decisions, the labels sit inside a model-risk governance regime that expects documentation, reproducibility, and independent validation.

The supervisory expectation, set out in the Federal Reserve and OCC interagency guidance on model risk management (SR 26-2), is that a firm can explain and defend how a model was built, which includes the data it learned from. That pushes annotation toward strict label taxonomies, recorded inter-annotator agreement, and traceable changes, so a validator can reconstruct how a training label was assigned. Annotating financial documents at volume, while keeping that lineage intact, is closer to AI-powered finance and accounts processing than to open-ended crowd labeling.

Financial text also spans languages, jurisdictions, and regulatory vocabularies, and a label scheme that works for one market often breaks in another. Building consistent multilingual NLP datasets for finance requires annotators who understand both the language and the local disclosure rules, because the same phrase can be neutral in one filing regime and material in another. Disclosure-sensitive material, including anything touching material non-public information, has to be walled off so annotation does not itself create a selective-disclosure or insider-information problem.

How is legal document annotation different from general NLP annotation?

Legal document annotation differs from general NLP annotation because the unit of meaning is the clause, the labels encode legal consequence, and the source text is often privileged. Tagging a contract is not topic classification; it is identifying which span creates an obligation, a prohibition, a renewal term, or an indemnity, and those distinctions require legal reading. The expert-annotated Contract Understanding Atticus Dataset illustrates the bar; and its annotations were produced by legal experts identifying 41 categories of clauses that lawyers actually look for, and even strong models reach only nascent performance against it.

Three properties make legal annotation distinct from general text work:

  • Clause-level precision: Labels attach to exact substrings that carry legal effect, so partial or approximate spans defeat the purpose of the dataset.
  • Expert credentialing: In datasets like CUAD, annotation was done by law students with 70 to 100 hours of specialized training under attorney supervision, not by generalist labelers.
  • Privilege and confidentiality: Contracts contain confidential and often privileged terms, so the annotation environment has to prevent disclosure that could waive privilege or breach a confidentiality undertaking.

Because legal labels feed retrieval and review systems where a missed clause has direct consequences, the review architecture matters as much as the individual label. A multi-layered data annotation pipeline with senior legal review on top of first-pass labeling is what keeps clause tagging defensible, and benchmarks such as the BRIDGE evaluation of clinical and professional text reinforce that expert-built ground truth, not crowd consensus, is the reliable reference for high-stakes domains.

What compliance standards must a data annotation company meet for regulated industries?

A data annotation company serving regulated clients must meet the standard its client is bound by, because under frameworks like HIPAA, the client remains legally responsible for what its vendors do. That makes vendor compliance a contractual and architectural question, not a checkbox. The recurring requirements across healthcare, finance, and legal work are consistent enough to list.

Signed agreements that allocate responsibility: A BAA for PHI and detailed SLAs that specify data use, breach-reporting timelines, and deletion obligations at contract termination.

Independent security attestations: Certifications such as SOC 2 Type II or ISO 27001, encryption in transit and at rest, and role-based access so only credentialed annotators reach sensitive data.

Data residency and controlled environments: The ability to keep data in a required jurisdiction and to process it inside a secure environment rather than moving it to an open labeling platform.

Audit trails and data lineage: A record of who labeled what, under which guideline version, so the dataset can demonstrate provenance to a regulator or an internal validation team.

Audit trails deserve emphasis because they are where regulated annotation most often falls short. Modern de-identification and labeling workflows increasingly pair masking with automated traceability, so compliance is built into the data lifecycle instead of reconstructed after the fact. The same logic extends to model evaluation that tests for accuracy, bias, and safety to produce the documented evidence a regulated model needs before deployment, closing the loop between how the data was labeled and how the resulting model behaves.

How Digital Divide Data Can Help

Digital Divide Data (DDD) builds annotation programs for regulated AI around the constraints described above rather than retrofitting them. For healthcare, that means PHI-aware data collection and curation with de-identification, BAAs, role-based access, and audit logging built into the workflow, so clinical text reaches annotators only in a controlled, compliant form. Annotators are credentialed for the domain, and quality assurance is measured with inter-annotator agreement against expert-defined guidelines, not generic accuracy alone.

For finance and legal work, DDD applies the same discipline through multimodal data annotation services and multilingual NLP capabilities, with strict label taxonomies, recorded label lineage, and senior review layered over first-pass annotation. Financial document and transaction labeling runs with the controls expected under model-risk governance, and legal clause tagging is handled in environments designed to protect confidentiality and privilege. Where a model must be defended to a regulator, DDD’s model evaluation services supply the accuracy, bias, and safety evidence that connects labeled data to measured model behavior.

The common thread is that compliance, credentialing, and traceability are part of the pipeline design from the start, which is what lets regulated teams scale annotation without scaling their exposure.

Build annotation programs that stand up to regulatory scrutiny. Talk to an Expert!

Conclusion

Regulated annotation is a discipline of evidence as much as accuracy. The label has to be correct, the person who made it has to be qualified, and the record has to prove both. Organizations that treat these requirements as pipeline design decisions can move PHI, financial records, and contracts into AI systems lawfully and at scale. Organizations that bolt compliance after the fact tend to discover the gap during a breach, a validation review, or a privilege dispute, when it is most expensive to fix.

The verticals will keep diverging as state AI laws, updated HIPAA security rules, and model-risk expectations tighten, so the annotation partner’s job is to absorb that complexity rather than pass it to the client. 

References

Hendrycks, D., Burns, C., Chen, A., & Ball, S. (2021). CUAD: An Expert-Annotated NLP Dataset for Legal Contract Review. arXiv preprint arXiv:2103.06268. https://arxiv.org/abs/2103.06268

Wu, J., Gu, B., Zhou, R., Xie, K., Snyder, D., Jiang, Y., Carducci, V., Wyss, R., Desai, R. J., Alsentzer, E., Celi, L. A., Rodman, A., Schneeweiss, S., Chen, J. H., Romero-Brufau, S., Lin, K. J., & Yang, J. (2025). BRIDGE: Benchmarking Large Language Models for Understanding Real-world Clinical Practice Text. arXiv preprint arXiv:2504.19467. https://arxiv.org/pdf/2504.19467

Frequently Asked Questions

What are the annotation requirements for healthcare AI?

Healthcare AI annotation starts with de-identifying the HIPAA categories of protected health information before labeling, then requires clinically trained annotators who can capture meaning like negation, timing, and medication changes. If the AI is a medical device, the dataset and labeling process also need lifecycle documentation for regulatory submission.

What is PHI-safe data annotation?

It means the protected identifiers in patient data are removed, masked, or consistently tokenized before annotators see the text, with any residual access governed by a Business Associate Agreement and role-based controls. The goal is to let people label the clinical content without exposing who the patient is.

How do financial services firms use data annotation?

They label transactions, classify financial text, and tag entities in filings to train models for fraud detection, credit decisions, and document processing. Because those models are governed by model-risk rules, the labels need strict taxonomies, recorded inter-annotator agreement, and traceable changes so a validator can reconstruct how each label was assigned.

How is legal document annotation different from general NLP annotation?

Legal annotation works at the clause level, attaching labels to the exact spans that create obligations, prohibitions, or other legal effects, and it usually needs legally trained annotators rather than generalists. The contracts are often confidential or privileged, so the work has to happen in an environment that prevents disclosure.

AI Data Annotation Services in Regulated Industries: What Healthcare, Finance, and Legal Teams Need Differently Read Post »

AI training data providers

An Enterprise Framework for Evaluating AI Training Data Providers

Selecting an AI training dataset provider requires evaluating five dimensions: workforce model and annotator expertise, data security and compliance posture (SOC 2, ISO 27001), quality SLAs backed by measurable inter-annotator agreement (IAA) and defect-rate commitments, AI-assisted throughput with human oversight, and, of course, commercial flexibility. 

Most failed AI programs we see are not model failures. They are data failures, sourced from a provider that looked capable at the proposal stage but couldn’t hold quality or volume at production scale. The decision of which AI training data collection and curation provider to work with is one of the highest-leverage procurement decisions an AI team makes. 

Key Takeaways 

  • Selecting an AI training dataset provider is a five-dimensional decision: workforce model, security posture (SOC 2 Type II, ISO 27001), quality SLAs grounded in IAA scores, AI-assisted throughput with human oversight, and commercial flexibility.
  • Generic vendor scoring usually misses the failure modes (annotator quality drift, inconsistent IAA, and contractual structures) that actually break AI data programs.
  • A quoted accuracy of 99.5% can mask production-grade failures unless the provider defines how it’s measured, what QA sampling method is used, and what IAA scores look like by task type.
  • Providers that apply the same automation ratio across all task types signal immature tooling.
  • Use the scorecard in this framework as a starting point. Adapt the weights and thresholds to your program’s specific risk profile before comparing providers.

Who is an AI Training Data Provider?

An AI training data provider, also called a data labeling vendor, annotation partner, or AI data services company, is an organization that produces labeled, curated, or structured datasets used to train, fine-tune, or evaluate machine learning models. The scope varies widely. Some providers focus exclusively on annotation (bounding boxes, classification, NER, etc.). Others offer end-to-end services: data collection, curation, annotation, quality assurance, and AI model evaluation.

The market includes offshore-only crowdsourcing platforms, technology-first tool vendors that rely on gig workers, and full-service providers with managed expert workforces. These are structurally different products, even when they present similar service catalogs. Understanding which model a vendor operates is the first procurement decision.

The right provider depends on the individual AI program’s modality (text, vision, audio, multimodal), annotation complexity (simple classification vs. complex reasoning and preference tasks), volume requirements, and security constraints. A provider that works well for consumer-grade image classification frequently fails on high-precision ADAS sensor fusion or RLHF preference data for enterprise LLMs.

Why Standard Enterprises Vendor Scoring Falls Short for Data Providers?

Generic vendor evaluation rubrics, such as financial stability, past clients, certifications, and delivery timelines, do not capture what actually determines success in an AI data program. A vendor can hold ISO 27001 and still produce annotations with 15% defect rates under volume pressure. A provider can quote 99% accuracy and define it against a metric that masks the failures that matter to your model.

The risks specific to AI data vendors include annotator quality drift under surge conditions, inconsistent inter-annotator agreement (IAA) across task types, security gaps in data handling at the worker level (not just the enterprise perimeter), and contractual structures that do not create incentives for sustained accuracy. As data collection and curation at scale require careful pipeline design from the beginning, evaluating providers on these specific axes is essential before the program starts.

This framework structures evaluation across the five most important dimensions. Each dimension has a set of qualifying questions, red flags, and a weighted scoring range for use in a comparative scorecard.

Dimension 1: Workforce Model and Annotator Expertise

The quality of annotated data is a direct function of the annotators producing it. The workforce model describes how a provider recruits, trains, retains, and manages the people doing the annotation work. There are three common models: managed in-house workforce, managed workforce plus gig overflow, and crowdsourcing platforms.

In-house managed workforces, typically located in dedicated delivery centers, tend to show more consistent quality on complex or specialized tasks. Gig and crowdsourcing models offer surge capacity but frequently struggle with complex annotation schemas, especially those requiring domain expertise, linguistic judgment, or nuanced preference rankings.

Key qualification questions:

  • What percentage of annotators are permanent employees vs. contract or gig workers?
  • How are annotators trained for new task types, and how is training quality validated?
  • How does the provider handle annotator churn and knowledge transfer for long-running programs?
  • Does the provider offer domain-expert annotators for specialized verticals (legal, medical, ADAS, coding)?

Red flags:

  • Inability to describe onboarding time and annotator certification criteria.
  • No structured process for calibration sessions or IAA measurement by task type.
  • Heavy reliance on third-party platforms that they do not control for quality assurance.

Dimension 2: Security, Compliance, and Data Governance

Enterprise AI programs regularly involve proprietary data, personally identifiable information (PII), or data subject to export controls. Security evaluation must go beyond checking whether a vendor holds a certification. The critical question is whether their controls extend to the annotation workspace and individual worker level.

SOC 2 Type II (covering Security, Availability, Confidentiality) and ISO 27001 are the baseline standards. SOC 2 Type II requires ongoing auditing, making it a stronger signal than Type I. For programs involving regulated data, confirm that the provider can sign a Data Processing Agreement (DPA) and that their subprocessor list does not introduce jurisdictional exposure.

Key qualification questions:

  • Does the provider hold SOC 2 Type II certification? What audit period does it cover?
  • Is ISO 27001 certified for the specific delivery centers handling your work?
  • What endpoint controls exist at the annotator workstation level (screen capture restrictions, USB blocking, no-download policies)?
  • Can the provider support air-gapped or on-premise annotation environments for high-sensitivity programs?
  • Who holds data processing agreements, and what does the subprocessor chain look like?

Red flags:

  • SOC 2 Type I only, or a certification that is more than 12 months old and not renewed.
  • Annotators using personal devices or personal cloud storage in the workflow.
  • Vague answers about where data resides during annotation and how deletion is confirmed post-delivery.

Dimension 3: Quality SLAs

Quality SLAs are the most frequently misrepresented dimension in AI data vendor proposals. A quoted accuracy of 99.5% can mean almost anything, depending on how the denominator is defined, how defects are sampled, and whether the metric applies to initial submission or post-QA output.

As detailed in the analysis of what 99.5% annotation accuracy actually means in production, the gap between headline accuracy and production-grade reliability is frequently significant. Precision, recall, and IAA scores by task type give a more reliable picture than aggregate accuracy alone. Inter-annotator agreement (Cohen’s Kappa or Fleiss’ Kappa, depending on annotator count) measures whether independent annotators reach consistent conclusions for label reliability.

Key qualification questions:

  • How is accuracy defined, initial submission or post-review final deliverable?
  • What IAA metric does the provider track, and what Kappa scores do they target and report?
  • How is QA sampling performed: random sampling, stratified by annotator, or full review?
  • What are the SLA remedies when accuracy falls below the contracted threshold?
  • Can the provider share historical accuracy and defect-rate data from comparable programs?

Red flags:

  • Accuracy claims with no definition of the measurement methodology.
  • No IAA tracking, or IAA not reported separately by task type.

Dimension 4: AI-Assisted Throughput and Human Oversight Balance

Most credible providers now use AI-assisted annotation for pre-labeling, active learning loops, and model-in-the-loop QA to improve throughput. The question for buyers is not whether AI assistance is used, but whether human oversight is structurally embedded in the workflow at the right points.

The decision of when to use human-in-the-loop vs. full automation for gen AI is task-dependent. For straightforward classification tasks, high automation ratios are appropriate. For complex reasoning, preference annotation, edge-case ADAS annotation, or safety-critical data, human oversight must dominate. Providers that apply the same automation ratio across all task types are a signal of immature tooling.

Evaluate whether AI-assisted throughput translates to faster delivery at maintained quality, or faster delivery at degraded quality that is partially masked by automated QA. Ask for throughput and accuracy data from programs that underwent AI-assisted workflows, not just raw throughput numbers.

Key qualification questions:

  • What AI-assisted tooling is used, and is it proprietary or third-party?
  • At what stages does human review occur in an AI-assisted workflow?
  • How does the provider calibrate automation ratios by task complexity and risk level?
  • How does throughput scale under surge conditions without sacrificing quality SLAs?

Dimension 5: Commercial Flexibility and Program Scalability

AI data programs are rarely steady-state. They scale up during model development cycles, contract during evaluation phases, and frequently pivot in task type as model requirements evolve. A provider whose commercial model requires long fixed-term commitments, minimum volume thresholds, or rigid scope definitions will create friction as your program changes.

Pricing models largely vary for per-unit (per annotation or per task), per-hour (for managed teams), milestone-based (for fixed-scope projects), or hybrid. Per-unit pricing is easy to compare but incentivizes speed over quality unless paired with strong SLA penalties. Per-hour managed team models align incentives better for complex, long-running programs. Understand which model applies and what the ramp, scaling, and wind-down provisions look like.

Key qualification questions:

  • What is the minimum engagement size, and what are the ramp timeline commitments?
  • How are scope changes handled contractually, in the change order process, timeline, and pricing impact?
  • What are the provisions for scaling up rapidly (within 2–4 weeks) to 2x or 3x volume?
  • Does the provider support pilot programs before a full contract commitment?
  • What is the data portability provision at contract end?

The Provider Evaluation Scorecard

Use this scorecard to score providers from 1 (poor) to 5 (excellent) per criterion. Multiply by the weight to get a weighted score. The maximum total score is 100.

Dimension Primary Criterion Weight Key Performance Indicator
Workforce Model Annotator tenure, training, and domain expertise coverage 25% % permanent staff; onboarding time per task type; IAA by workforce segment
Security & Compliance SOC 2 Type II, ISO 27001, DPA capability, endpoint controls 20% Certification recency; air-gap option; subprocessor transparency
Quality SLA IAA scores, defect rate, QA methodology, SLA remedies 25% Cohen’s Kappa ≥0.80 on complex tasks; defect rate ≤1%; financial SLA penalties
AI-Assisted Throughput Human-in-the-loop ratio by task type; automation calibration 15% Throughput/quality parity data; automation ratio by complexity tier
Commercial Flexibility Pricing model, ramp provisions, pilot availability, portability 15% Pilot program availability; 2x scale-up timeline; data portability clause

Providers scoring below 60/100 present material delivery risk at scale. Providers scoring 60–74 may be viable for lower-complexity programs with enhanced oversight. Providers scoring 75+ are suitable for enterprise-grade AI data programs with appropriate contractual protections in place.

How Digital Divide Data Can Help

DDD’s end-to-end data collection and curation services are built around a managed in-house workforce operating from dedicated delivery centers, unlike a crowdsourcing platform. Annotators are permanent employees trained to domain-specific certification standards before touching production data. This workforce model is deliberately designed to hold quality at scale, not just at pilot volume.

On the quality side, DDD’s model evaluation services include IAA measurement, defect-rate tracking, and structured QA sampling as standard program components. For programs involving human preference annotation, DDD’s RLHF and human preference optimization workflows embed expert human review at every stage of the preference ranking pipeline, ensuring that automation assists rather than replaces the human judgment that RLHF data requires.

DDD holds SOC 2 Type II certification and ISO 27001 accreditation, with endpoint controls at the annotator workstation level. The data pipeline infrastructure supports secure data handling, access-controlled annotation environments, and structured delivery workflows. Commercial engagement models range from pilot projects to full-scale multi-year programs, with ramp provisions and scope flexibility built into standard agreements.

Evaluate providers correctly, then build a data program that holds at scale. Talk to an Expert!

Conclusion

Evaluating an AI training dataset provider on generic vendor criteria produces generic results. The five dimensions in this framework, workforce model, security posture, quality SLA methodology, AI-assisted throughput, and commercial flexibility, address the specific failure modes that cause AI data programs to underperform. Scored consistently against a common rubric, they give procurement and AI program leads a defensible, comparable basis for vendor selection.

Organizations that work through a structured evaluation before signing tend to enter vendor relationships with aligned expectations, enforceable quality standards, and a shared definition of what “done” means for their data. Those who skip it typically find the gaps mid-program, after ramp costs are sunk, timelines are committed, and switching providers is no longer a real option. The cost of a rigorous evaluation upfront is measured in days. The cost of skipping it is measured in quarters.

References

Northcutt, C. G., Athalye, A., & Mueller, J. (2021). Pervasive Label Errors in Test Sets Destabilize Machine Learning Benchmarks. Proceedings of the 35th Conference on Neural Information Processing Systems (NeurIPS). https://arxiv.org/abs/2103.14749 

Ziegler, D. M., Stiennon, N., Wu, J., Brown, T. B., Radford, A., Amodei, D., Christiano, P., & Irving, G. (2020). Fine-Tuning Language Models from Human Preferences. arXiv preprint. https://arxiv.org/abs/1909.08593 

Paullada, A., Raji, I. D., Bender, E. M., Denton, E., & Hanna, A. (2021). Data and its (Dis)contents: A Survey of Dataset Development and Use in Machine Learning Research. Patterns, 2(11). https://arxiv.org/abs/2012.05345 

Frequently Asked Questions

How do I evaluate and select an AI training data provider?

Evaluate providers across five structured dimensions: workforce model (permanent vs. gig), security certifications (SOC 2 Type II, ISO 27001), quality SLA methodology (IAA scores, defect rates, QA sampling), AI-assisted throughput with human oversight ratios, and commercial flexibility, including pilot availability. 

What is a reasonable inter-annotator agreement (IAA) score to require from a provider?

For complex annotation tasks like preference ranking, reasoning annotation, and ADAS sensor fusion, a Cohen’s Kappa of 0.80 or above is a reliable threshold. For straightforward classification, 0.85+ is achievable. Ask providers to share historical Kappa scores broken out by task type, not as an aggregate figure.

What security certifications should an AI data vendor have for enterprise programs?

SOC 2 Type II and ISO 27001 are the baseline. SOC 2 Type II is stronger than Type I because it covers a continuous audit period, not a point-in-time assessment. For programs handling regulated or sensitive data, also confirm endpoint controls at the annotator level and the provider’s ability to sign a Data Processing Agreement.

Why does a per-unit pricing model create quality risks in annotation programs?

Per-unit pricing creates a financial incentive to maximize throughput, which can encourage annotators to prioritize speed over accuracy. This is manageable with strong SLA penalties tied to defect rates and IAA scores, but without those contractual levers, per-unit models frequently produce quality degradation under volume pressure.

An Enterprise Framework for Evaluating AI Training Data Providers Read Post »

Scroll to Top