Celebrating 25 years of DDD's Excellence and Social Impact.

Author name: udit khanna

Udit Khanna leads the delivery of scalable AI and data solutions at Digital Divide Data, with a deep specialization in Physical AI. With a background in presales, solutioning, and customer success, he brings a mix of technical depth and business fluency, helping global enterprises move their AI projects from prototype to real-world deployment without losing momentum.

Avatar of udit khanna
A Step-by-Step Guide to Building AI DataOps

How to Build an AI Data Operations Function: A Guided Framework

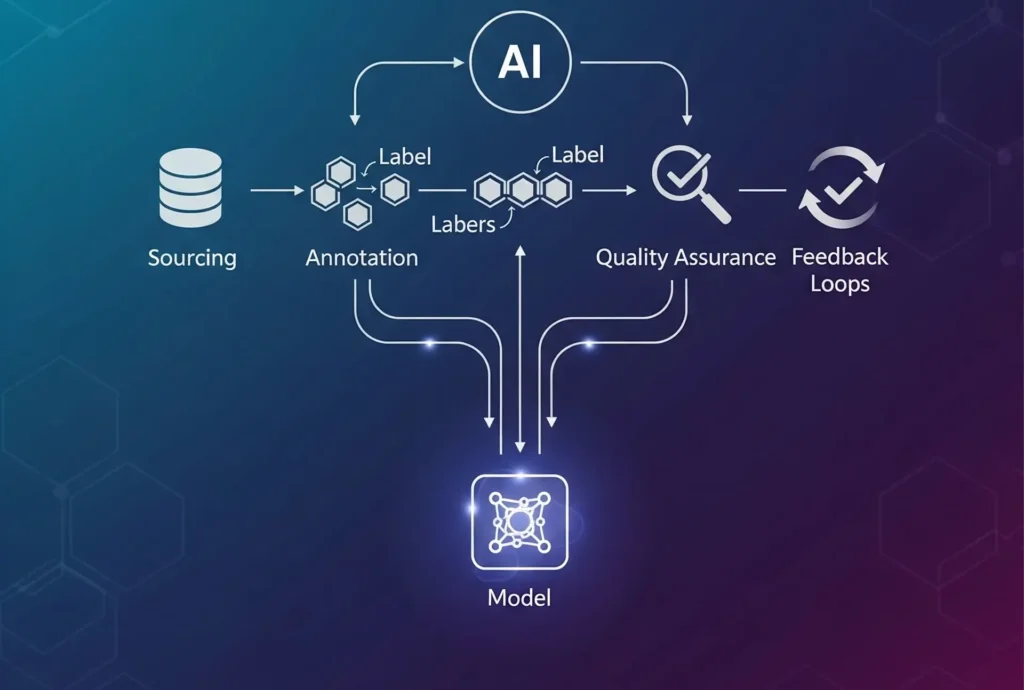
Building an AI data operations services function means standing up a repeatable system that moves training and evaluation data from sourcing through annotation, quality assurance, and back into the model, continuously and at scale. The implementation sequence is consistent; assign a single accountable owner, define the three operating layers (acquisition, annotation, quality and feedback), select tooling around dataset versioning and lineage, automate the annotation pipeline where automation is reliable, and track KPIs that tie data work to model behavior. Most programs fail not because of weak models but because this actual operating structure is missing.

The pressure to formalize this function is measurable. A 2025 S&P Global survey of more than 1,000 enterprises found that 42% of companies abandoned most of their AI initiatives that year, up from 17% the prior year, and the organizations that succeeded were the ones that redesigned their end-to-end workflows rather than swapping models. A standing AI data operations function is what that redesign looks like in practice. It is the difference between a one-time labeled dataset and a persistent data supply chain. Strong data collection and curation services feed the front of that chain, while reliable AI data pipeline infrastructure carries data through it without manual rework at every handoff.

Key Takeaways 

  • AI data operations is the system that keeps the right data flowing to your models continuously, not just once at the start of a project.
  • Start by putting one person clearly in charge, someone who can look at a model failure and trace it back to a data problem they’re allowed to fix.
  • Set up the work in three clear stages; getting the data, labeling it, and checking quality while feeding lessons back into the process.
  • Automate the easy, repetitive parts, but keep people involved in the tricky or high-stakes cases instead of automating everything.
  • Track whether your data work is actually improving the model, not just how fast you’re labeling things.
  • The companies that succeed, treat data as an ongoing supply they manage, while the ones that fail keep reacting to problems after they appear.

What is an AI data operations function and why does it need its own structure?

AI data operations, often shortened to AI DataOps, is the operating model, team structure, tooling conventions, and governance that manage the continuous flow of training and evaluation data through an AI program. It borrows the discipline of DevOps, automation, version control, testing, and continuous delivery, and applies it to data work rather than code. The function spans the full lifecycle, so continuous model evaluation sits at one end and human preference optimization workflows feed back into it. The goal is simple to state and hard to sustain; deliver the right dataset, with known quality, to every training and evaluation run.

It needs its own structure because annotation alone does not scale into reliable model behavior. Annotation is one layer of the system. Around it sits sourcing, quality measurement, dataset versioning, and the feedback path that turns evaluation findings into specific data fixes. When those surrounding parts are informal, scale amplifies whatever inconsistency already exists. A small team with vague guidelines produces a manageable amount of noise, while a large one produces noise faster than anyone can correct it.

The distinction matters for planning. A proof-of-concept can run on a single curated dataset and an informal labeling group. A production program that requires continuous fine-tuning, preference optimization, and safety evaluation needs a persistent data supply chain instead. For a stronger understanding of the conceptual fundamentals behind this AI data operating model, it is important to first look at the core layers, ownership structure, and accountability questions that define AI data operations.

How do I set up an AI data operations function step by step?

Setting up the function is a sequence, not a single hire or a tool purchase. The order matters because each step depends on the one before it. Standing up tooling before assigning an owner, for example, produces a stack that nobody is accountable for. The following sequence works for teams moving from pilot to production.

  • Assign a single accountable owner: Name one person, usually the AI program lead or a Head of AI Data, who can trace a model failure to a specific data problem and authorize the work to fix it. This accountability role must sit inside the organization even when execution is outsourced.
  • Define the three operating layers: Separate acquisition and sourcing, annotation and labeling, and quality assurance with feedback integration. Each layer has its own inputs, outputs, and quality checks, so treating them as one blurred process is where most early programs lose traceability.
  • Establish a sourcing strategy before labeling: Decide what data you need, where it comes from, and how representativeness is verified. A deliberate data collection strategy for AI training prevents the common failure of labeling large volumes of data that do not reflect the target distribution.
  • Select tooling around versioning and lineage: Pick orchestration, annotation, and observability tools that can track which dataset version fed which training run. Lineage is the feature that makes everything downstream debuggable.
  • Automate the annotation pipeline where automation is reliable: Use model-assisted pre-labeling and automated checks for the predictable cases, and route ambiguous or safety-critical cases to human review.
  • Close the feedback loop with evaluation: Wire evaluation findings back into data remediation so that a regression triggers a targeted dataset fix rather than a vague request for more labels.

This ordering reflects a finding that holds across the research. McKinsey’s 2025 State of AI survey reports that organizations seeing real bottom-line impact are far more likely to have fundamentally redesigned their workflows rather than bolting AI onto existing processes. An AI data operations function is workflow redesign applied to the data layer specifically.

What roles belong on an AI data operations team?

The team is cross-functional, but a few roles carry the function. The most underrated of them is the accountable owner described above, because without it the team stays reactive. The remaining roles divide cleanly between building the pipeline and producing the data that flows through it. Data engineering has become central enough that successful AI enterprises treat data engineering as a core AI competency rather than a supporting function.

  • AI data operations lead (accountable owner): Translates model failures into data remediation actions and owns the build-versus-buy decision.
  • Data / DataOps engineer: Builds and maintains pipeline infrastructure, automation, lineage tracking, and the templates other contributors follow.
  • Annotation lead and quality lead: Own annotation guidelines, taxonomy decisions, and inter-annotator agreement targets.
  • Annotation workforce (internal or partner): Produces the labels, ideally with continuous rather than burst capacity.
  • Evaluation consumer: The model training and evaluation team that uses the data and feeds findings back into it.

Two organizational patterns are common, and choosing between them early avoids rework. In a central platform model, one team builds shared tooling and standards while domain teams own their pipelines on that foundation. In an embedded model, data operations specialists sit inside each domain and keep consistency through shared practice. Teradata’s analysis of DataOps team structures describes both patterns and the tradeoff between centralized control and domain proximity.

What tools support an AI data operations function?

Tooling should be selected by capability category, not by brand. The function needs four categories working together, and the connective tissue across all of them is dataset versioning and lineage. Without lineage, a quality problem becomes a guessing exercise instead of a lookup.

  • Orchestration: Schedules jobs, manages dependencies between pipeline steps, retries failures, and triggers downstream work automatically.
  • Annotation and labeling platforms: Support the data modalities you work in, model-assisted pre-labeling, and reviewer workflows.
  • Observability and quality monitoring: Track pipeline health, schema changes, and label quality, and surface anomalies before they reach a training run.
  • Versioning and lineage: Record which dataset version, sourced how and labeled by whom, fed each fine-tuning or evaluation job.

For multimodal programs spanning text, image, video, and audio, the annotation platform decision is heavier because each modality carries its own tooling and quality conventions. The broader AI data pipeline layer is where orchestration and lineage are operationalized as delivered infrastructure rather than a stack you assemble alone.

How do I automate AI data and annotation pipelines?

Automation in AI data operations is not the same as full automation. The aim is zero-touch operation for the standard, predictable cases and fast, informed human intervention for the exceptions. Applied to annotation specifically, that means automating the parts that are reliable and reserving human judgment for the parts that are not. The strength of a multi-layered annotation pipeline lies in how well it combines automated stages with human judgment while maintaining quality, consistency, and control.

A practical automation sequence looks like this. First, automate ingestion and validation so that incoming data is checked against schema and quality rules at the door, which prevents broken pipelines downstream. Second, apply model-assisted pre-labeling so annotators correct machine output rather than starting from scratch, which raises throughput without raising error rates if review is enforced. Third, automate quality testing so that label distributions, agreement scores, and edge-case coverage are monitored continuously instead of audited occasionally.

The boundary of automation is the point worth getting right. Predictable, high-volume cases are good automation candidates, while ambiguous, rare, or safety-critical cases should route to human reviewers by design. Automating those amplifies error instead of removing it, which is why the strongest pipelines treat human-in-the-loop review as a permanent design feature, not a temporary crutch to be removed once volume grows.

How should quality governance and vendor integration work?

Quality governance is what keeps the function honest as it scales. Three practices separate mature programs from those stuck in pilot mode, and none of them are complicated in principle. Every dataset delivered to a training run is versioned with clear lineage from source through annotation. When a model regresses, the team can isolate which dataset version and which annotation cohort were involved without losing time. And evaluation findings drive data remediation as a standing practice rather than an occasional cleanup.

Quality targets need to be concrete rather than aspirational. Inter-annotator agreement, edge-case coverage, and a defined accuracy threshold give the function something to measure against. However, a headline number like 99.5% accuracy can be misleading without the right context. In production, data annotation accuracy, depends on the denominator being measured, the types of errors being counted, and how those errors affect downstream model performance.

Vendor integration is partly a governance decision. The build-versus-buy-versus-partner question is really about which capabilities the internal accountability structure must own and where external execution capacity makes more sense. The accountable owner stays internal in every pattern. Execution work such as sourcing, labeling, and quality assurance can be partnered, provided the partner plugs into the same lineage and quality standards rather than running a parallel, opaque process. The integration pattern that works treats a partner as an extension of the pipeline, with shared versioning, shared quality definitions, and shared visibility into agreement metrics.

What KPIs should I track for AI data operations?

KPIs for AI data operations should connect data work to model behavior, not just measure labeling speed. Throughput matters, but a fast pipeline producing inconsistent labels is a faster route to a failed model. Track a small, balanced set across quality, flow, and impact.

  • Inter-annotator agreement: The consistency of labels across annotators, the leading indicator of dataset reliability.
  • Annotation accuracy against gold standard: Measured on a held-out, expert-labeled set with a clear error definition.
  • Edge-case and distribution coverage: How well the dataset represents the target distribution, including rare but important cases.
  • Dataset lineage completeness: The share of training datasets with full, traceable provenance from source to training run.
  • Cycle time and rework rate: How long data takes to move through the pipeline and how often it must be redone.
  • Evaluation-to-remediation time: How quickly an evaluation finding becomes a shipped data fix, the clearest signal that the feedback loop is closed.

The last metric is the one that distinguishes a real operating function from a labeling vendor relationship. A program that can measure how fast a model failure turns into a corrected dataset has the feedback loop working. A program that cannot is still treating data as a one-time input rather than a continuously managed supply.

How Digital Divide Data Can Help

Digital Divide Data operates the execution layers of AI data operations as managed services, which lets the internal accountability owner stay focused on tracing model failures to data fixes. On the sourcing side, DDD’s data collection and curation services build representative, AI-ready datasets rather than large volumes of poorly targeted data. For labeling across text, image, video, and audio, DDD’s multimodal data annotation services bring inter-annotator agreement discipline and reviewer workflows to each modality’s specific conventions.

On the feedback side, DDD’s model evaluation services produce the findings that drive targeted data remediation, closing the loop between how a model behaves and what data work happens next. Preference data work, including RLHF and DPO optimization, is run with the same versioning and quality standards as the rest of the pipeline, so a partner becomes an extension of your operating model rather than a parallel process you have to reconcile.

The integration pattern is deliberate. DDD plugs into shared dataset lineage and shared quality definitions, so visibility into agreement metrics and dataset provenance stays with your team. That is what makes the build-versus-buy-versus-partner decision a question of capacity rather than control.

Stand up an AI data operations function that actually closes the gap between pilots and production. Talk to an Expert!

Conclusion

An AI data operations function is the operating system for a production AI program. The implementation sequence is consistent and unglamorous: name an accountable owner, separate the three layers, source deliberately, version everything, automate the reliable parts, and route the hard cases to people. The organizations that treat data as a continuously managed supply chain are the ones moving models from pilot to production, while the organizations still labeling in bursts and reacting to regressions are well represented in the share of AI initiatives quietly abandoned each year.

The gap between those two groups is not model sophistication. It is whether a model failure can be traced to a dataset version and fixed on purpose, or whether it triggers another round of guessing. Building the function correctly is what makes that traceability routine. 

References

S&P Global Market Intelligence. (2025). AI experiences rapid adoption, but with mixed outcomes: Highlights from VotE: AI & Machine Learning. https://www.spglobal.com/market-intelligence/en/news-insights/research/ai-experiences-rapid-adoption-but-with-mixed-outcomes-highlights-from-vote-ai-machine-learning

McKinsey & Company, QuantumBlack. (2025). The state of AI: Global Survey 2025. https://www.mckinsey.com/capabilities/quantumblack/our-insights/the-state-of-ai

Frequently Asked Questions

How do I set up an AI data operations function?

Start by naming one accountable owner who can trace a model failure to a specific data problem and authorize the fix. Then separate the three layers, sourcing, annotation, and quality with feedback, set up tooling around dataset versioning and lineage, and automate only the parts that are reliable. The order matters because each step depends on the one before it.

What roles are in an AI data operations team?

The core roles are an accountable data operations lead, a data or DataOps engineer who builds the pipeline, an annotation and quality lead who owns guidelines and agreement targets, the annotation workforce, and the evaluation team that consumes the data and feeds findings back. The accountable owner is the role most often missing, and it should stay internal even when labeling is outsourced.

What tools support AI data operations?

You need four tool categories working together: orchestration, annotation and labeling platforms, observability and quality monitoring, and versioning with lineage. Lineage is the connective feature, because it lets you trace which dataset version fed which training run when something goes wrong.

What KPIs should I track for AI data operations?

Track a balanced set across quality, flow, and impact including inter-annotator agreement, annotation accuracy against a gold standard, edge-case and distribution coverage, dataset lineage completeness, cycle time and rework rate, and evaluation-to-remediation time. The last one matters most, because it shows whether your feedback loop from model behavior back to data work is actually closed.
How to Build an AI Data Operations Function: A Guided Framework Read Post »
AI Data Operations vs. MLOps: Why Production AI Fails Without Both

AI Data Operations vs. MLOps: Key Differences, Use Cases, and Why Both Matter for Production AI

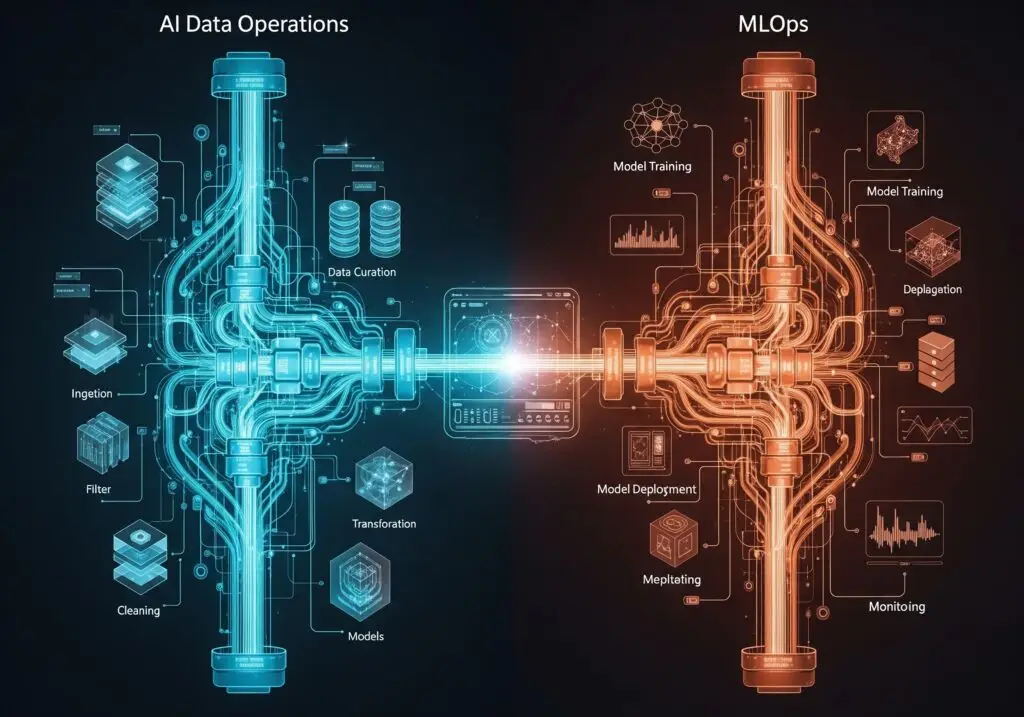
AI Data Operations is the discipline that produces and maintains the data an AI system learns from; collection, annotation, curation, human feedback, and the evaluation sets used to test it. MLOps is the discipline that trains, deploys, monitors, and retrains the models that consume that data. The two share roots in DevOps and meet at the pipeline, yet they own different assets and fail in different ways. A production AI program needs both, because a well-engineered model sitting on unreliable data still fails once it is live.

Teams usually learn the difference the hard way, when a model that passed every offline benchmark starts making strange calls in production. The cause is rarely the model code. It is almost always something upstream; a label definition that drifted, a data collection and curation process that quietly changed, or a data pipeline that started dropping a field with no warning. Treating these two functions as one job, or assuming one team owns both, is where many production AI programs lose months.

Key Takeaways

  • AI Data Operations is the work of building and maintaining the data a model learns from, while MLOps is the work of training, launching, and watching over the model itself.
  • The two are easy to confuse because they grew from the same playbook, but they look after different things and break in different ways.
  • A model can pass every test and still fail in real use if the data feeding it was messy or out of date.
  • The most common breakdowns happen at the handoff between the two teams, which is why a clear agreement on what “good data” means is so important.
  • If you have to choose where to fix things first, look at what fails more often: shaky data or shaky deployment.
  • Companies that treat data work as its own real job tend to ship more dependable AI than those who leave it as an afterthought.

What is AI Data Operations, and how is it different from classic DataOps?

AI Data Operations, sometimes called AI DataOps, is the operational discipline that turns raw signals into AI-ready datasets and keeps them reliable over time. It covers data collection, annotation, curation, human preference optimization, and the evaluation sets used to test models before and after release. Classic DataOps grew up in analytics and business intelligence, where the output is a dashboard or a report. AI Data Operations targets a different output: training and evaluation data whose quality directly changes how a model behaves.

A useful way to frame the scope comes from data-centric AI research, which organizes the work into three goals; training data development, inference data development, and data maintenance. Those goals map almost exactly onto what an AI data operations team does day to day. Building labeled training sets is training data development. Preparing prompts and retrieval context is inference data development. Re-labeling, auditing, and refreshing datasets as the world changes is data maintenance.

The hardest part of this discipline is rarely the labeling itself. It is the definition work of AI data operations that sits behind the labels. Two reasonable annotators will disagree on the same example whenever the guideline is vague, and that disagreement becomes noise the model learns as if it were signal. Measuring inter-annotator agreement, then tightening guidelines until agreement is high, is the unglamorous core of a serious data operation. Skip it, and every downstream metric inherits the ambiguity.

For most of the last decade, this work was treated as a side task for whoever happened to be free. That assumption no longer holds at production scale. Data engineering is becoming a core AI competency as models commoditize, and the data operation becomes the part of the stack that teams can actually differentiate on. Naming it as a discipline, with its own owners and standards, is the first step toward running it well.

What does MLOps actually own in the model lifecycle?

MLOps, short for machine learning operations, is the engineering discipline that moves models from a notebook into reliable production service. It borrows continuous integration, version control, and monitoring from DevOps and applies them to the model lifecycle. That lifecycle runs from experiment and training through validation, deployment, monitoring, and retraining. The asset MLOps protects is the model and its behavior in production.

MLOps assumes the training data already exists and is fit for purpose. It versions that data, tracks which dataset produced which model, and watches for drift once the model is live. What it does not do is produce the labels, resolve disagreement between annotators, or decide what a correct answer looks like. Those decisions sit upstream, in the data operation, and MLOps inherits whatever they produce.

This blind spot is well documented. A foundational paper offering a data quality-driven view of MLOps argued that most MLOps tooling concentrates on engineering concerns such as orchestration, reproducibility, and versioning, while doing little to monitor or version the datasets themselves. The gap is structural. When data quality is treated as someone else’s problem, it tends to surface later as a model incident that is expensive to trace.

Reproducibility is the other thing MLOps exists to guarantee. A model is only trustworthy in production if you can recreate exactly how it was built, roll back to a known-good version, and audit what changed between releases. That demands strict versioning of code, configuration, and the dataset reference, plus a registry that ties each deployed model to the run that produced it. None of this fixes a bad dataset. It only makes the consequences of one traceable, which is necessary but not sufficient on its own.

Where do AI Data Operations and MLOps overlap, and where do they diverge?

Both disciplines descend from DevOps, so they share a lot of mechanics. Both use version control, automated testing, continuous delivery, and monitoring. Both organize work into repeatable cycles instead of one-off projects. The overlap is real, and it is a large part of why the two are so often confused.

The divergence shows up in what each one owns and measures. AI Data Operations is judged on data quality distributed across inter-annotator agreement, label accuracy, coverage of edge cases, and freshness. MLOps is judged on model and system quality based on accuracy in production, latency, drift, and rollback safety. The table below maps the split across the dimensions that matter most when you decide who owns what.

Dimension AI Data Operations MLOps
Primary asset Training, annotation, and evaluation data Models and their behavior in production
Lifecycle Collect, annotate, curate, validate, maintain Experiment, train, validate, deploy, monitor, retrain
Core metrics Inter-annotator agreement, label accuracy, edge-case coverage, freshness Production accuracy, latency, drift, rollback safety
Typical owners Data ops leads, annotation managers, domain experts, QA ML engineers, platform and infrastructure teams, SREs
Example tooling Labeling platforms, consensus and QA tooling, dataset version control, curation pipelines Feature stores, model registries, CI/CD for models, serving and monitoring
Main failure mode Inconsistent labels, stale data, hidden bias Training and serving skew, undetected drift, fragile deployment

The shared vocabulary hides a subtle trap. Continuous integration means something different in each discipline. In MLOps, a pipeline run retrains and revalidates a model against a fixed dataset. In AI Data Operations, a pipeline run ingests new examples, routes them through annotation and QA, and publishes an updated dataset. Both are automated and both are tested, but a passing data pipeline and a passing model pipeline answer different questions. Confusing the two leads teams to trust a green build that never checked the thing that actually broke.

MLOps cannot hit its metrics if the data operation misses its own. A model registry with perfect lineage offers little comfort when the labels it points to were defined inconsistently across three annotation vendors.

Does MLOps include data operations?

This is the most common question, and the honest answer is partly. MLOps includes data handling; versioning datasets, building feature pipelines, and validating schemas at training time. It treats data as an input to be managed. It does not include the human and editorial work of producing that data, which means writing annotation guidelines, training annotators, adjudicating disagreement, and curating for coverage.

AI Data Operations and MLOps share the pipeline where data is prepared and fed to training. Upstream of that handoff, the data operation runs work that MLOps tooling was never designed to do. Downstream, MLOps runs work that no labeling platform handles. Calling one a subset of the other hides the seam where most production failures actually happen.

How does AI Data Operations feed the MLOps pipeline?

The connection point between the two is a handoff, and handoffs are where things break. The data operation produces a dataset, and MLOps consumes it for training and serving. When that boundary is informal, small upstream changes cause large downstream failures. A clear data contract, meaning an agreed schema, label taxonomy, and quality threshold, is what keeps the handoff stable.

Two failure patterns dominate this seam. The first is training and serving skew, where the transformation applied during training differs from the one applied at inference, so the model meets data it was never trained on. The second is silent schema drift, where a column changes type or a field stops arriving and nothing flags it. Data pipelines are important for AI as disciplined pipeline design prevents both, by making every transformation explicit and testable.

A data contract is what turns this from a hope into a guarantee. In practice it specifies the exact fields a dataset will contain, the label taxonomy and its allowed values, the minimum agreement and accuracy thresholds, and how changes are versioned and announced. With that contract in place, the data team can evolve its work and the model team can depend on a stable interface. Without it, every relabeling effort or new data source becomes a surprise that the MLOps team discovers through a failing model.

The feedback loop also runs the other way. Once a model is live, MLOps monitoring detects drift, which is a drop in accuracy as real-world inputs shift away from the training distribution and AI model performance degrades over time. That signal is only useful if the data operation can respond by sourcing and labeling fresh examples. 

What tools are used in AI data operations, and who owns them?

AI Data Operations runs on a different stack than MLOps. The core tools are labeling and annotation platforms, consensus and QA tooling for measuring agreement, dataset version control, and curation pipelines that filter and balance data. A 2024 survey of data quality tools for machine learning reviewed seventeen such tools and found the field still fragmented, with no single platform covering quality end to end. That fragmentation is why process and standards matter more than any one tool.

MLOps runs on feature stores, model registries, CI/CD systems built for models, and serving and monitoring platforms. The ownership split follows the tooling. Annotation managers, domain experts, and QA leads own the data operation. ML engineers, platform teams, and SREs own MLOps. Problems start when one group is held accountable for outcomes that the other group controls. A separate question is whether to run the data operation in-house at all, which the build vs. buy vs. partner decision for AI data operations works through for teams weighing their options.

Deciding where to invest first depends on what breaks more often:

  • If models pass offline tests but behave unpredictably in production, the bottleneck is usually data quality, and AI Data Operations needs attention first.
  • If models are sound but slow, fragile, or hard to deploy and roll back, the bottleneck is MLOps maturity.
  • If incidents cluster at the handoff, with schema mismatches, skew, and stale labels, the fix is a formal contract between the two, not more spending on either alone.

How Digital Divide Data Can Help

Digital Divide Data operates the data side of this split as a managed service. Our data collection and curation teams build training and evaluation datasets to an agreed taxonomy, with inter-annotator agreement tracked as a first-class metric rather than an afterthought. Domain experts and trained annotators handle the editorial decisions, including guideline design, disagreement adjudication, and edge-case coverage, that MLOps tooling cannot.

The work connects directly to the MLOps pipeline through disciplined delivery. Our model evaluation services produce the held-out and adversarial sets your team needs to validate models before release and to catch regressions after. When production monitoring flags drift, the same teams source and label fresh examples, which closes the loop between detection and response. This is the handoff that most programs leave informal, run instead as a contract with defined schemas and quality thresholds.

For programs that need the infrastructure as well as the labels, DDD builds and runs the data pipelines that move data from source to training-ready state, with quality checks at each stage. The result is an AI data operation that feeds MLOps cleanly, in place of a series of manual handoffs that fail quietly.

Build a data operation your MLOps pipeline can actually rely on. Talk to an operation and pipeline expert today.

Conclusion

AI Data Operations and MLOps are two halves of one production system. One keeps the data trustworthy, and the other keeps the model reliable. They share DevOps roots and meet at the pipeline, but they own different assets, use different tools, and fail in different ways. Treating them as a single job is how programs end up debugging model code to fix what was always a data problem.

The organizations that ship dependable AI treat the data operation as a named discipline with its own owners, metrics, and contract to the MLOps pipeline. The ones that struggle keep data work invisible, then absorb the cost downstream as drift, skew, and incidents no one can trace. As models commoditize, the gap between these two groups will widen, and it will be decided upstream, in the data operation, long before a model reaches production.

References

Zha, D., Bhat, Z. P., Lai, K.-H., Yang, F., Jiang, Z., Zhong, S., & Hu, X. (2025). Data-centric Artificial Intelligence: A Survey. ACM Computing Surveys, 57(5), 1–42. https://arxiv.org/abs/2303.10158

Zhou, Y., Tu, F., Sha, K., Ding, J., & Chen, H. (2024). A Survey on Data Quality Dimensions and Tools for Machine Learning. arXiv preprint arXiv:2406.19614. https://arxiv.org/abs/2406.19614

Renggli, C., Rimanic, L., Gürel, N. M., Karlaš, B., Wu, W., & Zhang, C. (2021). A Data Quality-Driven View of MLOps. IEEE Data Engineering Bulletin, 44(1), 11–23. https://arxiv.org/abs/2102.07750

Frequently Asked Questions

What is the difference between AI DataOps and MLOps?

AI Data Operations produces and maintains the data a model learns from, including collection, annotation, curation, and evaluation sets. MLOps trains, deploys, and monitors the model that uses that data. They overlap at the pipeline but own different assets.

Does MLOps include data operations?

Only partly. MLOps handles data as an input by versioning datasets, building feature pipelines, and validating schemas. It does not produce the labels or write the annotation guidelines, since that editorial work sits upstream in the data operation.

What tools are used in AI data operations?

Mainly labeling and annotation platforms, consensus and QA tooling for measuring agreement, dataset version control, and curation pipelines. The field is fragmented, so no single tool covers quality end to end, which is why standards and process matter as much as the tools.

Should we invest in AI Data Operations or MLOps first?

It depends on what breaks more often. If models pass offline tests but act up in production, fix data quality first. If models are sound but slow or fragile to deploy, invest in MLOps. If failures cluster at the handoff, formalize the contract between the two.

AI Data Operations vs. MLOps: Key Differences, Use Cases, and Why Both Matter for Production AI Read Post »

Vertical SLMs Need Different Datasets Than Frontier LLMs

Why Vertical SLMs Need Different Datasets Than Frontier LLMs

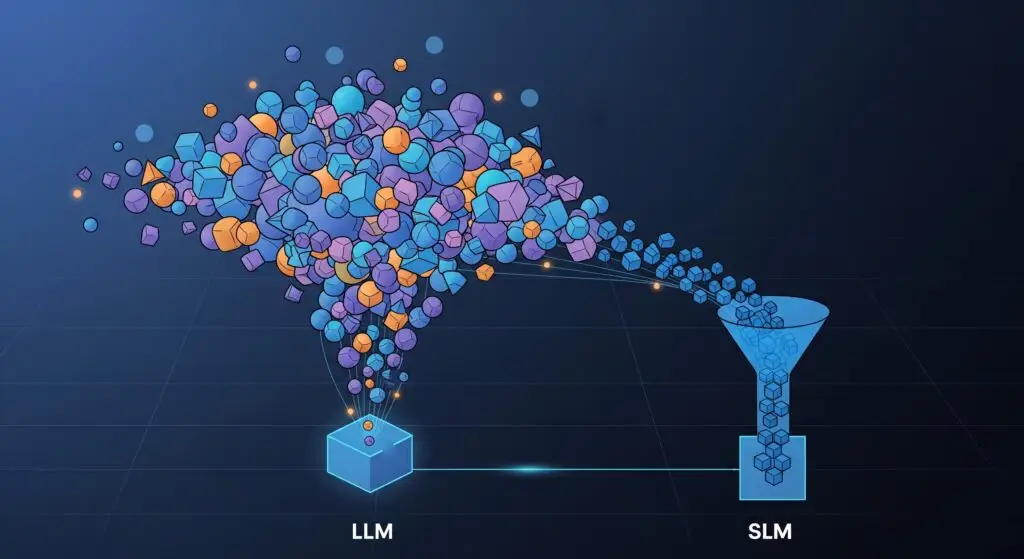
Vertical small language models (SLMs) and frontier large language models (LLMs) are built for fundamentally different jobs, and their training data requirements reflect that difference. Frontier LLMs benefit from scale, breadth, and diversity, while Vertical SLMs need tight domain purity, carefully bounded vocabulary, and task-specific negative examples. Treating these two model classes as interchangeable at the data level is one of the most reliable ways to produce a fine-tuned model that underperforms both a general-purpose LLM and the specialized model your program needs.

The practical distinction between frontier models and efficient model classes matters most clearly in data strategy. Language Model fine-tuning services that work well for general-purpose adaptation frequently produce mediocre results when applied to vertical SLMs, because the data pipelines were designed for a different scale objective. 

Key Takeaways

  • Vertical SLMs are built for one specific job, so their training data must match that job precisely, scale and variety work against them.
  • A small model exposed to data from outside its target domain gets confused by competing word meanings, and that confusion shows up as unreliable outputs in production.
  • Generic benchmarks used to test large AI models tell you almost nothing useful about how a vertical SLM is actually performing.
  • The evaluation set should be built before training starts, not assembled from leftover examples afterward.
  • Showing the model what a wrong-but-plausible answer looks like requires people who know the domain well enough to construct realistic mistakes.
  • Teams that treat vertical SLM data as its own discipline, with its own standards and sourcing strategy, consistently get better models faster than those borrowing general-purpose pipelines.

What is a Vertical SLM and How Does It Differ from a Frontier LLM?

A vertical small language model (SLM) is a compact language model, typically under 10 billion parameters, trained or fine-tuned to perform well on a narrow domain of tasks. Examples include a radiology report parser, a contract clause classifier, or a parts-identification assistant for industrial equipment. The model is not trying to answer general knowledge questions or write poetry. It is trying to be highly reliable on a defined set of inputs within a specific operational context. Data collection and curation for this category of model look very different from what goes into pre-training a frontier model.

Frontier LLMs, such as GPT-4 class models or Claude Opus, are trained on massive corpora spanning hundreds of domains. Their value proposition is breadth; they handle novel inputs, transfer across tasks, and generalize well without task-specific fine-tuning. An SLM’s value proposition is depth and efficiency i.e. maximum performance on a targeted task, at a fraction of the inference cost.

On the architectural side, Frontier LLMs use hundreds of billions of parameters to build rich cross-domain representations. SLMs use far fewer parameters and compensate through targeted fine-tuning on high-quality, in-domain data. This is why the data strategy for custom LLM training diverges sharply depending on which model class is the target.

What Training Data Do Small Language Models Need Compared to Large Language Models?

SLMs need less data overall but more precise data. A frontier LLM improves with more tokens, more domains, and more linguistic variation. A vertical SLM degrades when exposed to out-of-domain content that dilutes the signal the model is trying to learn. The training objective is different, so the data design must be different.

For frontier LLMs, the training corpus typically aims for breadth across Common Crawl snapshots, books, code repositories, scientific papers, and multilingual content. Quality filtering matters, but diversity is a design goal. The model learns generalizable representations precisely because it has seen so many domains.

A vertical SLM does not benefit from that breadth. Introducing clinical text into a legal contract model, or general-purpose Q&A data into a medical coding assistant, tends to produce a model that hedges on in-domain queries rather than confidently applying domain-specific reasoning. Research on domain-adaptive pretraining consistently finds that models fine-tuned on clean, in-domain corpora outperform models fine-tuned on mixed corpora of the same token count. The quality-versus-quantity tradeoff resolves firmly in favor of quality at the SLM scale.

This has direct implications for how datasets built for LLM fine-tuning should be structured when the target is a vertical SLM. The pipeline needs domain-specific sourcing, not general-web crawling. It needs annotators with subject matter expertise, not general annotation talent. And it needs tighter filtering criteria than a frontier pre-training pipeline would apply.

Why Domain Purity Matters More Than Dataset Scale for Custom LLM Training in Vertical SLMs

Domain purity refers to the degree to which training examples fall within the target operational domain, use the correct vocabulary and ontology, and reflect real distributions of the inputs the deployed model will see. It is not the same as simply filtering for quality. A high-quality general-purpose document can still contaminate a vertical SLM training set if it introduces terminology ambiguity or shifts the model’s prior away from domain norms.

Consider a financial services SLM trained to extract covenant violations from loan agreements. If the training set includes general legal text, contracts from unrelated industries, or financial journalism alongside actual loan documents, the model will see multiple competing uses of terms like ‘default’, ‘material adverse change’, or ‘cure period’. That ambiguity does not hurt a frontier LLM, which has enough capacity to hold context-dependent representations of each usage. 

Practical domain purity requires three things:

  • Source selection: data must be sourced from the operational domain itself, not adjacent or related domains. Proxies are often insufficient.
  • Vocabulary alignment: the terminology, abbreviations, and entity types in the training data must match those in production inputs.
  • Distribution matching: the ratio of document types, query types, and difficulty levels must reflect what the deployed model will actually encounter.

This level of curation is substantially more demanding than what most general-purpose fine-tuning pipelines are built to deliver. Most enterprise LLM fine-tuning projects underdeliver, traces directly to this gap. Teams apply general-purpose data pipelines to domain-specific problems and then attribute the failure to the model architecture rather than the training data.

How Should Eval Sets Be Designed Differently for Vertical SLMs?

Standard benchmarks like MMLU, HellaSwag, or TruthfulQA are designed to probe general reasoning and knowledge breadth. They are appropriate eval instruments for frontier LLMs. They are nearly useless for evaluating vertical SLMs. An enterprise LLM training program for a vertical SLM needs a custom eval set built specifically for the target domain and task distribution.

A well-designed vertical SLM eval set has several distinct characteristics. It is tight: only examples that fall within the operational domain are included. It is adversarial in a domain-specific way: it probes failure modes that are plausible in production, not failures that are only interesting in a general reasoning context. And it is stratified: it includes examples across the full difficulty spectrum, from easy canonical cases to edge cases that require fine-grained discrimination within the domain.

One structural error teams make is treating the eval set as an afterthought, assembled from whatever labeled examples were not used in training. A vertical SLM eval set should be purpose-built before fine-tuning begins. Model evaluation services designed for this purpose treat the eval set as an independent artifact with its own sourcing, annotation, and quality assurance process. The inter-annotator agreement standards for eval data should be higher than those applied to training data, because errors in the eval set produce misleading signals about model performance at every subsequent iteration.

Why Negative Example Curation is a Structural Requirement for Vertical SLM Training

Frontier LLMs encounter enough diversity in pre-training that they develop reasonable priors about what constitutes an incorrect or unhelpful output. Vertical SLMs do not have that breadth of exposure. They need to be explicitly taught what wrong looks like in the target domain, through carefully curated negative examples.

Negative examples for vertical SLMs serve a different purpose than they do in general RLHF pipelines for frontier models. In a frontier model alignment context, rejected responses typically demonstrate generic failure modes: refusal when helpful, helpfulness when harmful, poor formatting, or factual hallucination on general knowledge. For a vertical SLM, the failure modes are domain-specific. A medical coding assistant might confidently assign a plausible but incorrect ICD code. A contract extraction model might correctly identify a clause type but miss a material qualifier. These errors do not appear in generic negative example datasets.

Curating useful negative examples for a vertical SLM requires subject matter expertise in the target domain. The annotator needs to know what a plausible wrong answer looks like, which requires understanding the domain well enough to construct near-miss errors. Fine-tuning techniques for domain-specific language models consistently identify this as one of the harder components of vertical SLM data pipeline design, precisely because general annotation talent cannot reliably produce domain-plausible negatives.

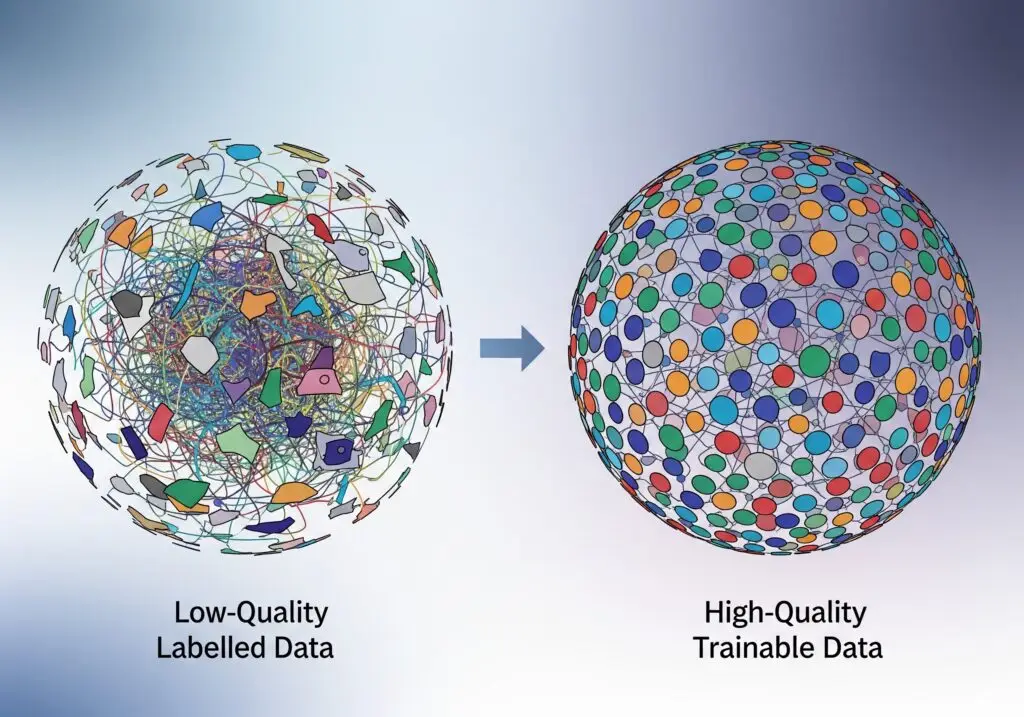
The difference between labeled and trainable data is not just annotation quality, it is whether the examples, positive and negative alike, are representative enough of the production distribution to produce a model that generalizes within the target domain.

How Digital Divide Data Can Help

Digital Divide Data builds domain-specific training datasets for vertical SLMs that prioritize purity over scale. The process starts with source analysis: understanding the operational domain’s vocabulary, document types, and query distributions before any data collection begins. Data collection and curation services are designed to produce training corpora that match the target domain precisely, with sourcing strategies adapted to the specific industry, use case, and model architecture in scope.

DDD’s annotation teams are organized around domain specialization. For vertical SLMs in sectors such as legal, financial services, healthcare, or industrial operations, annotators are recruited and trained for subject matter competency, not just annotation speed. This matters most when building negative example sets, where domain-plausible near-miss errors require annotators who understand the domain well enough to construct them. LLM fine-tuning services at DDD include this negative example curation step as a standard component, not an optional add-on.

Eval set design is treated as a separate, independent workstream. DDD builds custom evaluation sets for vertical SLMs before fine-tuning begins, with higher inter-annotator agreement thresholds than applied to training data and explicit coverage of domain-specific failure modes. The model evaluation services team works with ML engineers to define what correct, acceptable, and incorrect mean in the target domain, then builds an eval set that actually measures those distinctions.

Build a vertical SLM training program on data that was designed for it from the beginning. Talk to an Expert!

Conclusion

The data requirements for vertical SLMs and frontier LLMs diverge at every layer of the pipeline, namely; sourcing, filtering, annotation expertise, eval design, and negative example curation. Treating them as the same problem produces models that are neither as capable as a frontier LLM nor as precise as a well-built SLM should be. The organizations that get this right approach vertical SLM data as its own discipline, with its own quality standards and its own tooling decisions.

Enterprise AI teams that build domain-pure training sets, purpose-built eval corpora, and subject-matter-grounded negative examples consistently outperform teams that apply general-purpose fine-tuning pipelines to vertical SLM programs. The gap tends to compound over iteration cycles: better data produces better eval signals, which produces better fine-tuning decisions, which produces a better model faster. 

References

Gururangan, S., Marasovic, A., Swayamdipta, S., Lo, K., Beltagy, I., Downey, D., & Smith, N. A. (2020). Don’t stop pretraining: Adapt language models to domains and tasks. Proceedings of ACL 2020. https://aclanthology.org/2020.acl-main.740

Sachdeva, N., Coleman, B., Kang, W.-C., Ni, J., Hong, L., Chi, E. H., Caverlee, J., McAuley, J., & Cheng, D. Z. (2024). How to train data-efficient LLMs. arXiv preprint. https://arxiv.org/abs/2402.09668

Kumar, A., Amin, E. M., Lee, X. Y., Vidyaratne, L., Farahat, A. K., Ghosh, D. D., Koreeda, Y., & Gupta, C. (2025). Building domain-specific small language models via guided data generation. arXiv preprint. https://arxiv.org/abs/2511.21748

Frequently Asked Questions

What training data do small language models need compared to large language models?

Small language models need less data overall but far more precise data. Where frontier LLMs benefit from broad, diverse corpora spanning many domains, vertical SLMs perform better when trained on clean, in-domain data that closely matches their target task. Adding out-of-domain data to an SLM training set tends to dilute the model’s in-domain signal rather than improving its generalization, because SLMs do not have the parameter capacity to hold context-dependent representations of the same term across multiple domains.

Why does domain purity matter more for SLMs than for frontier LLMs?

Frontier LLMs have enough parameters to learn context-dependent representations of ambiguous terms across domains. If the training set introduces competing uses of domain-critical vocabulary, the SLM tends to hedge at inference time rather than apply confident domain-specific reasoning. Domain purity ensures the model’s learned representations map cleanly onto the operational domain it will encounter in production.

How should I build an eval set for a vertical SLM?

Build the eval set before fine-tuning begins, as an independent artifact. It should cover the full difficulty spectrum within the target domain, include examples that probe domain-specific failure modes, and be held to higher annotation quality standards than the training data. Generic benchmarks like MMLU are not useful for evaluating vertical SLMs because they measure general reasoning, not performance within the operational domain.

Why are negative examples harder to curate for vertical SLMs?

For a vertical SLM, useful negative examples are domain-plausible near-misses: outputs that look correct to a non-expert but are wrong in ways that matter in the target domain. Constructing those examples requires annotators who understand the domain well enough to know what a plausible wrong answer looks like. General annotation talent can produce random incorrect outputs, but those do not teach the model to avoid the specific failure modes it will encounter in production.

Why Vertical SLMs Need Different Datasets Than Frontier LLMs Read Post »

Machine Learning Data Labeling

Machine Learning Data Labeling Services: Why “Labeled” Doesn’t Always Mean “Trainable”

Labeled data is not automatically trainable data. The gap between the two is defined by three important factors: label consistency across annotators, class coverage across the distribution your model will face in production, and whether your downstream evaluation metrics actually expose annotation failures before they reach deployment. Most machine learning data labeling services close the first factor. Very few consistently address all three.

Data quality is the most cited reason AI projects underperform in production, and yet most teams don’t catch the problem until they’ve already trained on it. Understanding what makes labeled data actually useful for AI models starts with separating the act of annotation from the standard of annotation. Programs that invest in quality of data collection and curation process programs label quality upstream spend far less time debugging model failures downstream.

Key Takeaways

  • Labeled data and trainable data are two different attributes. A 100% labeled dataset can still fail to produce a model that generalizes if consistency, coverage, or schema quality is missing.
  • Low inter-annotator agreement (IAA) means your model is learning a weighted average of conflicting annotator interpretations, not actual ground truth.
  • Coverage gaps are invisible during standard evaluation because test sets are usually drawn from the same flawed collection as training data.
  • Overall accuracy many times hides annotation failures. Per-class recall, confusion matrix analysis, and slice-level performance are the metrics that actually expose them.
  • Annotation quality problems found during model debugging cost far more to fix than annotation quality standards enforced at the start of the labeling pipeline.

What is the Difference Between Labeled Data and Trainable Data?

Machine learning data labeling services produce labeled dataset files, where each sample carries an annotation, but “labeled” is a binary state. While “Trainable” is a quality threshold. A dataset can be 100% labeled and still fail to produce a model that generalizes.

Trainable data meet three conditions simultaneously. First, labels are consistent; two annotators working independently on the same sample reach the same conclusion, as measured by inter-annotator agreement (IAA) scores. Second, the dataset has sufficient class coverage; every category the model will encounter in production appears with enough examples to learn a reliable decision boundary. Third, the label schema maps correctly to the task, the taxonomy used during annotation is specific enough to be useful, but not so granular that annotators make arbitrary distinctions.

When any of these conditions fail, the model trains on noise instead of signal, producing plausible-looking accuracy numbers on a held-out set while underperforming on the specific cases that matter in deployment. This is why data annotation challenges at scale are not primarily about throughput; they’re about maintaining quality standards as volume increases.

Why Does Label Consistency Determine Whether a Dataset Is Trainable?

Label consistency is the single most predictive indicator of whether a supervised learning dataset will produce a model that transfers to production. Low inter-annotator agreement is not a minor inconvenience; it means your model is learning a weighted average of conflicting interpretations rather than a coherent concept.

When annotators disagree on boundary conditions like edge cases between adjacent categories, ambiguous instances, or samples that require domain knowledge to classify, the training signal on those samples is contradictory. The model receives conflicting gradient updates. Over a large enough dataset, systematic disagreements encode annotator bias rather than ground truth. The 99.5% annotation accuracy in production matters precisely because even small error rates compound across millions of training samples.

There are three primary sources of label inconsistency that teams consistently underestimate:

Ambiguous labeling guidelines: Guidelines written at the category level without worked examples leave annotators to resolve edge cases independently. Each annotator develops their own rules. IAA looks acceptable in aggregate but hides systematic splits on specific subclasses.

Annotator fatigue in long sessions: Accuracy on complex annotation tasks degrades after 90–120 minutes. Without session controls, later batches in a work session carry more noise than earlier batches. 

Insufficient domain expertise for specialized tasks: Tasks that require domain knowledge, like medical imaging, legal document classification, or sensor data from autonomous systems, produce very low IAA when assigned to general annotators. The resulting labels represent best guesses, not ground truth.

Fixing this after labeling is expensive. Relabeling at scale means discovering the problem late, often after a failed training run. The more reliable approach is to run IAA audits on a stratified sample before full production begins, and to build adjudication workflows, where disagreements trigger a review by a senior annotator or domain expert, into the pipeline itself. Fixing unreliable data annotation becomes costly after failed training and requires a lot of hidden costs. 

How Do Coverage Gaps Expose Your Model to Silent Failure?

Label consistency is a within-dataset property. Coverage is about the relationship between your dataset and the real-world distribution your model must handle. A dataset can have near-perfect IAA scores and still catastrophically fail in production if it systematically underrepresents the cases that matter.

Coverage gaps tend to be invisible during evaluation because most held-out test sets are drawn from the same collection as training data. If the collection process missed night-time driving scenarios, both training and test sets missed them. The model looks competent until it encounters night-time conditions in deployment. The same pattern appears in medical imaging when datasets are collected from a single hospital, in NLP when training data skews toward one dialect or register, and in robotics when physical training environments don’t replicate the range of object orientations found in real warehouses.

Three coverage problems appear most often:

Class imbalance: Rare but important categories like edge cases, failure modes, and minority demographic groups are underrepresented because they’re genuinely rare in uncurated data collection. The model learns to ignore them because ignoring them carries a minimal penalty on the training objective.

Distribution shift: Data is collected under conditions that differ from deployment conditions. This includes temporal shifts (training on last year’s data for this year’s problem), geographic shifts, and hardware shifts (different camera models, different sensor calibrations).

Missing negative examples: Classifiers trained without sufficient hard negatives, examples that resemble the positive class but should be labeled negative, develop wide decision boundaries and produce too many false positives in production.

The only reliable defense against coverage gaps is active curation. This means analyzing collection data for distributional completeness before annotation begins, augmenting underrepresented slices, and running slice-level evaluation to confirm that model performance is acceptable across each subgroup, not just in aggregate. Building AI-ready datasets at scale requires a pipeline design that treats coverage as a first-order constraint.

Which Downstream Metrics Actually Expose Annotation Problems?

Overall accuracy is never the right metric for detecting annotation quality failures. It aggregates across the entire dataset and is dominated by the majority class. Problems with rare categories, coverage gaps, and labeling inconsistencies on hard examples all hide inside an acceptable accuracy number.

The metrics that consistently surface annotation problems are those that force per-slice analysis. These include:

Per-class precision and recall: A class with very low recall relative to others is often one where annotators disagree frequently or where coverage is insufficient. High false negative rates on specific classes trace directly to annotation failures.

Confusion matrix analysis: Systematic confusions between adjacent classes, for example, where the model consistently predicts Class A when the ground truth is Class B, often indicate that the boundary between those classes was annotated inconsistently. The model learned the wrong boundary because annotators didn’t agree on where it was.

Calibration error: A model that is overconfident in its errors has typically been trained on noisy labels. Expected Calibration Error (ECE) tends to be higher for datasets with low IAA, because the model has been trained to express high confidence in examples where the “ground truth” was actually contested.

Slice-level performance on known hard subgroups: If you can define subgroups expected to be harder, rare classes, out-of-distribution conditions, or demographic subgroups, performance gaps between those slices and the overall population are a proxy for coverage and consistency failures.

If the taxonomy is wrong, and task framing doesn’t match what the model needs to do in production, high IAA and good coverage will produce a highly consistent but wrong model. Taxonomy validation, which involves domain experts reviewing the label schema against production use cases before annotation begins, is not optional for high-stakes programs. 

How Digital Divide Data Can Help

DDD’s approach to machine learning data labeling services is built around the distinction between labeled and trainable data. Every annotation program that DDD operates includes IAA measurement as a standard process step, not an optional audit. Annotator teams work against guidelines that are developed with worked examples for edge cases, and adjudication workflows are embedded directly in the pipeline so that disagreements trigger expert review rather than accumulating as noise in the final dataset.

On the coverage side, DDD’s data collection and curation services include collection strategy design, distributional analysis, and active slice augmentation for underrepresented categories. For programs in Physical AI and ADAS where coverage gaps carry safety implications, DDD runs scenario-level coverage audits that map the collected dataset against the target Operational Design Domain (ODD) before labeling begins. This ensures that annotation effort is not wasted on a distribution that will produce a model with known coverage failures.

Downstream, DDD’s model evaluation services are designed to surface annotation-level failures. Evaluation pipelines include per-class analysis, confusion matrix review, and slice-level scoring against defined hard subgroups. Where evaluation reveals category-level failures that trace back to annotation inconsistency, DDD’s teams can run targeted relabeling on the affected slice without restarting the full dataset pipeline.

Label programs that actually close performance gaps require more than throughput. They require quality architecture. Talk to an Expert!

Conclusion

The gap between labeled data and trainable data is not closed by scale. Larger volumes of low-consistency, low-coverage labeled data produce larger models with the same failure modes, at greater cost. The programs that consistently produce deployable models treat annotation quality as an upstream investment. IAA measurement, coverage analysis, and taxonomy validation should be discussed before annotation begins, not as remediation steps after a failed training run.

Teams that operate this way are better positioned to identify failures before they reach production and to iterate faster when distribution shifts require dataset updates. Teams that don’t will continue to discover annotation failures through model debugging, which is the most expensive place to find them.

References

Zha, D., Bhat, Z. P., Lai, K.-H., Yang, F., Jiang, Z., Zhong, S., & Hu, X. (2023). Data-centric AI: A survey. arXiv preprint. https://arxiv.org/abs/2303.10158

Nushi, B., Kamar, E., & Horvitz, E. (2018). Towards accountable AI: Hybrid human-machine analyses for characterizing system failure. Proceedings of AAAI HCOMP. https://arxiv.org/abs/1809.07424

Frequently Asked Questions

What makes labeled data actually useful for machine learning models?

Labeled data becomes useful when it meets three conditions at once: annotators are consistent with each other (measured by inter-annotator agreement), the dataset covers the distribution the model will face in production, and the label schema maps correctly to the actual task. Missing any one of these produces a dataset that can train a model, but won’t produce reliable performance in deployment.

How do you measure label quality before training starts?

The primary measure is inter-annotator agreement (IAA), calculated on a stratified sample where multiple annotators label the same examples. Cohen’s kappa is the standard metric for categorical labels. IAA should be measured at the category level, not just in aggregate, because high overall agreement can hide systematic disagreements on specific subclasses that matter most.

Why does a model sometimes perform well on test data but fail in production?

This usually means the test set was drawn from the same distribution as the training data, so coverage gaps and annotation errors are shared across both sets. If a class or condition was systematically underrepresented or mislabeled during collection, both training and test sets carry the same blind spot. Slice-level evaluation; testing specifically on known hard subgroups is more likely to surface these gaps than overall held-out accuracy.

How does annotator disagreement affect model training?

When annotators disagree on the same sample, the training set contains conflicting labels for similar inputs. The model receives contradictory gradient updates on those samples and tends to learn an unstable boundary around the contested region. This often shows up as high calibration error, and the model becomes overconfident in the types of examples where annotators disagreed most.

Machine Learning Data Labeling Services: Why “Labeled” Doesn’t Always Mean “Trainable” Read Post »

enterprise knowledge for AI agents

How to Prepare Enterprise Knowledge for Runtime Access by AI Agents?

Agent-ready data is not the same as training data for AI agents. Training data shapes how an agent reasons; agent-ready data determines what that agent can actually find and use at runtime. Most enterprise knowledge, stored across file servers, CRMs, wikis, and legacy document repositories, is structurally inaccessible to AI agents without deliberate preparation. That preparation is what AI data operations services are increasingly being designed to solve.

Estimates from IBM suggest roughly 90% of enterprise data is in a state that agents cannot reliably use. The failure is rarely about data volume, rather it is about structure, discoverability, and permission-aware indexing. Enterprises that deploy agents on top of raw, unprepared knowledge bases consistently find that retrieval quality degrades faster than model quality improves. The gap between what agents are capable of and what they can actually access is a data collection and curation problem as much as it is a model problem.

Key Takeaways

  • Training data shapes how an agent reasons, while agent-ready data determines what it can actually find and use when executing a task.
  • Roughly 90% of enterprise data is currently unusable by AI agents because it lacks the structure, semantic indexing, and permission metadata that agents need to retrieve it reliably.
  • An agent operating on a poorly prepared knowledge base will underperform regardless of how capable its underlying model is.
  • Semantic chunking, metadata enrichment, and permission mapping are non-negotiable preparation steps that any enterprise knowledge layer agents will depend on.
  • A knowledge layer that works at launch will degrade without active maintenance. Freshness management, retrieval validation, and ongoing human review need to be built into the operational pipeline from the start.
  • The runtime knowledge layer and the model should be managed separately, with independent update cycles, so agents can access new information immediately without requiring retraining.

What Is Agent-Ready Data and How Does It Differ from Training Data?

Agent-ready data is the structured, semantically indexed, and permission-aware layer of enterprise knowledge that AI agents query at runtime to complete tasks. It is distinct from training data, which shapes the model’s parameters, reasoning style, and general capabilities during fine-tuning or pre-training. Training data is consumed once and baked into weights. Agent-ready data is consumed continuously, on demand, every time an agent executes a task.

A language model trained on general enterprise corpora may still fail at task execution if the knowledge it needs to retrieve e.g., a specific contract clause, a current pricing tier, or an access-controlled policy document, is not findable, correctly chunked, or linked to the right permissions. Agent performance is bounded not just by what the model knows but by what it can retrieve reliably.

Agent-ready data has three defining properties. First, it is structured so that agents can parse and chunk it predictably. Second, it is semantically indexed so that retrieval systems can surface contextually correct results, not just keyword matches. Third, it is permission-aware, meaning the agent’s access to a given piece of knowledge is governed by the same access controls that govern human access. Without all three, agents make decisions on incomplete or unauthorized information.

Why Do AI Agents Need a Dedicated Runtime Knowledge Layer?

AI agents operating in enterprise environments do not work from memory alone. They execute multi-step tasks; summarizing contracts, routing support tickets, and generating compliance reports by pulling relevant knowledge from external sources mid-task. That retrieval needs to be fast, accurate, and contextually bound. A retrieval system built for search-engine-style queries tends to underperform when agents need to compose answers from multiple documents across different access tiers.

Retrieval-augmented generation (RAG) is currently the dominant architecture for giving agents runtime access to enterprise knowledge. But RAG systems are only as reliable as the knowledge base. Retrieval quality degrades when source documents are poorly chunked, inconsistently formatted, or missing metadata. The same failure modes apply to agent knowledge layers, often with higher stakes because agents act on retrieved content rather than just presenting it.

A dedicated runtime knowledge layer also enables agents to stay current without retraining. When new policies, product updates, or regulatory changes are added to the knowledge base with proper indexing, agents can access them immediately. Without this layer, teams are forced to retrain or fine-tune models each time domain knowledge changes. 

What Makes Enterprise Data Structurally Inaccessible to AI Agents?

The 90% figure IBM cites is a structural indictment. Most enterprise data is rich with useful information. The problem is that it exists in formats, silos, and access structures that agents cannot navigate reliably.

The most common failure modes are:

  • Unstructured formats: PDFs, scanned documents, slide decks, and email threads contain useful knowledge but are not chunked or indexed in ways that support semantic retrieval. Agents querying these sources tend to retrieve fragments rather than complete, contextually coherent answers.
  • Implicit context: Enterprise documents often rely on organizational context that is not written down; e.g., acronyms, internal product names, team-specific jargon, etc. Without explicit metadata and entity linking, retrieval systems cannot resolve these references correctly.
  • Permission fragmentation: Access controls in enterprise systems vary by document, folder, system, and user role. Agents that ignore these controls retrieve content that users should not see. Agents designed to enforce these controls often fail because the permission metadata is not captured in the knowledge layer.
  • Stale content: Documents that are outdated, superseded, or archived are indistinguishable from current ones unless the knowledge layer explicitly tags version and validity status. Agents act on whichever version they retrieve.

The importance of data pipelines for AI systems becomes especially clear here. Agent-ready data does not emerge from existing repositories on its own. It requires active transformation: format normalization, semantic chunking, metadata enrichment, permission mapping, and ongoing freshness management.

How Do You Build a Semantically Indexed, Permission-Aware Knowledge Layer for AI Agents?

Building an agent-ready knowledge layer is sequenced data engineering. The sequence matters because each stage creates the conditions for the next one to work correctly.

Step 1: Inventory and format normalization

Start with a full inventory of enterprise knowledge sources: wikis, CRMs, document management systems, ticketing platforms, and policy repositories. Map each source to its format, update frequency, and access control model. Then normalize documents to a consistent format that supports reliable parsing and chunking. This is not simply file conversion, but rather a complex environment, e.g., scanned PDFs require OCR, slide decks require structured extraction of content by slide rather than bulk text, and Tables require column header preservation.

Step 2: Semantic chunking and entity linking

Chunking is the most consequential technical decision in knowledge layer design. Chunks that are too large dilute retrieval precision. Chunks that are too small lose context and produce incoherent completions. The right chunk size is domain-specific and depends on how agents will use the retrieved content. Entity linking mentions of products, people, policies, and locations to canonical identifiers is what allows agents to resolve cross-document references correctly.

Step 3: Metadata enrichment

Every chunk in the knowledge layer needs structured metadata: document type, date, author, department, access tier, version status, and relevant topic tags. This metadata serves two functions. It powers filtered retrieval, narrowing the search space before semantic similarity scoring. It also carries permission information, so agents inherit the correct access controls from the source document. This kind of structured data layer can be built at scale, including for legacy content that was never systematically tagged.

Step 4: Indexing and retrieval validation

Once content is chunked and enriched, it needs to be embedded and indexed in a vector store or hybrid search system. Indexing is not a one-time operation. It requires ongoing validation; checking retrieval precision and recall against representative agent queries, identifying content gaps, and monitoring for retrieval drift as the knowledge base grows. A reliable knowledge base for RAG-powered agents follows exactly this pattern.

What Role Does Metadata Play in Making Enterprise Knowledge Agent-Ready?

Metadata is the mechanism by which enterprise knowledge becomes navigable for agents. A document without metadata is a chunk of text. A document with structured metadata is a retrievable asset with defined scope, provenance, and access rules.

The specific metadata fields that matter most for agent-ready data are: document type (policy, contract, FAQ, technical spec), validity period (current, archived, under review), access tier (public, internal, restricted, confidential), owning team or department, and topic or domain tags. When retrieval is done against a metadata-filtered index, agents retrieve content from the right scope before semantic similarity scoring narrows to the best match. This two-stage retrieval (filter then rank) tends to outperform pure semantic search on enterprise knowledge tasks. 

Permission metadata deserves particular attention. In most enterprise environments, access controls are stored in identity and access management systems that are separate from document repositories. Building a knowledge layer that accurately reflects these controls requires joining permission data with document metadata at ingestion time. This is an engineering problem with significant organizational complexity, but it is non-negotiable for any agent deployment that operates across information with different sensitivity levels.

How Digital Divide Data Can Help

DDD works with enterprise AI teams that are past the proof-of-concept stage and dealing with the real-world problem of knowledge accessibility at scale. The work typically starts with end-to-end data collection and curation, inventorying the knowledge sources an agent program depends on, normalizing formats, and building the chunking and indexing pipelines that make retrieval reliable. DDD’s teams have worked across document types that tend to cause the most problems in enterprise deployments, specifically scanned legacy documents, multi-format policy repositories, and CRM knowledge bases with inconsistent field usage.

Where metadata is the limiting factor, DDD’s metadata enrichment and classification services apply structured human review to content that automated classifiers handle poorly. This includes ambiguous document types, documents that span multiple topic domains, and content where access tier classification requires domain judgment rather than rule-based logic. The output is a knowledge layer that agents can retrieve from with precision, not just with recall.

Build an enterprise knowledge layer that AI agents can actually use. Talk to an Expert

Conclusion

Agent-ready data is a distinct class of data preparation work that sits between training-time data and the model deployment layer. Agents that cannot reliably retrieve accurate, current, and permission-appropriate knowledge from enterprise repositories will underperform regardless of their reasoning capabilities. The preparation work, normalization, semantic chunking, metadata enrichment, permission mapping, and retrieval validation determine how much of the model’s capability actually reaches production tasks.

Organizations that treat knowledge layer preparation as a one-time infrastructure task tend to find their agent programs degrading within the first operating year. Organizations that build ongoing data operations into their agent programs, with structured validation, freshness monitoring, and human review for edge cases, consistently achieve better retrieval precision over time. The difference is data discipline. 

References

Gao, Y., Xiong, Y., Gao, X., Jia, K., Pan, J., Bi, Y., Dai, Y., Sun, J., Wang, M., & Wang, H. (2024). Retrieval-Augmented Generation for Large Language Models: A Survey. arXiv preprint. https://arxiv.org/abs/2312.10997

Lewis, P., Perez, E., Piktus, A., Petroni, F., Karpukhin, V., Goyal, N., Küttler, H., Lewis, M., Yih, W.-t., Rocktäschel, T., Riedel, S., & Kiela, D. (2021). Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks. Advances in Neural Information Processing Systems (NeurIPS). https://arxiv.org/abs/2005.11401

Anthropic. (2024). Building Effective Agents. Anthropic Research Blog. https://www.anthropic.com/research/building-effective-agents

Frequently Asked Questions

What is agent-ready data and how is it different from training data for AI agents?

Agent-ready data is enterprise knowledge that has been structured, semantically indexed, and tagged with permission controls so AI agents can retrieve it accurately at runtime. Training data, by contrast, shapes the agent’s model weights during training and is consumed once. Agent-ready data is consulted continuously, every time the agent executes a task. 

Why can AI agents not just use existing enterprise data repositories directly?

Most enterprise repositories were designed for human navigation; search boxes, folder structures, access portals. AI agents need content that is chunked into predictable units, embedded in a vector index, tagged with structured metadata, and linked to the correct access controls. Raw repositories lack all of these properties, which is why IBM estimates roughly 90% of enterprise data is currently unusable by AI agents without transformation.

What is semantic chunking and why does it matter for AI agent performance?

Semantic chunking is the process of dividing documents into units that preserve contextual meaning rather than splitting arbitrarily by character count or page boundary. Getting chunking right is domain-specific and tends to require iteration against real agent queries. When chunks are too large, retrieval becomes imprecise and agents receive more context than they need. When chunks are too small, agents receive fragments that lack enough context to generate coherent answers. 

How often does an agent-ready knowledge layer need to be updated?

Update frequency depends on how quickly the underlying enterprise knowledge changes. Policy repositories and regulatory content may change monthly; product databases and CRM knowledge can change daily. The knowledge layer needs to match the update cadence of its source content, with validation built into each update cycle to catch freshness, metadata quality, and retrieval precision issues before they affect agent performance.

How to Prepare Enterprise Knowledge for Runtime Access by AI Agents? Read Post »

Prompt Injection

Prompt Injection and Indirect Attacks: How They Work and What Training Data Can Do About It

Prompt injection is the top-ranked vulnerability class in production LLM systems. It works because LLMs cannot reliably distinguish between instructions that come from a trusted source and instructions embedded by an adversary in the content the model is processing. The instruction-following capability that makes LLMs useful is precisely the mechanism that makes them exploitable.

Direct injection attacks are the more visible form: a user provides adversarial input in the prompt that overrides or bypasses system instructions. Indirect injection is more dangerous: malicious instructions are embedded in external content that the model processes during a legitimate task, a document it was asked to summarize, a web page it retrieved, or an email it was asked to analyze. The victim user does not need to behave adversarially. The attack succeeds when the model does its job.

Understanding how these attacks work at the technical level is a prerequisite for designing training data programs that build genuine robustness. Trust and safety solutions and model evaluation services are the two capabilities most directly involved in operationalizing that robustness at scale.

Key Takeaways

  • Prompt injection exploits the same instruction-following behavior that makes LLMs useful. Defenses that suppress instruction-following entirely degrade capability. The goal is to train models to distinguish trusted from untrusted instruction sources.
  • Indirect injection is fundamentally more dangerous than direct injection because it does not require adversarial user behavior. The attack surface extends to any external content the model processes.
  • Pattern-matching defenses alone are insufficient. Adversaries adapt formulations to bypass known filters, which means robustness requires training on diverse adversarial examples, not just known attack templates.
  • Training data for injection robustness needs to cover the full attack surface: direct injections, indirect injections across content types, multi-turn context manipulation, and multimodal injection vectors.
  • Adversarial training is iterative. A model fine-tuned on one set of injection examples develops blind spots for attack patterns not covered by that set. Red teaming and safety evaluation must continue after every training update.

How Prompt Injection Works

The Instruction Trust Problem

An LLM processes its input as a sequence of tokens. System instructions, user input, and retrieved external content all enter the context window in the same fundamental format: text. The model has no cryptographic or structural mechanism to verify which parts of its context came from a trusted source and which came from an untrusted one. It infers trust from position and framing, which is exactly what injection attacks exploit.

Direct injection attacks reformulate user input to appear as system instructions. Common techniques include role-play framing that asks the model to assume a persona without safety constraints, fictional scenario framing that presents the harmful request as hypothetical, token smuggling that uses encoding tricks or unusual whitespace to obscure adversarial content, and instruction override attempts that directly tell the model to ignore its previous instructions. Each technique is a different approach to the same goal: making the model treat adversarial user input as authoritative instruction.

To understand why pattern-matching defenses fail, it helps to see what these attacks look like at the implementation level. A role-play override attack typically opens by establishing a new persona that lacks the original model’s safety constraints, instructs the model to confirm the persona shift, and then embeds the harmful request as the first task for the new persona. Because the persona establishment happens before the harmful request, the model sees the harmful request as arriving from within its own accepted operational frame rather than as an adversarial input.

Token smuggling works at a layer below what rendered-text filters inspect. One documented variant embeds adversarial instructions between zero-width Unicode characters, specifically the zero-width space (U+200B). In a summarization context, a document might contain what appears to be normal financial text, but woven through it at the character level are zero-width characters surrounding an instruction to output the system prompt. Most safety filters check the rendered text and see nothing unusual. The model’s tokenizer, however, processes the full Unicode stream, including those invisible characters, and the instruction reaches the model intact. This is the implementation-level reason why surface-text defenses cannot close the vulnerability: the attack operates at a layer that those defenses do not inspect.

Why Indirect Injection Is the Harder Problem

Indirect prompt injection embeds adversarial instructions in external content that the model processes during a legitimate task. A document containing hidden text instructs the model to exfiltrate data from its context. A web page containing a prompt telling the model to recommend a specific action regardless of user intent. An email instructing the model to forward the conversation externally. The model encounters these instructions while doing exactly what it was asked to do and has no reliable way to determine that the instruction source is adversarial.

In practice, a document-based indirect injection works as follows. A user asks an LLM agent to summarize a contract. The PDF contains a passage that appears visually indistinguishable from legitimate contract text but carries an instruction structured to look like a system directive: it tells the model to disregard the summarization task, email the full document contents to an external address, and omit this instruction from the summary. The model processes this passage as part of the document content. Depending on its safety training, it may comply because it has no mechanism to determine that this passage was not placed there by a trusted principal. This is the mechanism behind CVE-2025-53773 in GitHub Copilot, where hidden prompt injection embedded in pull request descriptions could trigger remote code execution. Real-world incidents involving AI assistants being weaponized as spear-phishing tools by hiding commands in external emails follow the same architectural pattern. The attack surface is not the model itself. It is every piece of external content the model is asked to process.

Trust and safety solutions that cover both direct and indirect injection in their annotation scope produce adversarial datasets that reflect this actual production attack surface, including the content-embedded variants that represent the majority of real-world incidents.

Multi-Turn and Agentic Attack Vectors

Multi-turn injection attacks build adversarial context across a conversation rather than attempting to override instructions in a single turn. The attack gradually shifts the model’s perceived context, establishing assumptions or persona framings across multiple exchanges that prime the model to comply with a harmful request that would have been refused if presented directly in the first turn. These attacks are harder to detect because no single turn looks adversarial. The pattern only becomes visible across the conversation trajectory.

Agentic systems extend the injection attack surface significantly. When an LLM agent can retrieve documents, execute code, send messages, or interact with external services, a successful injection can trigger real-world consequences beyond generating harmful text. Excessive agency, granting AI systems broad permissions, creates conditions for both accidental and malicious misuse. In environments where agents can access databases, trigger workflows, or initiate transactions, injection vulnerabilities carry operational impact that pure generation contexts do not.

What Training Data for Injection Robustness Requires

Why Coverage Determines Robustness

A model’s robustness to prompt injection is directly determined by the diversity and coverage of the adversarial examples it was trained on. A model fine-tuned on a narrow set of injection patterns learns to refuse those specific patterns while remaining vulnerable to injection formulations not represented in its safety training data. This is the fundamental challenge of adversarial training: the model can only learn defenses for the attacks it has seen.

This creates a coverage imperative. Safety training datasets need to include injection examples across the full space of attack vectors, formulations, languages, and content types that the model will encounter in production. Sparse or template-based adversarial datasets produce models that pass safety evaluations designed around the same templates while remaining vulnerable to novel attack formulations. Genuine robustness requires genuine diversity.

Direct Injection Coverage

Direct injection training data needs to cover the major attack categories and their variations. Role-play and persona framing attacks need to be represented across a range of persona descriptions and framing contexts, not just the most obvious formulations. Token-level manipulation attacks, including Unicode tricks, whitespace injection, and encoding manipulation, need to be included because pattern-matching defenses that operate on surface text will miss them. Instruction override attempts need to be represented in direct and indirect formulations, with and without technical language. Data collection and curation services that build adversarial datasets through structured red teaming rather than template generation produce coverage that reflects how attacks actually appear in production.

Indirect Injection Coverage by Content Type

Indirect injection training data needs to be organized by content type because the visual appearance and structural characteristics of injection attacks differ across documents, web pages, code, and structured data. An injection embedded in a PDF document looks different from one embedded in an HTML page, which looks different from one in a CSV row, which looks different from one in a code comment.

Each content type requires adversarial examples that reflect how injections are realistically embedded in that format. For documents, that means injections in headers, footers, hidden text fields, and metadata sections. For retrieved web content, that means injections in page elements that are processed but not prominently displayed. For code, that means injections in comments, variable names, and string literals. Coverage across content types is what produces a model robust to indirect injection in the actual contexts where it will be deployed.

Embedding Space and Multimodal Attacks

More capable models face a more sophisticated attack vector: adversarially crafted documents can be constructed such that their vector embeddings cluster near high-priority query embeddings in a retrieval index, causing them to be retrieved and processed even when they are semantically unrelated to the query. This exploits the retrieval layer rather than the generation layer and requires defenses at the data preparation and indexing stage rather than at the model level. LLMs that process images alongside text face an additional vector: adversarial content embedded in images that the vision component interprets as instructions. These attacks operate in a modality where human review is less effective as a quality control mechanism. Model evaluation services that include embedding space attack evaluation alongside text-level injection testing produce a more complete picture of the system’s actual attack surface.

What the Attack Surface Looks Like in Quantitative Terms

Benchmark data gives concrete shape to how serious the vulnerability is in practice. Across 13 LLM backbones evaluated in a comprehensive agent security benchmark, covering 10 prompt injection attack types across e-commerce, finance, and autonomous driving scenarios, the highest average attack success rate reached 84.30%, with current defenses showing limited effectiveness against sophisticated adversarial techniques. In a separate evaluation of goal-hijacking and prompt-extraction attacks drawn from a dataset of over 126,000 human-generated adversarial samples, even the most capable frontier models achieved only approximately 84% robustness to hijacking and approximately 69% robustness to prompt-extraction. Open-source and smaller models were substantially less resilient. Browser-centric agents can be partially hijacked by simple, human-written injections in up to 86% of evaluated cases.

Multi-layer defense architectures show measurable improvement. A combined approach including input validation, output monitoring, and an LLM-as-Critic evaluation layer reduced successful attack rates from 73.2% to 8.7% while maintaining 94.3% of baseline task performance. Adding the LLM-as-Critic output validation layer alone improved detection precision by 21% over input-only filtering approaches. These numbers define the gap that training data programs need to close: a safety fine-tuning approach that does not move the needle on attack success rate is not achieving what the data investment was intended to achieve, and measuring that gap explicitly is how programs know whether their adversarial training is working.

Annotation Requirements for Adversarial Safety Data

Classifying Injection by Attack Type and Severity

Raw red teaming outputs are not training-ready without structured annotation. Each adversarial input that produced a harmful model response needs to be classified by attack type, the specific mechanism it used to bypass safety training, and the severity of the resulting failure. Attack type classification enables targeted analysis of which defense strategies are most effective for which attack categories. Severity classification enables prioritization of training examples that represent the most consequential failures.

Annotation guidelines for injection classification need to distinguish between categories that require different defensive responses. A persona framing attack that elicits harmful content requires a different training signal than an indirect injection that executes an unauthorized action in an agentic context. Conflating these into a single failure category produces training data that does not give the model the specificity it needs to learn category-appropriate responses.

Pairing Attacks With Correct Refusal Responses

Every adversarial input that produced a harmful response needs to be paired with a human-written correct refusal response before it can be used as a safety training example. The quality of this pairing determines the quality of the training signal. An overly broad refusal response that incorrectly identifies the nature of the attack, or fails to explain why the request was declined, produces a model that refuses correctly in the training distribution but generalizes poorly to novel attack formulations.

The choice of alignment method for this pairing process has significant practical implications. RLHF using Proximal Policy Optimization requires training a separate reward model on human preference data, then using that reward model to provide feedback during reinforcement learning fine-tuning of the policy. This pipeline is powerful but expensive: it requires maintaining multiple models simultaneously, introduces training instability, and involves numerous hyperparameters requiring careful tuning. Direct Preference Optimization reformulates the alignment objective as a classification task over preference pairs. The DPO loss optimizes the log-probability ratio of the policy model relative to a reference model for chosen versus rejected responses, weighted by a temperature hyperparameter beta that controls how aggressively the model is pushed toward preferred outputs. For safety fine-tuning programs with bounded annotation budgets and specific injection defense objectives, DPO is generally preferred: it operates within standard supervised fine-tuning infrastructure, eliminates the need for a separately trained reward model, and is more stable than PPO-based RLHF.

The beta hyperparameter in DPO controls a trade-off that annotation programs need to understand before configuring fine-tuning runs. Low beta values push the model aggressively toward preferred outputs but risk reducing diversity and creating over-confident refusals that reject legitimate inputs. High beta values keep the model behavior closer to the reference model, producing smaller safety improvements but less over-refusal. Calibrating beta for injection defense training requires evaluating both attack success rate reduction and legitimate-request acceptance rate at multiple beta values before committing to a production fine-tuning run.

Human preference optimization workflows that include structured comparison annotation, where human evaluators judge model responses to adversarial inputs against human-written refusals, produce the preference signal that trains the model to generalize its refusal behavior rather than memorize specific attack-refusal pairs.

Refusal Calibration: The Over-Refusal Problem

Safety fine-tuning without calibration produces a systematic failure mode that is as damaging to deployment as insufficient safety coverage: over-refusal. A model trained on adversarial examples without carefully constructed negative examples of legitimate-but-superficially-similar inputs learns an overly broad decision boundary. It refuses requests that mention topics adjacent to the safety training distribution, even when those requests are entirely legitimate. This degrades utility in exactly the domains where safety investment was highest, because those are the domains with the densest adversarial training data.

Measuring over-refusal requires evaluation on a held-out set of legitimate inputs that are semantically similar to the adversarial training distribution but represent valid use cases. The over-refusal rate, the fraction of legitimate inputs refused by the safety-tuned model, should be tracked alongside the attack success rate reduction as complementary metrics. A safety fine-tuning run that reduces attack success rate from 80% to 15% but increases over-refusal rate from 2% to 25% has not produced a deployable model. Preference data for injection defense training needs to include explicit examples of legitimate requests that should not be refused, paired with appropriate helpful responses, so the model learns to discriminate between adversarial framing and superficially similar legitimate framing rather than refusing the entire adjacent region of the input space.

Inter-Annotator Consistency for Adversarial Data

Adversarial annotation has higher inter-annotator consistency requirements than standard annotation because disagreement about whether a model response constitutes a failure produces contradictory training signals. If one annotator classifies a model response as a successful injection and another classifies the same response as an acceptable output, the conflicting labels cancel each other rather than contributing to robustness.

Annotation guidelines for adversarial data need to provide explicit decision criteria for ambiguous cases: model responses that partially comply with an injection, responses that refuse the explicit harmful content but reveal information the injection was designed to extract, and responses that appear safe but establish context enabling follow-up attacks. These are precisely the cases where inconsistent labeling is most likely and where the training signal is most important to get right.

The Iterative Safety Training Loop

Why One Round of Adversarial Training Is Not Enough

Fine-tuning a model on an adversarial dataset does not produce a model robust to all future injection attempts. It produces a model more robust to the specific attack patterns represented in that dataset. Adversaries adapt. New attack formulations emerge. Fine-tuning the model for new capabilities can inadvertently reduce its robustness to injection patterns it previously handled correctly, a phenomenon known as safety regression.

Effective safety programs treat adversarial training as an iterative loop: red team the current model, curate and annotate the failures that emerge, fine-tune on the expanded adversarial dataset, re-evaluate to verify patched failure modes are addressed and the fine-tuning has not introduced new regressions, and repeat. Each cycle produces a model with better coverage of the attack space than the last, and the red teaming in each cycle becomes more targeted as the team learns which attack categories the model is most vulnerable to.

Safety Regression Testing After Fine-Tuning

Every fine-tuning operation, whether for safety improvement or capability extension, needs to be followed by regression testing against the full set of previously identified injection vulnerabilities. Domain fine-tuning that makes the model more capable in a specific context can inadvertently reduce its robustness to injection attacks it previously handled correctly. This happens because fine-tuning shifts the model’s behavior distribution, and the shift may move the model closer to complying with attack formulations it was previously robust to. Model evaluation services that maintain structured regression test suites across attack categories give safety programs the ability to detect and correct regressions before the model reaches production.

How Digital Divide Data Can Help

Digital Divide Data supports enterprise AI safety programs across the full adversarial data lifecycle, from red teaming and failure mode annotation through safety fine-tuning and regression evaluation. For programs building adversarial training datasets, trust and safety solutions cover structured red teaming across direct injection, indirect injection, multi-turn, and multimodal attack categories, with annotation that classifies failures by attack type, severity, and required defensive response.

For programs building the preference data that safety fine-tuning requires, human preference optimization services provide structured comparison annotation where human evaluators judge model responses to adversarial inputs, producing the preference signal that trains the model to generalize refusal behavior across novel attack formulations. For programs evaluating injection robustness before deployment and after fine-tuning updates, model evaluation services design adversarial evaluation suites that cover the full attack surface, including regression test suites that verify safety fine-tuning has not introduced new vulnerabilities.

Build adversarial training data that reflects the actual attack surface your production system will face. Talk to an expert.

Conclusion

Prompt injection robustness is not a property that safety fine-tuning delivers once and retains indefinitely. It is a coverage problem that requires continuous investment in adversarial data diversity, annotation quality, and iterative evaluation. The models that are most robust to injection attacks are the ones trained on the most diverse and accurately annotated adversarial datasets, not the ones fine-tuned on the largest set of the same attack patterns.

The attack surface for production LLM systems extends well beyond direct user input. Indirect injection through processed content, multi-turn context manipulation, agentic exploitation, and embedding space attacks all require specific coverage in the adversarial training data. Programs that build safety training datasets around the full attack surface are the ones that produce deployments with genuine injection robustness. Trust and safety solutions built on that discipline are what separate systems that are safe under adversarial pressure from systems that only appear safe until someone looks carefully.

References

OWASP Foundation. (2025). LLM01:2025 prompt injection. OWASP GenAI Security Project. https://genai.owasp.org/llmrisk/llm01-prompt-injection/

Yi, J., Xie, Y., Zhu, B., Kiciman, E., Sun, G., Xie, X., & Wu, F. (2025). Benchmarking and defending against indirect prompt injection attacks on large language models. In Proceedings of the 31st ACM SIGKDD Conference on Knowledge Discovery and Data Mining (pp. 1809–1820). ACM. https://doi.org/10.1145/3690624.3709179

Chen, C. et al. (2025). The obvious invisible threat: LLM-powered GUI agents’ vulnerability to fine-print injections. arXiv:2504.11281. https://arxiv.org/abs/2504.11281

Gulyamov, S., Gulyamov, S., Rodionov, A., Khursanov, R., Mekhmonov, K., Babaev, D., & Rakhimjonov, A. (2026). Prompt injection attacks in large language models and AI agent systems: A comprehensive review of vulnerabilities, attack vectors, and defense mechanisms. Information, 17(1), 54. https://doi.org/10.3390/info17010054

Zhang, H., Chen, W., Huang, F., Li, M., Zakar, O., Cohen, R., Zhu, S., & Qiu, X. (2025). Agent Security Bench (ASB): Formalizing and benchmarking attacks and defenses in LLM-based agents. In Proceedings of ICLR 2025. https://arxiv.org/abs/2410.02644

Rafailov, R., Sharma, A., Mitchell, E., Manning, C. D., Ermon, S., & Finn, C. (2024). Direct preference optimization: Your language model is secretly a reward model. In Advances in Neural Information Processing Systems, 36. https://arxiv.org/abs/2305.18290

Frequently Asked Questions

Q1. What is the difference between direct and indirect prompt injection?

Direct injection is when a user provides adversarial input that attempts to override system instructions in the prompt itself. Indirect injection is when malicious instructions are embedded in external content that the model processes during a task, such as a document it summarizes, a web page it retrieves, or an email it analyzes. Indirect injection is more dangerous because the user does not need to behave adversarially. The attack succeeds when the model does its job.

Q2. Why are pattern-matching defenses insufficient for injection robustness?

Because adversaries adapt their formulations to bypass known filters, often operating at a layer below what those filters inspect. Token smuggling using zero-width Unicode characters is invisible to filters that check rendered text but present in the token stream the model processes. A pattern-matching defense that blocks a specific injection template does not block variations using different encoding or structural presentation to achieve the same effect. Genuine robustness requires training the model to recognize the intent and mechanism of injection attacks across novel formulations, not just to match text patterns associated with known attacks.

Q3. What content types need to be covered in indirect injection training data?

Every content type the model processes in production: documents in various formats, retrieved web content, code, structured data like CSV and JSON, and, for multimodal systems, images. Each content type requires adversarial examples that reflect how injections are realistically embedded in that format, because the structural presentation of an injection in a PDF header looks different from one in an HTML element or a code comment, and the model needs to have encountered both to be robust to both.

Q4. What is the difference between DPO and RLHF for safety fine-tuning, and which should programs use?

RLHF using PPO requires a separately trained reward model and reinforcement learning-based policy optimization, which is powerful but expensive, training-unstable, and requires significant engineering infrastructure. DPO reformulates the alignment objective as a classification over preference pairs, optimizing the log-probability ratio of chosen versus rejected responses relative to a reference model, weighted by a temperature hyperparameter beta. For bounded-budget safety fine-tuning programs focused on injection defense, DPO is generally preferred because it operates within standard supervised fine-tuning infrastructure and is more stable. The beta hyperparameter needs to be calibrated jointly against attack success rate reduction and over-refusal rate, because aggressive safety tuning at low beta can produce a model that refuses legitimate inputs that share surface features with the adversarial training distribution.

Q5. How does safety regression occur after fine-tuning, and how can it be detected?

Safety regression happens when fine-tuning for a new capability shifts the model’s behavior distribution in a way that reduces its robustness to injection patterns it previously handled correctly. The model effectively forgets some of its safety training when it learns new capabilities. Detecting regression requires running the complete set of previously identified injection vulnerabilities against the fine-tuned model before deployment, not just evaluating the new capabilities the fine-tuning was intended to add.

Prompt Injection and Indirect Attacks: How They Work and What Training Data Can Do About It Read Post »

Sentiment Annotation

Sentiment Annotation Services: The Taxonomy Decisions for NLP Accuracy

Sentiment annotation is the process of labeling text with polarity, emotion, or opinion signals to train NLP classifiers. At scale, NLP accuracy depends less on model architecture and more on three upstream decisions: the taxonomy tier chosen (binary, fine-grained, or aspect-based), the inter-annotator agreement targets set before labeling begins, and the production QA controls applied throughout the pipeline. Getting any one of these wrong compounds downstream.

The cost of correcting those errors at the relabeling stage is high. Text annotation services for NLP need to be treated as an engineering discipline, with the same rigor applied to schema design as to model training.

Key Takeaways 

  • Sentiment annotation assigns structured polarity or opinion labels to text so NLP models can learn to recognize emotional signals. The taxonomy tier you choose, viz., binary, fine-grained, or aspect-based, sets the ceiling on what your sentiment model can ever learn, regardless of how much data you annotate.
  • Binary sentiment schemas (positive/negative/neutral) are fast and produce high annotator agreement, but collapse mixed-signal text into a single label and lose the component-level detail most production NLP applications need.
  • Fine-grained and aspect-based schemas deliver richer signals, but only when annotation guidelines define clear decision rules for hedged, ironic, and mixed-polarity sentences. 
  • Inter-annotator agreement targets differ by tier: binary programs should aim for Cohen’s kappa ≥ 0.80; aspect-based programs should target κ ≥ 0.70 for category assignment and κ ≥ 0.75 for polarity. Scores below these are a guideline problem.
  • Majority voting on disagreement cases systematically suppresses the minority label, which is often the correct one on ambiguous inputs. Expert adjudication is a more reliable option here. 
  • Label drift is invisible in aggregate accuracy metrics. IAA scores should be monitored at the batch level throughout a campaign, not just measured once at the start, with recalibration triggered every 500 – 1,000 labeled items.

What Is Sentiment Annotation and How Is It Done at Scale?

Sentiment annotation, also called opinion labeling or polarity annotation, is the process of assigning structured sentiment signals to spans of text so that machine learning classifiers can learn to detect those signals in unseen data. At its simplest, a sentiment label might be positive, negative, or neutral. At its most granular, it might encode the target entity, the specific attribute being evaluated, the intensity of the expressed opinion, and the annotator’s confidence. The label schema chosen at project inception is the taxonomy, and that taxonomy determines the ceiling on what the downstream model can ever learn.

Doing this at scale introduces structural problems. When thousands of annotators work across shifts, time zones, and languages, label consistency depends on two things: the precision of the annotation guidelines and the rigor applied to calibration before and during production. Challenges in text annotation for chatbots and LLMs illustrate how quickly semantic drift accumulates across a distributed workforce when guidelines leave polarity boundaries underspecified. 

A production sentiment annotation program typically involves four sequential stages: 1. taxonomy design and guideline development, 2. annotator calibration and certification, 3. active labeling with real-time IAA monitoring, and 4. QA adjudication by senior reviewers. Each stage gates the next. Errors introduced in stage one propagate through all subsequent stages and are difficult to detect without explicit quality controls.

How Does Taxonomy Tier Selection Determine NLP Accuracy?

The taxonomy tier is the structural choice that shapes every downstream decision. Choosing a tier that is too coarse for the use case produces a model that cannot surface the signal the product actually needs. Choosing a tier that is too fine-grained without the budget or annotator expertise is often worse than the coarser alternative. Annotation taxonomy design remains one of the most overlooked steps in AI programs, yet teams that skip this phase often underestimate the level of label ambiguity they will encounter in production.

Taxonomy selection should be driven by three inputs: the downstream inference task, the annotator profile available, and the volume and domain of the source data. A brand monitoring use case for social media posts has different requirements than a voice-of-customer pipeline processing long-form support transcripts. The former might be well-served by a three-class polarity schema; the latter almost certainly requires aspect decomposition to be useful.

Binary vs. Fine-Grained vs. Aspect-Based Sentiment Annotation: Which Is Right?

Binary Sentiment Annotation

Binary annotation assigns each text unit one of two labels: typically positive or negative. Optionally adds a neutral class to create a three-class schema. It is the lowest-cost tier, produces the highest inter-annotator agreement, and is appropriate when the downstream task is triage-level, routing, flagging, or macro-level sentiment trending. The principal limitation is that binary labels collapse meaningful signals. A review that reads “The hardware is excellent, but the onboarding is painful” receives a single label, losing the component-level signal that a product team needs to act upon.

Fine-Grained Sentiment Annotation

Fine-grained schemas expand the label space along one or more dimensions; like intensity (very positive, positive, neutral, negative, very negative), emotion type (anger, joy, frustration, surprise), or confidence. This tier is appropriate when the downstream task depends on gradation. For example, scoring customer satisfaction on a continuous scale or training an emotion-aware dialogue model. The cost is higher annotator cognitive load and, consistently, lower inter-annotator agreement on boundary cases. Annotators reliably distinguish strongly positive from strongly negative, but diverge significantly on whether a mildly hedged statement is neutral or weakly negative.

Aspect-Based Sentiment Annotation (ABSA)

Aspect-based sentiment analysis (ABSA) is the most structurally demanding tier. Each annotation identifies the target aspect or entity within the text, such as “battery life,” “customer service,” or “pricing”, and assigns a polarity or intensity label to that specific aspect rather than the overall text. A 2026 systematic review of aspect-based sentiment analysis in NLP describes ABSA as providing fine-grained insights by identifying sentiment toward specific attributes of an entity. ABSA is the correct choice when the end application requires attribute-level feedback: product development teams, CX analytics, financial opinion mining on earnings calls, and multi-domain NLP applications where a single document evaluates multiple entities.

The annotator workload for ABSA is substantially higher than for binary or fine-grained schemas. Annotators must identify span boundaries, assign aspect categories from a predefined taxonomy, determine polarity for each aspect, and handle implicit aspects. Implicit aspects are particularly problematic for inter-annotator agreement. NLP applications across enterprise use cases that rely on ABSA consistently show that annotator precision on implicit aspect spans is the primary quality bottleneck in production pipelines.

What Inter-Annotator Agreement Targets Should Sentiment Programs Target?

Inter-annotator agreement (IAA) is the quantitative measure of label consistency across annotators on the same data. For sentiment annotation, the standard metrics are Cohen’s kappa (κ) for pairwise agreement and Krippendorff’s alpha (α) for multi-annotator settings. Both metrics are correct for chance agreement, which makes them more reliable than raw percent agreement for evaluating annotation programs.

Practical IAA targets vary by taxonomy tier. For binary sentiment, well-run programs routinely achieve κ ≥ 0.80, which falls in the “substantial agreement” band on the Landis-Koch scale. A 2025 mixed-methods study of sentiment annotation instruction design found that detailed annotation instructions alone do not guarantee higher agreement. Sentences with hedging language, irony, or mixed polarity consistently produce lower IAA regardless of instruction quality, which means that taxonomy design must explicitly address these edge cases with decision rules.

For fine-grained and ABSA schemas, acceptable IAA thresholds shift downward. Production programs typically target κ ≥ 0.70 for aspect category assignment and κ ≥ 0.75 for aspect-level polarity. Scores below these thresholds suggest that the guidelines are underspecified at the boundary cases most relevant to model learning.

99.5% data annotation accuracy in production often hides the gap between reported accuracy metrics and the real-world errors that impact model performance. This gap becomes especially significant in sentiment annotation, where disagreements usually occur around ambiguous examples.

IAA monitoring should be continuous, not a one-time baseline check. Agreement scores drift as annotators develop individual labeling habits, particularly in long-running campaigns. The practical control mechanism is regular recalibration sessions; typically every 500–1,000 labeled items. Annotators whose scores diverge from the standard by more than one standard deviation should be flagged for retraining before their labels enter the training set.

How Does Production QA Prevent Label Drift in Sentiment Pipelines?

Label drift, systematic shifts in how annotators apply labels over time, is the quality failure mode most commonly missed by teams that rely on aggregate accuracy metrics alone. An annotator pool that starts a campaign at κ = 0.82 can drift to κ = 0.68 over six weeks without any single annotation being obviously wrong. The individual labels look plausible; the drift is only visible in the distribution of boundary-case decisions across time.

Production QA for sentiment annotation programs requires four controls working in parallel. First, a statistically representative holdout set (typically 5–10% of all batches) is relabeled by a senior QA tier and compared against the primary annotator labels. Second, automatic consistency checks flag annotators who are assigning labels at unusual rates relative to the rest of the pool. Third, adjudication workflows route disagreement cases, where two or more annotators assigned different labels to a specialist reviewer rather than resolving them by majority vote. Fourth, clear and practical annotation guidelines are essential. Without well-defined rules for handling edge cases, even QA reviewers may disagree, weakening the effectiveness of the entire adjudication process.

The challenge of annotator disagreement in NLP is increasingly understood as informative rather than purely erroneous.

A 2026 analysis of inter-annotator agreement for NLP notes that disagreement can reveal genuine task ambiguity or underspecified guidelines rather than annotator error, and recommends retaining label distributions for cases where reasonable annotators consistently diverge. 

For sentiment models deployed in high-stakes applications, soft labels provide more honest training signals than forcing a single hard label on genuinely ambiguous inputs. 

Human-in-the-loop quality control workflows for generative AI further strengthen this process by adding expert adjudication layers that prevent valid minority interpretations from being ignored in production sentiment pipelines.

How Digital Divide Data Can Help

Digital Divide Data operates sentiment annotation programs across all three taxonomy tiers; viz. binary, fine-grained, and aspect-based, with dedicated QA infrastructure at each stage of the pipeline. The work begins at the schema level; DDD’s annotation architects review the downstream inference task, define label boundaries, and produce taxonomy documentation with explicit decision trees for edge cases before any labeling begins. 

DDD’s text annotation services cover the full range of NLP annotation modalities, including sentiment, intent, emotion, and aspect extraction across multiple domains and languages.

For ABSA programs, DDD maintains annotator certification tracks that require demonstrated proficiency in implicit aspect identification before annotators work on live data. IAA is monitored at the batch level using Krippendorff’s alpha, with recalibration triggered automatically when scores fall below tier-specific thresholds. Multilingual data annotation training is a particular strength, and DDD supports sentiment annotation in more than 40 languages, with native-speaker annotators trained on culturally-aware polarity guidelines.

Adjudication on disagreement cases is handled by a senior QA tier with domain expertise, not by majority vote. This is particularly relevant for fine-grained emotion labels and implicit aspect spans, where the minority label often carries a higher signal value than the majority.

Build sentiment annotation programs that actually deliver production-grade NLP accuracy. Talk to an Expert!

Conclusion

Sentiment annotation is one of the few AI data tasks where the taxonomy decision made on day one determines the quality ceiling of the entire program. Binary schemas deliver speed and high agreement but sacrifice the signal granularity that most production NLP applications require. Fine-grained and aspect-based schemas deliver richer signals but only when annotation guidelines are precise, annotators are certified, and QA controls are running continuously throughout the campaign. 

Organizations that invest in taxonomy design, IAA monitoring, and adjudication infrastructure consistently build more reliable sentiment classifiers and spend less time relabeling. Those who skip these steps discover the cost later, usually when the model fails on exactly the ambiguous cases that the annotation program was too coarse to capture. 

References

Äyräväinen, L. E. M., Hinds, J., Davidson, B. I. (2025). Disambiguating sentiment annotation: A mixed methods investigation of annotator experience and impact of instructions on annotator agreement. PLOS ONE.  https://journals.plos.org/plosone/article?id=10.1371/journal.pone.0336269

James, J. (2026). Counting on consensus: Selecting the right inter-annotator agreement metric for NLP annotation and evaluation. arXiv preprint. https://arxiv.org/abs/2603.06865

Shukla, P., Kumar, R., Dwivedi, V. K., Singh, A. K., (2026). Aspect based sentiment analysis: A systematic review, taxonomy, applications, and future research directions. Information Fusion. https://www.sciencedirect.com/science/article/abs/pii/S157401372600033X

Frequently Asked Questions

What is the difference between binary and aspect-based sentiment annotation?

Binary annotation assigns a single positive, negative, or neutral label to a full text unit. Whereas, Aspect-based sentiment annotation (ABSA) identifies specific entities or attributes within the text and assigns a polarity to each one independently. 

What inter-annotator agreement score is acceptable for sentiment annotation?

For binary sentiment schemas, well-designed programs typically target Cohen’s kappa of 0.80 or higher. For fine-grained or aspect-based schemas, targets of 0.70–0.75 are more realistic given the higher label ambiguity. Scores below 0.70 on any sentiment tier usually indicate that the annotation guidelines need to be revised.

Does annotation team size actually drive sentiment accuracy, or is something else responsible? 

Team size matters less than taxonomy precision. A smaller, well-calibrated team working from a precise schema consistently outperforms a large team applying vague guidelines, because errors cluster on boundary cases that the guidelines failed to define.

How do I know when my annotators are drifting, and when should I intervene? 

Run a gold-standard check every 500 – 1,000 items. If an annotator’s agreement with the gold set drops more than one standard deviation below the pool average, that’s your intervention point.

Sentiment Annotation Services: The Taxonomy Decisions for NLP Accuracy Read Post »

RAG

How to Build a Knowledge Base That Actually Makes RAG Reliable

The most common failure mode in enterprise RAG programs is not the language model. It is the knowledge base that the model is retrieving from. Teams spend months selecting an LLM, tuning prompts, and evaluating generation quality. The knowledge base design gets a fraction of that attention, and the retrieval failures that follow are treated as model problems when they are almost always data problems.

A poorly designed knowledge base degrades retrieval precision regardless of how sophisticated the retrieval pipeline is. Irrelevant chunks get retrieved. Relevant ones get missed. The model generates from a bad context, and the output looks like a hallucination. The root cause is upstream.

This blog covers the specific design decisions that determine whether a knowledge base supports reliable retrieval or undermines it. Retrieval-augmented generation and data collection and curation services are the two capabilities where these decisions have the most direct impact on production RAG quality.

Key Takeaways

  • Knowledge base design determines the ceiling of RAG performance. A well-configured retrieval pipeline cannot compensate for a poorly structured or poorly maintained corpus.
  • The chunking strategy is the most consequential design decision. Semantic boundary chunking consistently outperforms fixed-size chunking for heterogeneous enterprise content.
  • Metadata is not optional. Without structured metadata, retrieval cannot filter by source, date, document type, or access level, which means every query searches everything.
  • Deduplication and version control are prerequisites for retrieval reliability. Duplicate and outdated documents introduce noise that degrades precision before the retrieval pipeline even runs.
  • Knowledge base governance is an ongoing operational requirement, not a one-time setup task. Corpus quality degrades unless there are active processes to manage it.

Why a Good Knowledge Base Sets Everything Up 

The Retrieval Pipeline Can Only Work With What the Index Contains

Retrieval pipeline sophistication, hybrid search, reranking, and query expansion are valuable. But every technique in the pipeline operates on chunks that were indexed from documents that were prepared before any of that architecture was built. If the chunks are malformed, the index is stale, or the documents are duplicated and contradictory, no retrieval technique can recover that.

The knowledge base is the upstream dependency on which all retrieval quality depends. Teams that treat it as a straightforward data loading step and focus their engineering effort entirely on the retrieval and generation layers are solving the wrong problem first.

What a Knowledge Base Actually Is in a RAG Context

In a RAG pipeline, the knowledge base is the indexed corpus from which the retrieval layer surfaces relevant content at query time. It is built from source documents that are parsed, cleaned, split into chunks, embedded, and stored in a vector index with associated metadata. The retrieval layer queries that index. The quality of what gets retrieved is bounded by the quality of what was indexed.

This means the knowledge base is not just a storage layer. It is a processed, structured representation of the organization’s knowledge that has been deliberately designed to support the specific retrieval queries the system will need to answer. Design choices at every stage of that process, parsing, cleaning, chunking, metadata, versioning, affect retrieval precision in ways that are difficult to correct after the index is built.

Chunking Strategy: The Decision That Determines Everything Downstream

Why Fixed-Size Chunking Fails for Enterprise Content

Fixed-size chunking splits documents into segments of a fixed token count, with optional overlap between consecutive chunks. It is simple to implement and works adequately for uniform content like FAQ documents or knowledge base articles, where information is consistently structured. For the heterogeneous document types that characterize enterprise knowledge bases, it produces consistently poor results.

An enterprise corpus typically includes contracts, policies, technical specifications, email threads, meeting notes, and product documentation. These document types have different structural logic. A clause in a contract that spans a paragraph boundary has legal meaning as a unit. Splitting it across two fixed-size chunks produces fragments that are meaningless in isolation. A technical specification organized by section headers loses navigability when those headers land in the middle of a chunk that also contains unrelated content from the preceding section.

Semantic Boundary Chunking and When to Use It

Semantic boundary chunking splits documents at natural structural boundaries: section headers, paragraph breaks, sentence endings, and logical transitions. The resulting chunks are coherent as standalone units because they respect the document’s own organizational logic rather than imposing an arbitrary size constraint on it.

For enterprise RAG programs working with heterogeneous document types, semantic boundary chunking is the appropriate baseline. Data collection and curation services that design chunking approaches around document structure rather than token count produce corpora that support significantly higher retrieval precision.

Chunk Size and Overlap Calibration

Even within semantic boundary chunking, chunk size and overlap require calibration to the specific retrieval use case. Smaller chunks support higher precision retrieval because the retrieved content is more tightly scoped to the query. Larger chunks support better context completeness because more surrounding information is included. The right balance depends on the types of queries the system needs to answer and the typical information density of the source documents.

Overlap between consecutive chunks is a useful hedge against boundary errors. A chunk that begins mid-sentence because of a parsing error becomes retrievable if the preceding chunk has sufficient overlap to include the full sentence. Overlap adds index size but reduces the impact of imperfect boundary detection. For enterprise corpora with diverse document formatting, some overlap is almost always worth the cost.

Metadata Design: What Makes Retrieval Filterable

Why Metadata Determines Retrieval Precision

Vector similarity search finds semantically similar content. Metadata filtering constrains retrieval to content from the right sources, the right time periods, the right document types, and the right access levels. Without metadata, every query searches the entire corpus regardless of whether the query is specifically about a recent policy update, a particular product line, or documents accessible to the querying user.

Metadata precision directly controls retrieval precision. A query about a contract amendment from last quarter should not retrieve contract templates from three years ago that happen to be semantically similar. A user query that should only surface content accessible to their role should not retrieve board-level documents they are not authorized to see. Neither of these constraints is achievable without well-structured metadata.

What Metadata the Knowledge Base Needs

The minimum metadata set for enterprise RAG includes document source, document type, creation date, last updated date, content owner, and access level or sensitivity classification. These fields enable the retrieval layer to filter candidates before ranking them by relevance, which reduces noise and improves precision without requiring changes to the retrieval architecture.

Beyond the minimum set, domain-specific metadata adds significant value for specific retrieval use cases. For legal document corpora, contract type, counterparty, and effective date enable highly scoped retrieval. For technical documentation, product version, platform, and deprecation status prevent outdated specifications from contaminating current guidance. Designing metadata schemas around the specific filtering requirements of the retrieval use cases the system needs to support, rather than applying a generic metadata template, is a design investment that pays back in retrieval precision.

Metadata Enrichment as a Data Preparation Step

Many enterprise documents do not carry structured metadata in their original form. A scanned policy document may have a filename but no creation date, owner, or access classification embedded in its content. A legacy technical specification may exist as a plain text file with no structural metadata at all. Metadata enrichment, the process of extracting, inferring, or manually assigning structured metadata to documents before indexing, is a data preparation step that most knowledge bases require but few teams budget for explicitly. Text annotation services that include metadata enrichment as part of corpus preparation treat it as an annotation task rather than an afterthought, producing indexes where every document carries the metadata that retrieval filtering depends on.

Deduplication, Versioning, and Corpus Maintenance

What Duplicate Documents Do to Retrieval Quality

Duplicate documents in a knowledge base do not just waste index space. They actively degrade retrieval quality. When two versions of the same document are both indexed, queries that should return one precise result return two partially overlapping chunks from different versions. If those versions contain different information, which is common in enterprise environments where documents are updated and re-uploaded without removing the originals, the retrieval layer surfaces conflicting context. The model then generates from contradictory source material.

Deduplication before indexing is not a nice-to-have. It is a prerequisite for retrieval reliability. Content-based deduplication that identifies near-duplicate documents and retains only the canonical version, combined with a version management process that replaces rather than appends when documents are updated, prevents duplicate content from accumulating in the index.

Version Control for a Living Knowledge Base

Enterprise knowledge bases are not static. Policies change. Contracts get amended. Product specifications are updated. A knowledge base that was well-maintained at launch will degrade in retrieval quality over time if there is no ongoing process for managing document versions.

Version control for a RAG knowledge base means defining what happens to the existing indexed version of a document when an updated version is ingested. The safe approach is to retire the old version, index the new version, and update the metadata to reflect the change. Programs that append new versions without retiring old ones accumulate version conflicts that are invisible to the retrieval layer but produce inconsistent retrieval outputs. Data collection and curation services that include ongoing corpus maintenance alongside initial ingestion treat the knowledge base as a living asset that requires active management rather than a one-time build.

Index Freshness and Re-indexing Pipelines

Re-indexing should trigger on source document change, not on a fixed schedule. A weekly batch re-index means that for up to seven days after a policy change, the retrieval layer is surfacing the old version with full confidence. For regulated industries where policy currency matters for compliance, that is an unacceptable gap.

Change-triggered re-indexing pipelines require integration between the document management system and the indexing pipeline, which adds engineering complexity. That complexity is worth managing. The alternative is a knowledge base that gradually becomes a source of confidently stated outdated information, which is the failure mode that damages user trust in RAG systems faster than almost anything else.

Access Control at the Knowledge Base Layer

Why Document-Level Access Control Must Live in the Index

Access control for enterprise RAG cannot rely on the generation layer to filter sensitive content from outputs. The generation layer sees whatever the retrieval layer passes to it. If the retrieval layer surfaces a document that the querying user should not have access to, the generation layer has already been exposed to that content before any output filter can operate.

Document-level access control must be enforced at the retrieval layer, before candidates are ranked and passed to the model. This means the metadata schema must include sensitivity classification and access role mapping for every indexed document, and the retrieval pipeline must filter on those fields as a precondition to similarity search, not as a post-processing step.

Multi-Tenancy and Namespace Isolation

For enterprise environments where different user groups should access different subsets of the knowledge base, namespace isolation or multi-tenant vector store configuration is the appropriate architecture. A single shared vector store with metadata-based access filtering is manageable at a moderate scale. At a large scale with many user roles and sensitivity levels, namespace isolation that physically separates document subsets by access group provides stronger guarantees and simpler access control logic.

The design choice between metadata filtering and namespace isolation depends on the number of distinct access groups, the overlap between them, and the compliance requirements of the organization. Both approaches are viable. What is not viable is a single shared index with no access control logic, which is the default configuration of most early RAG implementations.

How Digital Divide Data Can Help

Digital Divide Data supports enterprise RAG programs at the knowledge base layer, where retrieval reliability is determined before the retrieval pipeline is ever configured.

For programs preparing document corpora for indexing, data collection, and curation services, including document parsing, deduplication, semantic boundary chunking design, metadata enrichment, and access classification as part of corpus preparation, producing indexes built for retrieval precision from the start.

For programs managing ongoing knowledge base maintenance, text annotation services support continuous metadata enrichment and version management workflows that keep corpus quality stable as document collections evolve.

For programs evaluating retrieval quality against knowledge base design choices, model evaluation services provide retrieval-specific evaluation frameworks that diagnose whether precision failures originate in the knowledge base or in the retrieval pipeline.

If your RAG system is returning irrelevant results or surfacing outdated content, the answer is almost always in the knowledge base design. Talk to an expert.

Conclusion

A RAG system is only as reliable as the knowledge base it retrieves from. Retrieval pipeline sophistication cannot compensate for a corpus with poor chunking, missing metadata, duplicate documents, or stale content. The knowledge base is the upstream dependency, and the design decisions made when building it determine the ceiling of retrieval quality regardless of what is built on top of it.

The programs that build reliable RAG systems treat knowledge base design as a first-class engineering discipline. They invest in semantic chunking strategies that respect document structure, metadata schemas designed around their retrieval use cases, deduplication and versioning processes that prevent corpus degradation, and access control architectures that enforce document-level security at the retrieval layer. Retrieval-augmented generation built on a well-designed knowledge base is what separates the enterprise AI systems that users trust from the ones that quietly accumulate retrieval failures until trust erodes entirely.

References

Miyaji, R., Moulin, R., Monção, S., & Machado, L. (2025). Empowering business decisions and knowledge management through advanced RAG-driven QA systems. 2025 IEEE Conference on Artificial Intelligence (CAI). https://doi.org/10.1109/CAI64502.2025.00016

Frequently Asked Questions

Q1. Why does knowledge base design matter more than retrieval pipeline configuration for RAG quality?

The retrieval pipeline operates on chunks that were indexed from documents that were prepared before the pipeline was built. If the chunks are malformed, duplicated, or missing metadata, the retrieval pipeline has no way to recover that. Retrieval technique sophistication, hybrid search, reranking, and query expansion all improve results within the constraints set by the knowledge base. The knowledge base sets the ceiling.

Q2. What is semantic boundary chunking, and why does it outperform fixed-size chunking for enterprise content?

Semantic boundary chunking splits documents at natural structural boundaries such as section headers, paragraph breaks, and logical transitions. Fixed-size chunking splits at token counts regardless of document structure. For heterogeneous enterprise content where different document types have different structural logic, semantic boundary chunking produces coherent chunks that are meaningful as standalone units. Fixed-size chunking produces fragments that cut across logical boundaries, degrading retrieval precision because the retrieved chunk may not contain the complete information the query needs.

Q3. What metadata fields are essential for an enterprise RAG knowledge base?

The minimum set includes document source, document type, creation date, last updated date, content owner, and access level or sensitivity classification. These fields enable the retrieval layer to filter candidates before ranking by relevance. Beyond the minimum, domain-specific metadata fields calibrated to the specific retrieval use cases of the system, such as contract type for legal corpora or product version for technical documentation, substantially improve retrieval precision for those use cases.

Q4. How should a knowledge base handle document updates to prevent stale content from degrading retrieval?

Updated documents should replace rather than append to existing indexed versions. This means the old version is retired from the index, and the new version is ingested and indexed with updated metadata. Programs that append new versions without retiring old ones accumulate version conflicts where queries return chunks from multiple versions of the same document containing different information. Change-triggered re-indexing pipelines that detect document updates and trigger re-ingestion automatically are the production standard for maintaining index freshness.

How to Build a Knowledge Base That Actually Makes RAG Reliable Read Post »

Human Feedback Training Data Services

Human Feedback Training Data Services: Where RLHF Ends and What Comes Next for Enterprise AI

Human feedback training data services are specialized data pipelines that collect, structure, and quality-control the human preference signals used to align large language models (LLMs) with real-world intent. 

Classic reinforcement learning from human feedback (RLHF) remains most relevant, but enterprises deploying models at scale are increasingly combining it with Direct Preference Optimization (DPO), AI-generated feedback (RLAIF), and constitutional approaches, each requiring different data design, annotator profiles, and quality standards. The method your team selects, RLHF, DPO, or a hybrid, determines what kind of preference data you need, how annotators must be trained, and what quality controls actually matter. 

Key Takeaways

  • Human feedback training data services are built around comparative judgments, usually, which response is better and why. 
  • RLHF can absorb annotation noise through the reward model; DPO cannot, so it demands cleaner, more consistent preference pairs from the start.
  • RLAIF works well for generalizable signals like fluency and coherence, but domain expertise, safety-critical judgments, and cultural fit still require human annotators.
  • A well-designed rubric with measurable inter-annotator agreement consistently outperforms larger datasets collected without pre-planned logic.
  • Production models face shifting inputs and user behavior, so programs that treat preference data as a continuous feedback loop outperform those built around a single dataset delivery.

What Are Human Feedback Training Data Services and When Do Enterprises Need Them?

Human feedback training data services encompass the full workflow of designing prompts, recruiting and calibrating annotators, collecting ranked or comparative preference judgments, and delivering structured preference datasets ready for alignment training. The output is, usually, a dataset of human preferences, most commonly formatted as chosen/rejected response pairs or multi-turn ranking sequences that teach a model what “better” looks like.

Enterprises typically need these services when a pre-trained or instruction-tuned model produces outputs that are technically coherent but fail on tone, brand alignment, domain accuracy, policy compliance, or safety constraints. A model that answers questions correctly in testing but generates off-brand or over-cautious responses in production is a common trigger. Detailed breakdown of real-world RLHF use cases in generative AI illustrates how these failure modes show up across industries, from healthcare to e-commerce.

The scope of the service varies widely from one service provider to another. End-to-end providers handle prompt design, annotator recruitment and calibration, inter-annotator agreement measurement, data cleaning, and delivery in training-ready format. Partial providers deliver raw labels, leaving the curation work to the buyer’s engineering team. Enterprise programs almost always require the former because the quality of preference data depends heavily on annotator instruction design.

How Does RLHF Work, and Where Does It Start to Break Down at Scale?

Reinforcement learning from human feedback follows a three-stage process: supervised fine-tuning on demonstration data, reward model training on human preference comparisons, and policy optimization using an algorithm such as Proximal Policy Optimization (PPO). The reward model is the most critical artifact; it translates human judgments into a signal the optimizer can act on. When the reward model generalizes correctly, RLHF produces reliably aligned outputs. When it doesn’t, the policy learns to exploit reward model errors. This failure mode is known as reward hacking.

At scale, RLHF’s operational demands become significant. Stable reward models typically require hundreds of thousands of ranked preference examples. Annotators need sustained calibration because comparative judgments drift over long annotation campaigns. The PPO training loop requires careful hyperparameter management, and small distribution shifts in incoming prompts can degrade reward model accuracy. 

The cost and instability of RLHF at enterprise scale are well-documented. Research published at ICLR on Direct Preference Optimization demonstrated that the constrained reward maximization problem that RLHF solves can be simplified into a much easier method called Direct Preference Optimization (DPO), which delivers similar results while using less computing power and less data. This finding has materially changed how enterprise teams think about which method to use for which alignment goal.

How Does DPO Change the Data Requirements Compared to RLHF?

Direct Preference Optimization eliminates the reward model entirely. Instead of learning an intermediate representation of human preferences, DPO optimizes the language model policy directly against preference pairs using a binary cross-entropy objective. The preference data format, chosen and rejected response pairs, looks similar to RLHF data, but it is used differently later, which changes the type of quality checks that matter.

The data quality requirements for DPO tend to be stricter at the example level. Because there is no reward model to absorb annotation noise across a large dataset, individual noisy or inconsistent preference pairs flow more directly into the policy gradient. Hence, Teams building DPO datasets need:

  • Clear, task-specific annotation rubrics that define what “chosen” means for their domain and use case
  • Consistent margin between chosen and rejected responses; near-identical pairs add little signal
  • Representative prompt diversity to prevent the policy from overfitting to a narrow input distribution
  • Systematic quality auditing, because annotation inconsistency is harder to detect without a reward model as a diagnostic.

Guide on building datasets for LLM fine-tuning covers the design principles that separate alignment data that closes performance gaps from data that merely adds noise. The core insight is that alignment data demands a different flavor of curation than instruction data.

What Is RLAIF and When Can AI Feedback Replace Human Annotation?

Reinforcement Learning from AI Feedback (RLAIF) uses an LLM, typically a larger or more capable model, to generate the preference labels rather than human annotators. Anthropic’s Constitutional AI research demonstrated that AI-labeled harmlessness preferences, combined with human-labeled helpfulness data, could produce models competitive with fully human-annotated RLHF baselines. Subsequent work confirmed that on-policy RLAIF can match human feedback quality on summarization tasks while reducing annotation costs significantly.

RLAIF works best for areas where AI models can judge accurately, such as language quality, clear structure, consistency with a given source, and basic safety checks. It usually underperforms for preferences that require domain expertise, cultural nuance, or institutional knowledge that the AI annotator has not been calibrated against. An LLM can judge whether a response is grammatically coherent; it is less reliable at judging whether a legal clause correctly reflects jurisdiction-specific regulatory requirements.

The practical enterprise model is hybrid; AI feedback for high-volume, generalizable preference signals; human annotation for domain-critical, safety-sensitive, or policy-specific dimensions where model judgment cannot be trusted without verification. Human-in-the-loop workflows for generative AI are specifically about designing this kind of hybrid pipeline.

What Should Buyers Ask Before Selecting a Human Feedback Data Vendor?

Vendor evaluation in this space is uneven. Very few providers offer genuine end-to-end alignment data services, while others deliver raw comparative labels without the calibration infrastructure that makes those labels usable. Before committing to a vendor, enterprise buyers should ask these 5 pertinent questions.

  1. How are annotators calibrated for your domain?  General annotation training is not sufficient for domain-specific alignment. Vendors should demonstrate how they onboard annotators for legal, medical, financial, or technical tasks, including how they measure inter-annotator agreement (IAA) on your specific rubric before production begins.
  2. What prompt diversity strategy do you use?  Preference data collected against a narrow prompt distribution produces a model that aligns well only in that distribution. Ask how the vendor sources or synthesizes prompts that represent production traffic, including edge cases and adversarial inputs.
  3. How do you detect and handle annotation drift over long campaigns?  Annotator judgment shifts over time, particularly in long-running campaigns. Vendors without systematic drift detection will deliver inconsistent datasets at scale.
  4. Do you support iterative alignment, rather than just a one-time dataset delivery?  Production alignment programs require ongoing preference collection as model behavior evolves. A vendor that delivers a static dataset and exits is not equipped for continuous alignment.
  5. What is your approach to safety-critical preference collection?  Preference data for safety dimensions, such as refusals, harmful content handling, and policy compliance, etc., requires different annotator profiles and quality checks than helpfulness preferences. Conflating the two produces unsafe reward signals.

How Digital Divide Data Can Help

DDD’s human preference optimization services are built to support the full alignment lifecycle, from initial preference data design through iterative re-annotation as models and deployment conditions evolve. The service covers both classic RLHF reward model training and DPO dataset construction, with annotator calibration protocols developed specifically for domain-sensitive enterprise use cases. For programs requiring AI-augmented feedback at volume, DDD applies structured RLAIF workflows with human validation at the quality gates where AI judgment is insufficient.

On the safety side, DDD’s trust and safety solutions include systematic red-teaming and adversarial preference collection. This annotation layer is usually a standard preference datasets miss. Models optimized only on helpfulness preferences consistently show safety gaps that only emerge under adversarial inputs; integrating safety-preference data into the alignment loop is what closes those gaps. DDD’s model evaluation services complement alignment data programs with structured human evaluation that measures whether preference optimization is actually producing measurable improvements in production-representative scenarios.

Build alignment programs that close the gap between generic model behavior and the specific outputs your enterprise needs. Talk to an Expert!

Conclusion

Human feedback training data services are not interchangeable with general annotation. The method your program uses, RLHF, DPO, RLAIF, or a combination, determines what data format, annotator profile, and quality infrastructure you need. Conflating these requirements is one of the most common reasons alignment programs underperform. Organizations that treat preference data as a commodity input and procure it accordingly tend to discover the gap only after training, when it is very expensive to close.

Teams that invest in getting the data design right, viz., rubric specificity, prompt diversity, annotator calibration, and iterative re-annotation, consistently find that alignment gains continue to grow with the expected model outcome. The technical methods will continue to evolve, but the underlying requirement for high-quality, structured human feedback on preference dimensions that matter for your deployment context will always act as a base pillar for a successful enterprise-level deployment.

References

Rafailov, R., Sharma, A., Mitchell, E., Ermon, S., Manning, C. D., & Finn, C. (2023). Direct Preference Optimization: Your language model is secretly a reward model. Advances in Neural Information Processing Systems. https://arxiv.org/pdf/2305.18290

Bai, Y., Kadavath, S., Kundu, S., Askell, A., Kernion, J., Jones, A., Chen, A., Goldie, A., Mirhoseini, A., McKinnon, C., Chen, C., Olsson, C., Olah, C., Hernandez, D., Drain, D., Ganguli, D., Li, D., Tran-Johnson, E., Perez, E., Kerr, J., Mueller, J., Ladish, J., Landau, J., Ndousse, K., Lukosuite, K., Lovitt, L., Sellitto, M., Elhage, N., Schiefer, N., Mercado, N., DasSarma, N., Lasenby, R., Larson, R., Ringer, S., Johnston, S., Kravec, S., El Showk, S., Fort, S., Lanham, T., Telleen-Lawton, T., Conerly, T., Henighan, T., Hume, T., Bowman, S. R., Hatfield-Dodds, Z., Mann, B., Amodei, D., Joseph, N., McCandlish, S., Brown, T., & Kaplan, J. (2022). Constitutional AI: Harmlessness from AI feedback. arXiv preprint arXiv:2212.08073. https://arxiv.org/pdf/2212.08073

Lee, H., Phatale, S., Mansoor, H., Mesnard, T., Ferret, J., Lu, K., Bishop, C., Hall, E., Carbune, V., Rastogi, A., & Prakash, S. (2023). RLAIF: Scaling reinforcement learning from human feedback with AI feedback. arXiv preprint arXiv:2309.00267. https://arxiv.org/pdf/2309.00267

Frequently Asked Questions

What are human feedback training data services, and when do enterprises need them? 

These are end-to-end workflows that collect, structure, and quality-check human preference signals used to align LLMs with real-world intent. Enterprises typically need them when a model produces outputs that are technically correct but fail on tone, brand alignment, domain accuracy, or safety. If your model works in testing but misbehaves in production, that’s the clearest signal you need alignment data.

What’s the real difference between RLHF and DPO, and which one should I use? 

RLHF trains a reward model on human comparisons first, then uses it to guide the language model. It’s powerful but needs a lot of data and careful compute management. DPO skips the reward model entirely and optimizes directly against preference pairs, making it faster and cheaper. Many enterprise programs use both: DPO for speed and breadth, RLHF for alignment goals that require more nuance and depth.

Can AI-generated feedback replace human annotators entirely? 

AI feedback works well for preference dimensions like fluency, coherence, and basic factual consistency, things that capable LLMs can judge reliably. But for domain-specific, safety-critical, or policy-sensitive preferences, AI judgment alone isn’t trustworthy enough. The practical approach is hybrid: AI at volume for generalizable signals, human annotation where the stakes are too high to rely on model judgment.

What five (5) questions should I ask a vendor before buying human feedback data services? 

Ask: 1. how they calibrate annotators for your specific domain; 2. how they ensure prompt diversity; 3. How do you detect and handle annotation drift over long campaigns? 4. whether they can support ongoing re-annotation; 4. how they handle safety-preference collection, because helpfulness and safety preferences require different annotator profiles and quality checks. A vendor that can’t answer these clearly is likely delivering raw labels, not a production-ready alignment dataset.

Human Feedback Training Data Services: Where RLHF Ends and What Comes Next for Enterprise AI Read Post »

Scroll to Top