Celebrating 25 years of DDD's Excellence and Social Impact.

Quality Control

AI researcher reviewing preference-based model alignment outputs with a human feedback workflow diagram

RLHF vs DPO vs RLAIF and the Trade-Offs That Actually Matter

RLHF, DPO, and RLAIF are three ways to align a language model with human preferences. RLHF trains a separate reward model and optimizes the policy against it with reinforcement learning; DPO removes the reward model and tunes the policy directly on preference pairs; RLAIF replaces most human labels with judgments from a strong model. The right choice depends on your compute budget, how clean your preference data is, and whether the task needs human judgment or a scalable proxy. 

For many teams, RLHF services and LLM fine-tuning services matter less than the quality of the preference data feeding them. The method your team picks changes what preference data you collect, how annotators are trained, and which quality controls actually protect model behavior. A reward model can absorb some annotation noise, while direct optimization cannot, so the same dataset can produce very different results across methods. That gap is where most alignment programs succeed or stall, and it rarely shows up in a benchmark table. Teams that plan the data around the method, rather than the other way round, tend to ship more reliable models.

Key Takeaways

  • RLHF, DPO, and RLAIF are three ways to teach a language model what people actually want from it, and each fits a different budget and goal.
  • RLHF is the most thorough but also the most expensive and complex to run, so it suits high-stakes work where safety and nuance matter most.
  • DPO is faster, cheaper, and simpler, but it only works well when the feedback data you feed it is clean and consistent.
  • RLAIF swaps most human reviewers for a strong AI model, which cuts cost dramatically but should not be trusted for expert or safety-sensitive judgments.
  • No method can fix bad feedback data, so the quality of what you collect matters far more than which technique you pick.
  • Most successful teams blend the methods and plan their data around the approach first, rather than chasing whichever technique looks best on a benchmark.

What are RLHF, DPO, and RLAIF, and how do they differ?

Alignment is the step that turns a capable base model into one that follows instructions, rejects incorrect requests, and matches the tone a product requires. Reinforcement Learning from Human Feedback (RLHF), Direct Preference Optimization (DPO), and Reinforcement Learning from AI Feedback (RLAIF) are the three dominant techniques for doing this from preference data. All three start after supervised fine-tuning and learn from comparisons, usually over the same underlying question: which response is better and why. Well-designed preference data collection and curation is the shared foundation each method depends on.

The methods differ in how that preference signal reaches the model. Reinforcement learning from human feedback trains an explicit reward model on human comparisons, then uses reinforcement learning, typically Proximal Policy Optimization (PPO), to push the policy toward higher-reward outputs. DPO folds those two stages into a single loss and optimizes the model directly on chosen and rejected pairs. RLAIF keeps a pipeline close to RLHF but sources most preference labels from a strong “teacher” model instead of people. Naming stays consistent across the industry: RLHF and PPO belong together, DPO is a direct alignment method, and RLAIF is AI feedback.

These three methods are not mutually exclusive. Many production teams run a hybrid, for example, DPO for broad style and instruction following, then a targeted round of RLHF for safety-critical behavior, with RLAIF filling in generic signals like fluency at scale. The sections below define each method, then compare them on the trade-offs that actually drive the decision.

What is the difference between RLHF and DPO?

The core difference is the reward model. RLHF trains one as a separate stage and then optimizes the policy against it with reinforcement learning. DPO consolidates both steps into a single objective computed directly on preference pairs, so there is no reward model and no RL loop to stabilize.

How does RLHF use a reward model?

RLHF runs in three phases: supervised fine-tuning, reward model training, and reinforcement learning. Annotators compare model outputs, a reward model learns to predict which output people prefer, and PPO tunes the policy to score well against that reward while a KL penalty keeps it from drifting into degenerate text. The reward model is the useful abstraction here, because it generalizes beyond the exact pairs it saw and it can be reused across training runs. It also absorbs a degree of labeling noise, since it learns an average signal rather than memorizing every comparison, which is why scaling RLHF data annotation without losing quality is a solvable operational problem rather than an all-or-nothing one.

Why is DPO simpler and cheaper to run?

Research presented at ICLR showed that the constrained reward-maximization problem RLHF solves can be reframed as a simple classification loss on preference pairs, delivering comparable results with less compute and a much simpler pipeline. DPO still needs a frozen reference model and high-quality pairs, but it removes reward-model training and the brittle RL phase, which is where most RLHF instability lives. Because it avoids a separate reward network and an online RL rollout, DPO pairs naturally with parameter-efficient methods; teams often combine it with LoRA, QLoRA, and adapters to keep the tuning cost low.

Why does data quality matter more for DPO?

DPO is more sensitive to noisy preferences than reward-model-based RLHF. Because it optimizes the policy directly against each pair, a mislabeled comparison pushes the model in the wrong direction with no reward model to average it out. Work on filtered DPO confirms that text quality in the preference set affects DPO more than it affects reward-model RLHF. The practical consequence is that comparative preference annotation versus scalar scoring is not a cosmetic choice; DPO demands cleaner, more consistent pairs from the start, and a recent analysis also found that the theoretical equivalence between DPO and RLHF is conditional, holding only when the optimal policy already prefers the human-preferred response.

What is RLAIF and how does it compare to RLHF?

RLAIF replaces human annotators with a strong model that generates preference labels, which are then used the same way RLHF uses human labels, either to train a reward model or, in the direct variant, to score responses during RL. The appeal is scale and cost: a Google DeepMind study found AI labeling to be roughly ten times cheaper than human annotation, and human evaluators preferred RLAIF and RLHF policies at statistically indistinguishable rates on summarization and helpful dialogue. On harmless dialogue, RLAIF actually scored a higher harmless rate than RLHF.

Where does RLAIF work well, and where does it fail?

RLAIF is strongest on generalizable signals a capable model already judges well, such as fluency, coherence, and format. It falters where the label depends on knowledge the teacher lacks. The same research is explicit that in high-stakes domains like medicine, law, and employment, human experts trained to strict policies should remain the gold standard, because AI feedback can transfer the teacher’s biases into the policy and amplify them. RLAIF is also only as good as its teacher; label quality tracks model size, and smaller labels show more position bias.

For most enterprises, the honest answer is a blend. Use RLAIF to cover volume on generic quality dimensions, and reserve human preference data for domain expertise, safety judgments, and cultural fit. That division keeps costs down without outsourcing the judgments that carry real risk. Constitutional AI and Kahneman-Tversky Optimization (KTO) sit nearby as related options; the former guides an AI labeler with written principles, the latter learns from simple thumbs-up or thumbs-down signals instead of paired comparisons.

How do the three methods compare on data, cost, and complexity?

The trade-offs cluster around four questions: what preference data you need, how much compute the method consumes, how hard it is to implement and stabilize, and how much it tolerates noisy labels. The table summarizes where each method lands so a team can match the method to its constraints rather than to hype.

Dimension RLHF (PPO) DPO RLAIF
Reward model Yes, trained separately None, optimized directly Optional; often trained on AI labels
Preference labels Human comparisons Human comparisons, cleaner pairs needed Mostly AI-generated
Compute cost Highest, RL rollouts Lower, single loss Low labeling cost, RL cost varies
Implementation Complex, RL tuning Simplest to stabilize Moderate, depends on teacher
Noise tolerance Higher, reward model averages Lower, sensitive to bad pairs Depends on teacher quality
Best fit Safety-critical, reusable reward Fast, sample-efficient alignment Scaling generic quality signals

One caveat worth stating plainly: published benchmarks do not consistently favor one method. Which one wins depends on task type, data quality, model scale, and how the evaluation is designed. The hardest part of alignment is the consistency and domain expertise behind the preference data, not the optimizer you choose.

When should you use DPO instead of RLHF?

Reach for DPO when you want fast, sample-efficient alignment on broad behaviors, and you can guarantee clean preference pairs. It suits instruction following, tone, and style, and it is a good default when a team lacks the infrastructure to run and debug a full RL loop. Because it is cheaper and more stable, DPO also fits rapid iteration cycles where you re-tune often as the product changes.

Prefer RLHF when you need a reusable reward model, richer reward shaping, online generation during training, or room for more complex objectives, and especially for safety-critical use cases where nuance matters. Fine-grained reward models add another lever here. Research on fine-grained human feedback for language model training showed that separate reward signals for factuality, fluency, and other axes let teams tune behavior deliberately, which a single DPO objective cannot express as cleanly. The decision is rarely all-or-nothing; many teams DPO first, then apply RLHF where the stakes justify the cost.

What are the advantages of RLHF over supervised fine-tuning?

Supervised fine-tuning teaches a model to imitate high-quality examples, establishing a strong baseline for instruction following, formatting, and consistent style. Its limitation is that it learns from demonstrations rather than explicit preferences; it can reproduce a target response but does not inherently learn why one acceptable response may be better than another. When fine-tuning LLMs, this makes supervised learning effective for teaching desired behaviors and domain patterns, while preference-based methods are better suited to refining subjective qualities such as helpfulness, tone, safety, and response quality.

Preference-based methods add the missing signal. By learning from comparisons, RLHF optimizes on sequence-level objectives that are hard to capture with token-level supervision, such as helpfulness, harmlessness, or subtle tone, and it can push quality past the best single demonstration. In the DeepMind study, human evaluators preferred RLHF and RLAIF policies over the supervised baseline 71 to 73 percent of the time on summarization, a gap SFT alone did not close. The practical takeaway is sequencing: SFT establishes competence, and preference optimization aligns behavior with what people actually want.

How Digital Divide Data Can Help

DDD’s human preference optimization services support the full alignment lifecycle, from designing the initial preference schema through iterative re-annotation as models and deployment conditions change. Because the method determines the data, DDD builds pipelines around comparative judgments and matches annotator profiles and quality controls to whether you are running RLHF, DPO, RLAIF, or a hybrid. For DPO specifically, where noisy pairs degrade the model directly, that means tighter inter-annotator agreement targets and cleaner chosen and rejected pairs from the start.

On the RLHF side, DDD trains reward models on expert-labeled examples for factual accuracy, tone, and domain quality, and captures rankings, labels, and free-form rationales that feed both reward modeling and direct optimization. Where AI feedback is appropriate, DDD scopes RLAIF to the generic signals it handles well while keeping subject-matter experts on domain and safety judgments. The same team also runs model evaluation services that combine structured benchmarks with human review, so you can measure whether alignment actually moved the behaviors you care about rather than trusting a single aggregate score.

Build alignment programs where the preference data is good enough for the method you chose. Talk to an Expert!

Conclusion

The choice among RLHF, DPO, and RLAIF is a choice about constraints, not a search for a single best method. DPO gives you speed and stability if your pairs are clean; RLHF gives you a reusable reward model and headroom for safety-critical nuance; RLAIF gives you scale on the signals a strong model already judges well. What ties them together is that none can rescue a weak preference set, and each fails differently when the data is wrong.

Organizations that treat the optimizer as the decision tend to relearn this the hard way, tuning method after method on the same noisy data. The ones that get durable results design the preference data around the method first, then measure alignment against behavior rather than a leaderboard. 

References

Rafailov, R., Sharma, A., Mitchell, E., Manning, C. D., Ermon, S., & Finn, C. (2023). Direct Preference Optimization: Your Language Model is Secretly a Reward Model. https://arxiv.org/abs/2305.18290

Lee, H., Phatale, S., Mansoor, H., Mesnard, T., Ferret, J., Lu, K., Bishop, C., Hall, E., Carbune, V., Rastogi, A., & Prakash, S. (2024). RLAIF vs. RLHF: Scaling Reinforcement Learning from Human Feedback with AI Feedback. https://arxiv.org/abs/2309.00267

Morimura, T., Sakamoto, M., Jinnai, Y., Abe, K., & Ariu, K. (2024). Filtered Direct Preference Optimization. https://arxiv.org/abs/2404.13846

Yang, Z., Zhang, Y., Xue, W., Fang, D., Han, B., & Guo, Y. (2026). Conditional Equivalence of DPO and RLHF: Implicit Assumption, Failure Modes, and Provable Alignment. arXiv preprint. https://arxiv.org/abs/2605.20834

Frequently Asked Questions

Is DPO better than RLHF?

Not universally. DPO is simpler, cheaper, and easier to stabilize because it skips the reward model and the reinforcement learning loop, but it needs cleaner preference pairs and offers less control over complex objectives. RLHF is often the better fit for safety-critical work where a reusable reward model and richer reward shaping matter. Which one performs better depends on your task, data quality, and model scale.

When should I use DPO instead of RLHF?

Use DPO when you want fast, sample-efficient alignment on broad behaviors like tone and instruction following, and you can guarantee clean chosen and rejected pairs. It is also the practical choice when your team cannot run and debug a full RL pipeline. Keep RLHF for cases that need a reusable reward model or nuanced safety behavior.

What is RLAIF and how does it compare to RLHF?

RLAIF replaces most human preference labels with judgments from a strong model, then trains the policy the same way RLHF does. Studies show it can match RLHF on tasks like summarization and helpful dialogue at roughly a tenth of the labeling cost, and it does well on generic signals like fluency. It struggles on domain expertise and safety judgments, where human annotators are still the gold standard.

What are the advantages of RLHF over supervised fine-tuning?

Supervised fine-tuning can only imitate the examples it is shown, so it cannot express that one response is better than another. RLHF learns from comparisons, which lets it optimize for helpfulness, harmlessness, and tone and push quality past the best demonstration. In practice you use supervised fine-tuning to build competence first, then preference optimization to align behavior with what people actually prefer.
RLHF vs DPO vs RLAIF and the Trade-Offs That Actually Matter Read Post »
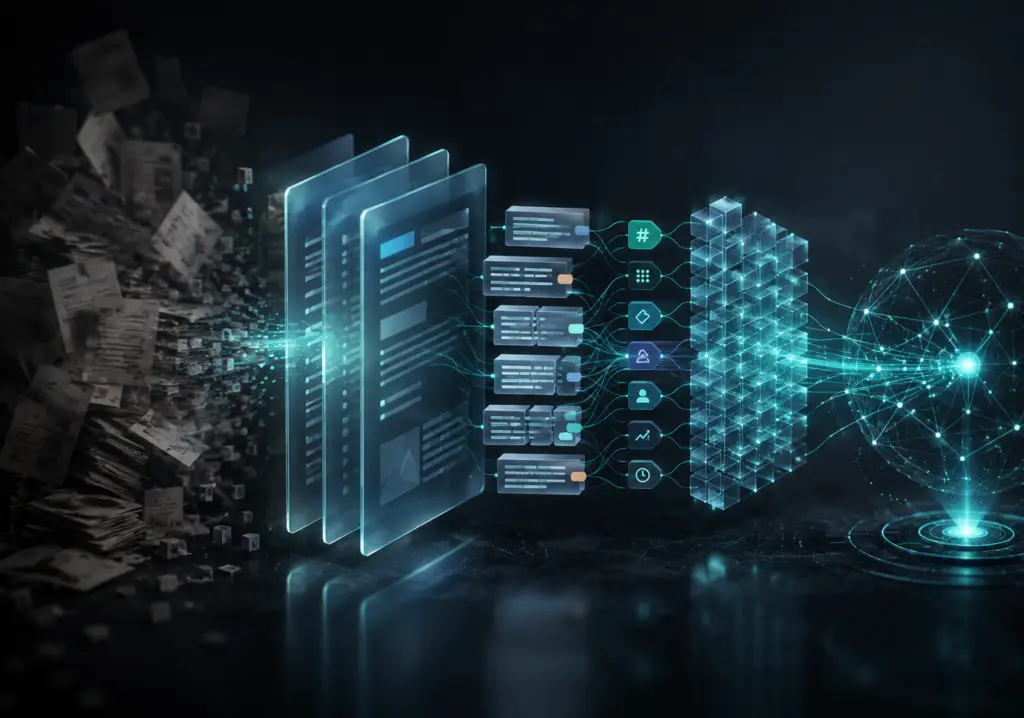
Knowledge base curation pipeline transforming raw documents into structured data for RAG retrieval

Why Your Retrieval System Is Only as Good as Your Knowledge Base Curation

Knowledge base curation for RAG is the upstream work of cleaning, structuring, chunking, tagging, and refreshing the source documents that a retrieval system searches. Retrieval quality sets a hard ceiling on answer quality, so a well-tuned retriever cannot recover from a noisy, stale, or badly segmented corpus. Teams that treat the knowledge base as a living, governed asset get more reliable RAG systems than teams that dump documents into a vector store and tune prompts afterward. Getting curation right often depends on disciplined structured data preparation and RAG fine-tuning.

Most RAG debugging starts in the wrong place. When answers are wrong, teams reach for a better embedding model, a larger context window, or a reranker, because those levers are visible and easy to change. The real constraint usually sits one layer up, in the documents themselves. A retriever can only return what the knowledge base contains, and it can only return it cleanly if the content was prepared to be found.

Key Takeaways

  • Your RAG system can only be as good as the documents it searches, so fixing the source content matters more than swapping models or tweaking prompts.
  • The way you split documents into pieces directly shapes what the system can find, and there’s no single right size; you have to always test it.
  • Tagging each piece with details like source, date, and section lets the system filter and cite answers instead of just guessing by similarity.
  • Old and duplicate documents quietly poison answers, because the system happily returns outdated content that still looks correct.
  • Regular checks against a fixed set of test questions are the only reliable way to know your knowledge base is actually working.

What is knowledge base curation for RAG?

Knowledge base curation for RAG is the set of upstream steps that turn raw source documents into a clean, well-labeled, searchable corpus that a retriever can query reliably. Retrieval-Augmented Generation, or RAG, is an architecture where a language model answers using text pulled from an external index at request time rather than from its trained weights. The knowledge base is everything the system is allowed to retrieve from, which includes the documents, the chunk boundaries, the metadata, and the vector index itself. Curation covers parsing, cleaning, deduplication, chunking, metadata tagging, and freshness management, and it is distinct from the generation logic that most teams spend their time tuning. Strong and successful teams consider data collection and curation as the product, not as a preprocessing afterthought.

The distinction matters because RAG has two phases, and each fails differently. Indexing prepares and stores content, while retrieval finds and returns it. A mistake during indexing can remain invisible during retrieval: if a document is parsed incorrectly or split across a concept boundary, the retriever may still return chunks and appear healthy in dashboards. The problem surfaces only when the system produces an incomplete or incorrect answer, which teams may then misattribute to the model itself. RAG data quality, evaluation, and governance are therefore critical for making this layer measurable, traceable, and easier to diagnose rather than simply assuming the retrieval pipeline is working as intended.

RAG converts source data to plain text and chunks it for retrieval, which works until the corpus grows diverse. As applications expand, plain-text retrieval becomes insufficient because textual information tends to be redundant and noisy, and complex questions often require joining several documents that plain text cannot relate to each other. The PIKE-RAG analysis of specialized knowledge for RAG makes this point directly; richer knowledge representations exist precisely because dumping documents in as-is degrades retrieval quality at scale. Curation is how you avoid that degradation before it compounds.

Why does source document quality cap retrieval accuracy?

Retrieval quality sets the ceiling for answer quality, which means no amount of prompt engineering or model choice can rescue a system whose retriever surfaces the wrong evidence. Generation only consumes what retrieval supplies, so if the right passage is buried, malformed, or absent from the index, the model has nothing accurate to ground its answer in. This is the single most important idea in RAG design, and it reframes the entire debugging process. When answers degrade, the first suspect should be the content and the retrieval path, not the language model.

Source quality caps accuracy through several concrete mechanisms rather than as a vague quality concept. Inconsistent parsing loses document structure, so headings, tables, and lists collapse into undifferentiated text that no longer signals what belongs together. Redundant and near-duplicate content pollutes the index, which pushes the retriever toward whichever copy happens to embed closest rather than toward the authoritative version. Study protocol manuals with non-uniform structure and description granularity, for example, cannot be used as-is and still yield consistent retrieval, a finding documented in a foundational study on retrieved chunk quality from real-world knowledge. The lesson generalizes well beyond medicine; upstream structure determines downstream precision.

There is a practical reason this failure mode persists in production teams. Cloud RAG platforms now automate layout analysis, chunk division, and indexing, which reinforces an assumption that existing manuals and documents can be fed in as-is and still produce satisfactory answers. That assumption holds for clean, uniform corpora and breaks for the messy, heterogeneous document sets most enterprises actually own. Preparing content properly through structured and enriched, AI-ready data is what closes the gap between a demo that works and a system that holds up under real query load.

How does chunk size affect RAG performance?

Chunk size controls the granularity of what the retriever can return, and it trades recall against precision on a curve that has no universal optimum. Chunks that are too large bundle several ideas together, which dilutes the embedding and forces the model to read past irrelevant text to reach the answer. Chunks that are too small fragment a single idea across boundaries, so the retriever surfaces a piece of the answer without the context needed to use it. The right size depends on document type, query pattern, and the embedding model, which is why chunking is an empirical decision rather than a default setting.

The strategy matters as much as the size, and several approaches trade off differently. The main options practitioners use are worth naming precisely:

  • Fixed-size chunking splits text into uniform segments, often around 512 tokens with 50 to 100 tokens of overlap, and is fast, predictable, and prone to cutting through concepts.
  • Recursive chunking splits hierarchically from sections to paragraphs to sentences, which respects structure better than fixed windows.
  • Semantic chunking draws boundaries where meaning shifts rather than at a token count, producing chunks that follow the natural flow of ideas.
  • Agentic chunking uses a model to decide split points, which can be accurate but is model-dependent and best reserved for a certified, high-value subset of the corpus.

Evidence backs the intuition that segmentation strategy changes measurable retrieval outcomes. A comparative evaluation of advanced chunking for clinical decision support built four otherwise identical RAG pipelines that differed only in chunking method, and found that fixed-length chunks split concepts and add noise in ways that measurably reduce precision, recall, and F1 relative to semantic and adaptive approaches. The practical takeaway is to start with a sensible default, then test chunking against real user queries and inspect the retrieved chunks by hand. Building training data for RAG therefore requires deliberate attention to chunk quality, relevance, and coverage so segmentation choices are validated against retrieval performance rather than based on guesswork alone.

What metadata should you add to documents for a RAG pipeline?

Metadata is the labeling layer that lets a retriever filter, route, and cite chunks instead of relying on vector similarity alone. Vector search finds semantically close text, but it has no built-in sense of source, recency, permission, or document type, and metadata supplies exactly those signals. Adding structured tags to each chunk turns an opaque similarity match into a query you can constrain, which improves precision and makes answers auditable. Treating metadata as foundational rather than optional is one of the clearest dividing lines between prototype and production RAG.

A practical metadata schema for RAG usually carries a consistent core set of fields:

  • Source and provenance: document title, author or owner, originating system, and a stable chunk ID so answers can cite a human-readable pointer back to the source.
  • Temporal fields: creation date, last-updated date, and an explicit staleness threshold, so the retriever can prefer current content and flag content that has aged past its useful life.
  • Structural context: section heading, document type, and position, which preserve the hierarchy that chunking would otherwise flatten.
  • Access and domain tags: permission level, business unit, and topic, which enable filtered retrieval and keep restricted content out of unauthorized answers.

Generating this metadata by hand does not scale, which is why enrichment increasingly uses models with human validation. Traditional curation methods scale poorly to unstructured enterprise datasets, a gap documented in a systematic framework for LLM-generated metadata to enhance RAG systems, which shows that document-level preprocessing through metadata enrichment measurably changes retrieval effectiveness. The reliable pattern is to tag metadata before chunking, use model-assisted extraction for entities and summaries, and keep a human in the loop for the fields where errors are expensive. This is core text and document annotation work, and it is where careful annotation design pays off directly in retrieval quality.

Why does deduplication and freshness management matter for RAG?

Deduplication and freshness management keep the index honest over time, and their absence produces the most dangerous class of RAG failure because it is silent. A knowledge base is not a static artifact; policies change, prices update, and manuals grow, so a corpus that was accurate at launch drifts out of date without any code change or infrastructure event. When an old version of a document stays indexed alongside a new one, the retriever returns confident, semantically relevant results that happen to be wrong. Nothing in a standard pipeline flags this, because vector similarity has no temporal dimension and a stale embedding scores just as high as a fresh one.

The operational danger is that freshness failures do not announce themselves the way chunking errors do. When chunking is misconfigured, retrieval quality suffers visibly and immediately, so teams tune it and move on. Staleness degrades distributionally instead; across hundreds of queries, accuracy quietly slips while every individual answer still looks plausible, and standard metrics like context recall and faithfulness keep scoring well because none of them measure whether the retrieved content is current. Reporting from practitioners tracking this describes the knowledge base staleness problem that teams solve last, usually after a customer incident report rather than before one. Deduplication addresses the same root issue by collapsing near-identical content so the retriever chooses the authoritative version rather than an accidental copy.

Managing this at scale requires treating freshness as a first-class part of the pipeline rather than a periodic cleanup. That means incremental indexing that detects and re-embeds only changed content instead of reprocessing the whole corpus, explicit staleness thresholds stored as metadata on every document, and monitoring for stale retrieval rate and coverage drift. It also means a reliable ingestion path, since freshness is only as good as the ML data collection pipeline feeding new and corrected content into the index. For multimodal corpora, where images, tables, and text must stay aligned, keeping the index current is harder still, and cross-modal RAG techniques for enhancing LLMs show why consistent curation across modalities matters.

How do you measure whether your knowledge base is actually working?

You measure a knowledge base by evaluating retrieval as its own component, separate from generation, using a curated test set rather than eyeballing final answers. The core instrument is a golden set: a fixed collection of representative questions paired with the passages that should support each answer. Running that set every time you change parsing, chunking, embeddings, or metadata tells you whether a change helped or quietly regressed retrieval. Without this, teams optimize blind and discover problems only when users complain, which is exactly the pattern that makes RAG projects fail after a successful proof of concept.

Retrieval evaluation checks whether the right chunks appear near the top of the results, which is distinct from assessing whether the final answer reads well. A fluent response can still be grounded in irrelevant, outdated, or superseded evidence. Measuring retrieval directly, using precision and recall against a golden set, helps isolate knowledge-base performance from model behavior and makes failure attribution more accurate. It also exposes freshness, duplication, and coverage issues that generation-level metrics may miss. Trust and safety solutions add another layer of control through grounding checks and output validation, confirming that generated answers are supported by the evidence retrieved from the approved knowledge base.

The discipline here is to treat the knowledge base as a system you validate, not a dump of documents you hope is complete. That reframing changes how teams spend their time. Instead of tuning chunk size in isolation as a local improvement, the teams that reach reliable, repeatable deployment govern the whole knowledge layer that feeds retrieval, which is a systemic one. In RAG in generative AI, knowledge base quality is therefore a system-level concern because weaknesses anywhere in the retrieval architecture can propagate directly into the model’s final answer.

How Digital Divide Data Can Help

Digital Divide Data works on the upstream layer that determines RAG performance, which is the preparation, structuring, and ongoing curation of the source documents a retrieval system depends on. Our data collection and curation services cover parsing heterogeneous document sets, deduplicating near-identical content, and building the clean, consistently structured corpus that retrieval quality rests on. Because curation is annotation work at its core, our text and document annotation teams design chunking schemas, apply metadata taxonomies, and validate the fields that are too expensive to get wrong, with human review built into the workflow rather than bolted on afterward.

Beyond initial preparation, we help teams keep knowledge bases current and trustworthy as they grow. That includes metadata enrichment for provenance, recency, and access control, incremental re-labeling as documents change, and grounding and output validation through our trust and safety solutions so answers can be traced back to authoritative sources. We build golden evaluation sets, run retrieval-level quality checks, and treat the knowledge base as a measured component rather than a static input, which is how curation stays honest at production scale across text and multimodal corpora alike.

Build a knowledge base that raises your retrieval ceiling instead of capping it. Talk to an Expert

Conclusion

Retrieval sets the ceiling, and the source documents set retrieval, so the knowledge base is where RAG quality is won or lost. The work that matters most, which is clean parsing, deliberate chunking, structured metadata, deduplication, and active freshness management, happens before a single query runs and stays invisible in most dashboards. That invisibility is exactly why it gets neglected, and why neglecting it produces confident wrong answers that standard evaluation never catches.

Organizations that treat the knowledge base as a living, governed, measurable asset build RAG systems that stay reliable as the corpus grows and changes. Organizations that treat it as a one-time document dump ship demos that work and production systems that quietly decay. The gap between the two is not a better model or a bigger context window; it is disciplined curation applied continuously. 

References

Wang, J., Fu, J., Wang, R., Song, L., & Bian, J. (2025). PIKE-RAG: sPecIalized KnowledgE and Rationale Augmented Generation. arXiv preprint. https://arxiv.org/pdf/2501.11551

Gomez-Cabello, C. A., Prabha, S., Haider, S. A., Genovese, A., Collaco, B. G., Wood, N. G., Bagaria, S., & Forte, A. J. (2025). Comparative Evaluation of Advanced Chunking for Retrieval-Augmented Generation in Large Language Models for Clinical Decision Support. PMC. https://www.ncbi.nlm.nih.gov/pmc/articles/PMC12649634/

Fukataki, Y., Hayashi, W., Kitayama, M., & Ito, Y. M. (2026). Measurement of retrieved chunk quality from real-world knowledge in retrieval-augmented generation: A Phase 1 foundational study. medRxiv preprint. https://www.medrxiv.org/content/10.64898/2026.01.01.26343326.full.pdf

Mishra, P. P., Yeole, K. P., Keshavamurthy, R., Surana, M. B., & Sarayloo, F. (2025). A Systematic Framework for Enterprise Knowledge Retrieval: Leveraging LLM-Generated Metadata to Enhance RAG Systems. arXiv preprint. https://arxiv.org/pdf/2512.05411

Frequently Asked Questions

What is knowledge base curation for RAG?

It is the upstream work of turning raw source documents into a clean, well-structured, well-labeled corpus that a retrieval system can search reliably. That includes parsing, cleaning, deduplication, chunking, metadata tagging, and keeping content current, all of which happen before generation and largely determine how good the answers can be.

How do I improve RAG retrieval accuracy?

Start with the documents, not the model. Fix inconsistent parsing so structure is preserved, remove duplicate and near-duplicate content, choose a chunking strategy that fits your document type, and add metadata for source, recency, and access so the retriever can filter as well as match. Then validate with a golden set of questions and expected passages so you can tell whether each change actually helped.

How does chunk size affect RAG performance?

Chunk size sets the granularity of what the retriever returns. Chunks that are too large mix several ideas together and dilute the match, while chunks that are too small split a single idea across boundaries and lose context. There is no universal best size, so you test against real queries and inspect the retrieved chunks, often starting near 512 tokens with some overlap and adjusting from there.

What metadata should I add to documents for a RAG pipeline?

At minimum, add source and provenance fields with a stable chunk ID for citation, temporal fields like last-updated date and a staleness threshold, structural context such as section heading and document type, and access or domain tags for filtered retrieval. Tagging metadata before chunking, with model-assisted extraction and human validation for the costly fields, gives the retriever signals that vector similarity alone cannot provide.

Why Your Retrieval System Is Only as Good as Your Knowledge Base Curation Read Post »

Hybrid Human and AI Workflows

How Hybrid Human and AI Workflows Are Reshaping Enterprise Labeling Economics

Hybrid annotation workflows, with AI pre-label data and trained human annotators, validate, correct, and escalate, are slowly replacing crowd-only labeling as the production standard. When implemented correctly, Hybrid Annotations significantly reduce labeling costs while maintaining the accuracy rates that safety-critical programs require. The gains are real, but they depend on getting the task routing, workforce tier design, and quality architecture right from the start.

Annotation costs are one of the most persistent pressure points in enterprise AI programs. For most of the last decade, the dominant answer was crowd-sourced labor; fast to spin up, cheap per label, and difficult to control at quality thresholds above roughly 90%. AI data annotation services have evolved considerably since then. Pre-annotation models combined with tiered human validation are changing the unit economics of labeling in ways that matter to program planning, vendor selection, and internal resourcing decisions alike. The organizations getting this right treat hybrids as a system design problem. Those struggling with it are treating it as a tooling swap. 

Key Takeaways

  • Hybrid annotation combines AI-generated labels with human review, and shifts annotators from doing the work from scratch to checking and correcting what the AI produces.
  • This approach can cut labeling costs by up to 70%, but only for straightforward, high-volume tasks; complex or rare scenarios still need full human annotation.
  • Organizing annotators into tiers (basic verifiers, domain specialists, senior reviewers) is what actually makes the cost savings work without hurting quality.
  • For self-driving and safety-critical AI, relying on AI pre-labeling alone is risky because its mistakes tend to repeat in patterns that are hard to catch through normal quality checks.
  • A vendor claiming high accuracy on a hybrid pipeline may only be measuring the easy portion of the data, and you should always ask whether that number covers the full dataset.
  • The real benefit of hybrid annotation comes from treating it as a deliberate workflow design, not just a technology upgrade.

What Is AI-Assisted Data Annotation and How Does It Actually Work?

AI-assisted data annotation, also called model-assisted labeling or pre-annotation, uses a trained model to generate candidate labels before a human annotator reviews the output. The human’s job shifts from drawing or typing labels from scratch to verifying, correcting, and in some cases rejecting what the model produced. The result is a workflow that assigns model output to the high-confidence, high-volume portion of a dataset, and routes genuinely difficult examples to skilled annotators.

A pre-annotation model, trained on prior labeled data from the same or a similar domain, runs inference on incoming raw data and generates bounding boxes, segmentation masks, text classifications, or other label structures. Labels above a confidence threshold go to a lightweight human verification queue. Labels below the threshold go to a full annotation queue. Labels in the ambiguous middle range may go to a secondary model or a senior reviewer.  Most production GenAI systems operate on a routing logic to increase the speed of annotation, yet maintain the accuracy. 

How Does Pre-Annotation Reduce Labeling Costs in Practice?

The cost reduction comes from two places: throughput and labor tiering. 

On throughput: Verification of a model-generated label is faster than producing a label from scratch. For image tasks like bounding box correction, studies consistently find that annotation time per instance drops by 40–70% when annotators validate pre-labeled data rather than annotating from scratch. For text classification, the time savings are more moderate because reading comprehension and category judgment take time regardless of whether a candidate label is presented. A 2025 analysis of hybrid annotation workflows on video footage confirmed that model-assisted labeling substantially reduces annotation effort, while also noting that systematic error patterns in pre-annotation require specific QA designs to catch.

On labor tiering: Hybrid systems allow programs to route simple verification tasks to lower-cost annotator tiers without sacrificing quality on hard examples. A crowd worker verifying a high-confidence bounding box is a different and cheaper task than a domain specialist annotating an edge case with occlusion, adverse lighting, or a rare object class. Programs that separate these tasks structurally recover significant cost without degrading the quality of the difficult portion of their dataset.

The cost reduction figure cited across industry reports is achievable, but it applies to specific task types under specific conditions: high object count per frame, established label taxonomy, strong pre-annotation model trained on in-domain data, and a dataset that skews toward common cases. Programs with higher edge-case density, novel categories, or tight accuracy requirements will see smaller efficiency gains. Enterprise image labeling economics at production scale are shaped as much by dataset composition as by tooling choice.

How Does a Tiered Workforce Model Look?

A tiered workforce model organizes annotators into structured roles based on task complexity and required judgment. Here is an elevated view of the three-tiered workforce model that most enterprise-grade hybrid programs follow. 

Tier 1- Verification workers: Trained crowd or managed workforce annotators who review high-confidence pre-labeled examples, approve or reject labels, and flag items that exceed their routing criteria. Fast, scalable, and cost-effective for well-defined tasks.

Tier 2- Domain annotators: Specialists with subject-matter knowledge or extended training in the target domain (e.g., medical imaging, ADAS sensor fusion, legal text classification). They handle ambiguous cases routed from Tier 1 and perform full annotation on low-confidence predictions.

Tier 3- Senior reviewers or QA leads: Experienced annotators who audit samples from both lower tiers, adjudicate inter-annotator disagreements, and maintain inter-annotator agreement (IAA) metrics across the program. They also identify systematic errors in the pre-annotation model that should trigger retraining.

Scalable multimodal annotation covering image, video, LiDAR, and text within a single program requires different labor profiles at each data modality. Routing LiDAR point cloud annotation to Tier 1 workers is a quality risk; routing standard RGB bounding box verification to Tier 2 specialists is a cost inefficiency. Matching task complexity to the annotator tier is where programs recover most of their labeling savings.

Workforce tier design also shapes the feedback loop back to the pre-annotation model. When Tier 3 reviewers log disagreements and correction patterns, those signals can drive active learning cycles that improve model confidence on precisely the categories and conditions that cost the most to annotate manually. Active learning in annotation workflow design is the mechanism that makes hybrid systems improve over time rather than plateau.

Where Does the Hybrid Model Break Down?

The hybrid model has limitations, and they matter most in the domains where annotation accuracy is hardest to recover.

Pre-annotation bias compounds at scale

When annotators are shown a candidate label, they anchor on it, even when it is wrong. Research on cognitive bias in AI-assisted annotation found that errors from pre-annotation workflows exhibit a more systematic pattern than errors from manual annotation. Instead of random mistakes scattered across the dataset, you get clusters of consistently wrong labels wherever the pre-annotation model fails coherently. This is harder to catch with standard sampling-based QA because the errors are correlated, not independent.

Safety-critical domains require full annotation

ADAS and AV annotation programs present the clearest case for limiting hybrid automation. Perception models trained on autonomous vehicle data must handle rare but consequential events: pedestrians in non-standard positions, sensor degradation in adverse weather, edge cases that occur infrequently in training data but deterministically in deployment. For these categories, the cost of a missed or incorrect label is not offset by throughput savings on common cases. Pre-annotation can accelerate common-case throughput in AV programs, but safety-critical categories should remain on full human annotation pipelines with senior reviewer adjudication.

How Digital Divide Data Can Help

DDD runs hybrid annotation programs across physical AI, ADAS, AV, and enterprise NLP/LLM use cases. The workflow architecture we use is built around the tiered workforce model described above: pre-annotation for high-volume common cases, domain specialist annotation for ambiguous and low-confidence items, and senior QA for adjudication, IAA measurement, and model feedback cycles. 

Our end-to-end data annotation services cover image, video, LiDAR, sensor fusion, text, and audio, enabling hybrid workflows across multimodal programs without fragmenting across vendors. For LLM and generative AI programs specifically, our text annotation services include structured human preference data collection and calibrated annotator workflows for RLHF and DPO programs, where model-assisted pre-labeling is inappropriate and human judgment is the primary signal.

For safety-critical ADAS and AV annotation, we maintain full human annotation pipelines for designated categories regardless of pre-annotation confidence scores. We do not route safety-critical perception tasks through Tier 1 verification workflows. Human feedback training data and hybrid pipeline design explain the broader framework for matching annotation workflow design to program risk profile.

Design a labeling program that actually controls cost without compromising quality. Talk to an Expert Today

Conclusion

The hybrid model (AI pre-annotation combined with structured human validation) is slowly becoming the current production standard for enterprise labeling at scale. It is a workflow design discipline that requires getting task routing, annotator tier structure, and QA architecture right before the savings materialize. Programs that treat it as a tooling upgrade tend to discover the failure modes (anchoring bias, accuracy denominator confusion, safety category under-coverage) after their training data is already compromised.

Organizations that approach hybrid annotation as a system with explicit routing rules, tiered workforce design, and differentiated QA standards for pre-labeled versus fully annotated examples consistently achieve better labeling economics without the accuracy regressions that crowd-only or fully automated pipelines introduce. The programs that do not will continue to spend on remediation cycles that cost more than the labeling savings they sought.

References

Beck, J., Eckman, S., Kern, C., & Kreuter, F. (2025). Bias in the Loop: How Humans Evaluate AI-Generated Suggestions. arXiv preprint. https://arxiv.org/pdf/2509.08514

Gutiérrez, J., Gutiérrez, V., Mora, Á., Rodríguez, S., & Blanco, J. L. (2025). An Evaluation of Hybrid Annotation Workflows on High-Ambiguity Spatiotemporal Video Footage. arXiv preprint. https://arxiv.org/abs/2510.21798

 Abbaspour, A., Patil, T. B., Kiran, B. R., Mohr, R., & Yogamani, S. (2026). Dataset Safety in Autonomous Driving: Requirements, Risks, and Assurance. arXiv preprint arXiv:2511.08439 (2026). https://arxiv.org/html/2511.08439v2

Frequently Asked Questions

What is AI-assisted data annotation, and how does it reduce labeling costs?

AI-assisted data annotation uses a pre-trained model to generate candidate labels before a human reviewer sees the data. The human verifies or corrects the model output rather than annotating from scratch, which reduces the time per label. Cost savings typically come from two places: faster throughput on verification tasks versus full annotation, and the ability to route simple verification work to lower-cost annotator tiers while reserving specialist labor for genuinely difficult examples.

Is hybrid annotation safe to use for autonomous driving or ADAS programs?

Hybrid annotation is safe for high-volume common-case categories in ADAS programs. It is not suggested for safety-critical perception categories, rare edge cases, or sensor degradation scenarios. For those critical categories, full human annotation with senior reviewer adjudication remains the correct approach. The risk with hybrid in safety-critical contexts is systematic error propagation; pre-annotation model failures produce correlated errors that standard sampling-based QAs are not designed to catch.

What does a tiered workforce model mean in practice?

A tiered workforce model divides annotation tasks by complexity. For example, Tier 1 workers verify high-confidence pre-labeled examples quickly, Tier 2 domain specialists annotate ambiguous or low-confidence items, and Tier 3 senior reviewers audit quality, resolve disagreements, and track inter-annotator agreement. The model reduces cost by matching task difficulty to annotator skill level, rather than routing everything through one labor pool at a single price point.

How should I evaluate vendor claims about annotation accuracy in hybrid workflows?

Accuracy claims in hybrid workflows need a denominator check. A vendor reporting 99% accuracy on a hybrid pipeline may be measuring pass rate on the high-confidence verification queue, which is a much easier target than accuracy across the full dataset, including difficult and low-confidence examples. Ask whether the reported accuracy covers the full dataset or only the pre-labeled subset, and what QA methodology is applied to the full annotation queue versus the verification queue.

How Hybrid Human and AI Workflows Are Reshaping Enterprise Labeling Economics Read Post »

AI DataOps, annotation quality, governance, and scalable workflows drive successful LLM programs.

AI Data Operations: The Operating Model Behind Every Scaled LLM Program

Most Gen AI programs fail between the pilot and production, and the reason is almost always the data supply chain. Annotation quality slips, dataset versions go untracked, and each new model iteration requires starting from scratch on data sourcing. Building AI data operations as a deliberate enterprise function with defined accountability structures and reproducible workflows, is what changes that outcome. Data collection and curation programs should be designed to support this kind of operating model, not replace it.

Key Takeaways

  • AI DataOps is an operating model, and It governs how training data flows from sourcing through annotation to model training, continuously and at scale.
  • A functional AI data operations function has three layers; data acquisition and sourcing, annotation and labeling, and quality assurance with feedback integration.
  • RACI clarity is the single most underrated factor. Without a clearly accountable owner who can translate model failures into data remediation actions, the function stays reactive.
  • More annotators without better annotation architecture makes quality problems worse, and scale amplifies inconsistency.
  • Mature pipelines maintain continuous annotation capacity, versioned dataset lineage, and evaluation-driven data remediation as standing practices.
  • The build vs. buy vs. partner decision for AI DataOps is partly a governance question; which capabilities must be internally owned, and where does external execution capacity provide more value?
  • Organizations that treat annotation as an engineering problem with measurable quality standards consistently outperform those that remain busy with headcount solutions

What is AI Data Operations Service, and Why is this Important?

AI data operations (AI DataOps) refers to the operating model, team structure, tooling conventions, and governance frameworks that manage the continuous flow of training and evaluation data through an enterprise LLM program. The reason AI DataOps has moved from a background concern to a strategic priority is scale. 

A proof-of-concept model can be trained on a one-time curated dataset with a small annotation team working informally. A production LLM program, the one that requires continuous fine-tuning, preference optimization, safety evaluation, and domain adaptation as the model encounters real user behavior, demands a persistent data supply chain.

A 2025 S&P Global survey of over 1,000 enterprises found that 42% of companies abandoned most AI initiatives in 2025, up from 17% the previous year. The distinguishing factor for those that succeeded was end-to-end workflow redesign, which is precisely what a mature AI data operations function provides.

The concept encompasses several related terms that practitioners use interchangeably; ML data operations, training data pipelines, data-centric AI operations, and LLM data infrastructure. All of them point toward the same structural need, viz. a repeatable, accountable process for producing training data that is fit for the model’s production task, not just its pilot benchmark.

The Three Layers of an AI Data Operations Function

A well-designed AI data operations function operates across three layers, each with different workflows, quality standards, and ownership structures.

Layer 1: Data Acquisition and Sourcing

This is where you decide what goes into the pipeline; crawled text, internal documents, human-generated content, synthetic data, or multimodal assets. The challenge is to make sure that what you source actually represents the situations the model will encounter in production. Sourcing decisions made casually at the pilot stage tend to encode distribution mismatches that compound throughout fine-tuning. Data engineering is becoming a core AI competency and early pipeline infrastructure decisions in a program determine whether scale is achievable later.

Layer 2: Annotation and Labeling

This is the execution core: structured human judgment applied to raw data at scale to produce the labeled training signal the model learns from. Annotators apply labels; intent, preference, quality ratings, refusal decisions, etc. based on the individual model requirements. LLM annotation is harder to get right than classical ML annotation because the quality criteria are more subjective and harder to define consistently across a large team. Annotation programs at production scale need written guidelines that leave little room for interpretation, tiered review processes, and annotators who understand the task domain.

Layer 3: Quality Assurance and Feedback Integration

The third layer closes the loop; measuring annotation quality through inter-annotator agreement, golden set validation, and model performance regression, then feeding those signals back into the sourcing and labeling layers. This is the layer most enterprise teams skip or do informally. When it is missing, data quality drifts silently, model regressions go unattributed, and iteration cycles lengthen because teams cannot isolate whether performance changes come from the data or the training procedure.

How Decision Rights and RACI Should Work?

The most common failure mode in enterprise AI data operations is organizational approach. Annotation tasks get handed off without clear quality owners. Data sourcing decisions are made by ML engineers who lack the domain context to judge representativeness. Model evaluation findings are disconnected from the data team, so poor performance generates another round of architectural experimentation rather than a targeted data remediation.

A functional RACI for AI data operations separates four roles:

  • Responsible: The data operations team that sources, processes, and delivers annotated datasets.
  • Accountable: The AI program lead or Head of AI who sets quality and coverage standards tied to business performance targets.
  • Consulted: Domain subject matter experts (SMEs) who validate annotation guidelines, flag ontology gaps, and review edge-case data.
  • Informed: The model training and evaluation team who consume the data and feed back evaluation findings.

The accountability role is the one most consistently missing. Without an owner who can translate model evaluation failures into specific data deficits. The build vs. buy vs. partner decision for AI data operations is partly a RACI decision; what capabilities does the internal accountability structure need to own, and where does external execution capacity make more sense than internal build?

What Does a Mature AI Data Operations Pipeline Look Like?

Mature AI DataOps programs share a few consistent features. None of them are complicated in principle. They are just consistently absent in organizations that are still stuck in pilot mode.

Versioned Dataset Management

Every dataset delivered to a training run is tracked, with clear lineage from source through annotation to the fine-tuning job. When model performance regresses, the data team can isolate which dataset version was involved and which annotation cohort produced it without losing precious time.

Continuous Annotation Capacity

Mature programs maintain standing annotation capacity that can respond to data deficits identified during evaluation. Most enterprise teams underestimate how important this is. Annotation is not a one-time project, rather it is a continuous function..

Evaluation-Driven Data Fixes

When evaluation finds problems; hallucination categories, refusal failures, domain coverage gaps, etc., those findings go directly to the data team as a sourcing or annotation brief. The decision between human-in-the-loop and full automation is a decision that gets revisited at each stage of this feedback loop, not a one-time architectural choice.

Governance and Compliance Infrastructure

Production LLM programs operate under data provenance requirements, privacy obligations, and safety documentation standards that pilots typically ignore. A mature AI data operations function embeds these requirements into pipeline design from the beginning. Retrofitting governance after the fact is expensive and often requires rebuilding datasets.

Why More Annotators Do Not Solve the Problem?

The intuitive common response to data quality problems is more annotators, more labels, and more data. This consistently fails to resolve the underlying structural issues, and sometimes makes them worse.

Adding scale to a broken process amplifies the problems in that process. A small annotation team with ambiguous guidelines produces inconsistent labels at a contained scale. A large annotation team with the same ambiguous guidelines produces inconsistent labels across a much larger dataset, and those inconsistencies are harder to detect because individual samples look fine in isolation. The root cause of fine-tuning underperformance is almost upstream of the training run and that is why most enterprise LLM fine-tuning projects underdeliver

The correct intervention is annotation architecture; calibrated guidelines that define quality rather than relying on annotator judgment, multi-tier review processes that catch systematic errors before they reach training, domain-trained annotators who understand the task context, and ongoing inter-annotator agreement measurement, so you know when quality is drifting. LLM fine-tuning programs that consistently close the performance gap between pilot and production share one characteristic; their data teams treat annotation as an engineering problem with measurable quality standards.

How Digital Divide Data Can Help

DDD’s AI data delivery model combines domain-trained annotation teams, calibrated multi-tier QA workflows, and standing capacity that can absorb the variable demand profile of production LLM programs, without the quality drift.

DDD’s data collection and curation services are built to produce data that reflects the actual production distribution your model will face. DDD’s sourcing methodology explicitly addresses coverage of edge cases, safety-relevant scenarios, and low-frequency but high-consequence inputs that standard collection processes tend to underweight.

On annotation and quality, DDD’s data annotation services run inter-annotator agreement measurement, golden set validation, and annotator calibration as standard practice . Evaluation findings from model training teams are routed back into annotation programs as specific remediation briefs, creating the feedback loop that converts model performance data into data supply chain improvements. 

For teams working through the build vs. buy vs. partner decision, DDD also provides the strategic input to structure that choice, which capabilities to keep internal, which to delegate, and how to set up the governance interface between your AI team and an external data operations partner.

Build the data operations function your LLM program actually needs. Talk to an Expert!

Conclusion

AI data operations is not a department that enterprises build after their LLM programs are working. It is the function that determines whether those programs work at all beyond a sandbox. The organizations that are currently scaling Gen AI in production share a common structural feature; they treat data sourcing, annotation, quality assurance, and feedback integration as a persistent operating function with defined ownership.

The contrast between those organizations and those still cycling through pilots is less about model architecture or infrastructure investment than it is about operating model maturity. Every model regression that goes unattributed to a specific data deficit, every annotation batch that ships without inter-annotator agreement measurement, and every evaluation finding that never reaches the data team represents a structural gap that no amount of fine-tuning hyperparameter adjustment will close. None of these are hard problems to understand. They are just consistently skipped in the push to get a model working fast.

For further reading on the structural requirements of production AI data programs, see DDD’s analysis of why AI pilots fail to reach production, the breakdown of when to use human-in-the-loop versus full automation for Gen AI, and the practitioner guide to why data engineering is becoming a core AI competency.

References

S&P Global Market Intelligence. (2025). 2025 Enterprise AI Survey: AI Investment, Adoption, and Abandonment Patterns Across North America and Europe. https://www.spglobal.com/market-intelligence/en/news-insights/research/2025/10/generative-ai-shows-rapid-growth-but-yields-mixed-results 

MIT NANDA Initiative. (2025). The GenAI Divide: State of AI in Business 2025 — Preliminary Report. Massachusetts Institute of Technology. https://mlq.ai/media/quarterly_decks/v0.1_State_of_AI_in_Business_2025_Report.pdf

McKinsey & Company. (2025). The State of AI: How Organizations Are Rewiring to Capture Value. https://www.mckinsey.com/~/media/mckinsey/business%20functions/quantumblack/our%20insights/the%20state%20of%20ai/2025/the-state-of-ai-how-organizations-are-rewiring-to-capture-value_final.pdf 

Frequently Asked Questions

What is the difference between AI data operations and just doing data annotation?

Annotation is one part of AI data operations. AI DataOps is the full system around it, including how data gets sourced, how annotation quality is measured, how evaluation findings feed back into data work, and who owns each of those steps. Annotation without the surrounding structure produces inconsistent results at scale.

Who should own AI data operations inside an enterprise?

The one who is able to look at a model failure and trace it to a specific data problem, then authorize work to fix it. That person is usually the AI program lead or a Head of AI Data. The execution work (sourcing, labeling, QA) can be handled internally or by a partner. The accountability role needs to sit inside the organization.

Why do annotation quality problems get worse as the team gets bigger?

Because scale amplifies whatever inconsistency is already in the process. A small team with unclear guidelines produces a manageable amount of inconsistent labels. A large team with the same unclear guidelines produces the same inconsistency across a much bigger dataset, and it is harder to catch because individual samples look fine in isolation. Better guidelines and review processes fix this.

Do we need to build an internal AI data operations team, or can we outsource it?

Most teams do a mix of both. The accountability layer; the person who connects model performance back to specific data problems, tends to work best internally, because it requires context about your business goals. The execution layer, including sourcing, labeling, and quality-checking data at volume, is where partnering with a specialist often makes more sense than building in-house, especially in the early stages when demand is unpredictable.

AI Data Operations: The Operating Model Behind Every Scaled LLM Program Read Post »

Quality2BControl2Bwith2BComputer2BVision2BDDD

Revolutionizing Quality Control with Computer Vision

By Umang Dayal

March 22, 2024

According to McKinsey & Company, businesses that utilized computer vision for quality assessments reported a 90% improvement in detecting defective items.

By imitating human vision, computer vision can identify product defects, measure dimensions, classify objects, and accurately assess quality. Let’s learn more about computer vision use cases in quality assurance and how it is transforming various industries.

Computer Vision Enhancing Quality Control

Computer vision is a subfield of artificial intelligence that develops ML models capable of understanding, interpreting, and identifying visual data. CV technology can be deployed in manufacturing processes via sensors, cameras, and radars to offer real-time analysis, allowing quick decision-making and reducing errors.

CV models are invaluable assets for quality control which allows integration of automation in the production line, avoids incorrect supply chain management, and reduces costs. The time and effort required for manual labor are reduced significantly, and talent can be allocated to more decisive functions.

Computer vision is already streamlining quality control and verification processes for many industries. In the FMCG category, where each product contains a specific expiry date, APRIL Eye combines ML algorithms with computer vision to simplify the traditionally used date code verification system. If the date code seems incorrect, the production line comes to a halt so no expired product is released in the supply chain. This whole verification method is fully automated to save time and allow FMCG products to achieve full traceability and efficiency.

How Computer Vision is Revolutionizing Quality Control

Enhancing Defect Detection

Computer vision models can be trained to analyze images or videos of items to detect flaws and abnormalities. These systems can assist in identifying minor faults, and critical defects and provide real-time alerts to manufacturers to take immediate corrective measures.

Computer Vision used for Coating Inspection

The first thing that buyers see after unpacking medicines is the coating of tablets. This is the major reason why pharma companies are extremely particular about coating instructions.

Computer vision can be used for coating inspection and quality assurance. These CV algorithms can analyze large quantities of tablets, and if a pill does not meet the standard criteria, the system will display rejected tablets for manual inspection. CV systems can inspect thousands of tablets in an hour and reduce the load for manual inspection of such tiny objects.

Computer Vision Battling Corrosion

Oil and gas companies use specialized CV systems for identifying corrosion on their offshore and marine structures. They cannot gather sufficient data from these offshore structures due to their large dimensions and inaccessible areas. Computer vision-integrated drones can be used to gather this data and identify the exact location of damages. These CV systems can evaluate the damaged areas and see real-time pictures of corrosion to take corrective actions.

Precision Measurement and Dimension Analysis

Advanced computer vision systems utilizing high-resolution cameras and sensors can measure various attributes such as height, weight, length, angles, and distance of objects. The machines can measure these attributes against predetermined specifications to ensure every product meets the required standards. When implemented practically, these CV systems allow manufacturers to maintain product consistency and prevent additional costs.

Read more: The Impact of Computer Vision on E-commerce Customer Experience

Real-time Monitoring and Process Control

Computer vision allows real-time monitoring of the supply chain operations. These AI-driven CV systems can capture visual data and analyze objects in a production line, allowing the workforce to identify deviations and take corrective actions.

Manufacturing companies can utilize these insights to make informed decisions and optimize the production process. Real-time monitoring and process control help identify defective products at the early stage to prevent large-scale production of deficient items or increase additional costs.

Seamless Integration

Manufacturing processes can be easily integrated with computer vision technology for seamless automation and efficient operations. CV models can assist manufacturers with uninterrupted quality assessment and inspection adhering to standard protocols. These systems can provide data insights by analyzing market trends, failure patterns, and scope for improvement.

Automated Defect Detection

A major challenge in quality control is the identification of defective items, which can be time-consuming, costly, and contain the potential for errors. Computer vision models can be utilized to analyze defective items and compare them to pre-defined standards. These automated CV algorithms can improve accuracy, reduce costs, and minimize human error.

Quality Control through Visual Inspection

Human quality inspectors can miss minor defects due to fatigue, overwork, or tired eyes. Computer vision can work non-stop for a longer period of time as it is not limited to human capabilities. These machines can perform visual inspection with more accuracy and without witnessing general fatigue or tired eyes. By minimizing manual processes and deploying a human workforce in a more efficient and decisive role, companies can expand operations and focus on achieving customer satisfaction.

The Future of Computer Vision in Product Inspection

Food Marketing Institute recently conducted a survey, and it revealed that 68% of retail grocery stores are considering the adoption of computer vision as their top investment priority. Another study, published by the International Journal of Engineering Research and Technology emphasized the importance of computer vision in quality control and defect detection, which can achieve 98.5% accuracy in various industries.

As computer vision technology is expanding rapidly we can expect more innovations in quality control and defect identification. Companies adopting CV systems will improve their overall production efficiency by analyzing real-time insights, reducing defects, and quality control. Computer vision technology can be integrated with other innovative technologies such as the Internet of Things (IoT) and robotics to enhance productivity and optimize operations.

Final Thoughts

Computer vision’s ability to automate product inspection can revolutionize how manufacturers maintain and manage quality. With data-driven CV systems, businesses can minimize human error and ensure that flawless products reach the market. These CV algorithms are simplifying how the quality inspection process is conducted and operations are automated for improved efficiency, and cost reduction. This revolution can immensely boost customer satisfaction and enhance brand loyalty.

If you are looking for innovative computer vision solutions for quality control, DDD can assist you with their highly accurate human-in-the-loop annotation services.

Revolutionizing Quality Control with Computer Vision Read Post »

Scroll to Top